
Affiliation
Commencer Gratuitement
AI Influencer Avatars: How to Build Your Own Video Persona
Oct 16, 2026
What an AI Influencer Avatar Actually Is
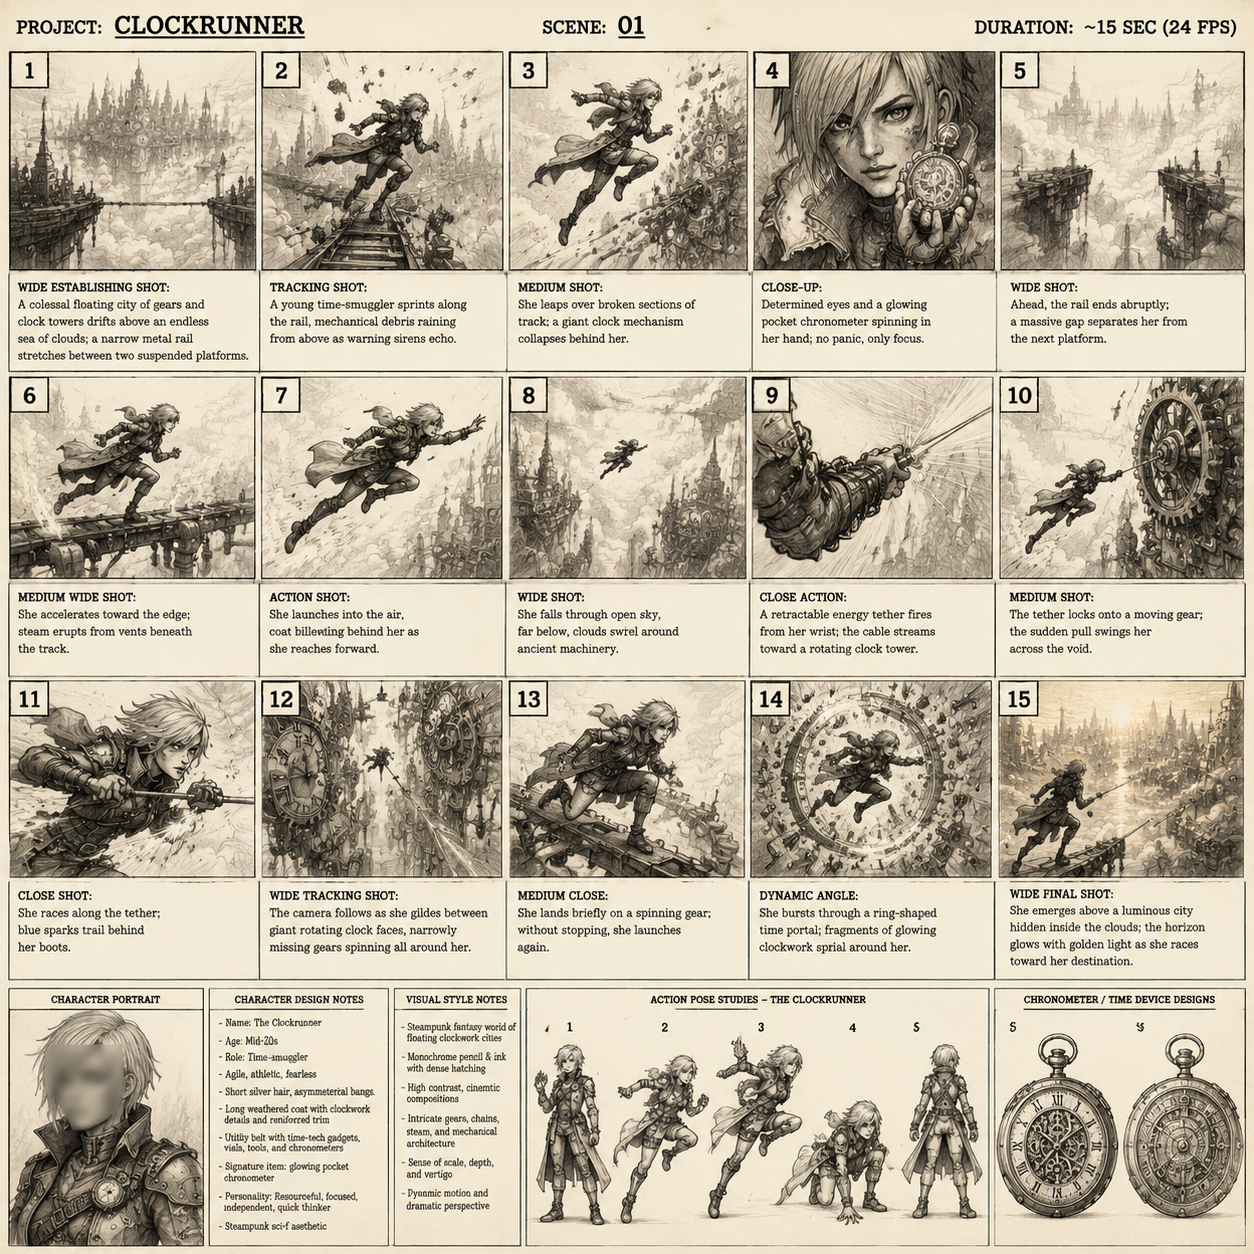
An AI influencer avatar is a reusable, recognizable on-screen persona that you can generate and direct with software rather than a camera. It has a face, a voice, a wardrobe, a tone, and a set of visual habits — the same things a human presenter has. The difference is that once you build it well, you can put it in front of a camera hundreds of times without scheduling conflicts, lighting setups, or retakes caused by a bad hair day.
That sounds like a novelty until you look at what it actually solves. Most creators and small marketing teams are bottlenecked by production, not by ideas. They know what they want to say. They just cannot film it often enough, consistently enough, and cheaply enough to compete with accounts that publish daily. An avatar removes the filming bottleneck while keeping the creative decisions in human hands.
It helps to separate three things that often get blurred together:
- The persona — the fictional or semi-fictional character: name, backstory, opinions, visual signature.
- The pipeline — the tools and steps that turn a script into a finished clip.
- The channel strategy — where the videos go, how often, and what they are supposed to achieve.
Most failed avatar projects fail at the persona or the channel strategy, not at the rendering. A technically flawless clip of an undefined character selling an unclear product convinces nobody. So this guide spends as much time on identity and workflow discipline as it does on generation settings.
Why Avatar Video Changed Content Production
Video generation models reached a point where faces hold together across shots, skin has texture instead of plastic sheen, and lip movement roughly matches speech. That shift matters less because of spectacle and more because of economics. When a presenter clip costs almost nothing to produce, the marginal cost of testing an idea collapses.
Consider what that unlocks:
Volume testing. A team can produce five hooks for the same offer and learn which one works before spending on a bigger campaign.
Localization. The same persona can speak multiple languages with new voice tracks and matched mouth shapes, instead of hiring a separate presenter per market.
Evergreen libraries. A persona that stays visually consistent across a year of uploads becomes a brand asset. Viewers recognize the face before they read the handle.
Scheduling independence. Scripts can be recorded at 2 a.m., batched in one session, or generated while you sleep.
The trade-off is authenticity. Audiences forgive synthetic presenters when the content is genuinely useful and the disclosure is honest. They punish synthetic presenters when the persona is used to fake expertise, fake testimonials, or fake human connection. The technology is neutral; the strategy around it is not.
A useful mental model: treat the avatar like a hired presenter with a contract. The contract says what topics it covers, how it speaks, what it will never claim, and how the audience is told it is synthetic. Written down, that contract prevents most of the credibility problems people worry about.
Designing the Identity Before You Generate Anything
Open a document and write the persona before you open a generator. Ten minutes here saves dozens of regenerations.
The identity sheet
Answer these in concrete terms, not adjectives:
- Name and handle — short, pronounceable, unlikely to collide with an existing brand.
- Age range and apparent background — broad enough to stay believable, specific enough to feel real.
- Face anchors — one hairstyle, one hair color, one eyebrow shape, one distinguishing feature such as a small scar, mole, or freckle pattern.
- Wardrobe rules — for example, always a dark crew-neck or a light linen shirt in warm settings. Two or three outfits total.
- Palette — three brand colors that appear in clothing, backgrounds, or captions.
- Voice profile — pitch range, pace, accent, common phrases, topics it refuses to discuss.
- Setting — a home-studio background, a café corner, a plain gradient wall. Repeating the setting is what makes a series feel deliberate.
Write a one-page persona bible
The bible is the single source of truth. Include the identity sheet, plus:
- Audience — who the videos are for and what they already know.
- Promise — the one thing this persona reliably delivers.
- Format beats — the opening line pattern, the mid-video example, the closing call to action.
- Off-limits list — medical claims, financial advice, political endorsements, anything requiring a license.
The off-limits list is not legal paranoia. It is what keeps a fictional persona from drifting into territory where a real human expert would be required.
Lock the look with reference images
Generate 20–40 still images of the persona from different angles: front, three-quarter, profile, slight low angle, slight high angle, smiling, neutral, mid-speech. Keep only the ones that match your anchors. This reference set becomes the visual DNA you feed into every future generation. Inconsistent references are the number one reason avatars drift between episodes.
Building Consistency: References, Training, and Style Locking
Consistency is the entire value proposition. A persona that looks slightly different in every clip reads as low quality, no matter how sharp the individual frames are.
Reference-based generation
The simplest approach is image-to-video with a strong reference. You supply the character still, the model animates it. This works well for talking-head content and requires no training at all. The catch is that the model may reinterpret the face when the head turns sharply or the lighting changes dramatically.
Custom model training
If you have 15–40 clean, consistent images of your persona, training a small custom model or adapter locks the identity far more tightly. Trained identities hold up across lighting, wardrobe changes, and camera angles. You pay for it in setup time and in the discipline required to keep the training set clean — one blurry or off-model image can poison the result.
Practical tips for a training set:
- Same apparent age, same bone structure, same hair in every image.
- Vary lighting and angle, not identity.
- Avoid heavy makeup changes, hats, and sunglasses unless they are part of the signature look.
- Crop tightly; remove busy backgrounds where possible.
- Include at least a few neutral-expression frames.
Style locking across episodes
Beyond the face, lock these too:
- Aspect ratio and resolution — pick one vertical format for shorts and one horizontal for long-form, then never mix inside a series.
- Lens feel — consistent focal length suggestions in prompts (for example, a 50mm portrait look rather than a wide angle).
- Color grade — the same LUT or preset applied to every episode.
- Caption style — one font, one position, one animation.
- Music bed — two or three recurring tracks.
When all five are constant, small variations in the face become invisible to viewers. When they are not, even a perfect face looks inconsistent.
A Practical End-to-End Production Workflow
Here is a repeatable pipeline you can run weekly. It works for solo creators and for small teams sharing a single persona.
Step 1: Script for the ear, not the eye
Write for spoken delivery. Short sentences. One idea per sentence. Read the draft aloud and cut anything you stumble over. Target 45–60 seconds of speech for a short, 3–4 minutes for a standard video. Mark emphasis words, because you will need them for voice direction.
Step 2: Build a shot list
Even synthetic videos benefit from structure. A simple pattern:
- Hook (0–3 s) — avatar medium close-up, direct address, strong opening line.
- Setup (3–15 s) — the problem, same framing.
- Body (15–40 s) — cut to B-roll or screen recordings every 4–6 seconds while the avatar voice continues.
- Payoff (40–55 s) — back to the avatar for the key claim.
- Close (55–60 s) — call to action with a caption overlay.
B-roll does heavy lifting. It hides any lip-sync imperfection and adds pacing that a static talking head cannot match.
Step 3: Generate base shots
Generate the avatar shots first, one clip per line or per short paragraph. Keep clips short — 3 to 6 seconds each. Short clips are easier to fix and easier to rearrange. Export at your final resolution and keep a folder of unused takes; you will reuse them.
Step 4: Voice and lip sync
Decide voice before you generate mouth movement, because re-syncing is expensive in time. Options:
- Synthetic voice — fastest, fully controllable, works in any language. Spend real effort on pacing and pauses; monotone delivery is the most common giveaway.
- Your own recorded voice — highest authenticity, and it pairs well with a synthetic face. Record in a treated room, keep levels consistent, and normalize before syncing.
- Hybrid — record your own scratch track, then regenerate segments where you misread, keeping the same tone.
Then run lip sync. Check consonant-heavy words and any word with an m, b, or p, since these are where mouth shapes most often break.
Step 5: Assemble and grade
In your editor: lay the voice track first, cut visuals to it, add captions, add music at roughly −18 to −22 dB under speech, then apply the series color grade. Export a master file plus platform-specific versions.
Step 6: Archive the assets
Every project should leave behind a folder of reusable pieces: the clean avatar plate, the voice track, the project file, the grade, and the caption template. Over a few months this archive becomes the real production advantage, because episode 30 takes a fraction of the time episode 1 did.
Quality Control Checklist Before You Publish
Run this list every time. It takes three minutes and catches almost everything.
Face and identity
- Same bone structure, hair, and distinguishing features as the reference set?
- Eyes symmetrical and pupils consistent across shots?
- Teeth and mouth interior believable during speech?
Motion
- Head turns without warping the jawline?
- Hands, if visible, with five fingers and natural joints?
- No flicker or texture crawl on skin between frames?
Sound
- Lip sync holds through fast passages?
- No clipped plosives or uneven levels between clips?
- Music never masks consonants?
Message
- Hook lands inside the first three seconds?
- Every claim is accurate and within the persona's off-limits list?
- Disclosure is present and legible if the platform or audience expects it?
Technical
- Correct aspect ratio, safe margins for UI overlays, captions readable on a phone at arm's length?
- Filename and metadata follow the archive convention?
If a clip fails two or more items, regenerate it rather than patching. Patching synthetic video creates artifacts that compound in the edit.
Tool Categories and How to Choose
You do not need one platform that does everything. You need coverage across five categories, and you can mix vendors freely.
| Category | What it does | What to check |
|---|---|---|
| Video generation | Turns prompts or stills into motion clips | Identity retention, clip length, resolution, cost per second |
| Avatar / lip sync | Drives a face from an audio track | Language coverage, mouth realism, processing speed |
| Voice synthesis | Produces or cleans the spoken track | Pacing control, emotion tags, pause editing |
| Editing | Assembles, captions, grades | Caption templates, proxy workflow, export presets |
| Asset management | Stores references, plates, and masters | Search, versioning, sharing permissions |
Decision criteria that actually matter:
- Identity retention across shots — test with your own reference set before committing.
- Iteration speed — a fast, mediocre model beats a slow, perfect one when you are testing hooks.
- Deterministic controls — seeds, reference strength, and motion settings you can reproduce.
- Output licensing — confirm you have commercial rights to generated output.
- Export flexibility — you must be able to get clean files into your own editor.
Run a one-hour bake-off: same script, same references, three tools, then compare lip sync and identity consistency side by side. That single test tells you more than any feature list.
Cost, Scale, and Team Decisions
Costs in synthetic video come in three forms: generation time, storage, and human review. The first two scale predictably; the third does not, and it is usually the real constraint.
A rough planning model:
- A 60-second video needs roughly 12–25 generated clips after selection.
- Expect to discard 30–50% of generations, so budget for 30–45 clips.
- Review time is about 1.5–2× the finished runtime for a trained operator.
That means one person can realistically ship three to five polished short videos per week, not thirty. Teams that promise daily output usually do it by lowering the bar on review, and the audience notices within a month.
When you add people, split roles clearly:
- Persona owner — guards the bible and approves any change to the look.
- Scriptwriter — owns hooks and structure.
- Operator — runs generation, sync, and assembly.
- Reviewer — the person who did not make the clip, checking the QC list.
Separating the reviewer from the operator is the single cheapest quality improvement available. Self-review misses drift because you have been staring at the same face for hours.
For scaling, batch by function rather than by video: write ten scripts, generate all shots, sync all voices, assemble all edits. Context switching is what eats the day.
Ethics, Disclosure, and Audience Trust
Synthetic presenters are legitimate. Deceptive synthetic presenters are not, and the line is drawn by disclosure and by claims.
Practical rules that keep you safe and credible:
- Disclose in the channel, not just the fine print. A short line in the bio or a recurring on-screen label is usually enough.
- Never fake credentials. If the persona is not a doctor, engineer, or licensed advisor, it should not imply that it is.
- Do not fabricate testimonials. Synthetic customers praising a product is fraud in most jurisdictions, regardless of labeling.
- Respect likeness rights. Never build a persona from a real person's face or voice without written permission.
- Keep a human accountable. Someone real should be reachable and responsible for what the persona says.
There is also a craft argument for disclosure: audiences reward transparency with attention. The accounts that treat the avatar as a stated part of the format — "our AI host covers three tools every week" — build durable audiences. Accounts that hide it spend their energy managing suspicion instead of making better videos.
Common Mistakes and How to Fix Them
Drifting identity. Cause: inconsistent references or no trained model. Fix: rebuild the reference set and lock the training data.
Uncanny mouth movement. Cause: long clips and mismatched voice timing. Fix: shorten clips to 3–6 seconds, normalize audio, re-sync after any voice edit.
Flat delivery. Cause: default voice settings. Fix: insert pauses manually, vary sentence length in the script, add emphasis marks.
Static talking head for a full minute. Cause: no B-roll plan. Fix: cut away every 4–6 seconds.
Overly polished, no personality. Cause: personas defined by adjectives instead of habits. Fix: give the avatar two verbal tics and one recurring visual gag.
Burnout at episode ten. Cause: bespoke production for every video. Fix: templates for structure, captions, grade, and thumbnails.
FAQ
Do I need a trained model, or is a reference image enough?
For a single talking-head series, references are usually enough. Train a custom model when you need the persona in varied lighting, multiple outfits, and many angles without drift.
Can one avatar speak several languages?
Yes. Generate or record a separate voice track per language and re-run lip sync. Keep the visual identity and wardrobe identical so the persona stays recognizable across markets.
How long should avatar clips be?
Three to six seconds for generation, then cut together into 45–60 second shorts or 3–4 minute videos. Long single generations are where artifacts appear.
Is avatar video good for long-form?
It can be, but use it as a segment host rather than a continuous presence. Mix in screen recordings, B-roll, and graphics to keep pace.
What is the fastest way to start?
Pick one topic, one format, one setting. Build a 20-image reference set, generate five clips, and publish a single 45-second video. Iterate from there instead of planning a full channel first.
How do I know if the quality is good enough?
Watch it muted. If you cannot follow the story without sound, the visuals or captions need work. Then watch it on a phone at arm's length — that is how most of your audience will see it.
Where to Start This Week
Build the persona bible first, not the video. Twenty minutes of writing about identity, wardrobe, voice, and off-limits topics will shape every downstream decision and prevent the drift that kills most avatar channels.
Then produce one small thing end to end: a 45-second short with five generated clips, one B-roll insert, captions, and a consistent grade. Archive the plate, the voice track, and the project file. That single finished loop teaches you more about your tools, your reviewer's eye, and your audience than a month of research.
The creators who win with synthetic presenters are not the ones with the most advanced models. They are the ones with a locked identity, a repeatable pipeline, a QC habit, and honest disclosure. That combination scales — and it is available to anyone willing to be systematic.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.