
Affiliation
Commencer Gratuitement
Integrated AI Video Editing Workflows: A Practical Guide
Oct 16, 2026
Why Integrated AI Editing Changes the Production Math
For years, video production operated as a relay race. A script went to a producer, the producer booked a shoot, the shoot delivered cards to an editor, and the editor passed a locked cut to a colorist and a mixer. Every handoff cost time, and every tool spoke a slightly different language. Generative AI did not remove that relay race. It added a new runner who works fast, never gets tired, and occasionally hands you something completely unusable.
The real shift is not that AI can generate footage. It is that generation now happens inside the editing timeline rather than before it. When your model output, your asset library, and your sequence share the same metadata, iteration stops being a logistics problem and becomes a creative one. You stop asking "can we afford another take?" and start asking "which of these twelve takes is right?"
That change moves the bottleneck. Generation gets cheap; review gets expensive. A team that produces forty variants of a shot now needs a system for selecting the best one quickly, or it drowns in folders. Integrated tooling solves this in three ways:
- Generation as a timeline operation. A clip can be regenerated at a specific length, aspect ratio, and resolution because the timeline knows what it needs.
- Model selection as a creative decision. Different shots genuinely need different model families, and treating that choice as craft rather than configuration produces better results.
- Versioning as a default. When every output carries its prompt, seed, and settings, you can reproduce a look months later instead of guessing.
None of this replaces editing skill. It raises the ceiling on how many ideas a small team can test, which means taste and judgment matter more than ever.
Mapping the Pipeline From Script to Final Render
A reliable AI-assisted pipeline has four stages, and each one should produce artifacts the next stage can consume without manual cleanup.
Ideation and Scripting
Write a beat sheet first, then a shot list. Each shot becomes a shot card containing the intent, framing, lens, lighting, motion, target duration, and a reference still if you have one. This sounds like overhead until you are twelve shots deep and cannot remember why a particular clip exists.
Generation
Generate in batches organized by look, not by scene order. Shots that share lighting and palette benefit from shared prompt language and consistent seeds. Keep a naming convention from the first render so nothing becomes an orphan file later.
Assembly and Rough Cut
Drop selects onto a timeline against temporary music. Do not wait for perfect footage to start cutting. Placeholder cards with correct durations let you evaluate pacing, and pacing problems are far cheaper to fix than rendering problems.
Finishing, Audio, and Delivery
Color, audio, captions, and delivery specs come last. Keep generated originals untouched and work from mezzanine intermediates such as ProRes or DNxHR. This protects you when a client asks for a different aspect ratio or a slightly longer hold on a shot.
The through-line is simple: every stage should be re-runnable. If regenerating one shot forces you to rebuild the sequence, the pipeline is not integrated — it is just adjacent.
Choosing the Right Generation Model for Each Shot
There is no single best model. There are model families with different strengths, and matching them to shots is the highest-leverage decision in the whole workflow.
Text-to-video works well for establishing shots, landscapes, abstract transitions, and anything without a specific character identity to preserve. It is fast, flexible, and the easiest place to explore.
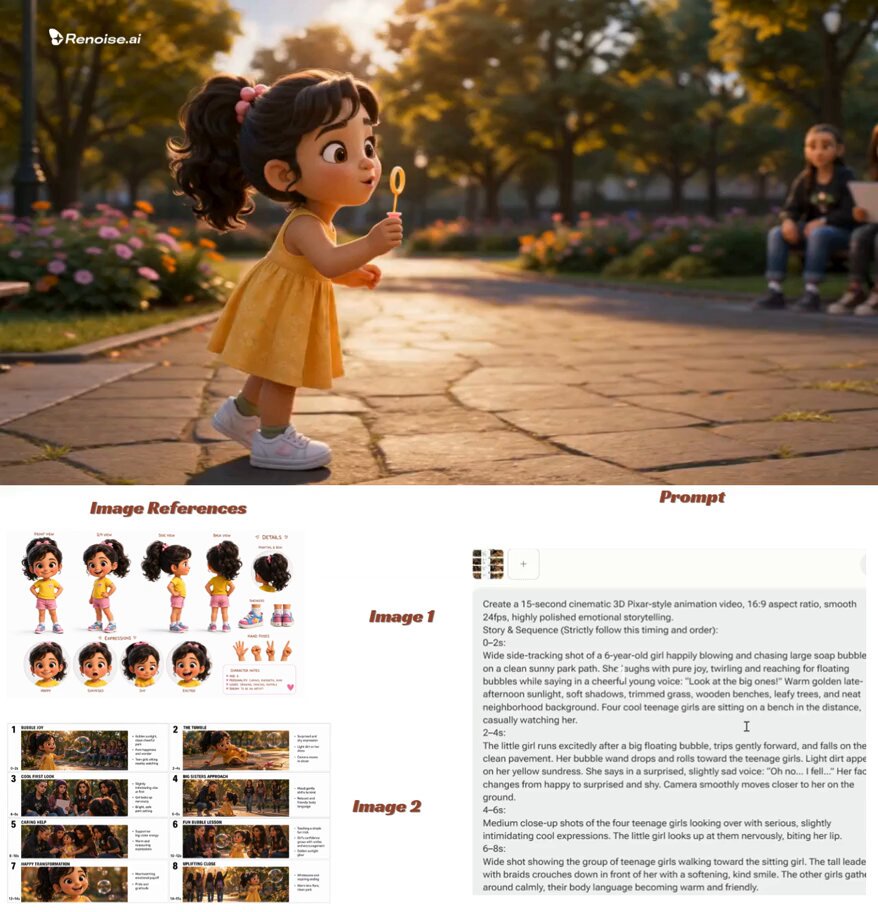
Image-to-video is the workhorse for anything with a locked look. If you have a product photo, a character sheet, or a mood-board still, conditioning on that image gives you far more control than describing it in words.
Video-to-video handles restyling: turning live-action plates into animation, applying a grain or film-stock treatment, or matching a shot to a style you already established elsewhere.
Specialized passes cover the gaps — upscaling, frame interpolation, matting and rotoscoping, lip sync, and voice synthesis. These are unglamorous but they are what make generated footage feel finished.
Use these criteria when routing a shot:
- Duration. Short clips are more stable. If a shot needs eight seconds, consider generating four and extending deliberately.
- Motion complexity. Fast camera moves and complex human action fail more often than slow, deliberate motion.
- Consistency requirements. A recurring character almost always justifies an image-conditioned approach.
- Resolution target. Generating at 4K when the shot will appear at 25 percent scale in the frame is wasted effort.
- Latency budget. A rough cut needs speed; a hero shot can afford a slower, better pass.
A hybrid approach often beats a purely generative one. Use planar tracking or 3D camera projection for screen replacements and inserts, and reserve generation for the shots where no plate exists.
Keeping Visual Consistency Across Shots
Consistency is where most AI-assisted projects fall apart, and it is almost never a model problem. It is a documentation problem. The team changes phrasing between shots, forgets which seed produced a look, and then cannot reproduce it.
Build a style bible — a single document with verbatim phrasing for your look. Not adjectives, exact sentences. "Soft window light from the left, 35mm lens, shallow depth of field, muted teal shadows, warm skin tones, subtle 35mm grain." Reuse that string every time. Small wording changes produce visible style drift over a sequence.
Then layer these techniques:
- Anchor stills. Lock one approved frame per character, location, or product. Feed it as a reference for every subsequent shot in that thread.
- Multi-image fusion. When you need a character and an environment to stay consistent, condition on both references rather than describing one in text.
- Keyframe control. Define the first and last frame of a shot. The model fills the middle, which dramatically reduces drift in long takes.
- Seed discipline. Once a look is approved, freeze the seed and change only the variables you intend to change.
- A unifying grade. Apply a single LUT, grain plate, and lens-blur treatment across all generated footage. A consistent grade hides a surprising amount of underlying variation.
- Camera language consistency. Keep height, angle, and lens choice purposeful. Random camera height is the fastest way to make a sequence feel assembled rather than directed.
Finally, budget time for a consistency pass. Watching the sequence straight through, without stopping, reveals drift that frame-by-frame review misses.
Prompt and Keyframe Techniques That Reduce Retakes
Most wasted generations come from prompts that try to say too much. A prompt packed with fifteen requirements gives the model no way to prioritize, so it satisfies the easy ones and improvises the rest.
Use a stable structure instead:
Subject → Action → Environment → Camera → Lens → Lighting → Mood → Texture → Duration → Constraints
For example: "A ceramicist shaping a bowl, hands centered, sunlit studio, slow dolly in, 50mm, soft north light, calm and focused, fine film grain, four seconds, no text overlays."
Then apply these habits:
- Change one variable at a time. If you alter subject, lighting, and camera together, you learn nothing from the result.
- Describe motion explicitly. "Handheld drift," "slow push," and "static locked-off frame" produce very different results and should never be left to chance.
- Use negative constraints. Call out what you do not want: warped hands, extra fingers, text artifacts, rapid cuts, lens flares.
- Prefer short clips. Generate three to four seconds, evaluate, then extend or stitch. Long single generations accumulate errors.
- Keep a change log. Two columns: what changed, what happened. After twenty generations you will have a personal rulebook that is worth more than any generic prompt guide.
- Iterate on stills first. If the composition is wrong as an image, it will be wrong as a video. Fixing the frame before animating saves entire render cycles.
Keyframes deserve special attention for dialogue and product shots. Locking the opening and closing composition means the model only has to solve the middle, which is where consistency is easiest to maintain.
Managing Compute, Queues, and Long-Running Jobs
Generation jobs are unpredictable. Some finish in seconds; others stall. Treat them like any other asynchronous workload rather than like a file export.
Define clear job states: queued, running, succeeded, failed, retrying. Make jobs idempotent so a retry does not create duplicate outputs. Set timeouts that are generous but finite, and use exponential backoff rather than hammering a failing endpoint. Route repeatedly failing jobs to a dead-letter queue and review them in a batch instead of one at a time.
The single most effective cost-control habit is draft-first rendering. Generate at low resolution with fewer steps to validate composition, motion, and timing. Only re-render the shots that survive the rough cut at full quality. On a twenty-shot sequence, this routinely cuts total processing by more than half because most early attempts never make the final cut.
Other practical habits:
- Batch by look. Group similar shots into one overnight run so you review a coherent set in the morning.
- Prioritize by sequence position. Shots in the first ten seconds deserve more attempts than a two-frame transition.
- Log every job. Prompt, model, settings, duration, and outcome. Your log becomes the searchable history that makes future projects faster.
- Set retry limits. Three attempts, then reassess the approach. The fourth attempt at the same prompt rarely succeeds.
- Reserve headroom. Never schedule at 100 percent of your capacity; a single failed batch should not delay delivery.
Storage, Versioning, and Asset Hygiene
Media piles up faster with AI than with a camera. A single shot can produce thirty files in an afternoon, and without structure you will be scrolling through timestamps trying to find the good one.
Adopt a naming convention that encodes meaning:
project_scene_shot_take_version
Then keep a sidecar file — JSON, Markdown, whatever your team will actually maintain — recording the prompt, model, seed, reference images, duration, and any post-processing applied. This is what makes a shot reproducible. Without it, an approved look becomes a lucky accident.
Additional hygiene rules that pay off quickly:
- Never delete originals. Storage is cheaper than a re-shoot. Move old takes to cold storage with lifecycle rules instead.
- Separate folders for raw, selects, and finals. Editors should never have to guess which file is approved.
- Checksum large files. Silent corruption is rare but catastrophic in the middle of a deadline.
- Version prompts alongside media. If the wording of a style reference changes, that is a new version, not an edit.
- Keep a selects bin per scene. It turns a forty-file folder into a four-file decision.
Quality Control: A Pre-Delivery Checklist
AI-generated footage fails in specific, predictable ways. A short checklist catches most of them before a client does.
- Anatomy and objects. Check hands, teeth, ears, jewelry, glasses, and any object that rotates or passes behind something else.
- Temporal stability. Watch for flicker, warping backgrounds, and textures that crawl between frames.
- Text and signage. Any text in frame should be legible and intentional. If not, remove the shot or overlay clean type in the edit.
- Frame integrity. Confirm there are no dropped, duplicated, or blended frames after interpolation.
- Audio sync. Check lip sync at normal speed and at half speed, and verify dialogue against the waveform.
- Loudness targets. Around -14 LUFS integrated for web platforms, and roughly -23 LUFS for broadcast delivery.
- Caption accuracy. Auto-generated captions misread names, numbers, and jargon. Read them line by line.
- Color and safe areas. Verify color space tags and keep titles inside title-safe margins for every aspect-ratio variant.
- Two-screen review. Watch once on a phone and once on a large display. Small-screen viewing hides detail problems; large screens expose them.
Common Mistakes and How to Avoid Them
Rendering at final quality too early. Draft-first generation is almost always faster overall, even though it feels slower at the start.
Skipping the style bible. Inconsistent phrasing produces inconsistent footage, and no amount of grading fully fixes it.
Changing too many variables per attempt. This destroys your ability to learn from results.
Treating audio as an afterthought. Voice, music, and ambience carry more perceived quality than most people expect; a mediocre image with great sound reads better than the reverse.
Generating long clips. Errors compound. Short clips, carefully joined, are more reliable and easier to repair.
Ignoring rights and consent. Confirm you have permission for likenesses, trademarks, music, and any reference material you condition a model on.
Assuming AI removes the need for craft. It changes which craft matters — selection, pacing, and structure — but it does not remove it.
FAQ
How many attempts should a shot get before I change approach?
Three is a good default. If three attempts miss, the problem is usually the prompt structure, the reference image, or the model family — not the number of tries.
Do I need a dedicated AI editing application?
Not necessarily. Many teams get excellent results by generating assets separately and editing in a conventional non-linear editor, as long as metadata and naming conventions are disciplined.
What resolution should I generate at?
Match the delivery target, not the source ambition. If a shot occupies a quarter of the frame, generating at full delivery resolution wastes time and money.
How do I keep a character consistent across a whole sequence?
Lock an anchor still, reuse the exact same descriptive phrasing, freeze your seed where possible, and apply one unified grade at the end. Consistency comes from repetition, not from better adjectives.
Why does my generated footage look sharper than my real footage?
Generated material often lacks natural grain and lens softness. Adding a subtle grain plate and a slight blur to match your camera footage usually resolves the mismatch.
How long should I spend on a consistency pass?
Budget roughly ten to fifteen percent of total edit time. It is the difference between a sequence that feels directed and one that feels assembled.
Can I mix generated and live-action shots in one piece?
Yes, and it often works better than either alone. Match grain, black levels, and lens character, then let the grade unify them.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.