
Affiliazione
Inizia Gratis Ora
AI Video Animation Generators: A Practical Workflow Guide
Oct 15, 2026
Why AI Animation Belongs in a Modern Video Workflow
Video has become the default format for almost every kind of communication: product launches, internal training, social campaigns, explainer content, crowdfunding pitches. The bottleneck was never the idea. It was the cost of turning an idea into moving images. Traditional animation means storyboards, rigging, keyframes, render queues, and weeks of iteration before anyone sees a first cut.
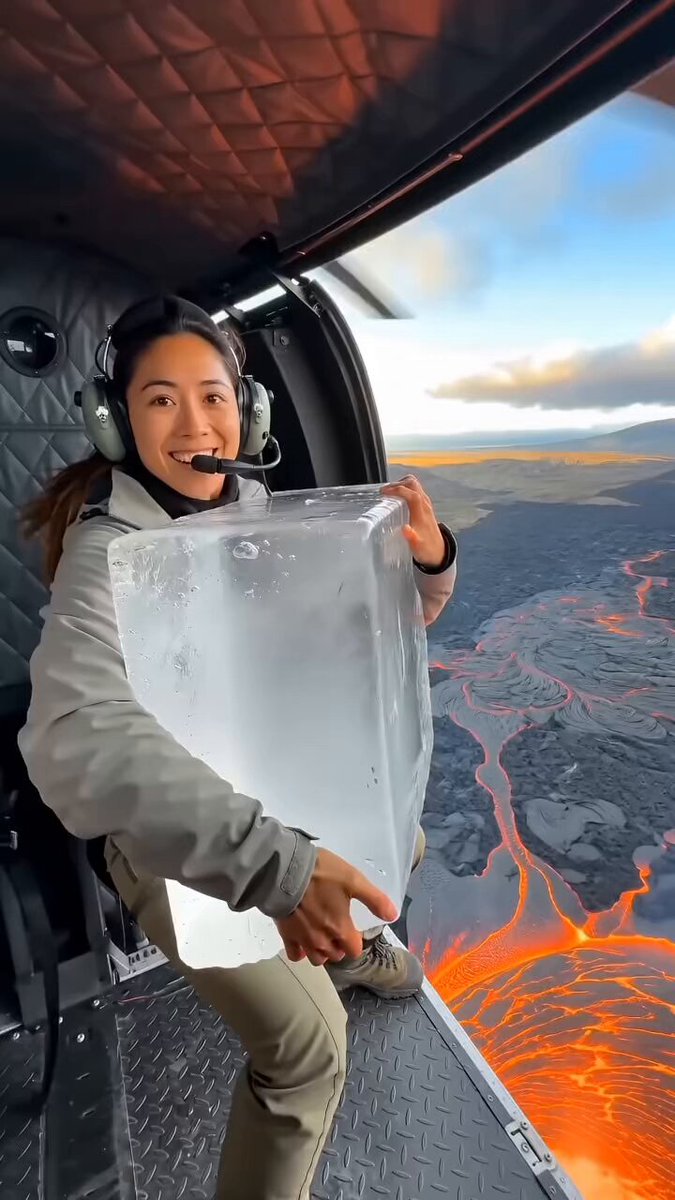
AI video animation generators compress that loop dramatically. You describe a shot, generate several variants in minutes, and iterate on the ones that work. A small team can now produce motion content that previously required a studio, and a solo creator can prototype a visual language before committing to a production budget.
That does not mean craft disappears. It moves. Instead of spending days on interpolation and cleanup, you spend your time on directing: what the shot must communicate, how the camera should behave, how the character reads, how the cuts land. The model handles pixel-level labor. You handle intent.
This guide covers how these systems work, how to match generation modes to specific shots, how to keep characters and style consistent across a sequence, and how to build a repeatable pipeline from script to export.
How AI Video Animation Generators Actually Work
Most modern generators share a common shape: a diffusion or transformer-based model trained on large volumes of video, conditioned on text, still images, or an existing clip. The conditioning signal is what defines the mode you are working in, and each mode has a distinct personality.
Text-to-video
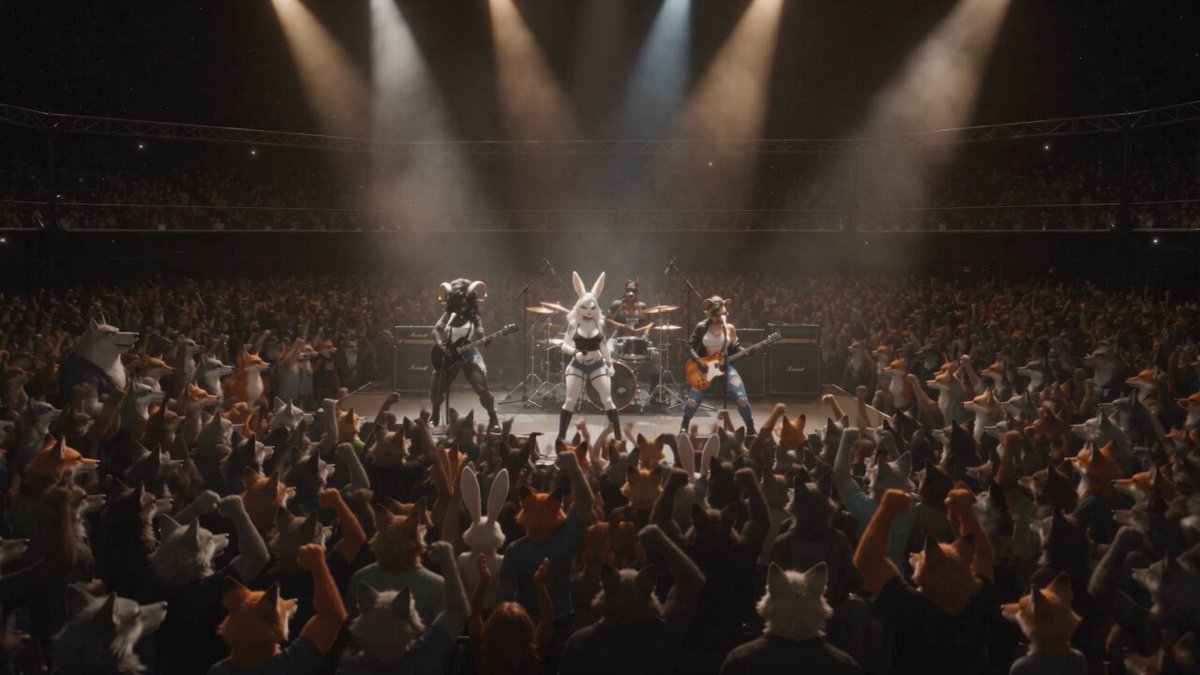
You write a prompt and the model returns a short clip. Text-to-video is the fastest way to explore tone, composition, and pacing, and the least reliable way to control a specific character's face. It shines for establishing shots, environments, abstract transitions, and mood boards. Prompts work best when they describe the subject, the action, the camera, and the light in that order, because models tend to weight early tokens more heavily.
Image-to-video
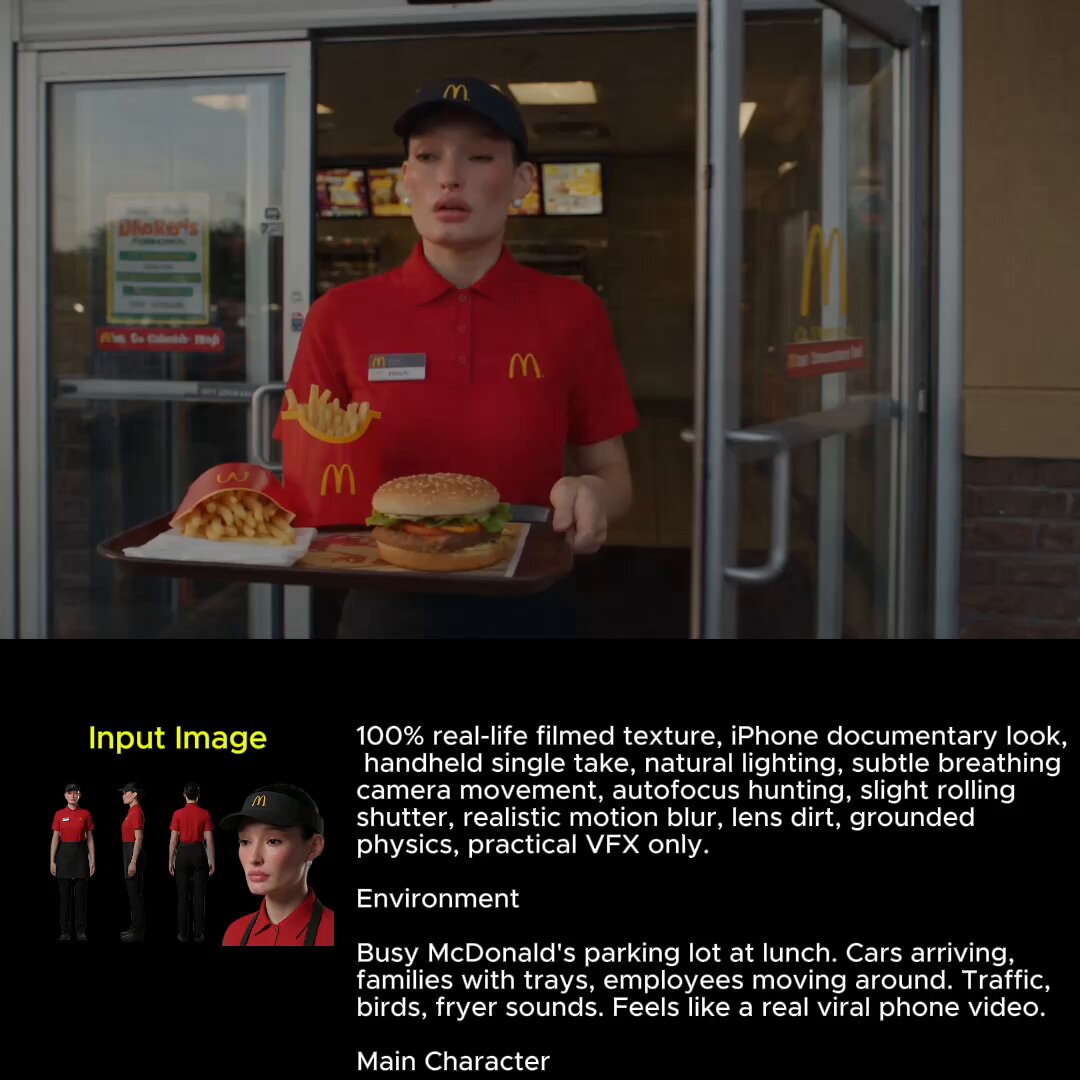
You supply a still and the model animates it. This is the workhorse of most production pipelines, because the still already encodes casting, wardrobe, framing, and color. Your prompt then only has to describe motion: a slow dolly in, hair drifting, fabric shifting in the wind. If you can art-direct a still, you can art-direct an animation. The quality ceiling of the output is largely set by the quality of the input frame.
Video-to-video and style transfer
You feed existing footage in and the model restyles, extends, or refines it. This covers illustration looks over live action, rotoscope-adjacent effects, frame interpolation, and clip extension. It is the most controllable mode because timing and blocking already exist, so the model only changes surface. If a shot must hit a musical beat precisely, start with footage or a pre-rendered animatic and restyle it.
In practice, most good workflows combine all three: generate stills, animate them, then restyle or extend the results. Treating these as a sequence rather than competing options is the single biggest productivity unlock.
Matching the Generation Mode to the Shot You Need
The fastest way to waste an afternoon is to use text-to-video for a shot that needed a still. Before you generate anything, classify each shot.
Decision rules that hold up across projects:
- Recurring character, close-up, consistent face: image-to-video from a locked reference sheet.
- Environment or establishing shot, no repeat characters: text-to-video, several variants.
- Restyling real footage: video-to-video.
- Precise action timing: animate or shoot the blocking first, then restyle.
- On-screen text, logos, UI, captions: do it in the editor, never in the generator.
Duration matters too. Most models produce convincing motion in the four-to-ten-second range, and quality degrades as you push beyond that. Edit around three-to-five-second shots. Shorter clips hide errors better, give you more chances to cut away, and keep a fast rhythm that audiences read as intentional.
Decide resolution and aspect ratio before generating, not after. Cropping a vertical clip into a widescreen master rarely looks good, and upscaling soft output into a hero shot is a losing battle.
Consistency: The Hardest Problem in AI Animation
Ask anyone who has shipped an AI-animated sequence what went wrong first, and the answer is almost always character drift. Faces shift between shots, wardrobe mutates, hair color wanders. Solving this is 80 percent of the perceived quality of your final video.
Reference images and character keyframing
Build a character sheet before you generate a single shot: front view, three-quarter view, profile, plus one full-body pose and one expression variant. Keep lighting neutral and backgrounds plain. Every shot featuring that character then references the same set. Models that fuse multiple reference images do noticeably better than single-image conditioning when you need the same face from different angles.
For recurring motion, generate a short keyframe clip first, then reuse it as the motion reference for later shots. A walk cycle, a signature gesture, or a specific head turn can become a reusable rig rather than something you re-invent every time.
Seed and prompt discipline
Lock the seed when you find a look you like, then change exactly one variable at a time. Write prompts from a template so camera, lens, and lighting language stay identical between shots while only the action changes. Keep a log with seed numbers, model version, reference file names, and a one-line note on what worked. It feels fussy until the first revision request arrives, at which point it saves hours.
One more habit that pays off: keep a small library of approved looks, graded and labeled, so new team members can match an existing sequence instead of guessing.
A Practical End-to-End Production Workflow
Here is a pipeline that scales from a single social clip to a multi-minute narrative piece.
1. Script, beat sheet, shot list
Write the script, convert it to a beat sheet, then convert that into a shot list with one row per generated clip: shot number, duration, generation mode, reference assets, prompt text, and status. This sounds bureaucratic until you have forty clips and cannot remember which seed produced the good one.
2. Asset preparation
Prepare stills at the target aspect ratio and name them consistently, for example char_aria_three_quarter_v2.png. Clean backgrounds, consistent lighting, and sharp edges matter more than raw resolution. A soft, low-contrast image animates badly no matter which model you choose.
3. Prompt construction
Use a reliable skeleton: subject, action, camera, lens and light, style, then negatives.
"A woman in a linen coat walking through a rain-slicked market, slow tracking shot at chest height, 35mm, overcast diffused light, muted teal and amber grade, shallow depth of field. No text, no logos, no extra limbs, no flicker."
4. Generation and triage
Generate in small batches, three to five variants per shot. Review each clip once at full speed and once frame by frame. Mark each one keep, fix, or discard, and write one sentence on why. The pattern in your rejections tells you precisely what to change in the prompt, which is far more useful than a vague sense that something is off.
5. Assembly, sound, and finishing
Cut in an editor, not in the generator. Add music, sound design, and foley, because motion without sound reads as unfinished to almost every viewer. Finish with a stabilization or retime pass rather than regenerating entire shots for minor timing fixes. Regenerating is expensive in time and often breaks continuity you already solved.
Prompt Patterns That Create Believable Motion
Static prompts produce static clips. Motion needs verbs, camera language, and physics.
- Use specific camera verbs: dolly in, crane up, whip pan, handheld follow, slow push, orbit left.
- Describe secondary motion: fabric shifting, steam rising, hair moving, dust catching light.
- Anchor physics: water splashes on contact, coffee sloshes as the cup lifts, papers scatter when the fan turns on.
- Keep the action realistic for the duration. A complex sequence packed into four seconds looks like a glitch reel rather than choreography.
- Repeat identity cues such as "the same woman, the same red scarf" in every prompt instead of trusting the model to remember earlier shots.
- Negatives are equally useful: extra fingers, warped faces, text, watermarks, flicker, jump cuts, duplicated characters.
A useful exercise: write ten prompt variants for one shot, changing only the camera language. You will quickly learn which phrasing your chosen model responds to and which words it ignores. That knowledge transfers across every future project.
Common Mistakes and How to Fix Them
Skipping the still. Animating directly from text and then trying to fix a face in post rarely works. Fix: art-direct the still first, then animate it.
Overloading the prompt. Five subjects, three actions, and two camera moves produce mush. Fix: one subject, one primary action, one camera behavior per clip.
Changing too many variables. When a result is bad, the temptation is to rewrite everything. Fix: lock the seed, change one element, compare side by side.
Ignoring motion blur and frame rate. Clips that look fine paused can strobe during playback. Fix: always judge at full speed before approving.
Expecting one clip to tell a story. A single ten-second generation is a shot, not a scene. Fix: plan sequences of short shots and let editing carry the narrative.
Treating sound as an afterthought. Fix: budget time for sound design equal to a third of your edit time.
No naming convention. Fix: adopt a strict file naming scheme from day one, including model version and seed.
Publishing without a frame-level check. Fix: run a quality-control pass at 0.25x speed on every shot that made the cut.
A Quality-Control Checklist Before You Export
Run this list against the locked cut, not against individual clips.
- Faces: hold for at least two seconds in a close-up and watch at full speed, then slow.
- Hands and contact points: check where objects are gripped, thrown, or set down.
- Edges: hair, fingers, thin objects, transparent materials, and fast-moving limbs.
- Background stability: no warping architecture, morphing passers-by, or breathing walls.
- Continuity: wardrobe, props, light direction, and screen direction across cuts.
- Motion quality: no stutter, no reversed frames, no global warping during camera moves.
- Audio: level-matched between shots, synced within a frame, and clean of clipping.
- Delivery specs: resolution, aspect ratio, bitrate, captions, and safe-area framing for each platform.
Catching one warped hand before export protects the credibility of the entire piece. Audiences forgive stylization, but they notice broken anatomy instantly.
Decision Criteria: When AI Animation Is the Right Tool
Use AI animation when you need stylized or illustrative motion quickly, when you are previsualizing a larger production, when you are repurposing a library of stills into motion, when you need volume content for social channels, or when you need to produce visuals for a market or language you cannot practically shoot in.
Avoid it when you need exact brand or legal accuracy, when photoreal human dialogue close-ups must be indistinguishable from live action, when you are demonstrating a precise user interface, or when a motion-graphics template or puppet rig would be both faster and more reliable.
On cost and time, the dominant factor is iteration, not model choice. A mildly cheaper model that takes three extra rounds to satisfy you is more expensive than a stronger one that lands in one. Reduce iterations by improving your stills, locking references, and writing tighter prompts. Resolution costs time, so generate at working resolution, approve the cut, and upscale only what survives the edit.
Finally, think in systems rather than one-off clips. A character sheet, a prompt template, a naming convention, and a rejection log turn a lucky generation into a repeatable process your whole team can use.
FAQ
How long should a generated clip be? Target three to five seconds for most shots. Longer clips are possible but harder to control and much harder to fix when something drifts midway.
Can I keep the same character across an entire series? Yes, with three habits: a fixed character sheet with multiple angles, multi-image reference conditioning, and a prompt template that repeats identity cues in every shot.
Do I need editing skills? Basic editing skills are essential. Generators produce shots; editors produce meaning. Timing, sound, and pacing live in the edit, and no prompt can replace them.
What about audio? Most pipelines generate visuals and audio separately. Some models produce synchronized speech or sound effects, which is convenient for dialogue-heavy shots, but bespoke sound design still beats generated ambience for anything client-facing.
How do I avoid the generic "AI look"? Vary shot length, allow imperfect framing, add grain or subtle handheld motion, and invest in real sound design. Uniform four-second clips with clean synthesized audio are the giveaway.
Can AI animation replace a full 3D or 2D animation pipeline? No. It is a complement. Use it for concepting, B-roll, stylized sequences, and volume work, and keep traditional pipelines for anything requiring precise rigging, exact timing, or repeatable character acting across long-form content.
What is the biggest quality win for the least effort? Spending thirty extra minutes on your reference stills. It improves every downstream shot, and it costs almost nothing compared to regenerating animations.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.