
Affiliazione
Inizia Gratis Ora
AI Video Generation Workflow for Busy Content Creators
Oct 15, 2026
Why AI Video Generation Became a Core Creator Skill
Video stopped being a specialty format and became the default one. Product pages open with a clip, onboarding emails link to a 30-second explainer, course modules are recorded segments, and social feeds prioritize motion. The problem is not demand. The problem is that traditional production is a straight line of dependencies: script, location, talent, lighting, camera, edit, sound, captions, revisions. Every step costs time, and every revision costs it again.
AI video generation compresses that line. A creator can now describe a scene, supply reference images, and get usable footage in the same afternoon. That does not mean the craft disappears. It means the craft shifts from operating equipment to directing intent: deciding what the video must accomplish, describing visuals precisely, judging output critically, and assembling fragments into something with rhythm.
A useful mental model is to treat generative video as a very fast, very literal production assistant. It will give you exactly what you asked for, including the parts you did not think through. The creators who get consistent results are the ones who bring a plan to the tool rather than hoping the tool will supply one.
This guide is a working playbook. It covers what modern AI video systems genuinely do well, where they still break, a repeatable production workflow, playbooks for different creator types, tool selection criteria, common mistakes, and a pre-publish checklist.
What Modern AI Video Tools Actually Do, and What They Do Not
Before building a workflow, get honest about capabilities. Marketing language blurs three different jobs: generating new footage, animating existing stills, and editing assembled video. Many tools do one well and the others poorly.
Text-to-video, image-to-video, and hybrid pipelines
Text-to-video generates a clip from a written description. It is excellent for establishing shots, abstract backgrounds, b-roll of generic scenes, and concept visualization. It is weakest when you need a specific person, a specific product, or precise text on screen.
Image-to-video takes one or more stills and adds motion: a slow push-in, drifting particles, a turning head, a moving camera. This is often the highest-value mode for creators because it reuses assets you already own. Product photos, illustrations, and stock images become moving sequences without a shoot.
Hybrid pipelines combine both: generate keyframes as images, refine them until they are exactly right, then animate them and join the clips. This is the approach serious creators settle into because it splits quality control into two manageable stages instead of one unpredictable one.
Consistency is the real bottleneck
Most viewer complaints about AI video are not about resolution. They are about continuity. A jacket changes shade between cuts. A character has three different jawlines. A room rearranges itself when the camera moves. Consistency is what separates a demo from a deliverable.
Modern tools attack this in several ways: reference images that anchor a character or product, seed values that make outputs reproducible, style references that carry a look across clips, and keyframe interpolation that fills motion between two defined frames. The practical takeaway is that you should define your anchors before generating: one character reference, one product reference, one palette, one lighting direction.
Where quality still breaks down
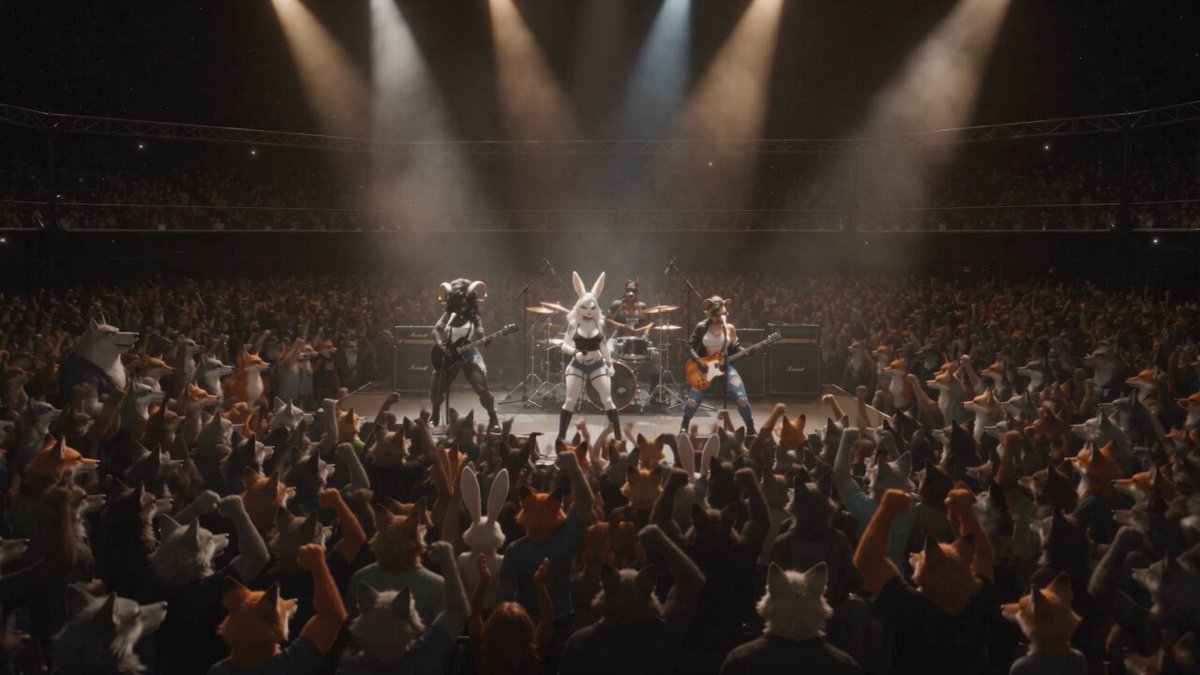
Expect trouble in predictable places. Hands interacting with objects. Text rendered inside the frame. Crowds. Complex physical interactions like liquid pouring or fabric folding. Fast camera moves combined with detailed backgrounds. Dialogue lip-sync in languages with distinctive mouth shapes.
The fix is not to fight these limits. Design around them. If a shot needs readable text, generate the plate without text and add the text in the edit. If a shot needs hands, frame tighter or use a cutaway. If a scene needs a crowd, keep it in the background and slightly out of focus.
A Repeatable AI Video Workflow
Ad hoc generation produces happy accidents, not a channel. A repeatable workflow produces something you can hand to a client, publish on schedule, and improve over time.
Start with the job the video has to do
Write one sentence: "This video must convince a first-time visitor that setup takes under five minutes." Everything downstream is judged against that sentence. Creators skip this step and end up with beautiful footage that does not sell, teach, or explain anything.
Write the script for the ear
Spoken language is shorter than written language. Read your script aloud and cut anything you stumble on. For a 60-second video, plan roughly 130 to 150 words of narration. For a 30-second social cut, keep it near 70 words. If you are not using narration, write the on-screen text first, because it dictates pacing.
Turn the script into a shot plan
Create a simple table with four columns: shot number, purpose, visual description, and duration. Purpose matters more than beauty. A shot either establishes, explains, proves, or transitions. If a shot has no purpose, cut it before you generate it.
For each shot, decide whether it should be generated from text, animated from an image, or captured practically. Mixing sources is normal and often necessary. A talking-head segment plus generated b-roll plus animated product stills is a completely legitimate structure.
Generate in small batches
Generate two to four variations per shot rather than one. Compare them side by side at small size, because differences that matter at full resolution are usually visible in thumbnails too. Keep a naming convention from the start: project_shot03_v2.mp4. You will generate more files than you expect, and searchability saves hours later.
Assemble and edit for rhythm
Generated clips rarely have the pacing you need. Cutting two seconds off the front and one off the back can transform a sluggish shot. Vary shot length deliberately: a run of three-second shots feels mechanical, while alternating one-second and four-second shots feels intentional.
Add sound, captions, and safe areas
Sound carries more perceived quality than most creators assume. A consistent ambient bed, subtle whooshes on transitions, and music that ducks under narration will make average footage feel professional. Add captions because a large share of viewers watch muted. Keep key text away from the edges of the frame so it survives vertical and square crops.
Run a quality pass, then version and archive
Watch the finished video once with sound, once muted, and once at 2x speed. Each pass catches different problems. Then export a master file, a vertical cut, and a square cut, and archive the project file with your prompts and reference images. Prompts are project assets. Losing them means losing the ability to make a consistent sequel.
Scene Blending and Multi-Image Fusion in Practice
Scene blending is the technique of joining visually distinct sources into a sequence that reads as one continuous piece. It is where AI video earns its keep for creators with existing asset libraries.
Travel and location sequences
A travel creator with photos from six cities can build a single montage with a consistent color grade and camera language. The trick is to pick one shared visual rule: same horizon height, same movement direction, same transition style. Without a shared rule, the montage feels like a slideshow.
Product stories across settings
An e-commerce team can show one product in a kitchen, on a desk, and outdoors without booking three locations. Generate the environment, animate the product still, and keep the product image as an anchor reference so the label and proportions stay intact. Always check logo legibility on the final render rather than trusting the preview.
Character continuity across cuts
For narrative work, lock a character reference image and reuse it in every shot, even when the character is small in frame. Change only the environment, camera angle, and action. If the character must change clothes, treat that as a scene break and re-anchor.
Style Adaptability Without Manual Redesign
Style controls let you move a project between aesthetics: documentary realism, soft watercolor, high-contrast cyberpunk, flat corporate illustration. The value is not novelty. It is the ability to test which look serves the message before committing budget.
A practical approach is to build two or three style presets and reuse them across a series. Presets create brand recognition, which is worth more than one-off visual cleverness. When testing a new style, apply it to a single hero shot first. If it survives a close-up of a face and a close-up of a product, it will usually survive everything else.
Keep a written style note alongside your presets: lens feel, contrast level, palette, grain, and motion intensity. Written notes prevent drift when you return to a project weeks later or hand it to a collaborator.
Workflow Playbooks by Creator Type
Social media managers
Volume matters. Build a template with a fixed hook, three body beats, and a call to action, then swap the visual content weekly. Generate a bank of b-roll clips in one session so you are never scrambling. Track which hooks perform and iterate on the script before you iterate on the visuals.
Educators and trainers
Clarity beats spectacle. Use generated visuals for abstract concepts, diagrams, and historical or inaccessible settings, and use screen recordings for anything a learner must replicate. Keep narration slow, chunk lessons into three-minute segments, and pair every concept with a visible example.
Independent filmmakers
Use AI for previsualization first. Generate the sequence before you shoot so you can test pacing, framing, and coverage decisions cheaply. For final work, use generated shots as inserts, transitions, and establishing material rather than the entire film. Audiences forgive stylization in inserts far more readily than in close-ups of actors.
Small e-commerce and service teams
Focus on the five assets that drive revenue: a hero clip, a how-it-works clip, an objection-handling clip, a testimonial visual bed, and a seasonal promo template. Reuse the same anchors every time so the brand looks coherent across channels.
How to Choose an AI Video Tool: Decision Criteria
Compare tools on the criteria that actually affect delivery, not on the length of a feature list.
- Output resolution and aspect ratios. Confirm native vertical and square exports if social is a priority.
- Reference and consistency controls. Character references, style references, and seed control matter more than raw generation speed.
- Clip length and continuation. Short clips are fine if the tool can continue a scene plausibly.
- Editing integration. Export formats, alpha channel support, and codec options determine how painful post-production is.
- Model flexibility. Access to multiple generation models inside one interface saves context switching.
- Learning curve. A tool you can operate confidently beats a better tool you avoid.
- Commercial usage terms. Read the license for the specific plan you intend to use.
- Team features. Shared asset libraries and comment threads reduce revision chaos.
Run the same test project through two candidates: a 30-second product explainer with one character, one product, and three environments. Whichever tool produces usable footage with fewer retries is the one to keep.
Common Mistakes That Kill AI Video Projects
Starting with the tool instead of the message. Pretty footage with no argument converts nobody.
Generating too much before reviewing. You end up with four hundred files and no decisions. Review in batches of ten.
Ignoring aspect ratios until the end. Reframing a finished horizontal edit into vertical is a rebuild, not an export.
Skipping audio. Silent drafts hide pacing problems that sound immediately exposes.
Using AI for the wrong shot. If a shot needs a real person's face, a real product, or readable text, shoot it or design it in post.
No naming convention. Version control saves more time than faster generation.
Chasing perfection on a single shot. If a shot has failed five times, change the approach rather than the prompt wording.
Forgetting accessibility. Captions, contrast, and legible text size are not optional.
Pre-Publish Quality Checklist
Run this before every upload.
- The first two seconds communicate the topic without sound.
- The video delivers on the promise in the title or thumbnail.
- No flickering, morphing artifacts, or warped hands in the final cut.
- Character, product, and wardrobe remain consistent across cuts.
- Text stays inside safe areas for every target aspect ratio.
- Audio levels are consistent, with music ducking under narration.
- Captions are accurate, including names and technical terms.
- The ending includes one clear next action.
- File naming and metadata are complete for future reuse.
FAQ
How long does an AI-assisted video take to produce?
A 60-second explainer with narration, b-roll, and captions typically takes two to five hours for an experienced creator, including generation retries. The first project in a new series takes longer because you are establishing anchors and templates.
Do I still need a script if the AI generates the visuals?
Yes. The script determines pacing, which determines shot length, which determines how much footage you need. Without a script, you generate footage you cannot use.
How do I keep a character consistent across many shots?
Create one strong reference image, reuse it in every prompt, keep lighting direction constant, and treat costume changes as scene breaks. Batch shots from the same environment together so corrections apply to the whole group.
Is generated video good enough for client work?
For inserts, backgrounds, product animation, and explainer visuals, usually yes. For footage where a real person's identity or an exact physical product is central, expect to combine generated material with real capture.
What is the fastest way to improve quality?
Improve the input. Better reference images, clearer shot descriptions, and shorter clips do more for output quality than switching tools.
Can I reuse prompts across projects?
You should. Save prompts with their reference images and style notes as reusable project kits. This is how a series maintains a consistent look while production speeds up over time.
How many variations should I generate per shot?
Two to four is the practical sweet spot. Fewer leaves you without options, and more overwhelms your ability to compare objectively.
What should I do when a shot will not work?
Change the constraint, not the wording. Simplify the background, reduce motion, split the action into two shots, or move the problematic element into post-production.
The Long Game
The creators who benefit most from AI video generation are not the ones chasing the newest model. They are the ones who built a workflow: a clear message, a shot plan, consistent anchors, disciplined review, and an archive of prompts and presets they can reuse. Tools will keep changing. A working process compounds regardless of which one you open tomorrow.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.