
Affiliazione
Inizia Gratis Ora
Cinematic AI: A Practical Guide to Visual Storytelling
Oct 13, 2026
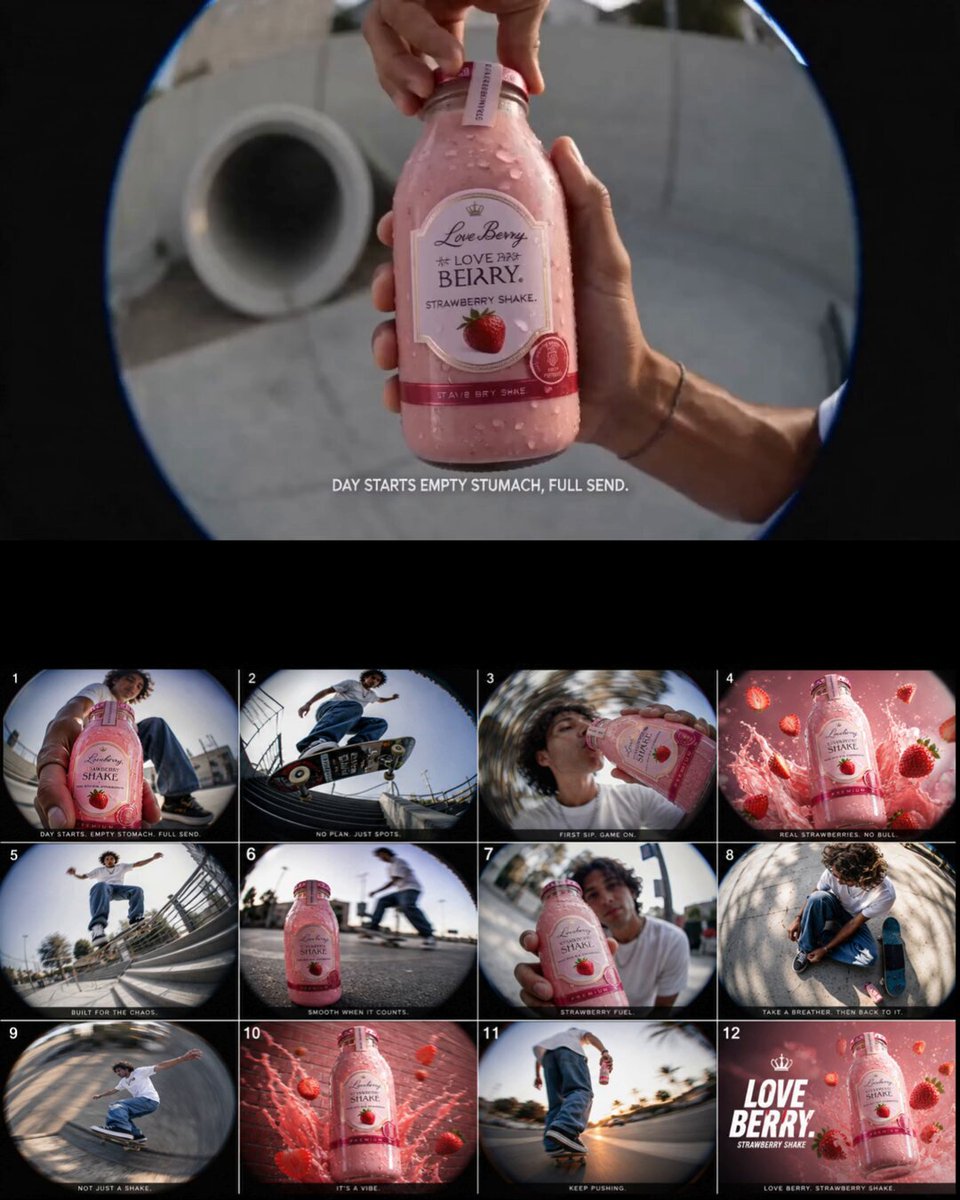
Cinematic AI has moved past the novelty stage. Shots that once required a crew, permits, a lighting truck, and a week of scheduling can now be blocked out on a laptop between coffee refills. But the flood of generated footage online also reveals the gap: most of it looks like a demo, not a film. The difference is rarely the model. It is the craft wrapped around the model — the shot design, the continuity, the sound, the edit, and the willingness to throw away nine generations to keep the tenth.
This guide is about closing that gap. It covers what makes footage feel cinematic, how the underlying models work and where they fail, how to choose tools for each stage, and a repeatable production workflow you can run on a single project or a weekly content calendar.
Why cinematic AI is reshaping visual storytelling
Visual storytelling is an old craft. Cave paintings, silent films, and vertical phone clips all rely on the same engine: a viewer wants to know what happens next. AI does not change that engine. What it changes is the cost and speed of producing the raw material.
That shift matters in three practical ways.
Iteration becomes cheap. A director used to get one or two chances at a difficult setup per shoot day. With generative tools, you can test five versions of a camera move before lunch and keep the one that actually serves the story.
Pre-visualization becomes real footage. Storyboards and animatics have always been useful, but they are abstract. When your pitch is a moving, lit, scored sequence, conversations with clients, collaborators, and stakeholders change completely.
Small teams can carry bigger ideas. A two-person team can now produce a branded short, a music video, or an explainer that once needed a dozen specialists. That does not mean the specialists are obsolete — it means the bottleneck moves from production capacity to taste and decision-making.
The risk is equally real. Generative tools make it easy to produce footage with no point of view: beautiful shots that never add up to a story. The rest of this guide is about avoiding that outcome.
The craft layer: what actually makes footage feel cinematic
Before touching a prompt box, get clear on the visual grammar you are trying to reproduce. Most "cinematic" qualities come from a small set of decisions that have nothing to do with AI.
Composition and lens language
Cinematic framing is intentional framing. That means choosing a focal length and sticking to it within a scene, placing subjects off-center when the story calls for tension, and using foreground elements to create depth. A wide lens close to a face distorts and feels intimate or aggressive. A long lens compresses and feels observational.
In practice, you can encode this in prompts with concrete language: "35mm lens, subject centered, shallow depth of field, background softly out of focus." Vague words like "cinematic" or "epic" do less work than a specific lens, distance, and framing choice.
Light, color, and contrast
Lighting is the single fastest way to separate amateur from professional-looking footage. Three patterns cover most needs:
- Key plus fill plus rim. A dominant light source, a softer fill to control shadow density, and a backlight to separate the subject from the background.
- Practical sources. Lamps, neon, screens, fire, and windows inside the frame. These give motivated light and a sense of place.
- Hard versus soft. Hard light creates defined shadows and drama; soft light flatters skin and reads as calm or corporate.
Color should follow the story, not a preset. A warm interior and a cold exterior tell the audience something about where safety lives. If every shot in your project has the same teal-and-orange grade, the grade stops communicating.
Motion, pacing, and sound
Motion is where AI video most often falls apart, so plan it deliberately. Decide whether the camera moves or the subject moves — rarely both aggressively in the same shot. Decide the speed: a slow dolly in creates anticipation, a handheld follow creates urgency, a locked-off frame creates stillness.
Pacing is an edit decision, not a generation decision. Generate longer clips than you need and cut them short. A three-second shot that lands is worth more than an eight-second shot that drifts.
Sound is the most underrated lever. Room tone, footsteps, cloth movement, a low drone, and a well-timed music drop will make mediocre footage feel intentional. Audiences forgive imperfect visuals far more readily than silence or mismatched audio.
How AI video models work — and where they break
You do not need to read research papers to get good results, but a mental model helps you predict failures instead of discovering them in a final render.
From diffusion to temporal consistency
Most current video generators build on diffusion techniques: start with noise, and iteratively denoise toward something that matches your prompt. Still-image models treat each frame as independent. Video models add a temporal layer that tries to keep frames consistent with each other, usually by attending to previous frames or by generating a compressed latent representation of motion.
The practical consequence: the model is constantly trying to decide what is plausible. When your prompt is ambiguous, it fills the gap with whatever is statistically common. That is why "a person walking" produces generic results while "a woman in a red raincoat walking away from camera through a wet market at dusk, handheld, 50mm" produces something with a point of view.
The failure modes to plan around
Expect these and design shots that survive them:
- Identity drift. Faces and clothing change across cuts. Fix with reference images, image-to-video, and tight shot variety that avoids holding on a face too long.
- Hands and fine detail. Fingers, jewelry, text, and complex props are still fragile. Frame them small, cut away, or place them off-screen.
- Physical impossibility. Liquids, collisions, and interactions between two moving subjects often wobble. Use them as background texture rather than story-critical action.
- Background morphing. Architecture and crowds shift between frames. Keep backgrounds simple or out of focus.
- Unmotivated camera drift. The model invents movement you did not ask for. Counter by specifying "locked-off tripod shot" or "slow push in" explicitly.
Designing around failure modes is not cheating. It is the same logic a practical filmmaker uses when they avoid a shot they know will be hard to light.
Choosing the right tool for each stage
There is no single best generator. There is a best generator for a given shot type, style, and budget.
Text-to-video, image-to-video, and video-to-video
Text-to-video is best for exploration: finding a look, testing a camera move, generating B-roll. It offers the most surprise and the least control.
Image-to-video is the workhorse for narrative work. Generate or shoot a strong still, then animate it. You keep the composition and the character design, and you only ask the model to solve motion.
Video-to-video and style transfer are for restyling existing footage — useful for animation looks, archival treatments, and turning a phone test shoot into a stylized sequence.
Specialized helpers: upscaling, lip sync, voice, and music
A finished piece usually passes through several tools:
- Upscaling and interpolation to bring a clip to delivery resolution and a smoother frame rate.
- Lip sync and facial performance tools for dialogue shots.
- Voice synthesis when you need narration in multiple languages or a scratch track before hiring a voice actor.
- Music and sound generation for beds and stingers, followed by a human pass on the mix.
Treat these as a pipeline, not a menu. The order matters: lock picture first, then sound, then finishing.
A repeatable production workflow
This is the sequence that keeps projects on schedule and prevents endless regeneration.
Step 1: concept and treatment
Write one page. Premise, tone, visual references, and the emotional beat at the end. If you cannot describe the feeling in a sentence, you are not ready to generate.
Step 2: shot list and keyframes
Break the piece into shots, each with a purpose, a duration, and a movement. Then produce a keyframe for each shot before generating any video. This single habit eliminates more wasted time than any other change you can make.
Step 3: continuity systems for characters and locations
Build a small reference library: one hero image per character, plus wardrobe, and one per location. Reuse those images as the starting point for image-to-video. Keep a written style block — lens, palette, lighting pattern, grain — and paste it into every prompt so the look stays consistent.
Step 4: generation passes and curation
Generate in batches of three to five variations per shot rather than one at a time. Score them immediately against three criteria: does it serve the story, is it physically believable, and does it cut with the neighbors. Delete ruthlessly. A shared folder with 200 clips you will never use is a liability.
Step 5: edit, sound design, and finishing
Edit for rhythm before you edit for prettiness. Cut on motion, keep shots shorter than feels comfortable, and let sound carry transitions. Then add color consistency, a subtle grain or film emulation pass, and a final mix. Export at delivery specs and check on the small screen, because most viewers will watch on a phone.
The five-part prompt template for cinematic shots
A reusable structure beats clever vocabulary.
Building the prompt
- Subject and action. Who, doing what, with what attitude.
- Environment. Location, time of day, weather, era, and one distinctive detail.
- Camera. Framing, lens, height, movement, and speed.
- Light and color. Source, quality, contrast, palette.
- Format and texture. Aspect ratio, grain, film stock feel, resolution cues.
An example: "A market fishmonger, mid-forties, slicing ice with calm precision. Wet stone floor, hanging bulbs, early morning, cold blue exterior light through an open door. Medium close-up, 50mm, eye level, slow handheld push in. Hard key from the doorway, warm practicals behind, deep shadow. 2.39:1, fine grain, muted palette."
Iterating without losing the shot
Change one variable at a time and label your versions. Keep a running note of what worked — "reduced motion instruction," "added 'no camera shake'" — because your project will need those answers again in week three.
Common mistakes that make AI footage look cheap
- Generic prompts. "Cinematic beautiful woman dancing" gives you stock imagery with wobble.
- Constant camera movement. Real films hold still far more often than beginners expect.
- Inconsistent look. Different palette and grain per shot reads as a slideshow.
- Explaining instead of showing. Long dialogue or narration over vague visuals kills momentum.
- Ignoring sound. Silent or lazily scored sequences feel unfinished.
- Holding shots too long. Cut before the illusion breaks.
- No reason for a shot to exist. Every shot should either advance information or advance feeling.
Ethics, rights, and disclosure
Generative work raises real questions you should answer before a client asks.
Confirm you have the right to use any reference images, voices, and music you feed into a pipeline. Avoid prompts that name living public figures or mimic a specific artist's identity. When a piece uses synthetic performance in a context where authenticity matters — news, testimonials, political content — disclose it clearly. Keep documentation of your sources and your generation process; it will save you in a revision round and it is increasingly expected by platforms and clients.
Also consider the human side. If you are replacing a shoot, be honest about what was replaced and what still needs a human: performance, judgment, and accountability.
FAQ
Do I need a powerful computer?
Most generation happens in the browser or in the cloud, so a mid-range laptop is often enough. Local processing helps mainly for upscaling, editing, and rendering.
How long does a one-minute cinematic piece take?
A tightly planned minute typically takes one to three days for a solo creator: a day for concept and keyframes, a day for generation and iterations, and a day for edit, sound, and finishing.
Should I generate or shoot the keyframes?
Either works. Shooting stills with a real camera and a real actor often gives better faces and lighting, then you animate them. Generating stills is faster and cheaper for abstract or impossible environments.
Why does my footage look soft and waxy?
Usually over-processing: too many upscale passes, aggressive smoothing, or heavy style transfer. Go back to the original generation and finish more gently.
How do I keep characters consistent?
Use one approved reference image per character, shoot mostly in medium and wide framings, keep wardrobe simple, and avoid extended close-ups.
Is AI video acceptable for client work?
Increasingly yes, especially for concept films, social content, and internal communication. Agree on disclosure and usage terms up front.
What aspect ratios should I deliver?
Generate in the ratio you will deliver. Cropping a 16:9 generation into 9:16 usually costs you composition, hands, and background detail.
Getting started this week
Pick a thirty-second idea you can finish, not a three-minute epic you cannot. Write the treatment, build six keyframes, generate three variations for each, and cut the best material to a scratch track. The point of the first project is not perfection — it is discovering your own bottlenecks, whether they are prompt clarity, continuity, or sound.
Then repeat with one deliberate upgrade per project: a stronger lighting plan, a real sound pass, a tighter edit, a consistent palette. Cinematic AI rewards the same things cinema always has — preparation, restraint, and a clear idea of what the audience should feel in the final seconds.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.