
Affiliazione
Inizia Gratis Ora
How Sora AI Creates Hyper-Realistic Video Scenes: A Deep Dive
Oct 15, 2026
Why hyper-realistic AI video changed the production pipeline
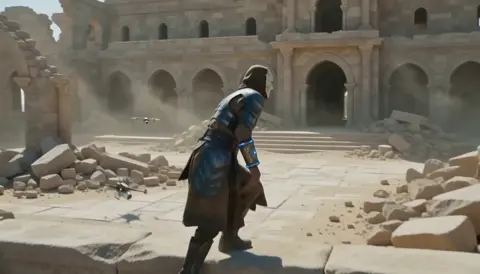
A few product cycles ago, text-to-video felt like a magic trick with a catch: the first second looked stunning, and the next second the protagonist's hands melted into each other. That gap has narrowed dramatically. Modern generators can hold a face steady through a camera move, keep a car's body panels rigid while it turns a corner, and render rain that obeys gravity instead of drifting sideways.
Hyper-realism is not one feature. In production terms it is four things working together:
- Temporal stability — no flicker, no identity drift, no background that reinvents itself between frames.
- Physical plausibility — objects carry consistent mass, light casts believable shadows, liquids behave like liquids.
- Camera logic — the shot behaves like something a camera operator could actually execute, with a coherent lens and perspective.
- Directorial intent — the clip communicates the subject, mood, and beat you asked for, not merely an attractive texture.
When those four line up, the output stops reading as AI video and starts reading as footage you can cut into a timeline. That is why pre-visualization artists, advertising teams, and independent filmmakers now treat these models as first-class parts of the pipeline rather than a novelty.
The interesting question is not what the models do, but how they get there. Understanding the mechanism is what lets you prompt, troubleshoot, and budget like a professional instead of a gambler.
Inside the architecture: diffusion meets transformers
Most capable video generators are hybrids. They borrow the image-making engine of diffusion and pair it with the sequence-modeling strength of transformers. That pairing explains almost every quirk you will run into.
From noise to motion: the denoising loop
A diffusion model begins with pure static and removes it in steps. Each step nudges the signal toward something more coherent, guided by your prompt. Trained on enormous numbers of examples, the model learns the statistical fingerprint of what a plausible image looks like at every level of noise.
Video extends the same idea into time. Rather than denoising a single frame, the model denoises a stack of frames together. Because the frames refine jointly, information flows between them: if frame twelve has a red jacket, frame thirteen knows it should too. This joint treatment is why generating frames independently and stitching them afterwards produces a very different, and usually worse, result.
Patch-based tokens and why consistency improves
Transformers do not read pixels. They read tokens — compressed chunks of data. A video is divided into patches, flattened into sequences, with time folded into the same representation. The model effectively perceives a clip as a long sentence of visual words.
That design has a practical consequence. When a subject travels across the frame, the model can attend to that subject's earlier appearance dozens of frames back. Long-range attention is what keeps a face, wardrobe, and environment coherent through a pan, a dolly, or an internal cut. It is also why a well-anchored first second tends to protect the rest of the clip.
What the transformer contributes
Diffusion supplies realism at the pixel level. The transformer supplies structure across time and space. Blended, they deliver fine detail and continuity at once — which is also why your wording influences not just the look of a frame but the behavior of the shot. Words that describe motion, such as slow push in or handheld drift, steer temporal structure. Words that describe surfaces, such as brushed aluminium or matte cotton, steer pixel detail. Learning to separate those two levers is one of the fastest ways to improve output.
How training data shapes realism
Generalization versus memorization
A video model trained on millions of clips learns regularities: how shadows fall at golden hour, how a person's weight shifts when they stand, how fabric folds at the elbow. This is generalization, and it is what allows a prompt describing a place that does not exist to still look convincing.
Memorization is the failure mode. If a specific scene appears too often in training data, the model may reproduce a recognizable artifact — a logo, a landmark, a signature composition. In practice, memorization shows up as output that looks oddly familiar and refuses to vary no matter how you rephrase the prompt. The fix is usually to change the semantic neighbourhood: alter the location, era, and lens rather than swapping synonyms.
Why data curation shows up in your output
The breadth of a training set determines stylistic range; the quality of curation determines native realism. Models trained with strong filtering produce cleaner hands, fewer text artifacts, and more consistent lighting. Models trained on narrower data produce distinctive aesthetics but break more easily on unfamiliar subjects.
When you evaluate any video tool, sample the categories you actually care about — close-up faces, food, architecture, fast action — instead of judging the demo reel. Demo reels are curated for the best case. Your project lives in the average case.
Physics, camera language, and temporal consistency
Why camera-move prompts actually work
Camera language is not decoration in a prompt. Terms like tracking shot, crane up, or shallow depth of field map onto consistent visual patterns in training data. A dolly move carries background parallax; a long lens compresses depth; a wide lens exaggerates it. When you specify a shot type, you borrow those patterns and give the model a strong prior about how the frame should evolve.
This is why a vague prompt often produces a drifting, ambiguous shot. With no camera instruction, the model averages several plausible motions and lands on something sluggish and slightly unstable.
Where physics breaks, and how to prompt around it
Typical failure zones:
- Contact and collision — objects passing through each other, feet sinking into floors.
- Fluids and cloth — water that flows but never splashes, garments that move like rubber.
- Fine manipulation — hands using tools, fingers on a keyboard.
- Crowd interaction — many subjects interacting with a single prop.
You rarely fix these by adding the word realistic. Better tactics: slow the action down in the prompt, reduce the number of simultaneous subjects, bring the camera closer so hands are larger and simpler, or split the action into two shots and cut between them. Editing is often a cheaper fix than another twenty generations.
A practical shot-by-shot workflow
Step 1: Write the shot list, not the scene
A scene is a paragraph; a shot is one camera setup with a clear beginning and end. Models handle a single beat far better than a montage. Convert every scene into shots of three to six seconds, each with one action, one camera behaviour, and one lighting condition. If a shot needs two ideas, it is two shots.
Step 2: Lock the look with reference frames
If your tool accepts images, use them. A still frame communicates more about palette, wardrobe, and composition than three sentences can. Generate or source a look frame first, then animate variations of it. Consistency across a sequence becomes dramatically easier when every clip starts from the same reference, the same colour grade, and the same lens description.
Step 3: Generate in short beats, then edit for rhythm
Generate more takes than you need, then assemble. Real editing rhythm — cutting on motion, holding a beat for emphasis, using a reaction shot — is where generated footage starts to feel cinematic. A two-second insert can rescue a clip whose fourth second falls apart. Never evaluate a take in isolation; drop it into the timeline and see whether the cut works.
Step 4: Post-production finishes the illusion
Treat generated clips as camera negative, not finished output. Stabilize jitter, colour-match between shots, add grain, layer in real sound design, and upscale only after editing. Sound is underrated here: crisp, well-timed audio makes viewers far more forgiving of minor visual imperfections. A clip with convincing footsteps and room tone reads as real even when the fine detail is soft.
Step 5: Keep a prompt log
Record the prompt, seed, reference frame, and settings for every take you use. When a client asks for a variation six weeks later, a log turns a day of guesswork into an hour of targeted regeneration.
Prompt patterns that raise perceived realism
Lighting vocabulary
Name the source and direction of light rather than its quality. Soft window light from camera left. Overcast diffused daylight. Single practical lamp inside the frame. Golden-hour backlight with a gentle flare. Directional language tells the model where shadows belong, and correct shadows do more for realism than any quality adjective.
Lens and format vocabulary
35mm lens with shallow depth of field. Anamorphic with soft flare. Wide lens, deep focus. Handheld documentary style. Format words also imply motion: handheld implies micro-shake, gimbal implies smooth tracking, tripod implies stillness.
Motion and pacing vocabulary
Slow push in. Static locked-off frame. Slight parallax from a passing foreground element. Subject enters frame right and settles. Describing what moves — and explicitly what stays still — reduces the model's tendency to animate everything at once.
A reusable prompt skeleton
Take a shot type, add a subject with specific attributes, give it one action, place it in an environment, then attach lighting, lens, one camera move, and a mood or grade. For example: medium shot of a pastry chef in a white apron plating a tart in a narrow kitchen, soft window light from camera left, 50mm lens with shallow depth of field, slow push in, warm neutral grade. That prompt is specific, contains a single action, and leaves little for the model to guess.
Real-world applications across film, ads, and training
Pre-visualization and pitch work. Directors use generated clips to communicate staging and mood before a shoot. A moving reference resolves arguments that storyboards cannot, and it costs a fraction of a test shoot day.
Advertising variants. Marketing teams produce multiple versions of one concept — different settings, product angles, or aesthetics — from a single base look, then test which performs. Keeping the reference frame fixed while changing the environment is the fastest route to a coherent campaign.
Education and training. Simulated environments for safety drills, equipment walkthroughs, and process explainers can be produced without a location shoot and updated quickly when procedures change. The key advantage is iteration speed, not photorealism.
Social and short-form content. Creators build recurring visual identities using reference-locked characters and reusable prompt templates, which is the difference between a one-off viral clip and a recognisable channel.
Archival and atmosphere. Documentary editors generate connective atmosphere shots — cityscapes, weather, textures — where licensing real footage would be slow or expensive. These inserts are usually a few seconds long, which is exactly the duration where these models are strongest.
Limits, ethics, and realistic expectations
Generated video is a prediction machine. It will occasionally invent physics that look wrong on the third viewing, and it should not be trusted to depict real events accurately. That makes labelling and disclosure essential, both for legal reasons and for audience trust.
Practical guardrails:
- Never generate a real person's likeness or voice without documented consent.
- Apply visible provenance markers or metadata where your platform supports it.
- Keep a written record of prompts and references used for anything client-facing.
- Budget time for review — a clip that passes at thumbnail size may fail on a large screen.
- Check the licensing terms of the specific model before commercial use, and re-check them as terms change.
On cost, think in terms of iteration. The expensive part of AI video is rarely the final render; it is the ten takes that did not work. Sharp shot lists, reference frames, and short durations reduce iteration count far more than any discount or plan upgrade.
Troubleshooting common realism failures
| Symptom | Likely cause | Fix |
|---|---|---|
| Faces drift between frames | Too many simultaneous subjects or too long a clip | Shorten to three or four seconds, single subject, add a reference frame |
| Background morphs | No scene anchor, ambiguous environment | Name materials, architecture, and weather; use a look frame |
| Motion feels floaty | No camera instruction | Specify a shot type and exactly one camera move |
| Hands look wrong | Fine manipulation seen from a distance | Move the camera closer, simplify the action, or cut away |
| Colours shift between shots | No shared reference | Generate all shots from one look frame and colour-match in post |
| Everything moves at once | Overloaded prompt | One action per clip; describe what stays still |
| Output looks familiar and repetitive | Prompt sits too close to a memorized pattern | Change location, era, and lens together |
Work through the table in order. Most realism complaints trace back to prompt overload or missing anchors rather than a limitation of the model itself.
FAQ
Is a hybrid diffusion-transformer model the only way to generate video?
No. Other families exist, including autoregressive token models and flow-matching approaches. They trade off differently: some are faster, some handle longer clips, some produce stronger temporal consistency at the cost of fine texture. If you are choosing a tool, test the same three prompts across candidates rather than comparing marketing pages.
Why does the same prompt produce different results each time?
Because sampling involves controlled randomness. Most tools expose a seed, and reusing a seed with an unchanged prompt usually reproduces a similar take. Changing the seed while keeping everything else fixed is the cheapest way to explore variations of a shot you almost like.
How long should a generated clip be?
Three to six seconds is the sweet spot for most work. Beyond that, the model has more opportunities to drift, and the value of a longer take rarely outweighs the risk. Build longer sequences by cutting several short shots together, exactly as you would with real footage.
How do I keep a character consistent across many clips?
Combine four things: a fixed reference image, an identical description block copy-pasted into every prompt, identical lighting and lens wording, and a consistent seed where the tool supports it. Finish with colour matching in post. Consistency is a system, not a single setting.
Do I need a powerful GPU to work this way?
Cloud tools remove the hardware requirement entirely, which is why most teams start there. Local generation becomes attractive when you need volume, strict privacy, or heavy fine-tuning, but it introduces setup and maintenance overhead. Choose based on how many iterations per day you actually run.
Can I use generated video for client work?
Often yes, with two conditions: the model's licence must permit commercial use, and your contract should state how synthetic footage is disclosed. Many brands now require a note in the deliverables list. Handling that upfront avoids awkward conversations later.
What is the single biggest realism upgrade?
Shorten the clip and specify one action. Almost every other improvement — lighting, lens, reference frames, post-production — compounds on top of that foundation. A tight, single-beat shot at four seconds will outperform a beautiful but overloaded ten-second shot in nearly every edit.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.