
AI Anime Photo Generator: Build a Stunning Art Portfolio
Oct 15, 2026
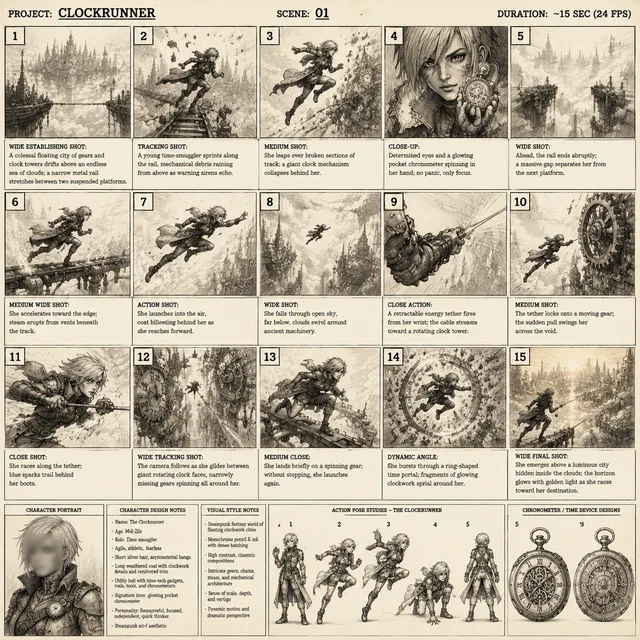
Anime illustration sits at a strange crossroads: instantly recognizable, endlessly variable, and surprisingly hard to do well. That combination is exactly why so many creators now build portfolios around AI anime photo generation. The tools lower the barrier to a first image, but they raise the bar for a body of work — and a body of work is what gets you hired, commissioned, or followed.
Why Anime-Style AI Art Has Become a Serious Portfolio Category
Streaming platforms commission anime-style key art for thumbnails. Game studios need character sheets at volume. Musicians want stylized covers. Indie authors want light-novel illustrations. Independent creators want avatars, stickers, and merch art. In every one of those cases, the buyer is not purchasing a single image — they are purchasing a look they can return to.
That is the core shift. Generating one passable anime portrait takes about ninety seconds. Generating twelve images that clearly belong to the same artist, world, and visual grammar takes planning, a repeatable workflow, and a willingness to edit.
Three qualities separate a folder of experiments from an actual portfolio:
- Coherence. Line quality, palette, rendering style, and level of detail stay stable across every piece.
- Range inside a style. You show different poses, expressions, environments, and moods — all recognizably from the same visual universe.
- Intent. Each image earns its place. You can explain why it is there and what it demonstrates.
If you can hit those three, the specific generator you use becomes almost irrelevant to the audience. If you miss them, even the most advanced model will produce work that reads as random.
How AI Anime Image Generation Actually Works
Nearly all modern anime generators are diffusion models. The model learns to reverse a noise process: given a scrambled image and a text description, it predicts the noise to remove, step by step, until a coherent picture emerges. Understanding a few moving parts makes you dramatically better at steering it.
The text encoder converts your prompt into a numeric representation. Words that appear rarely in training data get interpreted loosely, which is why "anime style" is a weak instruction and "1990s OVA cel animation, visible ink line, flat shadow shapes" is a strong one.
The sampler and step count control how the noise is resolved. Fewer steps can produce a bolder, more graphic look; more steps refine detail but can also smooth away texture and personality.
Guidance scale decides how literally the model follows your text. Push it too high and colors burn, anatomy stiffens, and compositions become predictable. Too low and the model ignores you.
The seed fixes the starting noise. Reusing a seed while changing one part of the prompt is the single most reliable way to explore variations of a composition instead of starting over.
Style itself comes from three sources: the base model's training data, style adapters (small add-on weights trained on a specific artist-like aesthetic), and reference conditioning (where you feed an image or character reference into the pipeline alongside text). Most professional-looking anime output uses all three.
What "Photo Generator" Usually Means
The phrase covers three different jobs, and mixing them up wastes time:
- Photo-to-anime translation — you upload a photograph and the model restyles it while preserving the pose and framing.
- Photoreal rendering with anime stylization — the model produces something semi-realistic but with anime proportions, hair, and eyes.
- Text-to-image with anime presets — the classic case; a written prompt generates the image from scratch.
Knowing which mode you are in determines your prompt strategy. In translation mode, your prompt should describe the style change, not the subject. In text-to-image mode, you must describe everything: subject, styling, camera, and light.
Choosing the Right Generator for Anime Work
There is no single best tool, only the right fit for your constraints. Judge candidates against these criteria rather than against a showcase gallery.
| Criterion | What to look for | Why it matters |
|---|---|---|
| Style fidelity | Strong anime/cel-shaded output without heavy prompting | Saves prompt tokens and reduces wasted batches |
| Consistency tools | Fixed seeds, character references, style adapters | Consistency is the hard part of a portfolio |
| Control inputs | Pose, depth, and line-art conditioning | Essential for matched sets and action poses |
| Resolution handling | Clean two-stage or tiled upscaling | Wall art and print need large, artifact-free files |
| Batch and variant controls | Adjustable batch size, variation strength | Determines how fast you can explore |
| Licensing terms | Clear commercial-use rules | Protects client and merch work |
| Hardware fit | Local GPU versus cloud rendering | Affects iteration speed more than quality |
| Learning curve | Node graphs versus plain text boxes | Node-based tools give control, plain tools give momentum |
Broadly, tools fall into five families: cloud all-in-one generators, local diffusion installs with style adapters, node-based pipelines for precise control, dedicated anime-focused apps with curated presets, and mobile apps for quick concept sketches. Many creators run two: a fast cloud option for ideation and a local or node-based setup for final renders.
Prompt Architecture: A Reusable Anime Style Recipe
The biggest mistake beginners make is writing a different prompt every time. A portfolio needs a template with a few slots that change.
The Five-Part Formula
- Subject — who or what, with one distinguishing detail.
- Character design — hair silhouette, eye shape, outfit, signature accessory.
- Style — era, medium, line treatment, shading model.
- Composition and camera — shot distance, angle, focal feel.
- Light and finish — key light direction, palette limit, texture notes.
A worked example:
a young swordswoman on a rain-slick rooftop, short black bob with a single red streak, cel-shaded late-1990s OVA style, visible ink line art with flat shadow shapes, three-quarter shot at eye level, teal and magenta neon reflections, soft rim light, limited palette, clean background separation
Every later image in the series keeps this skeleton and swaps slot one plus the camera line. That is how you get twelve images that look like one artist.
Keep a Token Budget
Longer prompts are not better. Beyond roughly sixty to eighty meaningful tokens, additional descriptions compete for attention and produce muddled results. Front-load the details you cannot live without, and delete anything the model already assumes from your style string.
Negative Prompts Do Real Work
A short, consistent negative list prevents the most common anime failures:
- extra fingers, fused hands, malformed eyes
- text, signatures, watermarks, UI overlays
- photorealistic skin texture, 3D render gloss
- muddy low-contrast haze, oversaturated neon bleed
Keep it short. A bloated negative list can strip the very texture you wanted.
Weights and Ordering
Emphasis syntax varies between tools, so test rather than assume. In general, placing a term earlier and wrapping it in your tool's emphasis markers strengthens it. One strong modifier beats five weak ones; "dramatic backlight" does more than "nice lighting, good lighting, cinematic lighting".
Building a Character and Style Bible
Before generating further, write two documents. They take twenty minutes and save hours.
The world/style sheet contains your style string verbatim, a palette with hex values, line-weight notes, allowed shading models (flat cel, soft gradient, screentone), and forbidden elements.
The character sheet contains per-character details: hair silhouette from front and side, eye shape and color, default outfit plus two variants, one signature accessory, and approved camera distances. Add a seed log with the seed, prompt version, and adapter settings used for each approved image.
Why bother? Because memory is unreliable and diffusion models are literal. The sheet also becomes your handoff document if you ever bring in a colorist, an animator, or a collaborator — and it is the difference between a hobby folder and something you can pitch.
A Step-by-Step Workflow from Concept to Finished Set
Step 1 — Define the Collection
Pick one concept and 8–12 images. More than twelve and you lose coherence; fewer than eight and it reads as a test. Sketch the beats in a sentence each: an establishing shot, a portrait, an action moment, a quiet character piece, a detail close-up, a group shot.
Step 2 — Lock the Style with a Cheap Test Batch
Generate twenty to thirty low-resolution images with wildly different style strings. Pick the three that feel closest to your target, then merge their wording into a single style string. Do not skip this. Choosing a style after you have already rendered hero images means redoing everything.
Step 3 — Generate Wide, Then Narrow
For each beat, produce four to eight candidates, changing only one variable per batch: pose, then camera, then lighting. Changing everything at once makes results impossible to learn from. Most generators offer a variation strength slider — keep it around the middle so results are related but not clones.
Step 4 — Enforce Consistency
Lock the seed for a composition, keep the prompt skeleton stable, and use a character reference image where the tool supports it. For action poses, feed a rough stick-figure sketch or a depth map through a control input so the model solves style rather than anatomy.
Step 5 — Upscale and Clean
Use two stages. First a moderate upscale (1.5–2x) with low denoise strength, around 0.2–0.35, to add resolution without changing the drawing. Then a tiled upscale for fine detail. Apply face restoration last and lightly — aggressive restoration flattens anime faces into a doll-like sameness.
Step 6 — Assemble and Sequence
Lay the images out in the intended viewing order. Cut anything that repeats a pose, palette, or composition already covered. A tight set of nine beats a loose set of eighteen every time.
Post-Processing Without Losing the Anime Look
Generated images usually need three passes, not thirty.
Line integrity. Check whether the line art is crisp or slightly mushy. A subtle contrast curve plus a light high-pass sharpen can restore ink quality. Over-sharpening creates halos along hair edges, which reads instantly as machine output.
Color grading. Adjust curves and levels for the palette you committed to. Anime styles reward limited palettes; if the piece has five competing hues, reduce saturation on the two least important.
Hand fixes. Repaint hands, eyes, and any structural errors directly. Inpainting a hand at high denoise with a tight mask often works, but for hero images a five-minute manual paint-over is faster and cleaner. Adding a screentone or halftone overlay on shadows can unify a piece that feels too smooth.
Export PNG for print and high-quality JPEG (quality 90+) for web. Keep a layered working file so corrections never require a full re-render.
Common Mistakes That Weaken an AI Anime Portfolio
- Style drift. Thirty images in thirty rendering styles reads as a sampler, not a portfolio. Fix: one style string, one palette, one line treatment.
- Same face syndrome. Every character shares identical eyes and jaw. Fix: vary eye shape and face structure parameters explicitly in the character sheet.
- Overstuffed prompts. Fifteen descriptors produce a muddy average of all of them. Fix: five slots, three details each.
- Relying on upscaling. If the composition is weak at low resolution, it stays weak at high resolution. Fix: approve thumbnails before rendering detail.
- Ignoring consent and licensing. Restyling real people's photographs requires permission, and commercial use depends on the tool's terms. Fix: check both before you publish.
- Never touching a brush. Purely generated work is easy to spot at the edges and hands. Fix: budget a manual cleanup pass per hero image.
- Publishing everything. Volume buries your best pieces. Fix: curate to twelve to twenty.
Presenting Your Portfolio and Collecting Feedback
Group images by series, not by date. Keep aspect ratios consistent within a series so a grid view reads cleanly. Write a one-line caption per image describing the intent, and include alt text for accessibility — it also helps search visibility.
Process posts outperform finished-image dumps. Showing a sketch, an early draft, and the final render tells viewers you have a method worth commissioning.
When asking for critique, ask structured questions rather than "what do you think?" Three reliable ones: Does the set look like one artist? Which image is weakest and why? Where does the style break? Then separate taste feedback from technical feedback, and act only on the technical notes first.
FAQ
How many images do I need for a portfolio?
Twelve to twenty finished pieces, ideally arranged as two or three series of six to ten each. Depth within a series signals control; breadth across series signals range.
Do I need an expensive GPU?
No. Cloud generators handle everything for concept work. A local setup becomes worthwhile when you want rapid iteration, style adapters, or precise control inputs without per-image latency.
How do I keep the same character across many images?
Three levers, used together: a fixed description block, a character reference image, and a control input for pose. Seeds hold composition; references hold identity; controls hold anatomy.
Is photo-to-anime restyling of real photos acceptable?
For your own photos, yes. For photos of other people, get permission before publishing, and check whether the tool's terms allow commercial output from uploaded images.
What resolution should I generate and export?
Generate at the model's native resolution, then upscale to roughly 2000–3000 pixels on the long edge for digital use, and 300 DPI at print size for physical products.
Should I disclose that I use AI tools?
Disclose when the context expects it — client work, competitions, and platforms with specific rules. Honesty about process rarely damages a portfolio; inconsistency does.
Why do all my characters look identical?
Usually because the character design slot in your prompt is too vague and the model falls back on its most common training pattern. Specify eye shape, face structure, hair silhouette, and age impression explicitly.
Can I sell prints or merchandise from generated anime art?
That depends entirely on the licence of the model and hosting platform you used. Read the terms carefully, keep records of the tools and versions used for each piece, and prefer tools with clear commercial-use language for anything you intend to sell.
Build the style bible, lock the skeleton prompt, test cheaply, and edit by hand. The generator gets you to the first image; the workflow is what gets you a portfolio.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.