
Utwórz
AI Video Generation Workflow: From Prompt to Polished Cut
Oct 13, 2026
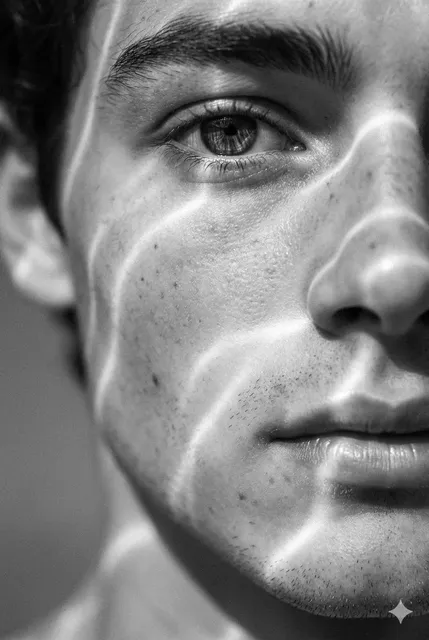
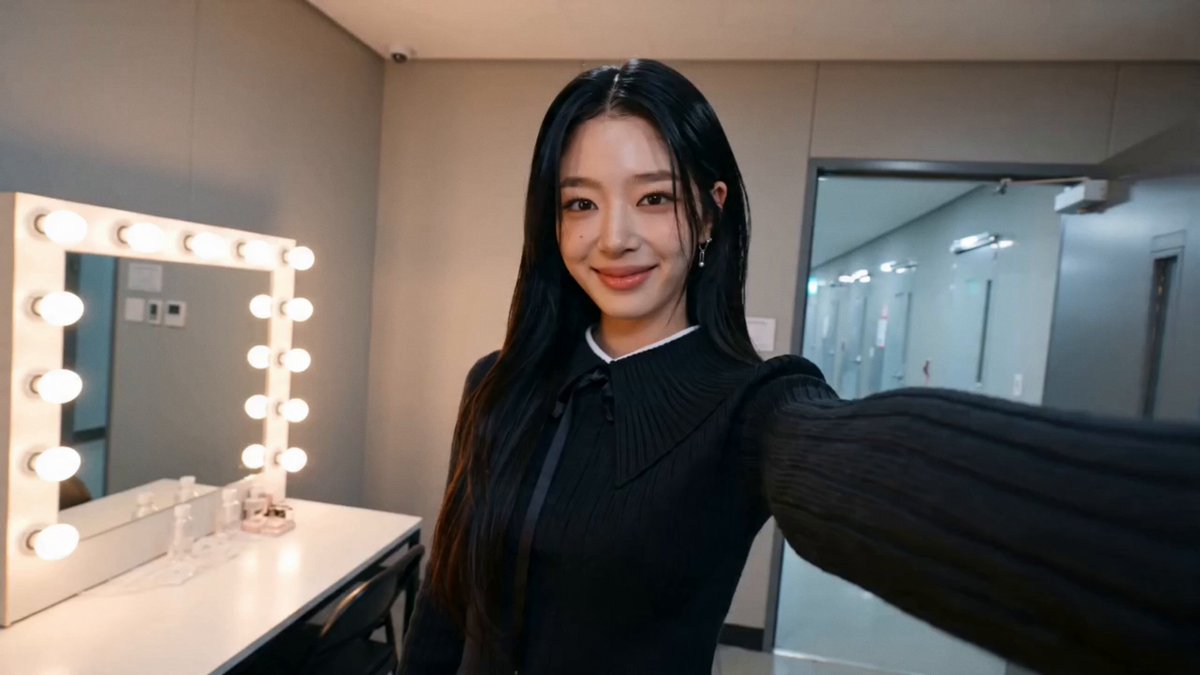
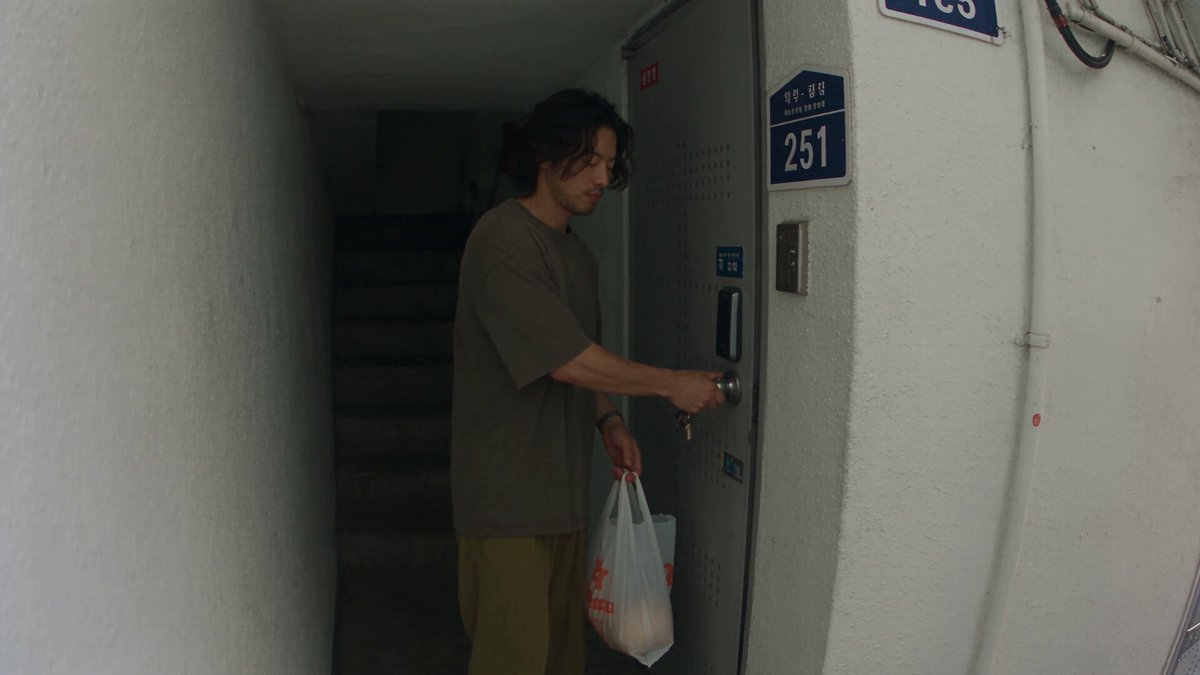
Why AI Video Generation Rewired the Production Pipeline
Generative video stopped being a novelty the moment teams realized it compressed the most expensive part of production: the distance between an idea and something watchable. A shot that once required a location scout, a crew call, a lighting package, and a permit can now be prototyped in an afternoon. That does not remove craft — it relocates it. The scarce skills become planning, continuity, and editorial judgment instead of logistics.
Three forces are driving the shift. Iteration cost has collapsed, so a director can test five visual interpretations of a scene before lunch. Distribution has fragmented, so a single deliverable now needs vertical, square, and widescreen variants built from the same source material. And audience expectations have recalibrated: viewers have seen enough synthetic footage to notice when motion is uncanny, so polish matters more than novelty.
The practical consequence is that AI video is no longer a separate category of work. It is a stage in a pipeline, sitting between the script and the edit, and it behaves best when it is treated that way. Teams that build a repeatable workflow get consistent output and predictable schedules. Teams that treat every generation as a lottery ticket end up spending their budget on retries and their evenings on cleanup.
There is also a quiet organizational benefit. When a rough visual exists early, feedback changes character. Stakeholders stop arguing about abstract descriptions and start reacting to a frame, which shortens approval cycles and surfaces disagreements while they are still cheap to fix.
How Modern AI Video Models Work
You do not need to read research papers to get good results, but a working mental model saves hours. Most current systems are diffusion-based or transformer-based generators trained on large collections of video paired with text descriptions. They learn a compressed representation of how motion, light, and material behave over time, then sample new sequences that satisfy a written prompt.
That has a practical implication: the model is not retrieving footage, it is predicting it. Everything it produces is an average of patterns it has seen, which is exactly why specificity in your instructions changes the result so dramatically.
Text-to-video, image-to-video, and video-to-video
Text-to-video generates a clip from a written description alone. It is the most flexible option and the least controllable, which makes it ideal for mood boards, background plates, and abstract transitions.
Image-to-video starts from a still frame and animates it. Because the first frame is fixed, composition, palette, and character appearance are locked before generation begins. For narrative work this is usually the highest-value mode: you control the frame, and the model supplies the motion.
Video-to-video takes existing footage and restyles or transforms it while preserving motion and timing. It is the workhorse for brand-consistent looks, rotoscoped effects, and turning generic stock into something ownable.
Duration, resolution, and motion coherence
Clip length is the constraint that shapes everything else. Short generations are more stable; long ones drift. A reliable strategy is to treat the model as a source of three-to-ten-second units and build the sequence in an editor, where you have frame-accurate control over timing, rhythm, and transitions.
Motion coherence — whether a hand stays a hand, whether a car keeps its shape — is the metric that separates usable output from interesting accidents. Coherence improves when the prompt describes one clear action, when the camera instruction is simple, and when the subject is well lit, centered, and moving within a plausible range of speed.
The End-to-End AI Video Workflow
A workflow is what turns a tool into a capability. The following sequence works for commercials, social spots, explainers, product loops, and narrative shorts alike.
Step 1: Define the deliverable before opening a tool
Decide aspect ratio, duration, platform, and tone first. A thirty-second vertical spot has different pacing needs than a widescreen hero film, and generating before you know the frame wastes iterations. Write a one-sentence creative brief and keep it visible on screen while you work.
Step 2: Write a shot list, not a prompt
Professionals storyboard. A shot list forces you to name the subject, the action, the camera, and the emotional beat in each unit. When you later translate those lines into prompts, the model receives consistent intent instead of a wandering description.
Step 3: Lock the look with stills
Generate or source key frames before animating anything. Still generation is faster and easier to revise than video, so it is where you iterate on palette, wardrobe, and composition. Once a frame looks right, image-to-video converts it into motion with far less randomness than text alone.
Step 4: Generate in short, reviewable bursts
Produce many short clips rather than a few long ones. Review them at speed, keep the winners, and name files by shot number. A clip that looks wrong at three seconds will not improve at eight.
Step 5: Assemble in a real editor
The timeline is where AI video becomes film. Trim on motion, add cutaways, layer sound design, and grade the sequence so all shots share a consistent look. Models rarely produce a finished piece on their own; they produce rushes, and rushes need an edit.
Step 6: Archive prompts alongside renders
Keep each prompt, seed, reference image, and setting next to the final file. When a client asks for a variant six weeks later, reproducibility is worth more than any single lucky generation.
Prompting Craft That Actually Changes the Output
Prompt writing for video is closer to directing than to describing. Vague adjectives produce vague motion; specific instructions produce specific motion.
The six slots of a strong video prompt
Build each prompt from six slots: subject, action, setting, camera, lighting, and style. For example: a ceramicist (subject) presses a thumb into wet clay (action) in a sunlit studio (setting), slow dolly-in at eye level (camera), soft window light with warm falloff (lighting), documentary realism with shallow depth of field (style). Filling all six slots prevents the model from guessing.
Negative prompts and drift control
Most tools accept a negative list. Useful entries include extra fingers, morphing faces, text artifacts, jump cuts, and warped geometry. Negatives are not magic, but they reduce the frequency of the failures you already know you will see.
Iteration discipline: change one variable
When a clip fails, resist rewriting the whole prompt. Change the camera move or the lighting, not both. One-variable iteration teaches you what the model responds to and builds a reusable mental library of phrasing that works across projects.
Consistency: The Hardest Problem in AI Video
Audiences forgive an imperfect frame; they do not forgive a character whose jacket changes color between cuts. Consistency is the difference between a demo and a deliverable.
Three techniques carry most of the weight. First, anchor with reference images — a locked still of each character, prop, and location, reused as the starting frame for every shot in that scene. Second, keep a style block: a fixed string of descriptors for lens, palette, and grade that you paste into every prompt in the project. Third, describe wardrobe, hair, and key props explicitly in each prompt rather than trusting the model to remember, because most systems carry no memory between generations.
Beyond visuals, keep temporal consistency: match action direction, eyelines, and screen position across a cut. A character exiting frame right should enter the next shot from frame left. Small editorial rules like this do more for believability than any single generation setting.
A useful habit is to build a continuity sheet before generating anything, listing each character, prop, and location with its locked descriptors. The sheet becomes the single source of truth everyone references, and it prevents the slow drift that happens when five people generate shots independently.
Choosing a Tool: A Practical Decision Framework
Tool choice should follow the job, not the hype. Score candidates on five criteria.
Control: does the tool support image-to-video, camera instructions, and negative prompts? For narrative and brand work, control beats raw quality.
Coherence: how well does motion hold up across the full clip length? Test with a moving hand, a turning head, and a reflective surface.
Speed: how long does a draft take? Fast drafts mean more experiments per hour, which usually outweighs a marginal quality edge.
Output format: resolution, frame rate, aspect ratios, and whether the export is clean enough to drop straight into an edit without artifacts.
Cost model: predictable subscriptions suit high-volume production, while per-generation pricing suits exploratory work. Match the pricing model to the work, not to the marketing page.
Run the same test prompt through two or three tools before committing. A five-minute comparison tells you more than any feature list, and the right answer often depends on whether you are making stylized loops or photoreal narrative footage.
Fitting AI Video Into a Publishing Rhythm
The most common failure in AI video is treating it as a one-off project rather than a repeatable format. Formats scale; one-offs do not.
Start by finding a format the tool is naturally good at: a recurring visual essay, an animated explainer series, a stylized product loop, or a mood-driven music cut. Define a template with fixed duration, aspect ratio, typography, and audio bed. Then produce episodes in batches — write five scripts, generate all stills, animate all clips, and edit them in a single pass. Batching dramatically improves consistency because you hold the style in your head across the entire set.
Keep a small library of reusable assets too: establishing shots, transitions, texture overlays, and sound effects. Reuse is what makes a weekly cadence realistic, and it also trains your audience to recognize the format instantly.
A practical start-to-finish checklist
Pick one format and one tool. Write a one-page brief with aspect ratio, duration, and tone. Build a shot list of eight to twelve units. Generate stills until the look is right. Animate with image-to-video. Assemble a rough cut with temporary music. Replace weak shots one at a time. Grade, mix, and caption. Publish, log your prompts, and keep the assets you reused. Then repeat — the second episode will take half as long as the first.
Mistakes That Kill AI Video Projects
Chasing realism when style would be faster. Photoreal humans are the hardest thing to generate convincingly. Stylized, animated, or product-focused footage often looks better and costs less effort.
Prompting a whole scene in one line. Models handle one clear action well and three poorly. Break scenes into beats and generate each beat separately.
Skipping sound. Viewers judge polish by audio as much as by picture. Ambience, foley, and a music bed rescue imperfect motion and lift good motion further.
Generating without a shot list. Without a plan you accumulate clips that do not cut together, no matter how good each one looks in isolation.
Ignoring the edit until the end. Assemble rough cuts early; the timeline reveals which shots you actually need and which generations were wasted effort.
Overlooking text and hands. Both remain weak points. Frame around them, avoid on-screen text inside generated shots, and add titles in post where you control typography.
Rights, Disclosure, and Quality Control
Two questions come up in every commercial context: what can you use, and what must you say?
On rights, check the terms of the specific tool for commercial use, and be careful with prompts that imitate a living artist, a trademarked character, or a recognizable person. Use reference material you own or that is properly licensed. Keep provenance: a simple log of tool, date, prompt, and source assets protects you later and makes client review painless.
On disclosure, follow the platform policy for synthetic media and the expectations of your audience. Many brands now label AI-assisted visuals voluntarily, and audiences generally respond well when the label is not the point of the piece. Where a person's voice, face, or likeness is synthesized, consent is not optional.
Finally, build a quality gate. Before anything is published, it should pass three checks: technical (resolution, frame rate, audio levels), continuity (character, wardrobe, direction of movement), and editorial (does it say what we meant to say?). A five-minute review catches the errors that erode trust.
FAQ
Is AI video good enough for professional work?
For stylized, product, B-roll, and motion-graphics-led content, yes — routinely. For photoreal human performance in close-up, quality is improving quickly but still benefits from careful shot design, shorter clips, and strong sound.
Do I need a powerful computer?
Most capable models run in the cloud, so a standard laptop and a stable connection are enough for production work. Local models exist but demand a strong GPU and more patience.
How long does a short film take?
A thirty-second piece with ten to fifteen shots typically takes one to three days from script to locked cut once your workflow and asset library are in place. The first project always takes longer.
Should I generate video or stills first?
Stills first, almost always. They are faster, easier to revise, and they lock the look before you spend effort on motion.
What about audio?
Generate or license it separately. Dialogue, music, and sound design handled in a normal editor will outperform anything bolted on inside a video generator.
How do I keep characters consistent?
Use reference images, a fixed style block, explicit wardrobe descriptions, and matched action direction in the edit. Consistency is a process, not a setting.
Will AI replace editors and cinematographers?
It changes the ratio of planning to shooting and makes editing more central, not less. The judgment about what to keep and why remains human work.
Where This Leaves Your Next Project
AI video is at its best when it is treated as one stage in a longer pipeline rather than a magic button. Write the brief, build the shot list, lock the stills, animate in short units, and finish in an editor with real sound and real pacing. Keep a continuity sheet, iterate one variable at a time, and archive every prompt next to the render that came from it.
Do that consistently and the technology stops being the story. What remains is the part that always mattered: a clear idea, delivered with enough craft that the audience never thinks about how it was made.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.