
How to Use AI Tools to Create Engaging Video Podcasts
Oct 15, 2026
Why video podcasts set a higher production bar
Audio podcasts forgive a lot. A slightly dull room, an occasional cough, a guest who leans away from the microphone — listeners tolerate these because the medium is intimate and mostly invisible. Video removes that forgiveness. Viewers see the lighting mismatch between two remote guests, the jump cut that breaks eyeline, the caption that lands half a second behind the punchline. That is exactly why AI assistance has become common in video podcast production: not to replace the host, but to close the gap between what a two-person team can actually shoot and what an audience now expects to watch.
The other shift is structural. Video has become the default discovery surface for spoken-word content. Platforms that were once audio-first now push video versions of episodes, and short vertical clips drive most new listener acquisition. A single recording session is now expected to produce a long-form episode, several short clips, a transcript, and sometimes a translated version. That is where shows die — not at the recording stage, but at the "we have forty hours of raw footage and no plan" stage.
AI changes the math on that bottleneck. Speech-to-text editing lets you cut by deleting words. Auto-reframing turns a horizontal recording into vertical clips. Voice models repair broken takes or produce translated dubs. Avatar presenters can front a show when there is no camera-ready host. None of these tools are magic, and most fail loudly when pushed past their limits. The rest of this guide covers where each category genuinely helps, where it hurts, and how to assemble the pieces into a workflow you can repeat every single week.
Mapping the AI video podcast workflow end to end
Before evaluating a single tool, sketch the pipeline. Every video podcast, whether it is a solo monologue or a five-person panel, moves through the same stages:
- Concept and format selection
- Script or rundown preparation
- Recording (local, remote, or hybrid)
- Audio repair and dialogue cleanup
- Rough cut and structural edit
- Visual polish, graphics, and b-roll
- Captions, transcripts, and translations
- Quality control and export
- Publishing and distribution
- Repurposing into short-form clips
AI touches every stage, but it delivers the biggest return in stages four through seven, where the work is repetitive, rule-based, and time-consuming. It delivers the smallest return in stages one and two, where taste and point of view matter more than speed.
Pre-production decisions that save hours later
The single most useful pre-production habit is deciding your deliverables before you record. If you know you need three vertical clips, a 45-minute main episode, and a transcript, you can shoot with those outputs in mind: keep questions tight, avoid overlapping speech, and leave clean pauses where clips can start and end.
A realistic pre-production checklist looks like this:
- Show format: interview, solo commentary, panel, or documentary-style narrative
- Segment template: cold open, intro bumper, main conversation, listener questions, outro
- Deliverable list: long-form episode, short clips, audiogram, transcript, blog post
- Visual bible: color palette, lower-third style, intro animation, caption font
- Guest brief: microphone advice, quiet room, wired connection, no speakerphone
Recording: source quality beats any cleanup tool
No AI audio tool can fully rescue a bad recording. It can reduce noise, level uneven dialogue, and remove some room reverb, but it cannot invent detail that was never captured. The practical rules are boring and effective:
- Record locally when possible, even during remote interviews, so you have an uncompressed per-person track
- Ask guests to wear headphones to prevent echo and bleed
- Position the microphone a hand-width from the mouth, slightly off-axis
- Use a clap or a spoken marker at the start to make synchronization trivial
- Capture in 48 kHz WAV or a high-bitrate equivalent
- Light both sides of the frame at roughly 45 degrees, and match color temperature between cameras
- Keep the eyeline consistent so cuts do not feel like the host is looking somewhere else
If you record remote guests, insist on separate local recordings rather than relying only on a cloud capture. It is the difference between audio that needs ten minutes of cleanup and audio that needs an hour.
Tool categories and how to evaluate them
There is no single "best" AI tool for video podcasts, because the category is really five different job types wearing the same label. Evaluate tools per job rather than per brand.
Presenter and avatar tools
Avatar-based presenters are most useful when you need a host on screen but cannot or do not want to film one: faceless explainer shows, internal communication podcasts, localized versions of an existing episode, or a solo show where the host prefers not to appear on camera.
What to check before committing:
- Lip-sync accuracy on fast speech, names, and numbers
- Head and hand motion naturalness — robotic micro-movements are the fastest way to lose a viewer
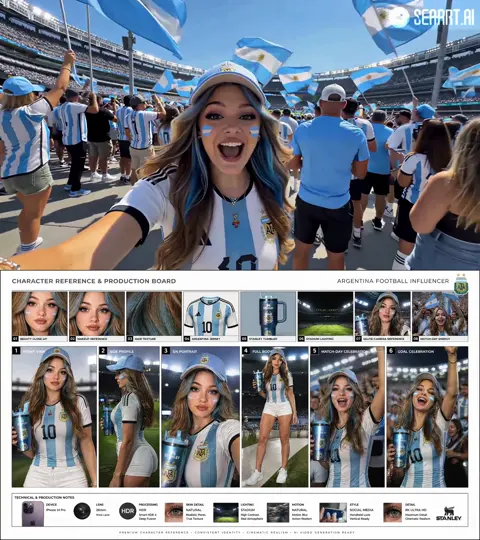
- Character consistency across scenes, so the same person appears with the same outfit, hair, and lighting throughout an episode and across a season
- Style lock, meaning the model does not drift in appearance halfway through a long script
- Export options, including resolution, aspect ratios, and background transparency
- Script handling, especially pronunciation controls for names and technical terms
Where avatar presenters fall short: comedy timing, spontaneous reactions, overlapping dialogue, and any moment where the human warmth of a real face is the point. Use them for structured explanation, not for banter.
Audio repair and dialogue cleanup
The modern cleanup stack usually includes several passes:
- Noise reduction to remove hum, fans, and traffic
- De-reverb to tighten a room that sounds too live
- Leveling so every speaker sits at a similar loudness
- De-essing and plosive repair for harsh consonants
- Breath and filler trimming, ideally reviewed by a human
- Loudness normalization at export
The temptation is to process everything aggressively. Resist it. Over-processed dialogue develops a metallic, underwater quality that is instantly recognizable and much worse than a little room tone. Always keep an untouched master file and process a working copy.
Editing, motion, and b-roll
Text-based editing — where you cut the video by deleting transcribed words — has become the biggest time saver in the category. It reduces a first pass from hours to minutes. Auto-reframing then converts that cut into vertical format by tracking the active speaker, which is how a single 50-minute episode becomes four short clips without a second edit session.
The weakness of AI editing is long-form consistency. Generated b-roll may change a character's clothing between shots, motion effects may fight each other, and a template that looks energetic in a 30-second clip becomes exhausting across a full episode. The fix is a visual bible: one document listing your fonts, colors, transition style, b-roll treatment, and caption rules, applied to every episode without exception.
Captions, translation, and repurposing
Automatic captions are now good enough to publish with light review, provided you check names, jargon, and numbers. For translation, AI dubbing with voice preservation can open a show to new audiences, but it needs disclosure and a native-speaker review of at least the first two minutes, where most errors cluster.
Useful caption deliverables:
- A burned-in version for social clips, where sound is often off
- A sidecar subtitle file for the long-form upload, so viewers can toggle captions
- A clean transcript for a blog post, newsletter, or search indexing
- A translated subtitle track for international distribution
A repeatable episode pipeline, step by step
The difference between a show that lasts three months and one that lasts three years is a pipeline that survives a busy week. Here is one that works for a small team.
Step 1: Lock the rundown. Confirm the guest, the topic, the segment order, and the deliverable list. If a clip is planned, note the likely timestamp range in advance.
Step 2: Record with redundancy. Local audio for every participant, a second camera angle if available, and a backup of everything to two locations before you go to bed.
Step 3: Sync and rough cut. Align tracks with a clap marker, then let transcription do the first structural pass. Move segments, cut tangents, and tighten the cold open so the first 30 seconds contain a reason to stay.
Step 4: Clean the audio. Run noise reduction, de-reverb, and leveling on a copy. Compare against the untreated master with headphones before accepting.
Step 5: Build the visual layer. Add the intro bumper, lower thirds, chapter cards, and any generated b-roll. Keep graphics on screen long enough to read but short enough not to linger.
Step 6: Caption and translate. Generate captions, correct proper nouns, then produce a subtitle file and, if relevant, a dubbed track.
Step 7: Quality control. Run the full checklist below before anything is exported.
Step 8: Export masters. Save a high-bitrate horizontal master, a vertical master, an audio-only file, and all subtitle files in one project folder named with the episode number.
Step 9: Publish and schedule. Upload the long-form episode, publish two to four clips across the week, and release the transcript alongside it.
Step 10: Review the numbers. After a week, compare retention curves with the previous episode. Look for the exact timestamp where viewers leave, and adjust the next rundown accordingly.
Quality control checklist before publishing
- Loudness normalized consistently across the episode and within the acceptable range for your destination platform
- No clipping, no sudden volume jumps between speakers
- Captions synchronized, with names and technical terms corrected
- No flash frames, black gaps, or accidental jump cuts at segment boundaries
- Chapter markers and timestamps added to the description
- Thumbnail legible at small sizes, with contrast and no more than four words
- Title and description accurate, and free of clickbait the episode cannot support
- Aspect ratios correct for every export: horizontal, vertical, and square if needed
- Intro and outro music licensed and at a lower level than dialogue
- Accessibility: captions available, color contrast sufficient, no meaning carried by color alone
Common mistakes that make AI-assisted podcasts feel cheap
The most frequent error is using an avatar or a generated voice for content that needed a human. Audiences forgive imperfect lighting; they do not forgive a host who cannot react.
The second is inconsistent treatment. If one guest gets noise reduction and another does not, the episode sounds stitched together. Apply the same chain to every track, then check the result as a whole rather than track by track.
The third is caption neglect. Auto-captions mispronounce names, mangle acronyms, and drop punctuation. Ten minutes of review prevents a comment section full of corrections.
The fourth is visual overdrive. Zoom punches, whooshes, and animated transitions every few seconds turn a conversation into a highlight reel. Use motion to mark structure, not to fill silence.
The fifth is losing the master. Once aggressive processing has been applied and saved over the original, there is no way back. Always keep a clean, unprocessed archive.
The sixth is ignoring vertical. If you plan to publish short clips, frame your shots with headroom for a vertical crop, and avoid placing important graphics near the edges.
The seventh is forgetting the guest. Send them the clip, the episode link, and a still they can share. Guests are your most reliable distribution channel.
Publishing, distribution, and repurposing strategy
Treat the long-form episode as the anchor asset and everything else as satellites. A typical satellite set from one recording:
- Two to four vertical clips of 30 to 60 seconds, each built around one complete idea
- One quote card or audiogram for text-first platforms
- A newsletter section summarizing the strongest 200 words
- A transcript page that can rank for the topic's search terms
- A follow-up clip answering a question the episode raised but did not fully resolve
When choosing clips, prioritize moments with a clear statement, a disagreement, or a surprising number. Avoid clips that require context from earlier in the conversation. A short clip should be understandable with the sound off.
For distribution, publish the long-form video where your audience already watches, and adapt rather than repost elsewhere. Each platform rewards native formatting: different aspect ratios, different caption styles, different thumbnail conventions. Uploading the same file everywhere produces mediocre results everywhere.
Budget and stack decision criteria
Rather than chasing a fixed tool list, decide based on your constraints. Ask these questions:
- Episode volume: one per month or three per week? High volume favors tools with strong batch processing and templates.
- Guest count: solo shows can lean on avatars; multi-guest interviews need solid audio repair and speaker-aware editing.
- Language reach: if you need translated versions, prioritize tools with reliable dubbing and subtitle export.
- Team skill: if nobody on the team edits video, choose tools with simple timeline-free workflows.
- Consistency needs: if your show has a recognizable look, style-locking and reusable character or template features matter more than novelty effects.
- Privacy and rights: for sensitive interviews, check where files are stored and whether your recordings may be used for model improvement.
- Export flexibility: confirm you own your output and can export at the resolutions you need without watermarks.
A sensible progression for most creators: start with excellent source capture, add speech-based editing, then captioning, then vertical reframing. Add avatar presenters and translation only when you have a specific use case that justifies the extra review time.
FAQ
Can an AI avatar host an entire podcast?
It can host a scripted, structured show — explainers, product updates, news summaries — convincingly. It struggles with unscripted conversation, humor, and emotional reaction. If your format depends on spontaneity, keep the avatar for bumpers and intros instead.
How much editing time do AI tools realistically save?
A first structural pass and captioning can drop from several hours to under an hour on a 45-minute episode. Visual polish, sound review, and clip selection still need human attention. Expect meaningful savings, not a fully automated pipeline.
Do I need an expensive microphone?
No, but you need a quiet room and a decent dynamic or USB condenser microphone placed correctly. Recording quality matters more than model choice, and it is the one thing no cleanup tool can fabricate.
Should I burn captions into the long-form video?
Burn them into short vertical clips, where most viewers watch muted. Keep the long-form version with a toggleable subtitle track so viewers who dislike permanent captions can turn them off.
How do I keep visual consistency across a season?
Write a one-page visual bible and follow it. Define fonts, colors, lower-third design, caption style, intro duration, and b-roll treatment. If you use generated characters, lock the same reference assets for the entire season.
Is AI dubbing safe for guest interviews?
Only with permission. Always tell guests that a translated version may be produced, give them the chance to review it before publication, and label dubbed versions clearly so audiences are not misled.
How do I choose between two similar tools?
Test both with the same five-minute excerpt that includes a hard case: a name, a number, crosstalk, and background noise. Compare output quality, correction effort, export options, and processing time. The faster tool is usually the one with fewer corrections, not fewer clicks.
What is the biggest beginner mistake?
Chasing tools before fixing format. A clear segment structure, a strong opening 30 seconds, and clean audio will outperform an expensive stack applied to a shapeless episode every single time. Get the fundamentals right, then automate the repetitive parts.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.