
AI Video Tools Beyond Avatar Platforms: A Workflow Guide
Oct 15, 2026
Why avatar-first video tools are no longer the default
For several years, the honest answer to "how do I make an AI video?" was a talking-head presenter. You pasted a script into a browser tab, picked an avatar, chose a background, and exported a polished clip in under an hour. That pipeline still works, and for a large class of corporate content it still wins. But it has a ceiling, and most teams hit it faster than they expect.
The ceiling is not visual quality. Modern avatar rendering is genuinely good — lip sync is tight, gestures look natural, and voice cloning is convincing enough for training content. The ceiling is structural. A talking head cannot walk through a location, cannot cut to a reaction shot, cannot hold on an empty room to build tension, and cannot show a product being used from three angles. When your story needs staging, camera language, or environment, the script-to-avatar format has nowhere to go.
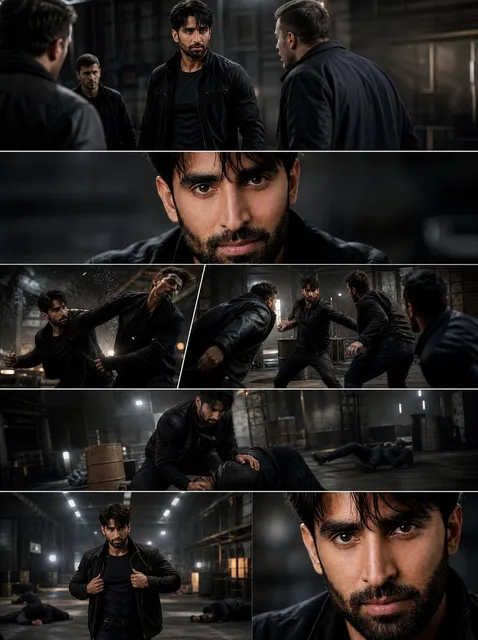
What changed is that a new class of generators learned to produce dynamic footage: multi-shot sequences, camera moves, physical motion, and consistent characters across cuts. Instead of animating a face, these systems synthesize a scene. That reframes the entire production question. You are no longer shopping for the best-looking presenter. You are choosing a pipeline that can carry a narrative from script to shot list to assembled cut.
The practical consequence is that most teams now need two tools, not one: an avatar platform for direct-to-camera explanation, and a scene-based generator for everything that needs staging. The rest of this guide is about picking both well and running them through a single workflow.
The four job types in AI video, and which tool class wins each
Most production requests fall into one of four buckets. Matching the bucket to a tool class before you open any editor saves hours of rework.
| Job type | Best tool class | Typical length | Common failure mode |
|---|---|---|---|
| Spokesperson and explainer | Avatar or script-to-video platform | 60–180 seconds | Robotic pacing, no visual variety |
| Marketing and product b-roll | Image-to-video and scene generators | 5–20 seconds per shot | Warping edges, inconsistent lighting |
| Narrative or short film | Multi-shot pipelines with character references | 2–8 minutes total | Character drift between shots |
| Social vertical | Fast-iteration generators plus caption tools | 15–60 seconds | Over-stylized output that fights the text overlay |
The first row is where avatar tools earn their place. A compliance update, an onboarding walkthrough, or a product tour with a host voice is exactly what script-to-avatar systems were designed for, and trying to generate that content with a cinematic model is a waste of render time.
Rows two and three are where the newer generation of tools separates itself. Image-to-video is the workhorse: you supply a still frame — a photo, a render, a designed key visual — and the model animates it. This gives you far more control than pure text prompting because composition is decided by you, not guessed by the model. Scene generators take the opposite approach and build the whole frame from a description, which is faster but less predictable.
Row four deserves its own caution. Vertical social video has the least tolerance for generation artifacts because viewers see the frame at full size on a phone and the text overlay draws the eye to exactly the areas where models tend to break: hands, mouths, and fine detail near edges.
Choosing a generator: four evaluation axes
Feature lists are useless for comparison because every platform claims the same capabilities. Evaluate instead on four axes that actually predict whether your project finishes.
Photorealism and prompt adherence
Photorealism is easy to judge visually and mostly solved at the top of the market. Prompt adherence is the harder, more useful test. Write a deliberately specific prompt — subject, wardrobe, action, lens, lighting direction, and camera movement — then check how many clauses survive into the output. A model that renders beautiful footage but ignores half your instructions is a model you will fight for every shot.
Run this test with three prompts of increasing specificity. If adherence collapses at the third prompt, that model is fine for mood-driven b-roll and poor for scripted sequences where the frame must match a planned edit.
Character and style consistency
Consistency is where most projects fail. A shot that looks perfect in isolation becomes unusable when the lead's jacket changes color in the next cut. The strongest workflows solve this by anchoring to reference images rather than text descriptions. Upload two or three images of the same character — different angles, same wardrobe — and the model has a visual target to match instead of a verbal one.
The same logic applies to style. If you want a consistent look across twelve shots, define it once as a reference frame and reuse it, rather than re-describing "moody teal and orange lighting" twelve times and hoping the model interprets it identically each time.
Duration, resolution, and reliability
Generation length is usually a trade-off, and short clips that stitch together cleanly beat long clips that drift. Prioritize:
- Resolution over duration — a crisp five-second shot can be slowed, held, or cut around. A mushy ten-second shot cannot be fixed.
- Deterministic re-runs — can you regenerate the same shot with a small prompt tweak and keep the parts that worked?
- Batch behavior — if the same prompt produces wildly different framing each run, planning an edit becomes guesswork.
Budget model and throughput
Cost structures vary: some platforms charge per generation, some per minute of output, some per seat with a monthly render allowance. What matters is throughput, not headline price. Estimate your real production rate — say forty shots per episode with a thirty percent regeneration rate — and calculate what that costs across two or three platforms. A cheaper tool that needs four attempts per usable shot is not cheaper.
A repeatable workflow from script to finished cut
Tools change; the workflow should not. This sequence works across avatar platforms and scene generators alike.
Step 1: Write for the ear, not the page
AI narration exposes writing that looks fine on a page and sounds stiff out loud. Read the script aloud before you generate anything. Cut subordinate clauses, replace passive constructions, and keep sentences under twenty words. If a line feels awkward in your own voice, it will feel worse through a synthetic one.
Step 2: Build a shot bible before generating
The single most effective habit is writing a shot list with locked details. For each shot, record:
- Shot number and duration target
- Subject, wardrobe, and props
- Location and time of day
- Camera framing and movement
- Lighting direction
- Which reference images apply
This document becomes your prompt source and your quality checklist. When shot seven drifts, you compare it against the book instead of arguing from memory.
Step 3: Generate in blocks, not one at a time
Group shots by location and by character appearance. Generating three shots of the same character in the same room back-to-back keeps conditions stable and reduces drift. It also makes review faster: you judge a block as a unit rather than context-switching between unrelated frames.
Expect a regeneration rate between twenty and forty percent. Budget your time accordingly — planning for a third of your shots to be regenerated is normal, not a sign that something is wrong.
Step 4: Assemble with rough cuts first
Do not polish individual shots in isolation. Drop everything into the timeline at approximate length, add temporary narration or music, and watch the sequence end to end. Problems that are invisible in a single clip — pacing that drags, a jump cut that breaks continuity, a cut that lands on a moving hand — become obvious in sequence. Only then go back and fix or regenerate specific shots.
When a presenter-driven tool is still the right answer
It is worth resisting the urge to abandon avatar platforms entirely. They remain the most efficient option when:
- The content is instructional, procedural, or compliance-driven
- You need to update a script frequently without re-shooting anything
- Localization matters more than cinematography, because voice and avatar swapping scales cheaply across languages
- Turnaround is measured in hours, not days
- The brand requires a consistent human face across dozens of videos
A useful hybrid: use an avatar presenter for the segments that explain, and scene-generated footage for the segments that demonstrate. Cut between them in the edit. The presenter carries authority; the generated footage carries evidence. Audiences accept this format easily because it mirrors the interview-plus-b-roll structure of documentary television.
Prompting patterns that hold up in scene generation
Prompt quality drives output quality more than platform choice. Three patterns consistently outperform freeform description.
Anchor, then vary. Establish the scene in your first clause — location, time of day, and light quality — then describe the action. Models weight early tokens heavily, so a scene set in the opening clause tends to remain stable across regenerations.
Name the camera, not just the subject. "Slow dolly in on a wide shot" produces different footage than "close-up of a person." Camera language gives the model a motion plan, which is where most outputs either succeed or turn into drifting mush.
One action per shot. Prompting a character to walk, open a door, and turn to camera in a five-second clip produces three half-finished motions. Split it into three shots. AI generation rewards the same discipline as traditional shooting: one beat per setup.
Also avoid negative-only prompts. Telling a model what not to render is far less effective than describing the frame you actually want.
Post-production: where AI footage becomes watchable
Raw generated footage rarely cuts together cleanly. Three fixes close most of the gap.
Stabilize and reframe. Generated clips frequently have subtle horizontal drift. Applying a mild stabilizer crops the frame slightly and removes the wobble, which also hides edge warp artifacts. If you shot vertical source, reframe to the target aspect ratio before editing so you are not fighting two problems at once.
Grade for consistency. Shot-to-shot color drift is the fastest way to make a sequence feel artificial. Apply one look — a LUT, a color-managed grade, or a shared reference frame — across every clip. Consistency in color does more for perceived realism than any single shot's detail.
Design sound deliberately. Synthetic visuals paired with generic music sound cheap. Layer ambience that matches the location, add dialogue or voiceover early in the edit so pacing is locked to speech, and use a small number of distinct sounds rather than a busy bed. Sound design is the cheapest realism upgrade available.
Quality control checklist before publishing
Run every sequence through the same list:
- Do hands, faces, and text stay coherent in motion?
- Does wardrobe and hair match across consecutive shots of the same character?
- Are lighting direction and color temperature consistent between cuts?
- Does pacing hold when watched with sound off, as most social viewers will see it?
- Is every claim in the narration accurate and current?
- Are there any unintended background objects or garbled on-screen text?
- Does the first three seconds earn a continued watch?
- Is the export resolution and aspect ratio correct for each destination platform?
Mistakes that cost the most time
Generating before planning. Producing twenty pretty clips with no shot list guarantees they will not assemble into a story. The script and shot bible come first, always.
Fixing in the edit what should be regenerated. If a shot's core action is wrong, cut it and rerun. Trying to salvage it with trim and speed changes burns more time than a fresh generation.
Ignoring continuity until the end. Drift is cheaper to catch in blocks of three shots than after twenty are finished.
Over-relying on a single model. Different generators handle different subjects better — one may excel at human motion and struggle with vehicles or architecture. Keeping a second option available for problem shots is faster than forcing one tool to do everything.
Shipping without a human pass. Synthetic media that has never been reviewed by a person is where factual errors and uncanny artifacts reach audiences. A ten-minute review pass over a two-minute video is cheap insurance.
FAQ
Can I make a complete video with only a text prompt?
You can generate individual shots that way, but a complete video still needs a script, a shot order, and an edit. Text-to-video replaces photography, not storytelling.
How long should each generated shot be?
Five to eight seconds is the practical sweet spot. Shorter clips are easier to control and cut around; longer clips drift more and give you less flexibility in the timeline.
What is the fastest way to get consistent characters?
Use reference images rather than repeated text descriptions, generate shots of the same character in batches, and lock wardrobe and lighting details into your shot bible.
Do I still need a presenter tool if I have a scene generator?
For explanation-heavy content, yes. Presenter formats remain the most efficient way to deliver dense information and to localize a single script across multiple languages.
How much footage should I generate for a two-minute video?
Plan on roughly twenty-five to thirty-five usable shots, then add a buffer of forty percent for regeneration. That puts your actual generation count around thirty-five to fifty clips.
Which matters more, model choice or prompt quality?
Prompt quality and workflow discipline matter more for most projects. Once you are working with a modern generator, the difference between platforms is smaller than the difference between a planned shot list and improvised prompting.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.