
Synthesia vs Advanced AI Video Models: A Practical Guide
Oct 13, 2026
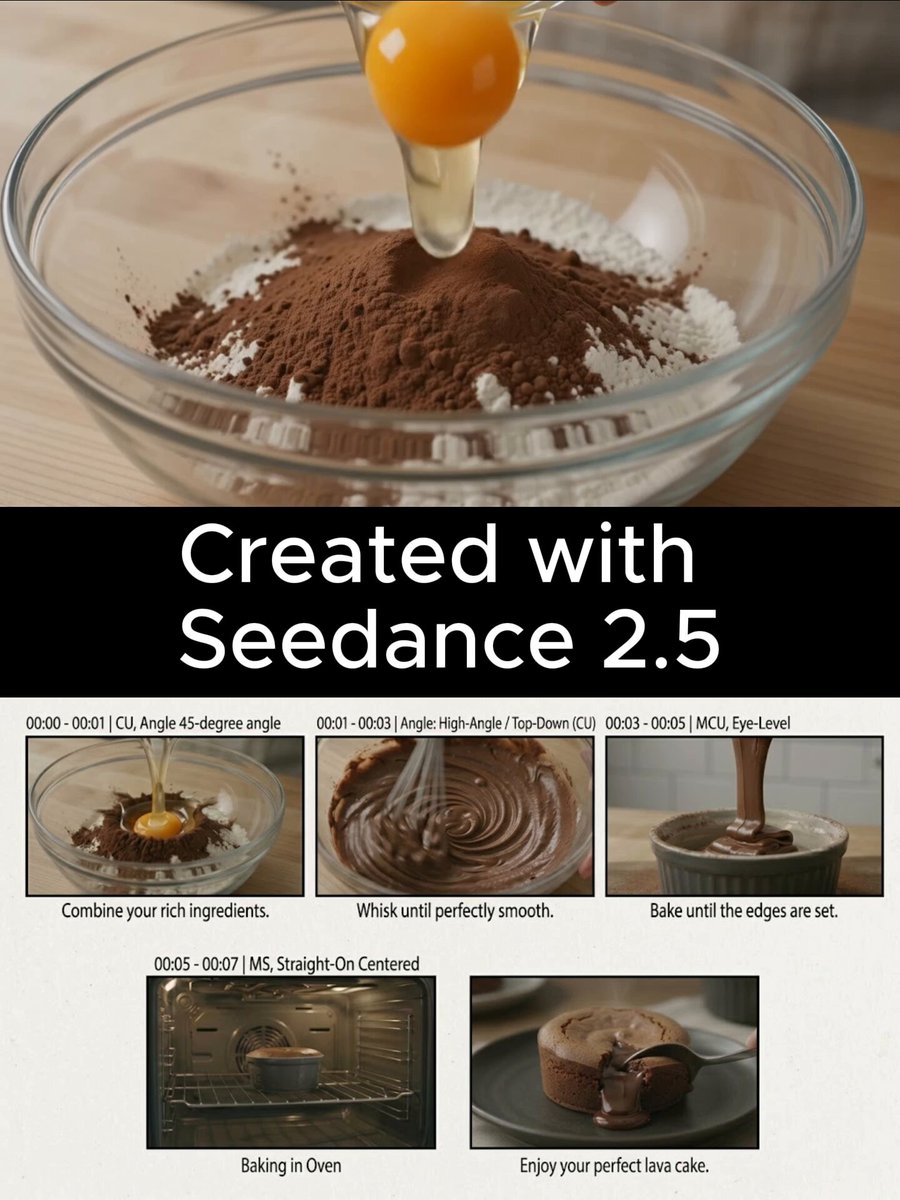
AI video production has split into two practical paths. One path is built around scripted presenters, polished templates, and fast turnaround. The other is built around generative scene creation, where the model invents camera moves, environments, and character action from prompts or references. Tools such as Synthesia sit in the first camp. They excel when you need a reliable spokesperson video, a training module, or a localized product explainer. Advanced generative video models sit in the second camp. They chase cinematic realism, long-form narrative, and directorial control. This guide compares the two approaches from a workflow perspective, not a hype perspective. It explains when an avatar-first tool is the right call, when a scene-generation model is worth the extra effort, and how to combine both without wasting time or budget.
Why the Avatar-Video and Generative-Video Split Matters
Teams rarely choose a video tool in isolation. They choose a production constraint: a deadline, a budget, a compliance requirement, or a distribution channel. Avatar tools reduce risk. You write a script, pick a presenter, and get a consistent result. Generative models increase creative range but also increase variance. You can produce a shot that looks like a feature film, but you may need ten attempts to get there. The split matters because the wrong choice creates hidden costs. An avatar tool used for a cinematic brand film will feel flat. A generative model used for a weekly compliance update will feel irresponsible. The goal is not to declare one category better. The goal is to match the tool to the job, then build a repeatable workflow around that match.
The Core Difference: Scripted Avatars vs. Scene Generation
Avatar-based tools start with a human performance template. The presenter is already captured or synthesized. The mouth shapes, gestures, and eye movements are constrained by the model. Your script drives the performance. This makes the output predictable, but it also limits what the camera can do. You usually get a fixed framing, a set background, and a small number of layout options. That is not a weakness. It is a design choice. Predictability is exactly what you want when the video must be approved by legal, translated into eight languages, and published every Monday.
Advanced generative models start with a scene description. The model builds the world, the lighting, the camera movement, and the character action. The presenter is not a template; the presenter is a generated element inside a generated shot. This allows for dolly moves, dramatic lighting, complex environments, and character interactions. It also means the model can make mistakes that a template would never make. A hand can melt. A background can shift between cuts. A face can change identity from one shot to the next. The workflow must include review loops that catch those errors before they reach an audience.
The practical difference shows up in revision. With an avatar tool, a revision usually means editing the script, changing the voice, or swapping a background. With a generative model, a revision can mean re-rendering an entire shot, adjusting references, or changing the prompt structure. Both are manageable. They just require different planning.
Quality Criteria: What to Evaluate Before You Commit
Before you compare specific products, define the quality bar for your project. A corporate training video and a product launch film have different tolerances for visual imperfection. Use the following criteria to score both avatar tools and generative models.
Lip-Sync and Facial Performance
Avatar tools generally win on lip-sync for standard business scripts. The phoneme mapping is mature, and the mouth shapes stay aligned with the voice track. Problems appear with unusual names, technical jargon, or rapid delivery. You should always review proper nouns and acronyms. Generative models can also produce strong lip-sync, but they often need a close-up shot and a clean audio track. Wide shots hide mouth errors. If your script depends on a tight close-up, test that shot early. If the model struggles, consider using an avatar tool for the presenter segments and a generative model for the b-roll.
Voice, Accent, and Prosody
Voice quality is not just about sounding human. It is about pacing, emphasis, and emotional range. Avatar platforms usually offer a library of voices with adjustable speed and pitch. That is enough for explainers and tutorials. Advanced models often pair with separate voice synthesis tools, which gives you more control but adds a step. The risk is mismatch. If the voice sounds excited and the face looks neutral, the video feels uncanny. Always generate a short test with the exact voice and script before committing to a full production.
Visual Consistency Across Shots
Consistency is the hardest part of generative video. A character can look slightly different in every shot. A jacket can change color. A room can rearrange itself. To manage this, you need reference images, seed control, and a shot list that minimizes complex changes. Avatar tools avoid this problem because the presenter and set are fixed. If your project needs a single presenter across twenty videos, an avatar tool is almost always more efficient. If your project needs a character to move through different environments, generative models offer more creative upside, but you must budget time for continuity checks.
Prompt Adherence and Iteration Speed
Prompt adherence measures how closely the output matches your description. A model that ignores camera direction or character details will slow you down. Avatar tools score high on adherence because the input is a script, not a scene description. Generative models vary widely. Some models follow cinematic language well. Others need very explicit prompts with shot size, lens, lighting, and action. The fastest workflow is not always the one with the fastest render. It is the one with the fewest failed attempts. Track how many generations it takes to get an acceptable shot. That number matters more than raw render time.
Workflow A: Fast Talking-Head Production with Avatar Tools
This workflow is ideal for training, onboarding, product updates, sales outreach, and localized announcements. It prioritizes speed, consistency, and easy revision.
Step 1: Script and Compliance Pass
Write for the ear, not the eye. Short sentences. One idea per sentence. Read the script aloud and mark words that sound awkward. Then run a compliance pass for claims, disclaimers, and brand rules. Because avatar tools generate from text, a clean script is the highest-leverage input you can prepare. If the script is messy, the video will feel messy no matter how good the avatar looks.
Step 2: Choose Presenter and Set
Pick a presenter whose age, wardrobe, and energy match the audience. A financial compliance video needs a different tone than a new-hire welcome video. Choose a background that supports the message without distracting from it. A simple office set works for most business content. A branded set works for external marketing. Keep the framing consistent across a series so viewers recognize the format immediately.
Step 3: Generate, Review, and Fix
Generate a rough cut, then review it in three passes. First, listen without watching. Audio problems are easier to catch when you ignore the visuals. Second, watch without listening. Look for odd gestures, blinking patterns, or mouth errors. Third, watch and listen together. Note the timecodes for every issue. Fix the script or voice settings before you re-render. Do not try to fix a pronunciation problem by changing the avatar.
Step 4: Localization and Accessibility
Avatar tools make localization straightforward because the script is separate from the performance. Translate the script, generate a new voice track, and keep the same presenter. This is a major advantage for global teams. Add captions and a transcript for accessibility. Check that translated text fits the on-screen layout. Some languages expand by thirty percent or more. If you use on-screen text, build in extra room during the design phase.
Workflow B: Cinematic Scene Generation with Advanced Models
This workflow is ideal for brand films, concept trailers, narrative shorts, and any project where atmosphere matters as much as information. It prioritizes visual impact and directorial control.
Step 1: Treatment and Shot List
Start with a one-page treatment. Describe the story, the mood, and the visual references. Then break it into a shot list. Each shot should include the subject, action, camera angle, lens, lighting, and duration. This is the step most teams skip, and it is the step that saves the most time. A generative model cannot guess your intent. A clear shot list turns a vague prompt into a production plan.
Step 2: Character and Style References
Create or collect reference images for every recurring element: faces, wardrobe, props, locations, and color palettes. Use those references consistently in every prompt. If the model supports image prompts, use them. If it supports style references, use them. Write down the exact phrasing that works. A prompt library is more valuable than a single perfect generation. When a shot fails, you want to know which variable to change.
Step 3: Shot-by-Shot Generation and Continuity
Generate one shot at a time. Review each shot for continuity before moving on. Check the character's face, hair, clothing, and position. Check the background for object permanence. Check the lighting direction. If a shot passes, save the prompt and settings. If it fails, change one variable at a time. Changing multiple variables at once makes it impossible to learn what worked. For complex scenes, generate a still frame first, approve it, then animate from that frame.
Step 4: Assembly, Sound, and Polish
Generative video is rarely final on its own. Assemble the shots in an editor. Add sound design, music, and voice-over. Color grade the footage to unify the look. Add transitions that match the pacing. If a shot feels weak, consider replacing it with a graphic, a stock clip, or an avatar segment. The goal is a coherent video, not a showcase of one model. Polishing is where the project becomes professional.
Hybrid Workflow: Combining Avatar and Scene-Based Tools
The strongest workflow for many teams is a hybrid. Use an avatar tool for the presenter and the explanatory core. Use a generative model for the opening hook, the b-roll, and the closing call to action. This gives you the reliability of a scripted presenter and the visual energy of cinematic scenes. The key is to plan the handoffs. Match the color temperature, the audio levels, and the pacing. If the avatar segment looks like a webcam and the generative segment looks like a film, the contrast will feel accidental. Use a consistent grade and a consistent sound bed to tie them together.
A hybrid workflow also helps with risk. If the generative model produces a weak shot, you can replace it with an avatar segment without rebuilding the entire video. If the avatar segment feels too static, you can insert a generative transition. Build your timeline with replaceable blocks. That way, a failure in one block does not sink the whole project.
Performance and Scalability Decision Matrix
Use this matrix to choose the right approach for your next project. It is not a product ranking. It is a decision tool.
- Deadline under 48 hours: Avatar tool. Generative models need iteration time.
- Script changes expected weekly: Avatar tool. Re-rendering a presenter is faster than re-generating a scene.
- Need eight language versions: Avatar tool. Localization is simpler when the presenter is fixed.
- Need a cinematic opening: Generative model. Use it for the hook, then cut to the avatar.
- Need a recurring character across episodes: Generative model with strong reference control, or avatar tool if the character is a presenter.
- Need complex camera moves: Generative model. Avatar tools rarely offer true cinematic camera control.
- Need legal review for every claim: Avatar tool. The script is the single source of truth.
- Need a mood-driven brand film: Generative model. Atmosphere is its strength.
Scalability depends on the number of videos, not just the length of one video. If you produce fifty short videos per month, an avatar tool with templates and batch generation will outperform a high-end generative model. If you produce one flagship film per quarter, the generative model is worth the extra time. Calculate cost per finished minute, but also calculate cost per revision. The tool with the lowest revision cost often wins.
Common Mistakes and How to Avoid Them
Mistake 1: Choosing a tool before defining the audience. A tool cannot fix a vague brief. Write the audience, the message, and the success metric first.
Mistake 2: Over-scripting a generative video. Generative models are bad at dense information. If you need to explain a process, use an avatar or a screen recording. Use generative shots for emotion and atmosphere.
Mistake 3: Ignoring audio. Bad audio ruins good visuals. Record clean voice-over, use licensed music, and mix the levels before you publish.
Mistake 4: Skipping continuity checks. In generative video, continuity errors are common. Check every shot against the previous one. Keep a reference sheet for faces, wardrobe, and props.
Mistake 5: Assuming localization is automatic. Translation is not localization. Check idioms, units, humor, and cultural references. A direct translation can sound strange even if the words are correct.
Mistake 6: Using too many tools. Every additional tool adds a handoff and a potential failure point. Start with one avatar tool and one generative model. Add more only when you hit a clear limit.
Tool-Selection Checklist for Teams
Before you commit to a platform, run this checklist with your team.
- What is the primary output: explainer, training, ad, or film?
- How often will the content be updated?
- How many languages and regions are required?
- Who approves the script and the final cut?
- What is the maximum acceptable production time?
- What is the budget for usage, storage, and post-production?
- Does the tool support the aspect ratios we need?
- Can we export a transcript and captions?
- How does the tool handle brand fonts, colors, and logos?
- What is the fallback if a generated shot fails on deadline?
A tool that scores well on this checklist is more valuable than a tool that wins a feature comparison. The best platform is the one your team can use repeatedly without friction.
FAQ
Do advanced generative models replace avatar tools?
No. They solve different problems. Avatar tools are better for information delivery, localization, and frequent updates. Generative models are better for atmosphere, narrative, and cinematic visuals. Most teams benefit from using both.
How do I estimate production time for a generative video?
Count the shots, then multiply by the average number of attempts per shot. If a shot takes four attempts and each attempt takes two minutes, that is eight minutes per shot before editing. Add time for continuity review, sound, and color. A one-minute film with twelve shots can easily take a full day.
What about cost?
Compare cost per finished minute, but include revision time and post-production. A cheap generation that requires hours of cleanup may cost more than a reliable template. Track your internal labor rate as part of the calculation.
Can I use these workflows for training and marketing?
Yes. Training content usually favors avatar tools because it needs accuracy and easy updates. Marketing content often mixes avatar segments with generative b-roll. The hybrid workflow is especially effective for product launches.
How do I keep brand consistency?
Create a brand kit with fonts, colors, logo placements, and tone of voice. Apply it in editing, not just in the generation tool. Keep a shared prompt library for recurring visual styles. Review every video against the brand kit before publishing.
What about rights and consent?
Use licensed music, fonts, and footage. If you use a real person's likeness or voice, get written consent. If you generate synthetic presenters, check the platform's commercial usage terms. Keep documentation for every asset.
Final Take: Choose the Workflow, Not the Hype
The AI video landscape is moving fast, but the production fundamentals have not changed. You still need a clear audience, a clean script, a shot plan, and a review process. Avatar tools such as Synthesia give you speed and consistency. Advanced generative models give you atmosphere and directorial freedom. The mistake is treating them as competitors in a single race. They are different production paths for different jobs. Start with the job. Choose the path. Build a workflow that lets you swap tools without rebuilding your process. That is how you get reliable output, whether you are publishing weekly training videos or a cinematic brand film. The teams that win are not the ones with the most models. They are the ones with the clearest workflow.

Alexander
More Blogs
Read MoreMontaggio video rapido: transizioni e software per l'AI
Guida pratica al montaggio video rapido con AI: transizioni fluide, software, workflow, coerenza visiva, errori da evitare e FAQ operative.
Building an AI Video Production Workflow From Concept to Cut
A practical guide to planning, generating, editing, and finishing AI-assisted videos with consistent characters, clear shot lists, and reliable review loops.
A Repeatable Post-Production Workflow for Polished AI Video
Build a repeatable AI video post-production pipeline: organize assets, cut story-first, design transitions, refine audio, and review versions calmly.