
AI Art Generation Workflow: From Prompt to Polished Visual
Oct 15, 2026
Why AI Art Generation Became a Real Production Tool
A few years ago, producing a finished-looking illustration meant a long chain of decisions: sketch, block in color, refine, repaint, adjust. The bottleneck was not talent, it was iteration cost. Every new direction required starting over. That is the constraint generative models removed. Today a text prompt returns four plausible variations in seconds, which changes the economics of exploring ideas. When a concept costs thirty seconds instead of three hours, you can test forty directions before committing to one.
That shift shows up everywhere. Storyboard artists use generated frames to pitch sequences. Thumbnail designers produce twenty options for a single video. Game teams explore environment mood before a single asset is modeled. Small brands build campaign visuals without hiring a photographer for every test concept. The output is not always final art, but it is almost always useful intermediate art, and intermediate art is what most production pipelines actually consume.
The important lesson from teams that get consistent results is that the tool matters far less than the workflow around it. A repeatable process, with defined prompts, reference material, and review criteria, produces better work than jumping between whatever generator looks impressive that week.
How Diffusion Image Generation Actually Works
You do not need to read research papers to use these tools well, but a mental model prevents a lot of wasted time. Diffusion models are trained by taking images, adding noise step by step until nothing recognizable remains, then learning to reverse that process. At generation time, the model starts from pure noise and removes it gradually, steered by your text through a text encoder that converts words into a numeric representation of meaning.
Several practical consequences follow from that design.
- Prompt weighting matters. Words that appear early and are reinforced by related terms tend to dominate the composition. Repeating a concept or describing it through multiple angles strengthens it.
- Guidance strength is a dial, not a setting. Low guidance produces softer, more painterly, more surprising images. High guidance obeys your prompt literally but often looks flatter and more synthetic.
- Step count has diminishing returns. Doubling steps rarely doubles quality; after a certain point you are paying time for nothing.
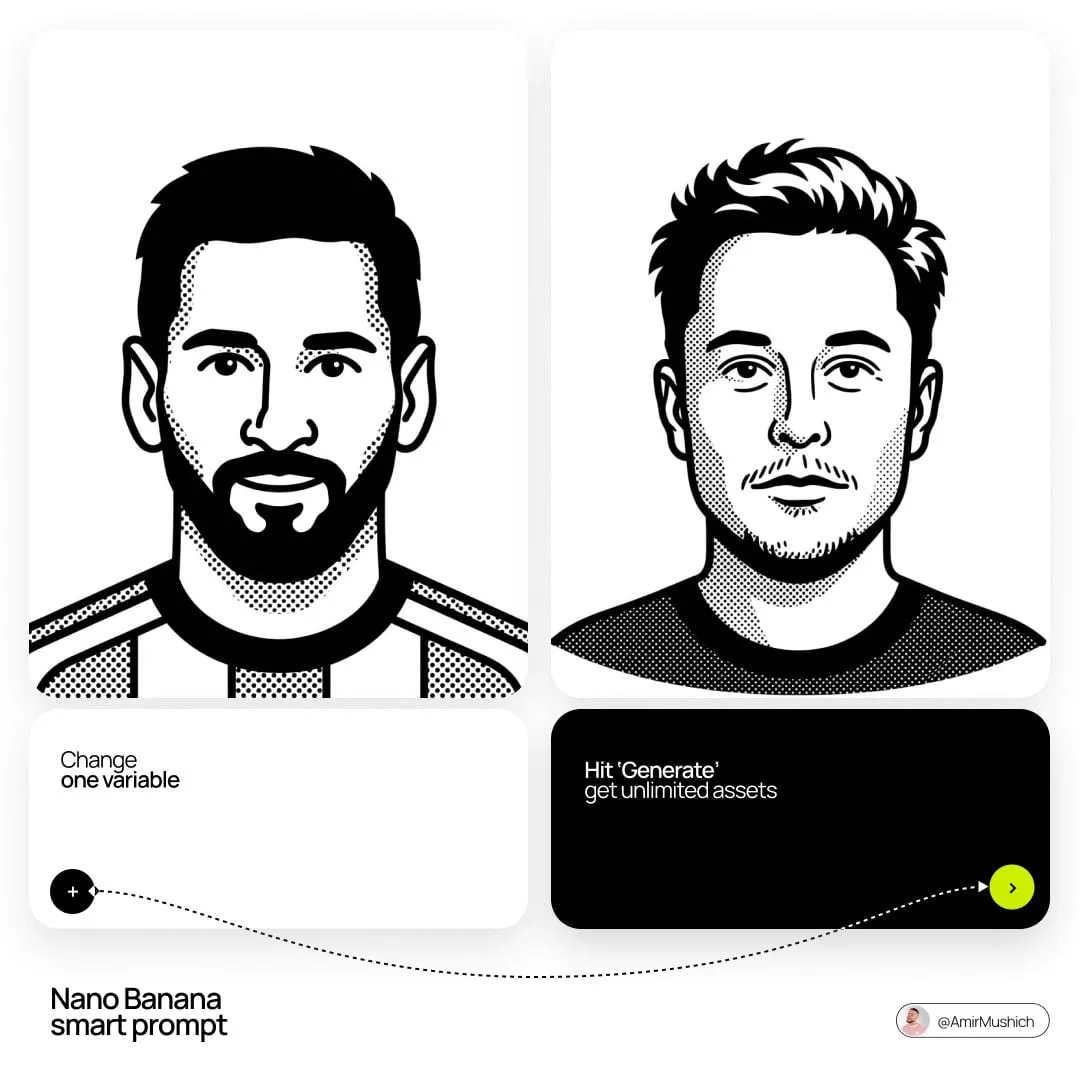
- Seeds create reproducibility. Fixing a seed lets you change one variable and see the effect, which is the only reliable way to learn what your prompt changes are doing.
- Aspect ratio influences composition. A wide frame pushes the model toward landscapes and establishing shots; a tall frame pushes it toward portraits and full-body figures.
Text-to-image in practice
Text-to-image is best for ideation. Feed it a description of subject, action, environment, lighting, and lens character, then generate a spread of four to eight images. Treat the results as sketches, not deliverables. Your job is to spot the one frame that has the right silhouette and mood, then refine from there.
Image-to-image, inpainting, and control layers
Once you have a direction, the workflow changes. Image-to-image lets you feed an existing image back into the model at partial strength, so the composition survives while style and detail shift. Inpainting lets you repair a hand, replace a background, or add an object without regenerating the whole frame. Control layers, such as depth maps, pose skeletons, or edge detection, let you lock structure while the model handles texture and lighting.
This is where quality separates from novelty. Anyone can type a prompt. The people producing usable art are the ones fixing specific regions instead of rerolling the entire canvas and hoping.
Building a Repeatable Prompt System
Random prompting produces random results. A structured prompt produces predictable ones, and predictability is what makes a workflow scalable. A reliable prompt has four slots.
- Subject and identity. Who or what, with distinguishing details: age range, build, clothing, materials, distinguishing features.
- Action and framing. What they are doing, from what distance, from what angle.
- Style and medium. Photographic, painterly, cel-shaded, claymation, archival film, editorial illustration. Reference a medium or a genre, not a living artist's name if you plan to publish.
- Technical treatment. Lens length, depth of field, lighting direction, time of day, color temperature, grain.
A filled-in example might read: a weathered lighthouse keeper in an oilskin coat, waist-up, looking out to sea, overcast dawn, 85mm lens, shallow depth of field, cool desaturated palette, subtle film grain. That prompt gives the model constraints rather than wishes.
Negative prompts and constraints
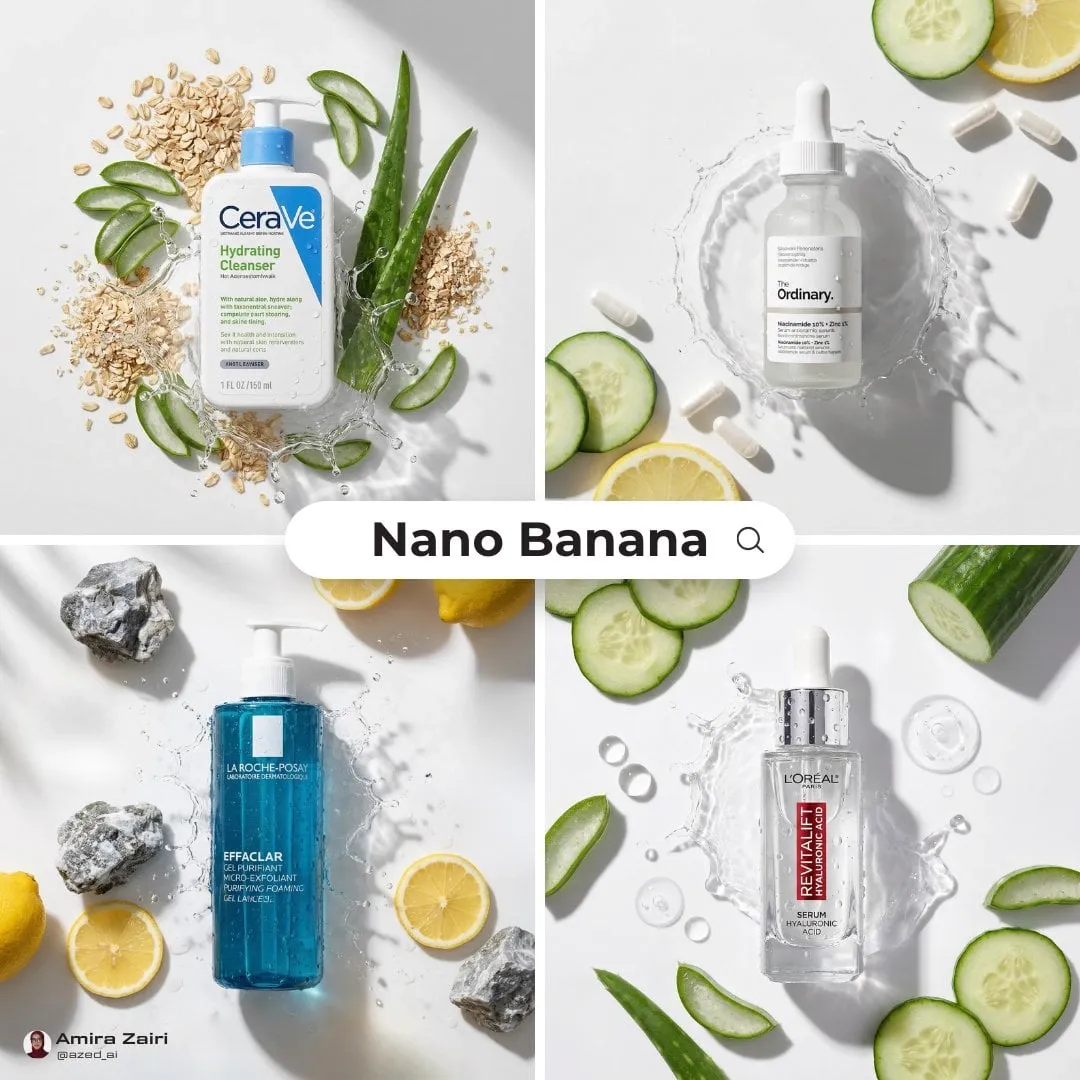
Negative prompts are the second half of the sentence you never wrote. Instead of listing what you want, you exclude what keeps appearing: extra fingers, watermark, blurry background, duplicated limbs, oversaturated colors, plastic skin. Keep negatives short and specific. A long list of exclusions starts fighting itself and can flatten the image.
Test one variable at a time
Keep a simple log: seed, prompt version, model, guidance, and a one-to-five rating for how close the result came to intent. Change one thing per batch. Within an hour of disciplined testing you will know more about your chosen model than weeks of casual prompting would teach you.
Keeping Characters and Scenes Consistent
Consistency is the hardest problem in generative art, and it is the one that decides whether you can tell a story or only make single images. A character that changes face between frames breaks the illusion instantly.
Reference sheets and identity anchors
Build a character sheet before you build scenes. Generate a front view, three-quarter view, profile, and a couple of expressions. Pick the version that reads best, then use that image as a reference input for every subsequent generation. Many tools accept multiple reference images at adjustable influence, letting you weight face, outfit, and palette separately.
Lightweight fine-tuning without overfitting
If you need a character or a visual style across dozens of images, fine-tuning a small adapter on a set of fifteen to forty curated images will outperform prompt tricks. The risk is overfitting: train too long and every output looks the same, with the model losing flexibility in pose and lighting. The fix is to train in short increments, test at each checkpoint on prompts you have never used, and stop when variety starts collapsing.
Scene continuity across a sequence
Environments need the same treatment. Generate a wide establishing shot, then derive closer angles from it using image-to-image or a control layer so architecture, signage, and weather stay identical. Write down the details that matter, such as the direction of the light and the color of the sky, and reuse that phrasing in every prompt for the sequence. Small written constraints beat memory.
Style Control and Multi-Theme Pipelines
Most projects need more than one look: a hero style for key art, a simpler style for diagrams, a grittier one for a dramatic beat. Managing several styles at once is easier when you treat each as a documented preset rather than a vibe you try to recall.
A style preset should record the medium description, the palette, the lighting logic, the level of detail, and the reference images used. When a client asks for a variation, you adjust the preset rather than rebuilding from scratch. Blending two styles is often more effective than describing a hybrid in words: combine a structural reference from one look with a color reference from another and let the influence sliders do the work.
Color discipline is the most underrated part of this. Generative models default toward high saturation and dramatic contrast because it looks impressive in a thumbnail grid. If your project needs restraint, say so explicitly and add desaturation to your negative prompt. A shared color script across a set of images will do more for perceived professionalism than any single prompt upgrade.
From Stills to Motion
Once stills are reliable, motion becomes the natural next step, and it is now accessible without a 3D pipeline. Image-to-video tools take a generated still and extend it into a few seconds of movement.
Image-to-video basics
Start with the cleanest frame you have. Low-resolution or noisy inputs produce smeared motion. Describe the movement, not the scene: the model already sees the scene through your image. A prompt like slow push in, hair moving in the wind, distant birds crossing frame works better than a full re-description of the environment.
Motion prompts and camera language
Borrow the vocabulary of a camera crew. Push in, pull out, pan left, tilt up, handheld drift, dolly alongside, orbit around subject. Short clips respond best to one dominant motion. Asking for three simultaneous movements usually produces mush.
Sound, pacing, and editing
Motion clips rarely work alone. Cut them to a beat, add ambient sound or a music bed, and keep individual shots short. Three seconds of well-executed movement reads better than twelve seconds of drifting. When a shot fails, the cause is usually the input frame rather than the motion prompt, so fix the still and regenerate.
Pre-Visualization, Games, and Social Formats
Storyboards and animatics
For film and advertising, generate a full board from a script breakdown, one frame per beat, then assemble them into an animatic with rough timing and scratch audio. This surfaces structural problems in a sequence before anyone commits budget to shooting.
Concept art and asset exploration
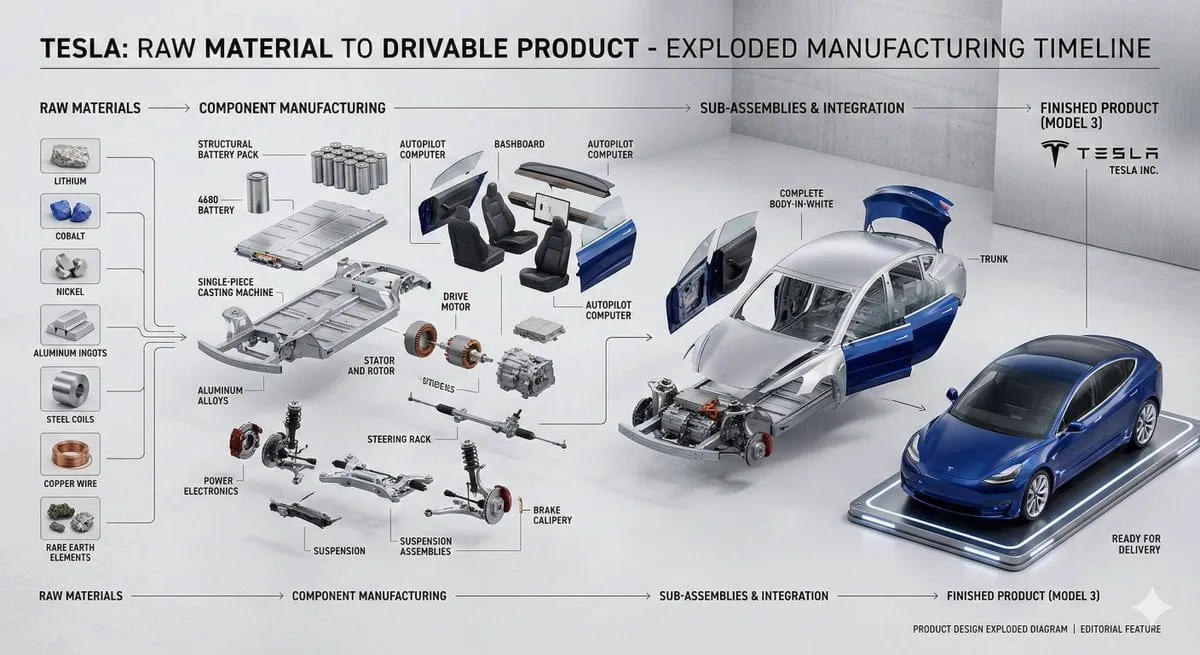
Game and product teams use generation to widen the search space early: thirty environment moods, twenty prop variations, a dozen interface directions. The goal is not finished art but a shared vocabulary, so the team can point at a frame and say "that one, but colder."
Vertical, social-first formats
Vertical video rewards different composition rules. Generate tall frames with the subject centered and headroom preserved for captions. Keep text out of generated images entirely, since lettering is still unreliable; add type in a layout tool afterward where you control legibility.
Quality Control: Common Mistakes and Fixes
Anatomy and hands. Fix with inpainting at high zoom rather than regenerating the frame. Generate the hand region separately at a tighter crop, then composite.
Over-stylization. When every image looks like the same poster, reduce style influence and add variation to framing and lighting across the set.
Mushy backgrounds. Detail density competes for the model's attention. Describe the background in two or three specific terms rather than leaving it open.
Resolution and upscaling. Generate at the size you need, then upscale in a dedicated pass. Upscaling noisy output magnifies the noise.
Text in images. Assume lettering will be wrong and plan to set type manually. It is faster than fighting the model.
Inconsistency. Almost always a reference problem, not a prompt problem. Add reference images before rewriting anything.
Rights and disclosure. Track which tools generated which assets, keep your reference inputs documented, and be honest with clients and audiences about generative elements. When a reference is a real person or a recognizable brand, get permission or change the reference.
Choosing a Tool: Decision Criteria
Rather than chasing the newest model, evaluate against your actual needs.
- Control surface. Do you get inpainting, control layers, and regional editing, or only whole-image generation?
- Consistency features. Can you supply multiple references and adjust their influence?
- Resolution and aspect ratios. Does it output the sizes your delivery format needs without constant upscaling?
- Throughput. How many generations can you run in an hour before hitting usage limits?
- Motion capability. If stills will become clips, staying inside one ecosystem saves pipeline friction.
- Collaboration and export. Can teammates review, comment, and export layered or clean files?
- Privacy and licensing terms. Commercial use, training data, and retention policies differ significantly between providers.
- Cost model fit. Compare subscription tiers against your actual monthly volume rather than guessing at peak usage.
Pick two tools: one strong generator for ideation and one controllable pipeline for refinement. Master both instead of sampling ten.
A Practical End-to-End Workflow
Here is a sequence that works for most projects, from a one-off illustration to a full campaign.
- Write a creative brief. One paragraph: subject, mood, audience, delivery format, constraints.
- Generate a wide spread. Twenty to forty low-commitment images across several prompt variants.
- Shortlist ruthlessly. Keep four to six frames with the right composition and mood.
- Extract a style preset. Document the phrasing and references behind the strongest frame.
- Build references. Create character sheets and environment plates for anything that repeats.
- Refine with inpainting and control layers. Fix regions, do not reroll the whole frame.
- Upscale and grade. One upscale pass, then a consistent color treatment across the set.
- Composite type and layout. Add text, logos, and captions in a design tool.
- Animate selected shots. Convert the strongest frames into short motion clips.
- Log and archive. Save prompts, seeds, references, and settings alongside final files so the look is reproducible.
Step ten is the one most people skip and the one that saves the most time later. A project whose settings are documented can be extended next quarter without guesswork.
FAQ
How many prompts should I test before judging a model?
At least fifty generations across ten prompt families. Judging from ten images tells you about novelty, not capability.
Do I need fine-tuning to get consistent characters?
Not for a handful of images. Reference inputs and inpainting are enough for short sequences. Fine-tuning pays off past roughly thirty to fifty frames of the same character.
Why do my images look shiny and artificial?
Usually high guidance plus default saturation. Lower guidance, add desaturation and plastic-skin terms to negatives, and specify the light source and direction.
Can generated stills become video without a 3D pipeline?
Yes. Image-to-video tools extend a still into a few seconds of motion. Clean input frames and a single dominant camera move give the best results.
How do I keep a whole set of images visually unified?
Freeze the style preset, reuse the same references, and apply one color treatment at the end. Consistency comes from constraint, not from talent.
What should I avoid generating?
Recognizable people without consent, protected characters and logos in published work, and anything you would be uncomfortable disclosing to the audience you are trying to reach.
Where to Take This Next
The gap between people who get striking results and people who get forgettable ones is not access to better models. It is process: a documented prompt structure, real reference material, disciplined regional editing, and a habit of logging what worked. Start with one project and one style. Build a preset, generate a character sheet, produce five refined frames, and animate the best one. That single loop teaches more than another month of casual prompting, and everything you learn becomes reusable the next time a brief lands on your desk.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.