
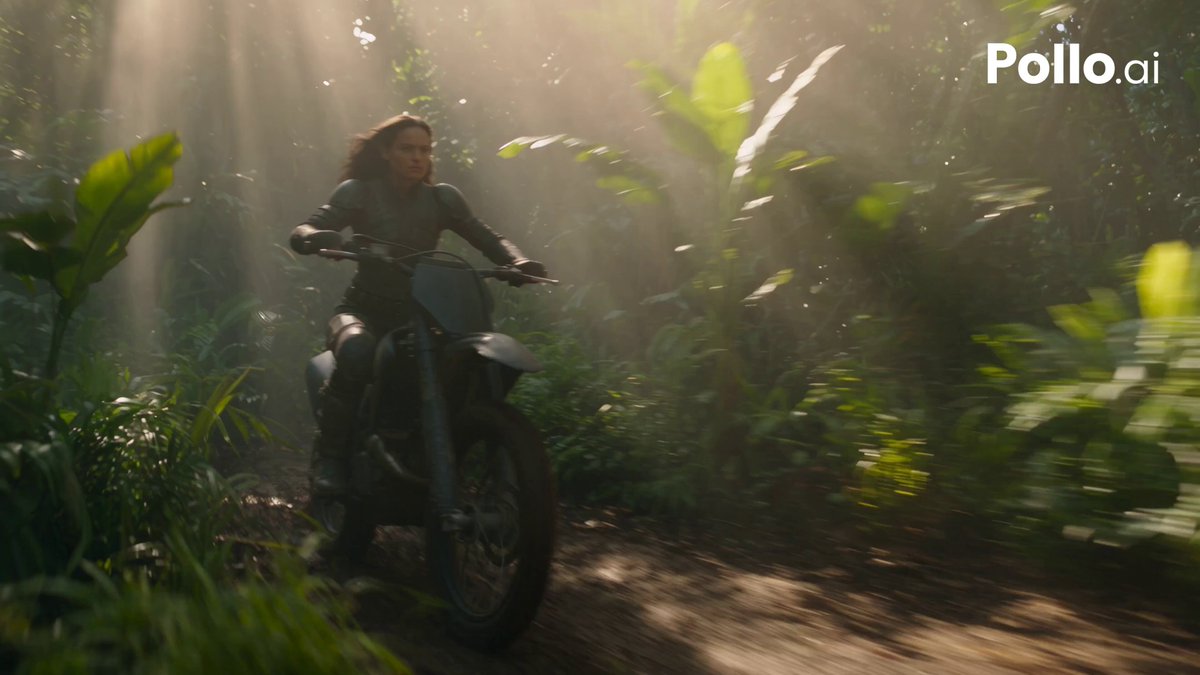
Photorealistic video used to require a camera, a crew, a location permit, and a colourist. Today, a single well-constructed still frame can be animated into a shot that holds up on a large screen. The craft has shifted: instead of operating a camera, you describe one with enough precision that a generative model can reconstruct the physics of light, skin, fabric, and atmosphere on its own.
That shift sounds simpler than it is. Anyone can type a sentence and get a moving image. Getting a moving image that reads as real — that survives a second look, a pause, a close-up — takes a repeatable process. This guide covers that process end to end: the anatomy of a believable image prompt, the motion language that keeps a frame from dissolving, continuity practices that hold a sequence together, and the review checks that catch failures before an audience does.
Why Image-to-Video Is the Fastest Route to Photorealism
Text-to-video is seductive because it feels like directing. You describe a scene, the model invents it, and sometimes the result is beautiful. The problem is control. Every generation reinterprets the subject, the wardrobe, the lighting direction, and the framing. Getting two shots that look like they belong to the same film is an exercise in luck.
Image-to-video flips the order. You first produce a still frame you are genuinely happy with — the right face, the right light, the right lens character — and then you animate it. Because the model is anchored to an existing frame, it has far less room to drift. Faces stay recognisable. Wardrobes stay consistent. The colour of the late-afternoon sun stays on the same side of the subject.
The trade-off is that you now own the hardest part: producing a still that looks real. But still-image generation is a mature discipline. You can iterate on a frame dozens of times for almost no cost, compare options side by side, and only commit to motion once the frame is right. That is a much better place to spend your attention than re-rolling a video and hoping.
There is a second, less obvious benefit. Stills are easy to critique. A director, a client, or a colleague can look at a frame and say "the light is wrong" or "she would not wear that." Motion adds noise to that feedback. Locking the frame first turns vague creative arguments into concrete decisions you can act on.
Anatomy of a Photorealistic Image Prompt
Photorealistic prompts are not longer for the sake of being longer. They are longer because a real photograph is the product of many simultaneous decisions: who is in frame, what they are wearing, what lens was used, where the light comes from, what time of day it is, and what the camera is doing. Each of those decisions is a lever. A prompt that omits them hands the lever to the model.
The most reliable structure is layered rather than conversational. Build the frame in this order: subject, surface detail, lens and sensor, light, atmosphere, composition. Then read it back and ask whether a photographer could actually set up that shot.
Subject and surface detail
Name the subject precisely and add the details that make skin read as skin. Age range, build, hair texture, whether the skin is matte or dewy, whether there is stubble, freckles, or a faint sheen of sweat. Vague descriptors like "beautiful woman" push the model toward plastic smoothness, because the average of a thousand stock photographs is smooth.
Specificity beats flattery. "A 34-year-old field biologist with wind-chapped cheeks, short dark hair pushed behind one ear, a faded olive canvas jacket" gives the model something to render. "A stunning professional" gives it a template. The same rule applies to clothing: name the fabric and its condition. Wool, linen, worn leather, a cotton shirt with a creased collar all behave differently under light.
Lens, sensor, and film language
Lens language is the single most underused tool in image prompting. "85mm portrait lens at f/1.8" tells the model to compress the background and blur it. "24mm wide angle" tells it to stretch the edges and exaggerate depth. "Shot on 35mm film with visible grain" pushes toward a filmic texture instead of a digital sheen.
You can layer sensor and processing language too: shallow depth of field, subtle chromatic aberration, slight lens flare, natural vignetting. These imperfections are what separate a render from a photograph. Cleanliness is the enemy of realism — real cameras have flaws, and audiences read those flaws as authenticity.
Light and atmosphere
Light is where most photorealistic prompts are too lazy. "Soft glowing key light" is a start, but it says nothing about direction, colour, or origin. Specify the source and its behaviour: a single window at camera left, overcast daylight diffused through frosted glass, a practical tungsten lamp just out of frame, the last twenty minutes of golden hour raking across the subject from behind.
Atmosphere does the rest of the work. Haze, dust motes, light rain, cigarette smoke, and humidity all give the light something to travel through, which produces volumetric depth. A subject lit by a bare source in perfectly clear air looks like a 3D render. The same subject lit through a little haze looks like a photograph.
Composition and framing
Finally, describe where the camera is and how the frame is divided. "Medium close-up, subject slightly off-centre to the right, negative space on the left, eye level, slight handheld tilt" is a complete compositional instruction. Mentioning the aspect ratio and whether the frame is level or deliberately canted removes yet another decision from the model's hands.
Motion Prompt Design: From Still Frame to Living Shot
Once the still is locked, motion prompting becomes the second discipline. The mistake here is describing a scene rather than a camera. A model that does not know what the camera is doing will invent movement — usually a slow drift toward the subject's face, which quickly reads as artificial.
Camera move vocabulary
Learn a small, precise vocabulary and reuse it. Dolly in, dolly out, truck left, truck right, pedestal up, crane down, pan, tilt, arc, orbit, push in, pull back, steadicam follow, locked-off tripod. Add a speed qualifier: slow, deliberate, almost imperceptible. Add a stability qualifier: gimbal-smooth, handheld with slight sway, tripod-locked with no movement at all.
A locked-off shot is a powerful choice and an underused one. If a subject is doing something interesting, a still camera lets the audience watch it. Constant movement is a nervous habit, not a style.
Subject motion and micro-motion
Realism lives in small movements: a blink, a swallow, the rise and fall of a chest, fabric shifting, hair moving in a light breeze, fingers tightening slightly on a strap. Large actions — running, fighting, dancing — are where generative models still struggle most, because they have to maintain anatomy under extreme deformation.
A practical rule: keep subject motion modest and let the camera carry the drama. A character turning their head slowly while the camera arcs around them will look more convincing than the same character sprinting through a crowd. If you need a big action, cut it into shorter beats and generate each beat separately.
Duration, pacing, and loop points
Short generations are more reliable than long ones. Four to six seconds is often enough to establish a beat, and it is far easier to keep consistent. If you need a longer shot, generate overlapping segments and cut between them, or extend a segment and hide the seam inside a camera move or a moment of motion blur.
Think in beats rather than seconds. One shot, one idea: she looks up. He steps forward. The door opens. Sequences built from clear beats cut together better and are easier to repair when one generation fails.
Consistency Across Shots: Faces, Wardrobes, and Locations
A sequence falls apart the moment a face changes between cuts. Solving this is mostly a matter of discipline rather than model choice. Start by establishing a canonical reference frame for each character — one image you consider the definitive version — and reuse it as the anchor for every subsequent shot rather than generating a fresh interpretation each time.
Keep a written character sheet with the exact descriptive phrases you used and copy them verbatim. Small variations in wording produce visible variations in faces. Treat the character description as a locked asset, not a creative field you improvise in.
Wardrobe deserves the same treatment. Note colours, materials, and wear. If a character starts a scene in a damp coat, she should still be damp three shots later — unless the story accounts for it. Continuity errors that would be obvious on a film set are just as obvious in generated footage, and audiences are quick to notice a jacket that changes shade between cuts.
Locations need anchoring too. Generate a wide establishing shot and reuse its palette, architecture, and light direction in the closer shots. If a room has windows on the left, they should stay on the left. Some workflows also benefit from generating a simple background plate once and compositing over it, which removes an entire class of drift.
Lighting, Colour, and Mood Continuity
Lighting continuity is the difference between a sequence and a collection of clips. Decide the direction of your key light, its colour temperature, and its contrast ratio, then keep those constants across every shot in a scene. Write them into every prompt.
Colour grading should be planned early, not applied as a rescue at the end. Pick a palette and a general look — warm highlights with teal shadows, desaturated mid-tones, high-contrast night exteriors — and let the prompts move toward it. Then finish the grade in a real editor with consistent scopes, not by eye across isolated clips.
Mood continuity is subtler. A scene that starts tense and ends warm should shift gradually. If each shot is generated in isolation with wildly different emotional descriptors, the result feels like a mood board rather than a scene. Track the emotional arc across your shot list and adjust wording incrementally.
Audio and Ambience: The Half of Realism Nobody Plans For
Visual realism collapses instantly when the audio is wrong. A photorealistic street scene with no ambience feels like a render. Add distant traffic, a footstep that lands on the right surface, a subtle room tone, and the same shot suddenly reads as footage.
Build ambience in layers. Start with a continuous bed — room tone, wind, traffic, rain. Add synchronised foley for anything the audience sees touching something: footsteps, fabric, a cup set on a table. Then add the sparse specific sounds that draw attention: a single bird, a phone buzzing in another room, a door latch.
Dialogue needs special care. If a character speaks on camera, ensure the voice matches the visible subject's age, build, and accent, and that the delivery matches the framing. A close-up demands more nuance than a wide shot. Where lip-sync is involved, generate the motion to match a pre-produced audio track rather than the other way around — this is far more reliable than trying to bend audio to fit generated lips.
A Step-by-Step Workflow From Reference Board to Final Render
The repeating failure in AI video production is trying to solve creativity and technical execution at once. Separate them into stages. Each stage has a clear output, and nothing moves forward until that output is approved.
Step 1: Build a reference board and shot list
Collect real photographs that match the intended look, not just generated images. Real photos tell you what the light actually does. Then write the shot list as a table: shot number, description, camera move, duration, characters present, location, and mood. This document is your contract with yourself.
Step 2: Generate and lock keyframes
Produce still frames for every shot before animating anything. Iterate on them with layered prompts, compare candidates side by side, and get feedback while changes are cheap. Only lock a frame when you would be happy to display it as a photograph.
Step 3: Animate in short beats
Animate each locked frame with a compact motion prompt: one camera instruction, one subject instruction, one stability qualifier, one duration. Generate several variations and keep a note of what you changed. Short beats are easier to regenerate and easier to assemble.
Step 4: Assemble and stabilise
Bring everything into an editor and cut to a scratch track. Look for jumps in exposure, colour, or framing. Stabilise only where needed — over-stabilising removes the handheld character that makes footage feel human. Where a face warps for three frames, cutting a fraction earlier is often better than regenerating the whole shot.
Step 5: Grade, mix, and deliver
Apply a consistent grade across the sequence, checking against scopes rather than your memory of the previous clip. Balance your audio layers so ambience sits well below dialogue. Then export at your target resolution and watch the whole thing on a phone as well as a large screen; small screens reveal composition problems, large screens reveal texture problems.
Choosing the Right Engine for Each Shot
Different engines excel at different things. Some are best at cinematic camera moves, others at human faces, others at stylised motion or long continuous takes. Rather than committing to one tool, match the engine to the shot and accept a slightly more fragmented workflow in exchange for much better results.
Use these criteria when deciding:
- Face fidelity — does the model preserve identity across a head turn?
- Motion coherence — how well does it handle hands, fabric, and fast action?
- Camera control — does it accept explicit move instructions, or infer them?
- Duration — can it produce a usable four to six seconds, or only two?
- Style adherence — does it respect an attached reference frame or drift toward its own look?
- Iteration speed — how fast can you test an idea and discard it?
- Output quality — is the native resolution enough for your delivery, or will you rely on upscaling?
Run a small standardised test before committing to a project: the same keyframe, the same motion prompt, the same duration, in three or four engines. Compare them side by side at full size. The differences become obvious within an hour and will save days later.
Common Mistakes That Break the Illusion
Most realism failures come from a short list of recurring errors. Catching them early is cheaper than fixing them in post.
- Overloading the prompt with adjectives. Style words fight each other. Pick a look and describe it clearly instead of stacking eight moods.
- Forgetting the camera. If the prompt does not specify a move, the model invents one — usually a generic drift.
- Chasing big action. Running, fighting, and crowds are the hardest things to render. Stage them as cut beats.
- Regenerating instead of adjusting. When one detail is wrong, change one line of the prompt and re-run. Wholesale rewrites lose the parts that were working.
- Ignoring audio. Silent photorealistic footage reads as a technical demo, not a film.
- Grading clip by clip. Inconsistent grades are visible immediately. Grade the sequence with scopes.
- Skipping the reference board. Without real photographic references, you end up imitating other AI output, which inherits its tells.
Quality Control and FAQ
Even with a solid workflow, you need a deliberate review pass. Run the sequence at full speed once without stopping — this is how an audience will see it. Then watch it frame by frame through the shots most likely to fail: close-ups, hands, fast motion, and any moment where the camera changes direction.
Pre-delivery checklist
- Faces remain identifiable across every cut
- Wardrobe, hair, and props are continuous
- Light direction and colour temperature are stable
- Camera moves are purposeful, not drifting
- Audio ambience is present under every shot
- No warping frames survive into the final cut
- Grade is consistent when clips are compared side by side
- Output is checked on both a phone and a large screen
Frequently asked questions
How many image prompts does a realistic short sequence need? Usually one locked keyframe per shot, plus a few alternates per shot for safety and variant testing. Ten shots might mean thirty to forty generated frames, of which ten are final.
Can I get photorealism without a reference image? It is possible but unreliable. Starting from a real photograph — even an approximate one — anchors lens behaviour, skin texture, and light direction in a way text alone rarely does.
Why do my generated faces look slightly uncanny? Almost always because the prompt is too generic and the lighting is too even. Add texture detail, specify a light direction, and introduce a small imperfection such as grain or a subtle lens flare.
How long should each generated shot be? Four to six seconds is the sweet spot for reliability. Longer shots can be assembled from overlapping segments with cuts hidden inside motion.
Should I upscale before or after editing? Animate and cut first, then upscale the final conform. Upscaling early multiplies render time and storage without improving creative decisions.
Is a locked-off camera boring? No — it is a legitimate cinematic choice. If the subject is doing something worth watching, a still camera forces the audience to watch it. Movement should be motivated, not decorative.
The through-line in all of this is patience at the frame level. Photorealism is not produced by a single clever prompt; it is produced by locking decisions one at a time — subject, lens, light, composition, motion, sound — until nothing is left for the model to guess. Do that consistently, and the result stops looking like generated footage and starts looking like something you shot.
