
Why Stills Are the Strongest Starting Point for AI Video
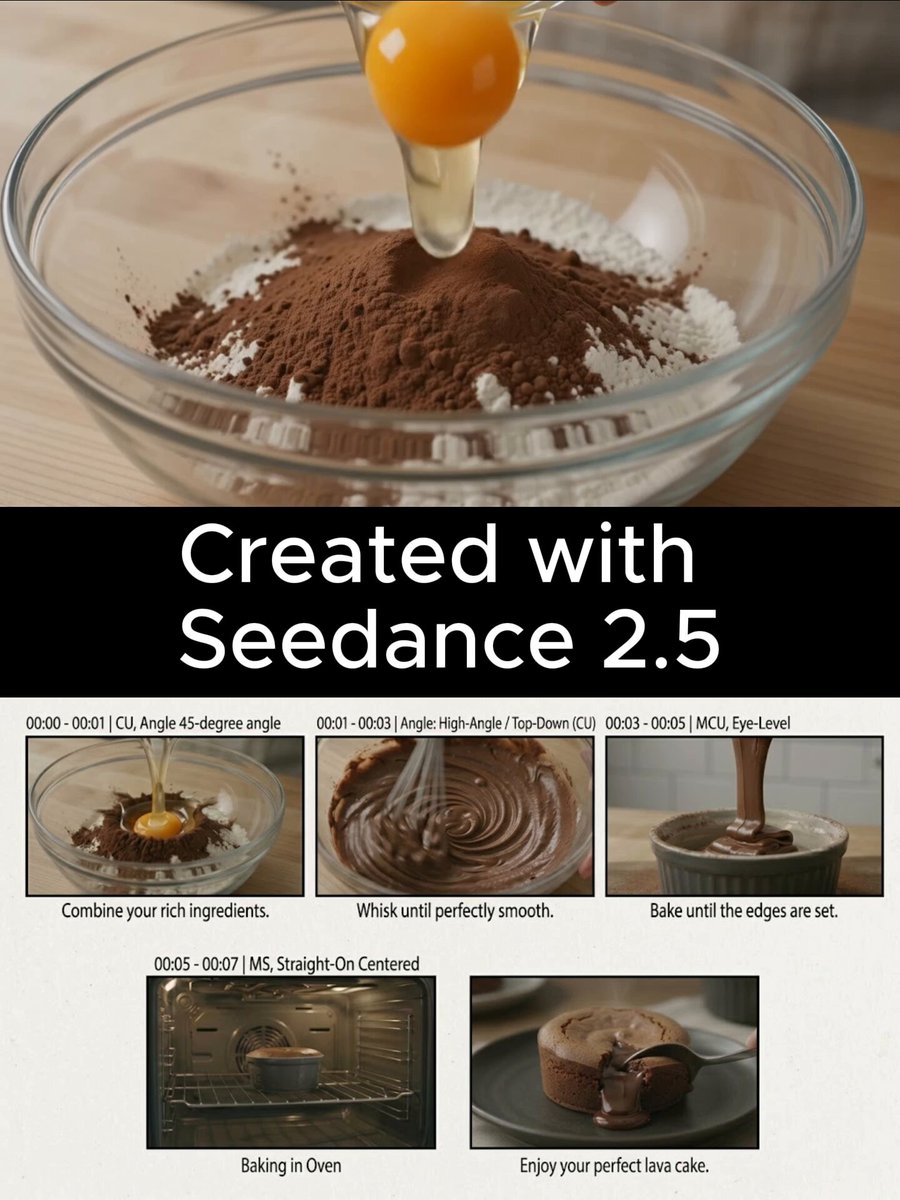
Generating a clip from text alone asks a model to invent composition, wardrobe, lighting, lens choice, and facial geometry all at once. Generating a clip from a still image asks it to do one thing: add believable motion to something that already looks right. That difference is enormous, and it is the reason image-to-video has become the default production path for short-form creators, indie filmmakers, and marketing teams.
A still frame is also a contract. Once you approve the look of the first frame, you have locked the art direction. Every later decision, from camera move to pacing, is a variation on an approved idea rather than a fresh gamble. This makes iteration cheap and review fast: two stakeholders looking at the same frame are arguing about motion, not about aesthetics.
Finally, stills are everywhere. Product photography, portrait sessions, storyboards, 3D renders, illustrations, archival scans. Image-to-video lets you monetize and repurpose libraries that already exist instead of commissioning new shoots.
How Image-to-Video Actually Works
It helps to understand the machine at a conceptual level before you fight it with prompts.
Temporal layers and latent motion
The model receives your still, encodes it into a compressed representation, and then predicts a sequence of latent frames that continue that representation forward in time. A temporal layer keeps those frames related to each other so the scene does not dissolve into noise. Your prompt biases which continuations are likely, and your motion settings bias how far the frames are allowed to travel from the original.
What the model infers and what you must specify
Models infer a lot: how cloth falls, how hair moves in wind, how shadows shift when a light source changes, how water ripples. They are much worse at guessing intent. If you want a slow push-in on a face rather than a walk across a room, you must say so. If you want the subject to stay still while only the background moves, that is an explicit instruction, not a default.
The practical takeaway: describe motion, not appearance. The image already handles appearance. Redundant appearance prompts waste attention and often cause the model to reinterpret the look you carefully built.
Preparing Source Images That Survive Motion
Most disappointing clips are traceable to the input image, not the prompt. Prepare properly and everything downstream gets easier.
Resolution and aspect ratio
Feed the model the highest quality version you have, ideally at or above the resolution you want for the output. Upscale before you animate, not after. Match the aspect ratio to the destination: vertical for social feeds, wide for cinematic framing, square for certain ads. Cropping later destroys the motion you paid for in time and compute.
Framing and headroom
Leave room for motion. If a subject's head touches the top edge of the frame, a camera tilt has nowhere to go. If a hand is cut off, a gesture will look trapped. Give yourself margin on all four sides and keep the main subject roughly on a rule-of-thirds intersection so pan and push techniques remain available.
Lighting, edges, and background separation
Clean, directional lighting with a clear subject-background separation animates best. Flat, dim images with tangled edges produce mushy motion and shimmering artifacts. If the background is busy, consider a mild blur before animating so the model is not tempted to invent movement in every leaf and brick.
Source-image mistakes to avoid
- Heavy JPEG compression that creates blocky texture the model reads as motion.
- Watermarks, logos, and UI overlays, which models love to wobble.
- Multiple subjects at different depths with no separation, which invites limb swapping.
- Extreme close-ups of hands, teeth, or eyes on the first attempt. Start wider.
- Photographs of screens or printed material, which introduce moire patterns.
Writing Motion Prompts That Do What You Mean
The four-part prompt structure
A reliable motion prompt answers four questions in order: who or what moves, how they move, how the camera moves, and what the atmosphere does. For example: a woman turns her head slightly toward camera, a slow dolly-in follows her, warm afternoon light flickers through blinds, subtle fabric movement. Each clause maps to a distinct behavior the model can act on.
Keep prompts short. Three to five clauses is usually the sweet spot. Long descriptive prose dilutes the action words and increases the chance of an unwanted cut or scene change.
Stability phrases and negative motion
When output ripples, shakes, or drifts, add explicit calm: steady camera, consistent lighting, no scene change. Most tools support a negative prompt field, where you can suppress terms like morphing, warping, extra fingers, flicker, blur, jump cut, and text artifacts. Build a reusable negative list once and paste it into every project.
One motion per clip
Resist stacking a zoom, a pan, and a subject walk in a single generation. Models handle one dominant motion far better than three competing ones. If your shot needs a complex move, split it into two clips and join them in the edit.
Camera Control: Presets, Manual Moves, and Motion Strength
Matching camera language to emotion
A slow push-in creates intimacy and tension. A pull-back reveals context and ends a scene. A lateral tracking shot conveys journey and scale. A static tripod shot with a moving subject feels documentary and honest. Choose the move based on what the beat needs, then write it plainly: slow push-in, gentle pan left, handheld follow, static camera.
Dialing in motion strength
Most tools expose a motion intensity, guidance, or strength value. Low values preserve the source frame and produce subtle, premium-looking movement. High values produce dramatic action but risk distortion, face drift, and limb artifacts. A practical habit: render the same frame at low, medium, and high intensity, then pick. Keep a personal log of which intensity suits which shot type, because the answer varies by model and by subject.
Seed and duration discipline
Locking the seed keeps a look reproducible while you tune other settings. Short durations of three to six seconds are easier to control and cheap to iterate; longer clips look impressive but drift more. For anything past eight seconds, generate overlapping segments and cut between them rather than asking one render to hold.
Keeping Characters Consistent Across Shots
Multi-reference conditioning
When a tool accepts several reference images, use them. Provide a clear front-facing portrait, a three-quarter view, and a profile if you have them. Consistency across angles teaches the model the underlying structure of the face instead of one flat appearance.
The shot bible method
Maintain a project document with the approved reference images, the locked prompt fragments for wardrobe and lighting, the seed values, and the settings that produced accepted takes. When a render drifts, you compare against the bible rather than guessing. This single habit eliminates most inconsistency complaints.
Practical consistency rules
- Keep wardrobe and hair descriptions identical across prompts.
- Avoid mixing drastically different lighting setups within a scene.
- Shoot or render all reference images at the same focal length.
- When a character must turn or speak, generate from the closest matching reference angle.
Choosing Models and Settings: A Decision Framework
Model names change constantly, so decide on capabilities rather than brands. Ask five questions before you commit to a render queue.
1. Does it accept image conditioning at all?
Some tools are text-only, some accept a single frame, and some accept multiple references plus a control signal. Your shot list dictates the minimum.
2. What is the effective maximum duration?
A tool that produces a stable four seconds is more useful than one that produces a shaky twelve. Check the length at which quality visibly degrades, then design your edit around that number.
3. How controllable is motion?
Look for a motion strength or camera parameter, a seed field, and negative prompting. Any tool missing all three will force you into a render-until-lucky loop.
4. What is the cost of a bad take?
Iteration speed is the real budget. A fast, cheap, slightly lower-quality model is often the right choice for drafting, with a heavier model reserved for final renders of approved shots.
5. Does it suit your subject matter?
Anime, product macro, human faces, and landscapes stress models differently. Always run your own genre test rather than trusting a general showcase.
The draft-then-final protocol
Draft at low resolution with a fast model and loose settings. Lock composition and timing. Then re-render only the approved shots at full resolution with your best model and tuned intensity. This two-pass approach typically cuts wasted render time dramatically while raising final quality.
A simple test protocol for any new tool
Take one still from your own library. Render it at three motion intensities with the same prompt and seed. Render one of those at double duration. Compare stability, face fidelity, and edge artifacts. You now know more about that tool than any marketing page can tell you.
A Repeatable End-to-End Workflow
Step 1: Define the deliverable
Write down the aspect ratio, target duration, frame rate, and platform. Every technical decision follows from this line.
Step 2: Build the shot list
Two to five shots is a realistic first project. For each, note the subject action and the camera move in one sentence.
Step 3: Prepare and approve stills
Upscale, crop, clean, and approve each source image before any animation happens. Reject anything with watermarks or heavy artifacts.
Step 4: Draft renders
Use a fast model, moderate motion, and short durations. Judge motion only; ignore grain and resolution at this stage.
Step 5: Fix and re-render
Adjust one variable at a time: intensity, prompt clause, or seed. Change two variables and you lose the ability to learn from the result.
Step 6: Final renders
Move to your best model at full resolution with locked seeds. Render one extra take per shot for safety.
Step 7: Editing and sound
Assemble in your editor of choice. Cut on motion, not on time. Add subtle scale animation to hide seams between segments. Sound is where AI video stops feeling synthetic: ambient beds, footsteps, fabric rustle, and a light music layer do more for believability than another render pass ever will.
Step 8: Color and delivery
Apply a consistent grade across all shots, add a light film grain, and export at platform-appropriate bitrates. Keep a master file at the highest quality in case you need a different aspect ratio later.
Troubleshooting Common Failures
Faces melting or changing identity
Cause: too much motion strength, too few reference angles, or a source image with soft facial detail. Fix: lower intensity, add a front-facing reference, sharpen the source, and keep the subject smaller in frame.
Flickering or pulsing brightness
Cause: compressed source, extreme contrast, or a prompt implying light changes. Fix: re-export the still cleanly, add steady lighting and consistent exposure to the prompt, and reduce intensity.
Warping architecture and straight lines
Cause: the model inventing parallax where none should exist. Fix: minimize camera movement, use a static shot with moving subject, and shorten duration.
Limbs appearing or duplicating
Cause: multiple overlapping subjects at similar depth. Fix: reframe so subjects are separated, or animate one subject at a time and composite later.
Output looks like a slow zoom on a still
Cause: motion strength too low or a prompt with no action verb. Fix: name a concrete action, raise intensity a notch, and describe what the atmosphere is doing.
FAQ
How long should a single AI-generated clip be?
Three to six seconds is the reliable zone for most tools. Anything longer benefits from generating overlapping segments and cutting between them.
Can I use AI-generated motion for commercial work?
That depends on the model's license and your local rules, so read the terms of the specific tool you use and keep records of your inputs. Many teams also keep human-authored elements in the pipeline to strengthen the final result.
Do I need a powerful computer?
Not necessarily. Most image-to-video tools run in the cloud. A mid-range laptop plus a stable connection is enough; a decent GPU only matters if you run open models locally.
What is the single biggest quality lever?
The source image. A sharp, well-lit, cleanly composited still outperforms any prompt trick applied to a poor one.
Should I write prompts in my native language?
Write in whatever language the model handles best, usually English, but keep a translated reference sheet so your team understands the intent behind each shot.
How do I stop the model from cutting to a new scene?
Add explicit continuity language such as single continuous shot, no scene change, same background, and pair it with a moderate motion strength and a short duration.
Building Your Own Muscle Memory
Image-to-video rewards repetition more than it rewards secret settings. Pick one shot type, one lighting setup, and one model, then produce twenty variations. Vary intensity, prompt clause, and duration one at a time, and write down what changed. Within a few sessions you will have a personal playbook that beats any generic tutorial, because it is tuned to your subject matter, your library, and your editing style.
Then scale carefully. Add a second character only after you can hold one. Add a camera move only after a static shot looks convincing. Add duration only after short clips are stable. Each constraint you remove should be a deliberate upgrade, not an experiment. That discipline is what separates a folder of wobbly test renders from a finished piece of work that audiences never question.
