
Why Precision Beats Volume in Modern Video Strategy
Producing video has never been cheaper. A single person with a laptop, a handful of generative models, and a decent storyboard can ship something that would have required a small studio a decade ago. That collapse in production cost has created a new bottleneck. The constraint is no longer rendering power or editing time — it is the decision of what to make, for whom, and in what format.
That decision layer is where data-driven strategy lives. When everyone can produce, attention becomes the scarce resource, and attention is allocated by relevance. A video that answers a question people are actively asking will outperform a technically superior video that answers a question nobody has. Trend analysis, done well, is simply a method for finding the questions before you spend the production budget answering them.
It helps to think in three loops that run at different speeds:
- The signal loop runs continuously. It watches search behavior, comment threads, save rates, remix activity, and emerging visual styles.
- The production loop runs weekly or biweekly. It converts validated signals into scripts, prompt sets, and rendered scenes.
- The feedback loop runs after publication. It measures whether the bet paid off and feeds that back into the signal loop.
Most creators only run the middle loop. They produce, publish, and move on. Teams that consistently win run all three and keep them connected, which is why an AI-assisted workflow matters: it shortens the distance between a detected signal and a finished asset to a few days instead of a few weeks.
The Signals Worth Tracking (and the Ones to Ignore)
Not all data deserves your attention. A useful filter is to ask whether a signal can change a decision you are about to make. If it cannot, it belongs in a dashboard you check monthly, not in your daily workflow.
Demand signals
These tell you what people want to watch. Strong demand signals include query growth in a topic area, repeated questions in comment sections across multiple creators, save-and-share ratios on short-form posts, and the emergence of new vocabulary around a subject. Vocabulary is particularly valuable — when a topic gains its own shorthand, it is usually about to expand.
Format signals
These tell you how people want to watch. Hook length, average scene duration, aspect ratio, caption density, and music style all move in cycles. A topic can be perfectly chosen and still fail because it was packaged in a format that felt dated. Format signals are best read by sampling the top performers in a niche and measuring structural properties rather than content properties: how fast the first cut arrives, how many distinct visual ideas appear in the first fifteen seconds, whether narration leads or follows the visuals.
Saturation signals
These tell you what to avoid. A topic with high demand and low supply is an opportunity. High demand with overwhelming supply is a trap unless you can bring a genuinely different angle. Saturation is measurable: count how many near-identical explanations of the same idea appeared in the last thirty days, and how many of them performed above the channel's own baseline.
Noise
Vanity metrics sit on the other side of the filter. Raw view counts without context, follower totals, and absolute like numbers rarely change a production decision. Worse, they encourage imitation of whatever is biggest rather than what is best suited to your audience and your production strengths.
Mapping Audience Intent with AI Trend Analysis
The practical heart of this workflow is turning messy, unstructured demand data into named content pillars you can actually produce against.
Clustering raw queries into semantic groups
Collect the raw material first: search suggestions, autocomplete strings, forum thread titles, comment questions, and short-form captions from adjacent niches. This will be several hundred lines of unstructured text. The goal is not to read it all — it is to group it.
A language model is genuinely good at this. Give it the raw list and ask for clusters with a short label, an estimated size, and a one-sentence description of the underlying intent. Expect clusters to fall into recognizable types:
- How-to intent: someone wants a process, a sequence, a recipe.
- Comparison intent: someone is deciding between two options.
- Diagnostic intent: something is broken or underperforming and they want a cause.
- Inspiration intent: they want to see what is possible, not how to do it.
- Identity intent: they want content that reflects who they are or want to be.
Each intent type maps to a different video structure. How-to content needs clear steps and visible progress. Comparison content needs side-by-side framing and a verdict. Diagnostic content needs a symptom-then-cause structure. Inspiration content can be loose and atmospheric. Identity content lives or dies on tone, casting, and music.
Naming content pillars from clusters
A cluster becomes a pillar when it is large enough to sustain multiple videos, specific enough to have a clear promise, and aligned with something you can produce repeatedly. Three to five pillars is usually the right number. More than that and you dilute; fewer and you run out of angles.
Assign each pillar a format, a target length, a primary platform, and a visual signature. That last item matters more than people expect. When viewers can recognize your series before the title appears, retention improves across every episode.
Validating demand before you produce
Validation is a cheap step that most teams skip. Before committing to a full production run, test the promise rather than the product: a script read-through recorded on a phone, a single generated key frame used as a thumbnail concept, or a short text post describing the premise. If the framing does not attract response in a low-cost test, a full render will not rescue it.
From Insight to Prompt: Translating Strategy into Generation
The distance between a trend report and a finished video is where most data-driven strategies quietly die. Closing that gap is a prompt engineering problem.
Prompt templates that encode strategy
Build reusable prompt templates instead of writing prompts from scratch. A good template encodes four things: subject, visual treatment, motion behavior, and format constraints. For example, a template for a comparison pillar might specify a split-frame composition, neutral studio lighting, slow lateral camera movement, and a vertical crop with safe space at the top for a headline.
Store these templates as text files with placeholders. When a new signal arrives, you fill the placeholders rather than reinventing the visual language. Consistency is a retention feature, and templates are how consistency survives contact with deadlines.
Maintaining a consistent visual language across a series
Three levers keep a series coherent when you are generating scenes individually: a locked reference image, a fixed palette described in words, and a small set of camera moves reused across episodes. Reference images are the strongest of the three, because most modern image and video models respond reliably to visual anchoring. Locking a reference also reduces the drift that appears when you describe the same character in slightly different words each time.
Shot lists and storyboard helpers
Draft the shot list before generating anything. A shot list is a list of information beats, not a list of pretty images: establish place, introduce problem, show failed attempt, show correction, show result. Once the beats exist, assign a generation approach to each one — text-to-video for atmospheric establishing shots, image-to-video for character consistency, and simple motion graphics for text-heavy explanation.
Assistant-style director tools can help here by expanding a paragraph of intent into a beat sheet, but treat their output as a first draft. Their value is speed of iteration, not taste.
Rapid Prototyping and Iteration Loops
Generation is fast enough that the limiting factor becomes experiment design, not rendering.
Batch generation and variant testing
The efficient pattern is to generate variants in batches along one dimension at a time: five hooks for the same script, or five visual treatments for the same hook. Change one variable per batch. If you change the hook and the visual style simultaneously, you learn nothing about either.
Keep a lightweight log. A single row per variant with the variable changed, the asset path, and the metric you care about is enough. Teams that skip logging end up re-testing the same idea months later without realizing it.
Basic experiment hygiene
Two rules prevent most false conclusions. First, decide the success metric before you publish — completion rate, save rate, click-through, or comment sentiment. Choosing the metric afterward guarantees you will find a story in the noise. Second, give a variant enough exposure to be meaningful. Short-form platforms distribute unevenly, and a variant with a few hundred views tells you almost nothing.
Choosing the Right Model for Each Job
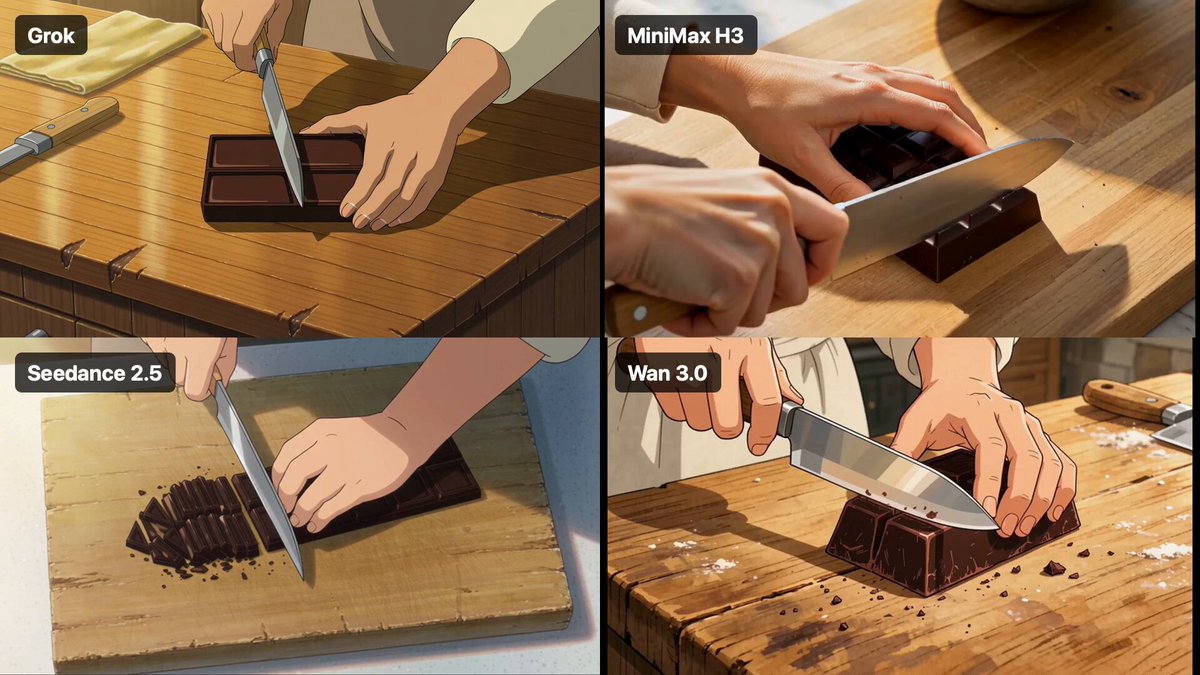
Model selection is a strategy decision disguised as a technical one. Different models excel at different things, and using the wrong one for a task wastes both time and money.
Matching model strengths to scene types
- Photoreal product and lifestyle shots: models with strong texture and lighting fidelity, usually driven from a reference image.
- Stylized animation and illustration: models that hold a consistent artistic style across frames.
- Dialogue and performance-driven scenes: models with better temporal coherence around faces and mouths.
- Abstract and transitional sequences: faster, cheaper models where motion smoothness matters more than detail.
Trade-offs to weigh
Four factors interact: fidelity, controllability, speed, and cost per finished second. High-fidelity models often cost more per attempt and require more retries, which changes the economics of a long scene. Fast models are excellent for boardomatic-style drafts where you are testing pacing rather than final look. Controllability matters most when a scene must match a locked reference or an existing brand look.
A practical default: draft everything with a fast model, then regenerate only the shots that survive editing at higher fidelity. This front-loads creative decisions and back-loads spending.
When reference images and fine-tuning pay off
If a character, product, or location appears in more than three videos, invest in reference material or a light fine-tune. The setup cost is repaid quickly through fewer retries and stronger series recognition. For one-off videos, skip it.
A Weekly Operating Rhythm for Data-Driven Video
Strategy fails when it is a quarterly document rather than a weekly habit. A simple rhythm works well for small teams.
Day 1: signal review and shortlist
Spend sixty to ninety minutes reviewing the signal loop. Cluster new queries, check saturation for your standing pillars, and shortlist two or three concepts. Write a one-line promise for each concept: who it is for and what they will be able to do afterward.
Midweek: production sprint
Convert the shortlist into shot lists and prompt sets. Batch-generate drafts, assemble a rough cut, and evaluate pacing before polishing visuals. The goal of this phase is a watchable draft, not a finished film.
End of week: performance review and archive
Review the previous week's published pieces against the metric you chose in advance. Archive the prompt templates, reference images, and variant log for anything that performed above baseline. That archive becomes your institutional memory, and it is the single most valuable asset a video team accumulates.
Mistakes That Quietly Break Data-Driven Video
- Chasing aggregate trends instead of niche demand. A globally popular topic can still be irrelevant to your audience.
- Confusing correlation with cause. A format that happens to accompany a hit is not necessarily the reason it worked.
- Optimizing hooks while ignoring retention. A strong opening with a weak second minute trains viewers to expect disappointment.
- Changing too many variables at once. You get a result but no knowledge.
- Letting templates fossilize. Templates should encode structure, not freeze style; revisit them monthly.
- Ignoring production cost per finished second. A workflow that needs twenty retries per shot is not sustainable, however good the peak output is.
- Publishing without a defined metric. Undefined success is indistinguishable from failure.
A Compact Scorecard
A small scorecard beats a sprawling dashboard. Track a handful of metrics, each tied to a decision.
| Metric | What it tells you | Review cadence |
|---|---|---|
| Hook retention (first 3 seconds) | Whether the promise lands | Per video |
| Completion rate | Whether the structure holds | Weekly |
| Save or share rate | Whether the content has lasting value | Weekly |
| Comment question themes | What to make next | Weekly |
| Cost per finished second | Whether the pipeline is efficient | Monthly |
| Series recognition (repeat viewership) | Whether your visual language is working | Monthly |
FAQ
How much data do I need before a data-driven approach is worth it?
Less than most people assume. A few hundred lines of search suggestions, comments, and forum titles are enough to produce meaningful clusters. The value comes from systematically turning that material into named pillars, not from volume.
Can AI trend analysis replace audience research?
No, and treating it that way is a common failure. Language models summarize and group what already exists in the text you give them. Direct conversation with your audience, customer interviews, and comment replies still surface motivations that no clustering pass will reveal.
Which model should I use for a first draft?
Use the fastest model that produces recognizable motion and composition. Draft fidelity is irrelevant at the boardomatic stage. Once the edit locks, regenerate surviving shots on a higher-fidelity model. This keeps spending aligned with decisions you have already made.
How do I keep characters consistent across many generated scenes?
Lock a reference image, describe the palette in fixed wording, and reuse a small set of camera moves. Avoid re-describing the character in different words for each shot, because small wording changes produce visible drift. If the character appears in many episodes, a light fine-tune is worth the setup.
What is the biggest mistake in AI-assisted video strategy?
Letting the technology drive the plan. Generative tools make almost anything producible, which tempts teams to start from what looks impressive rather than what the audience needs. Start from demand, then choose the production method that serves it.
How often should I revisit my content pillars?
Every four to six weeks is a reasonable rhythm. Pillars should be stable enough to build recognition and flexible enough to absorb new vocabulary as a topic evolves. If a pillar has not produced an above-baseline piece in two cycles, retire it and promote a cluster that is growing.
Closing: Build the System, Not the Single Hit
A single successful video is largely luck. A repeatable process that converts demand signals into finished assets is a business asset. The workflow described here is deliberately modest: cluster demand, name pillars, template your prompts, batch your variants, choose models per task, and review on a fixed cadence.
What makes it powerful is the connection between the loops. When a signal detected on Monday is a finished draft by Thursday and a measured result by the following week, you stop guessing. You accumulate knowledge about your audience faster than competitors who treat each upload as a fresh roll of the dice. Precision, not volume, is the durable advantage — and it compounds.
