
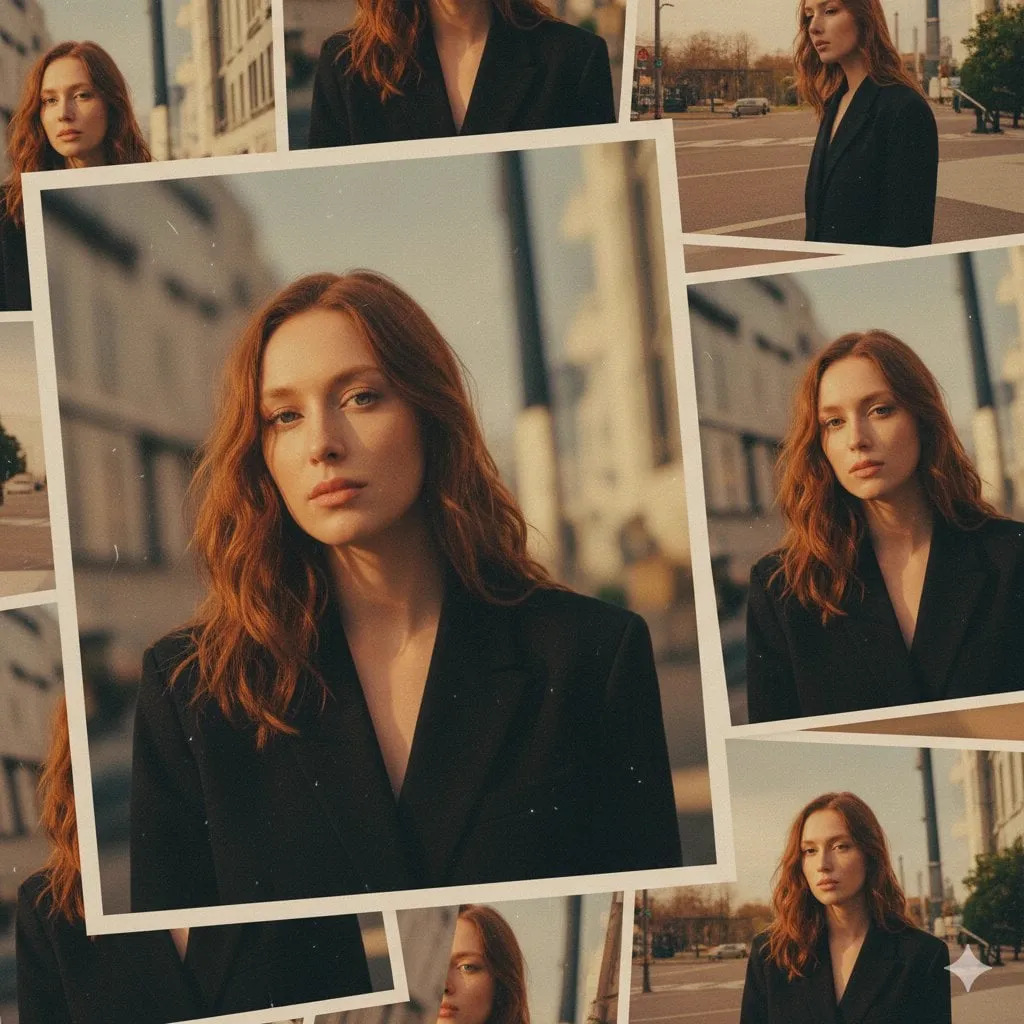
Multi-image fusion is the practice of feeding several reference images into a generative video pipeline so that a character, product, or visual style survives every cut, angle, and lighting change in a sequence. Instead of describing a person in words and hoping the model lands on the same face twice, you hand the system two to six curated stills and let it anchor identity to pixels rather than adjectives. The result is footage that feels like it was shot on one continuous production day rather than assembled from a dozen unrelated generations.
This guide walks through the mechanics, the preparation work, the failure modes, and the practical workflows you can run today. It is written for creators producing narrative shorts, brand spots, product loops, and serialized content where the same subject has to appear again and again without drifting into a stranger.
Why visual consistency breaks in the first place
Most generative video tools treat every prompt as an independent event. Ask for a woman with auburn hair and a green coat in a cafe, and you get one plausible woman. Ask again for the same woman on a street, and the model has no memory of the first frame. It reinterprets the text, resamples the latent space, and returns someone who shares a vibe but not a face.
Three forces drive the drift:
- Text is lossy. Words like "warm smile" or "silver pendant" map to huge regions of possibility. Two generations can satisfy the same sentence and share almost no visual detail.
- Sampling is stochastic. Even with a fixed seed, changing the camera angle, motion budget, or aspect ratio reshuffles the latent noise and pulls new features forward.
- Scene context bleeds. A dramatic sunset pushes skin tones warmer; a rain scene adds sheen and droplet textures that alter how a face reads. The character does not change, but the way the model renders them does.
Multi-image fusion attacks all three. Reference images are not suggestions; they are constraints. They carry far more information than a sentence, they are stable across runs, and they can encode the exact features you care about while leaving the model free to vary pose and environment.
What multi-image fusion actually is
Think of it as a casting sheet plus a continuity bible, compressed into images and injected into the generation step. The pipeline usually involves four moving parts:
- A feature encoder that converts each reference image into embeddings capturing identity, texture, and palette.
- A fusion step that blends those embeddings into a single conditioning vector, weighting some references more heavily than others.
- A generator that renders each new shot conditioned on that fused vector, so identity stays fixed while motion and camera work vary.
- A validator that compares generated frames against the references and flags drift before you waste time on a bad take.
The fusion step is where the craft lives. Averaging every reference equally tends to produce a mushy, generic face, because lighting and background differences fight each other. Weighting the cleanest, most neutral references higher, and using the rest as secondary anchors for silhouette or wardrobe, keeps the identity sharp.
Choosing references that actually work
Reference quality determines output quality more than any setting you will tweak later. A weak reference set cannot be rescued by prompt engineering.
The ideal reference set
Aim for three to six images of the same subject, ideally generated or captured in one session so the underlying identity is truly identical. Cover these angles:
- A frontal, neutral expression, evenly lit. This is your primary anchor.
- A three-quarter view, which teaches the model how the face reads when it turns.
- A profile, so the silhouette and nose line stay stable in side shots.
- One full-body frame, so proportions, build, and wardrobe are constrained.
- Optionally, one expression variant (laughing, speaking) to give the model range without identity loss.
What to avoid
- Mixed lighting temperatures across references. If one is golden hour and another is fluorescent, the fused vector splits the difference and the skin tone goes muddy.
- Heavy occlusion: hands over the face, hair blown across features, sunglasses that hide the eyes.
- Low resolution or compression artifacts. Detail loss in the reference becomes detail loss in every frame.
- Extreme expressions as your primary anchor. A wide grin distorts the jaw and cheek geometry, which then propagates into every neutral scene.
- Duplicates from the same second of footage. Five near-identical frames add no information and skew the weighting.
A validation pass before you commit
Before generating anything long, run two or three quick test shots: the subject in a plain environment, the subject in a contrasting environment, and the subject at a different camera distance. Compare the results side by side against the frontal reference. Ask three questions:
- Is the face recognizably the same person, or just a similar type?
- Did hairstyle, hairline, and facial hair survive the environment change?
- Did wardrobe and any signature accessory (a pendant, a specific jacket cut) stay intact?
If any answer is no, fix the reference set rather than adding prompt language. Statements like "keep the same face" rarely work; image anchors do.
Building a consistent sequence step by step
Here is a workflow you can adapt for a short narrative piece, a product spot, or a serialized social series.
Step 1: Lock the character bible
Write down the non-negotiables in plain text before you touch a tool. Not for the model, for you. Identity anchors (age range, hair, distinguishing features), wardrobe layers, accessory inventory, and the palette you want the character surrounded by. This list becomes your acceptance criteria when you review output, and it prevents the slow slide where each generation is "close enough" and the fifth one is a different person.
Step 2: Establish a master plate
Generate one wide, evenly lit, front-facing shot of your subject in the environment where the story begins. This is your master plate. It is the shot every later frame gets compared against. Keep it clean: no dramatic styling, no motion blur.
Step 3: Derive your reference set from the master plate
Instead of hunting for references from scratch, generate the frontal, three-quarter, and profile views from the master plate itself. Because they share an origin, the identity is already coherent, and you avoid the mixed-lighting problem entirely. This is the single highest-leverage habit in the whole workflow.
Step 4: Fuse and generate shot by shot
With the reference set locked, generate each shot as an independent scene that inherits identity from the fusion vector. Vary one thing at a time where you can: camera angle in one pass, lighting in another, action in a third. When a shot drifts, you will know which variable caused it.
Step 5: Gate every clip
Review each clip against three criteria before it enters the edit: identity match, wardrobe match, and color match with neighboring shots. Reject early and regenerate with a tighter reference subset. It is faster to redo one clip than to color-grade five clips back into agreement.
Handling scene transitions without losing the character
Transitions are where continuity usually falls apart, because a cut implies a different location, and different locations pull the model toward different looks.
- Cut on a matched element. End the outgoing shot on a detail that also exists in the incoming shot, such as a hand, a doorway, or a logo. The shared element gives the model and the viewer a visual thread.
- Keep one light source conceptually continuous. If interiors are lit from the left, keep shots lit from the left even when the location changes. Consistent light direction reads as the same world.
- Change location, not geometry. Moving the subject from a kitchen to a library is fine. Changing their apparent height, build, or facial structure is not.
- Insert a reaction shot at the seam. A close-up of the character reacting covers the shift in environment and gives you a natural place to reset the reference weighting.
Style fusion: keeping the look as stable as the face
Consistency is not only about people. If your series has a signature look, that look has to travel too. Treat style as a second fusion channel with its own reference set:
- Two or three frames that exemplify the palette, contrast, and texture you want.
- A frame showing how the style behaves in low light, since many styles collapse in shadows.
- A frame showing how it handles skin, because some stylizations wreck skin tones first.
Keep stylistic references separate from identity references. Mixing them into one pile lets a heavy grade dominate the identity embedding, and your character's face starts absorbing the style's color cast.
Decision criteria: when fusion is the right tool
Multi-image fusion is powerful but not free. It adds preparation time and constrains how far you can push a shot before identity breaks. Use it when:
- The same subject appears in more than two or three shots.
- The piece will be serialized, so viewers will notice drift across episodes.
- A real person's likeness matters, for example an approved brand ambassador or a known presenter.
- The deliverable is commercial and a mismatched face would be a credibility problem.
Skip it, or use lighter conditioning, when:
- The subject only appears once, in a single hero shot.
- The aesthetic is deliberately abstract, impressionistic, or rotoscoped, where exact identity is irrelevant.
- You are exploring concepts and want maximum variety before committing to a direction.
Common failure modes and how to fix them
Face drift across a long sequence
Usually caused by an inconsistent reference set or by a reference that is heavily stylized. Fix: rebuild the set from a clean master plate and drop any reference with unusual lighting.
Identity bleeds into the background
The model applies the fused embedding too broadly. Fix: weight references toward tight head-and-shoulders crops, and describe the environment explicitly so the model has something else to condition the background on.
Wardrobe mutation mid-sequence
Often the result of mixing references from different outfits. Fix: keep wardrobe references separate and only fuse in the outfit currently in play.
Waxy, over-smoothed faces
A symptom of over-weighting the identity vector, which can flatten texture. Fix: lower the identity weight slightly and let a natural-lighting reference contribute more detail.
Motion looks stiffer than usual
Heavy conditioning reduces the generative freedom the model uses to invent motion. Fix: generate motion separately where possible, or accept a slightly shorter, more deliberate camera move.
Managing a multi-shot project without losing your mind
The organizational side of consistency matters as much as the technical side. A few habits save enormous time:
- Name files with a scheme that encodes subject, shot, and version, so you can tell at a glance which clip belongs to which reference generation.
- Keep one canonical reference folder per character and never edit it mid-project. Create a new versioned folder instead, so you can trace why output changed.
- Log the settings for every accepted shot. When a later shot drifts, you can compare against a known good configuration rather than guessing.
- Batch by scene, not by shot type. Generating all the kitchen shots together keeps the palette coherent and reduces rework at the edit.
- Review in sequence, not in isolation. A clip that looks fine alone can jar visibly when cut next to its neighbors.
Task management in the generation tool matters here too. Group related shots under a single project, run them in a queue you can pause and inspect, and keep rejected takes labeled rather than deleted until the sequence is locked. You will sometimes pull a detail from a rejected take, such as a good hand position or a strong background plate.
Efficiency: where the time actually goes
Teams new to fusion often assume the bulk of the work is generating. In practice the split looks more like this:
- Reference preparation and validation: roughly a third of the effort on the first project, less on later ones because you reuse references.
- Generation and iteration: the largest chunk, but it shrinks fast once your reference set is stable.
- Review, gating, and rework: the hidden cost. A tight acceptance checklist cuts this dramatically.
- Edit and color: small if the previous stages did their job, painful if they did not.
The leverage is all in the front. Twenty extra minutes validating references routinely saves hours of regeneration and color matching. The second-largest lever is a written acceptance checklist, because it turns subjective "does this look right" reviews into fast yes-or-no gates.
A worked example: a three-scene product story
Suppose you are producing a short piece following one character using a compact espresso maker across three scenes: morning kitchen, mid-morning commute, office desk.
- Master plate: the character standing in the kitchen, neutral expression, even light, holding the product at chest height.
- Reference set: frontal, three-quarter, and profile derived from that plate, plus a separate still of the product alone at three angles.
- Scene one: the character at the counter. Identity from the character set, product geometry from the product set. Warm interior light, consistent from the left.
- Scene two: the character walking, product visible in a hand or bag. Same fusion vectors, cooler ambient light, same light direction relative to the subject.
- Scene three: the character at a desk, product on the surface. Slight top light, consistent palette, same wardrobe.
- Continuity check: place the three accepted clips side by side and scrub between them. Verify face, wardrobe, product silhouette, and color temperature. Regenerate the weakest clip rather than grading around it.
That structure generalizes to almost any subject: generate one strong anchor, derive references from it, fuse, then gate every clip against a short checklist.
Frequently asked questions
How many reference images do I actually need?
Three is usually the floor for a stable identity across angles, and six is a practical ceiling. Beyond that, additional references tend to dilute the fused vector unless they are all exceptional quality and perfectly consistent.
Can I reuse one reference set across different projects?
Yes, and you should, when the character or brand asset is meant to recur. Version it, document the settings that worked, and treat it as a reusable asset rather than something to solve again each time.
Does fusion work for non-human subjects?
It works well for products, mascots, vehicles, and stylized creatures. The principles are identical: consistent lighting across references, multiple angles, and a clean master anchor. Products are often easier because they lack the expressive variation that makes faces hard.
What if my source references are photographs of a real person?
Only proceed with clear permission and be deliberate about the use case. Likeness carries legal and ethical weight that stylized characters do not, and the reference set should be built from material you are entitled to use.
Why does one environment always break my character?
Check the light. Environments with strong colored casts, heavy fog, or dramatic practicals are the usual culprits, because they push the model's rendering of skin and texture. Add a reference frame from a similarly lit scene, or route those shots through a lighting pass after generation.
Is multi-image fusion worth it for a one-off clip?
Usually not. If a subject appears once, a well-written prompt plus a single reference is cheaper and faster. Fusion earns its overhead in sequences, series, and any work where the audience will see the same subject more than twice.
How do I know when a clip is truly consistent enough?
Judge it in context. Scrub it next to its neighbors at normal playback speed. If nothing pulls your eye, it passes. If you find yourself explaining away a difference, regenerate instead of rationalizing.
Bringing it together
Consistency in AI video is not a single setting; it is a production discipline built on a stable identity anchor, a disciplined reference set, and a fast review gate. Multi-image fusion gives you the technical mechanism, but the workflow around it is what makes a sequence feel intentional. Build one clean master, derive your references from it, fuse deliberately rather than averaging everything, and gate every clip before it reaches the edit. Do that consistently and the audience stops noticing the seams, which is exactly the point.
