
Why Multi-Model Beats Single-Tool Loyalty
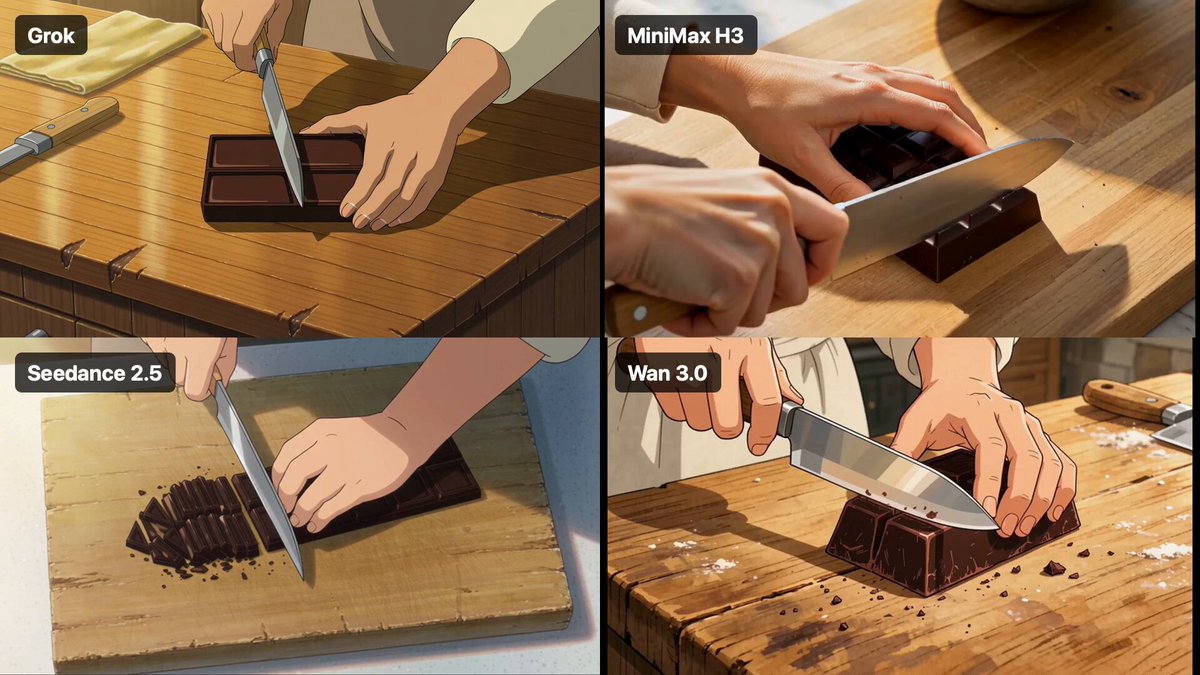
Every generative video engine has a personality. One renders skin, hair, and fabric beautifully but falls apart on fast lateral camera moves. Another handles crowds and physics convincingly but softens faces at a distance. A third is unmatched for stylized, illustration-like motion yet produces uncanny results with photoreal humans. If you commit to a single tool, you inherit its weaknesses as permanent constraints on every project you make.
Professional teams treat generation models the way a cinematographer treats lenses. Nobody shoots an entire feature on one focal length. You choose a wide for the establishing shot, a long lens for the intimate moment, and a macro for the insert. The same logic applies here: the best model is always the best model for this specific shot, in this specific style, at this specific stage of production.
There is a second reason to keep more than one engine in rotation. Roadmaps move fast. A tool that leads on realism this quarter may lag on controllability next quarter. Teams that build their pipeline around swappable components — planning, prompting, generation, assembly — survive those shifts without rewriting their entire process. Teams that build around one interface have to relearn everything when that interface changes.
Finally, multi-model workflows solve a practical problem: no single engine is good at everything a finished video needs. You need text-to-video for establishing shots, image-to-video for character consistency, lip-sync for dialogue, and upscaling or frame interpolation for the final finish. That is four different jobs, and they rarely live inside the same product.
The Four Layers of a Professional AI Video Pipeline
Before choosing tools, separate your production into four layers. Confusing them is the single most common reason AI video projects stall halfway.
Layer 1 — Development. Script, treatment, shot list, style references, and a clear decision about runtime and aspect ratio. This layer produces documents, not pixels.
Layer 2 — Asset creation. Character sheets, locations, props, and look-development stills. Almost every reliable AI video starts as a still image that already looks correct. If your still is wrong, no amount of motion prompting will save it.
Layer 3 — Motion generation. Text-to-video, image-to-video, video-to-video, lip-sync, and motion transfer. This is where most people spend 90 percent of their time and where model swapping pays off most.
Layer 4 — Assembly and finishing. Editing, sound design, color, upscaling, stabilization, and delivery specs. AI footage is raw material, not a finished film.
Teams that skip Layer 1 generate endlessly and never converge. Teams that skip Layer 4 export clips that look impressive in isolation and amateurish in sequence.
Planning: Script, Shot List, and Reference Assets
A shot list is the most valuable document in an AI video project. It forces you to decide, before generating anything, what each shot must accomplish.
Write shot rows with six columns: shot number, duration in seconds, description, camera behavior, model assignment, and status. The camera column matters more than beginners expect. "Slow push in," "static locked-off," "handheld follow," and "orbit right" produce radically different results on different engines. Some models handle a locked-off shot with a subtle breathing motion almost perfectly; others add unwanted drift no matter how you prompt.
Build a reference board next. Collect eight to twelve images that define your look: lighting direction, color palette, lens character, wardrobe, and environment. These references do two jobs. First, they keep your own taste consistent across a long project. Second, several engines accept a reference image alongside the prompt, which meaningfully improves style matching.
For anything with recurring characters, create a character sheet on day one. Generate ten to twenty variations of the same person — front, three-quarter, profile, neutral expression, extreme close-up, full body. Pick the three strongest and delete the rest. Those three become your anchors. Every later shot references one of them.
Finally, decide your aspect ratio and frame rate before generating. Vertical social clips and 2.39:1 cinematic framing demand different compositions, and regenerating a finished sequence because the ratio was wrong is the most avoidable kind of rework.
Prompting Techniques That Change the Output
Prompting for video is not prompting for stills. You are describing change over time, and the vocabulary reflects that.
Describe the camera, not just the picture
A prompt that only describes content gives the model freedom to invent camera behavior. Add explicit direction: "locked-off tripod shot," "slow dolly forward at walking pace," "camera tilts up to reveal the skyline." If you want no movement at all, say so twice in different words — models frequently interpret "static" as merely slow.
Motion verbs beat adjectives
"Cinematic" and "beautiful" do very little. "Steam rises from the cup," "the jacket flaps in the wind," "rain streaks across the lens," and "she turns her head toward the window" give the model concrete temporal events to render. One clear motion event per shot is usually better than three.
Specify what must not change
Negative instructions carry real weight in video: "no face distortion, no text overlays, no extra limbs, no sudden zoom." Keep the list short and specific. Long lists dilute each item.
Iterate one variable at a time
When a shot is close but not right, change one thing: the camera instruction, the lighting, the framing, or the motion. Change three at once and you learn nothing about which change mattered. Keep a simple log of prompt, model, seed, and result so you can reproduce a win later.
Matching Generation Models to Shot Types
This is where the multi-model approach earns its keep. Rather than ranking engines globally, rank them per job.
Dialogue and performance-driven shots
Performance shots need lip-sync accuracy and micro-expression control. Some engines specialize in driving a still portrait from an audio track, which is often more reliable than asking a text-to-video model to produce speech from scratch. Workflow: generate or select a strong portrait still, generate the audio separately, then drive the mouth and head movement from that audio. Record natural pauses; rushed audio produces frantic mouth movement.
Action, crowds, and complex physics
Fast motion, multiple subjects, and contact between objects are the hardest problems in generative video. Choose engines known for temporal stability, keep shots short — two to four seconds — and lean on editing to create the illusion of a longer action beat. Cutting on motion hides more artifacts than any upscaling pass.
Product, food, and brand-safe footage
Commercial work demands accuracy and repeatability. Image-to-video with a clean product still is almost always the right choice, combined with subtle camera moves and controlled lighting. Avoid text-to-video for anything with logos or brand-specific detail; models will hallucinate letterforms.
Stylized, animated, and graphic looks
For animation, illustration, and graphic-design-driven motion, engine choice matters less than consistency of style vocabulary. Pick a look descriptor set and reuse it verbatim in every prompt. Mixing "anime cel," "flat vector," and "painterly" in the same project guarantees a patchwork.
Keeping Characters and Locations Consistent
Consistency is the difference between a demo and a deliverable. Four techniques do most of the work.
Anchor every shot to a still. Image-to-video with a consistent starting frame beats text-to-video for character work, because the model inherits the character rather than inventing one.
Reuse a fixed style block. Write one paragraph of style language — lighting, palette, lens, grain, mood — and paste it into every prompt unchanged. Only the action sentence varies.
Keep seeds and settings documented. If a model supports seed control, record the seed for any shot you might need to extend or match. Losing a seed means recreating a look by trial and error.
Track wardrobe and props in a continuity sheet. A one-page table listing character, outfit, hair state, and key props per scene prevents the classic mistake of a jacket changing color between shots. Regenerate props as standalone stills and composite them if a model refuses to cooperate.
Locations follow the same rules. Build a plate shot — an empty, clean view of each environment — and use it as the base for every scene that happens there.
A Shot-by-Shot Production Walkthrough
Here is a complete loop you can run for a 60-second piece.
- Lock the script and shot list. Aim for 12 to 18 shots at roughly three to five seconds each. Fewer, longer shots are harder to generate and harder to fix.
- Create the look. Generate 20 to 30 style tests. Choose three that define the world. Do not proceed until you are genuinely happy; everything downstream inherits this choice.
- Build character sheets and location plates. Ten to twenty variations each, then select the best.
- Generate rough motion for every shot. Use your assigned engine per shot type. Accept imperfection at this stage; you are checking composition and continuity, not final quality.
- Assemble a rough cut with no sound. Watch it end to end. Most continuity problems become obvious here, and you will cut shots you thought were essential.
- Regenerate only the weak shots. Change one variable per attempt. Keep a version stack so you can revert.
- Add sound. Voice, ambience, and music change how footage reads more than most people believe. Motion that felt floaty often locks in once a footstep is audible.
- Finish. Upscale, stabilize, color grade, and export to your delivery spec.
Run this loop on a small project before applying it to a client deadline. The rhythm of generate-cut-regenerate is learnable, and it is faster to learn on something low stakes.
Editing and Compositing: Turning Clips Into a Film
AI clips are ingredients. The edit is the meal.
Start with a paper edit — an ordered list of shots with intended durations — before you touch generated footage. Then cut to the rhythm of the piece rather than to the length each clip happens to be. If a shot is three seconds long but the beat wants two, trim it. Cutting earlier than feels natural usually improves pacing.
Transitions are a repair tool as much as an aesthetic one. A whip pan, a match cut on motion, or a brief flash frame can hide a continuity break that would otherwise be visible. Hard cuts between shots from different engines are usually fine if the grade is matched; what betrays mixed sources is inconsistent contrast and color temperature, not the engines themselves.
Apply a single grade across the whole timeline. A slight contrast curve, matched black levels, and a consistent grain layer unify footage from different sources more effectively than any technical trick. Add subtle camera shake to static generated shots if the sequence feels lifeless.
Sound is where AI video stops looking like AI video. Layer room tone under every scene, add specific foley for actions the audience sees, and let music carry transitions. Silence is the fastest way to make synthetic footage feel synthetic.
Finally, upscale only after the cut is locked. Upscaling twelve minutes of footage you later trim to four wastes hours.
Quality Control, Iteration Budgets, and Common Mistakes
Set an iteration budget per shot before you start — typically three attempts for simple shots, six for hero shots. Without a budget, a single difficult shot can consume an entire production day.
Run a checklist before export:
- Does every shot advance the story or mood?
- Are faces stable for the full duration of every shot?
- Do hands, jewelry, and props survive the full motion?
- Is the camera behavior consistent with the intended style, with no unexplained drift?
- Do colors and contrast match across engines?
- Is audio mixed so dialogue sits above ambience?
- Is the export aspect ratio, frame rate, and codec correct for each destination?
Common mistakes worth naming: generating without a shot list, accepting the first plausible output, letting one engine handle every shot type, regenerating whole sequences instead of single shots, changing three prompt variables at once, and treating the first draft as final because the footage looks impressive in isolation.
The subtler mistake is over-generating. More footage does not produce a better film; it produces a longer edit. Shoot what the shot list needs, then stop.
FAQ
How many generation models do I actually need?
Two or three covers most projects: one for photoreal human performance, one for environment and action, and one that handles stylized looks. Add a specialist for lip-sync if dialogue is central.
Can I mix footage from different engines in one video?
Yes, and most audiences will never notice — provided you match contrast, color temperature, grain, and motion cadence in the edit. The giveaway is inconsistent movement speed, not inconsistent rendering.
Why does my character change appearance between shots?
Almost always because you are using text-to-video. Switch to image-to-video with a locked character sheet, reuse a fixed style block, and change only the action sentence.
How long should individual AI shots be?
Two to five seconds is the practical sweet spot. Longer clips accumulate artifacts and drift. If a beat needs ten seconds, cut it as three shots and let the edit create continuity.
Do I need to do post-production if the generation looks good?
Yes. Grading, sound design, and timing are what separate a clip compilation from a finished piece. Even a five-minute grade pass and a foley layer transform the result.
What is the fastest way to improve results?
Write a shot list, build character sheets before animating, and iterate one variable at a time. Those three habits account for most of the quality gap between beginners and experienced AI filmmakers.
