
Why Prompt Engineering Decides the Quality of AI Short-Form Video
Short-form vertical video is a demanding format. A viewer decides in less than two seconds whether to keep watching, and the platform rewards retention, rewatches, and shares. That means every frame has to carry intention. When you generate video with an AI model, the prompt is your only control surface before the render. It is not a magic phrase or a lucky string. It is a shot brief, a lighting plan, a performance note, and a continuity record all compressed into text.
A weak prompt usually fails in predictable ways: the camera drifts, the subject morphs, the light changes between cuts, or the action resolves too quickly. A strong prompt does not guarantee a perfect render, but it narrows the search space. It tells the model what matters, what can vary, and what must stay fixed. That is the core skill of prompt engineering for short-form video: reducing randomness while preserving enough motion and life to feel cinematic.
This guide walks through a model-agnostic workflow. It covers prompt structure, camera language, character consistency, iteration, troubleshooting, and advanced techniques. You can apply it whether you are generating a product teaser, a narrative micro-story, a music visual, or a social ad.
The Anatomy of a Directable Prompt
A directable prompt has layers. If you write one long sentence, the model has to guess which details are priorities. If you separate the layers, you can adjust one variable at a time. The most useful layers are subject, action, environment, lens, movement, light, style, and continuity.
Subject, action, and environment
Start with a specific subject. Instead of a woman, write a ceramic artist in her sixties with silver hair tied back. Instead of a car, write a matte-black electric coupe with rain beading on the hood. Specificity gives the model visual anchors it can reuse across shots.
Action should be simple and filmable. A model can render a hand reaching for a cup, a dancer turning, or a door opening. It struggles with complex sequences such as someone assembling furniture while explaining a recipe. For short-form, one clear action per shot is usually enough.
Environment sets the world. Include time of day, weather, texture, and depth. A rooftop at blue hour with distant city lights creates a different mood than the same rooftop at noon with harsh sun and laundry lines.
Lens, movement, and light
Lens language controls the feel. A 24mm lens gives a wide, immersive look. An 85mm lens compresses the background and flatters faces. Macro implies texture and detail. You do not need perfect camera metadata, but mentioning lens type helps the model choose perspective.
Movement should be explicit. Dolly in, truck left, orbit clockwise, crane up, handheld follow, whip pan, static tripod. Without a movement instruction, many models default to a slow push or a drifting frame that feels unintentional.
Light is the fastest way to change emotion. Soft window light feels intimate. Hard noon sun feels abrasive. Neon rim light feels nocturnal and energetic. Practical lights, such as a desk lamp or a refrigerator glow, add realism and motivate the source.
Style and continuity anchors
Style covers medium and treatment: photorealistic, 16mm film grain, anime concept art, claymation, watercolor, documentary handheld, studio commercial. Pick one primary style and keep it consistent across the sequence. Mixing styles between shots breaks the illusion faster than any technical artifact.
Continuity anchors are repeated details. Wardrobe, hair, props, color palette, location, and time of day should appear in every prompt for a given scene. If your character wears a red scarf in shot one, repeat red scarf in shot two. If the product is a blue bottle, repeat blue bottle with brushed metal cap. Models do not remember unless you remind them.
Negative constraints
Negative constraints are not a substitute for positive description, but they help. Useful exclusions include no text overlays, no watermark, no extra limbs, no rapid zoom, no scene cut, no cartoon style. Keep the list short. Too many negatives can flatten the image or confuse the model.
Build a Reusable Prompt Template for Vertical Video
A reusable template saves time and makes consistency easier. Fill in each slot, then shorten only if the model performs better with compact prompts.
[Shot size] of [subject] [action] in [environment], [camera movement], [lighting], [lens], [style], [continuity anchor], vertical 9:16, [negative constraints].
Example:
Medium close-up of a baker with flour on her apron pulling a tray of croissants from an oven in a small bakery kitchen, slow dolly in, warm morning light through a window, 50mm lens, photorealistic documentary style, mustard-yellow apron and copper oven door, vertical 9:16, no text, no watermark, no extra hands.
The same template works for a product shot:
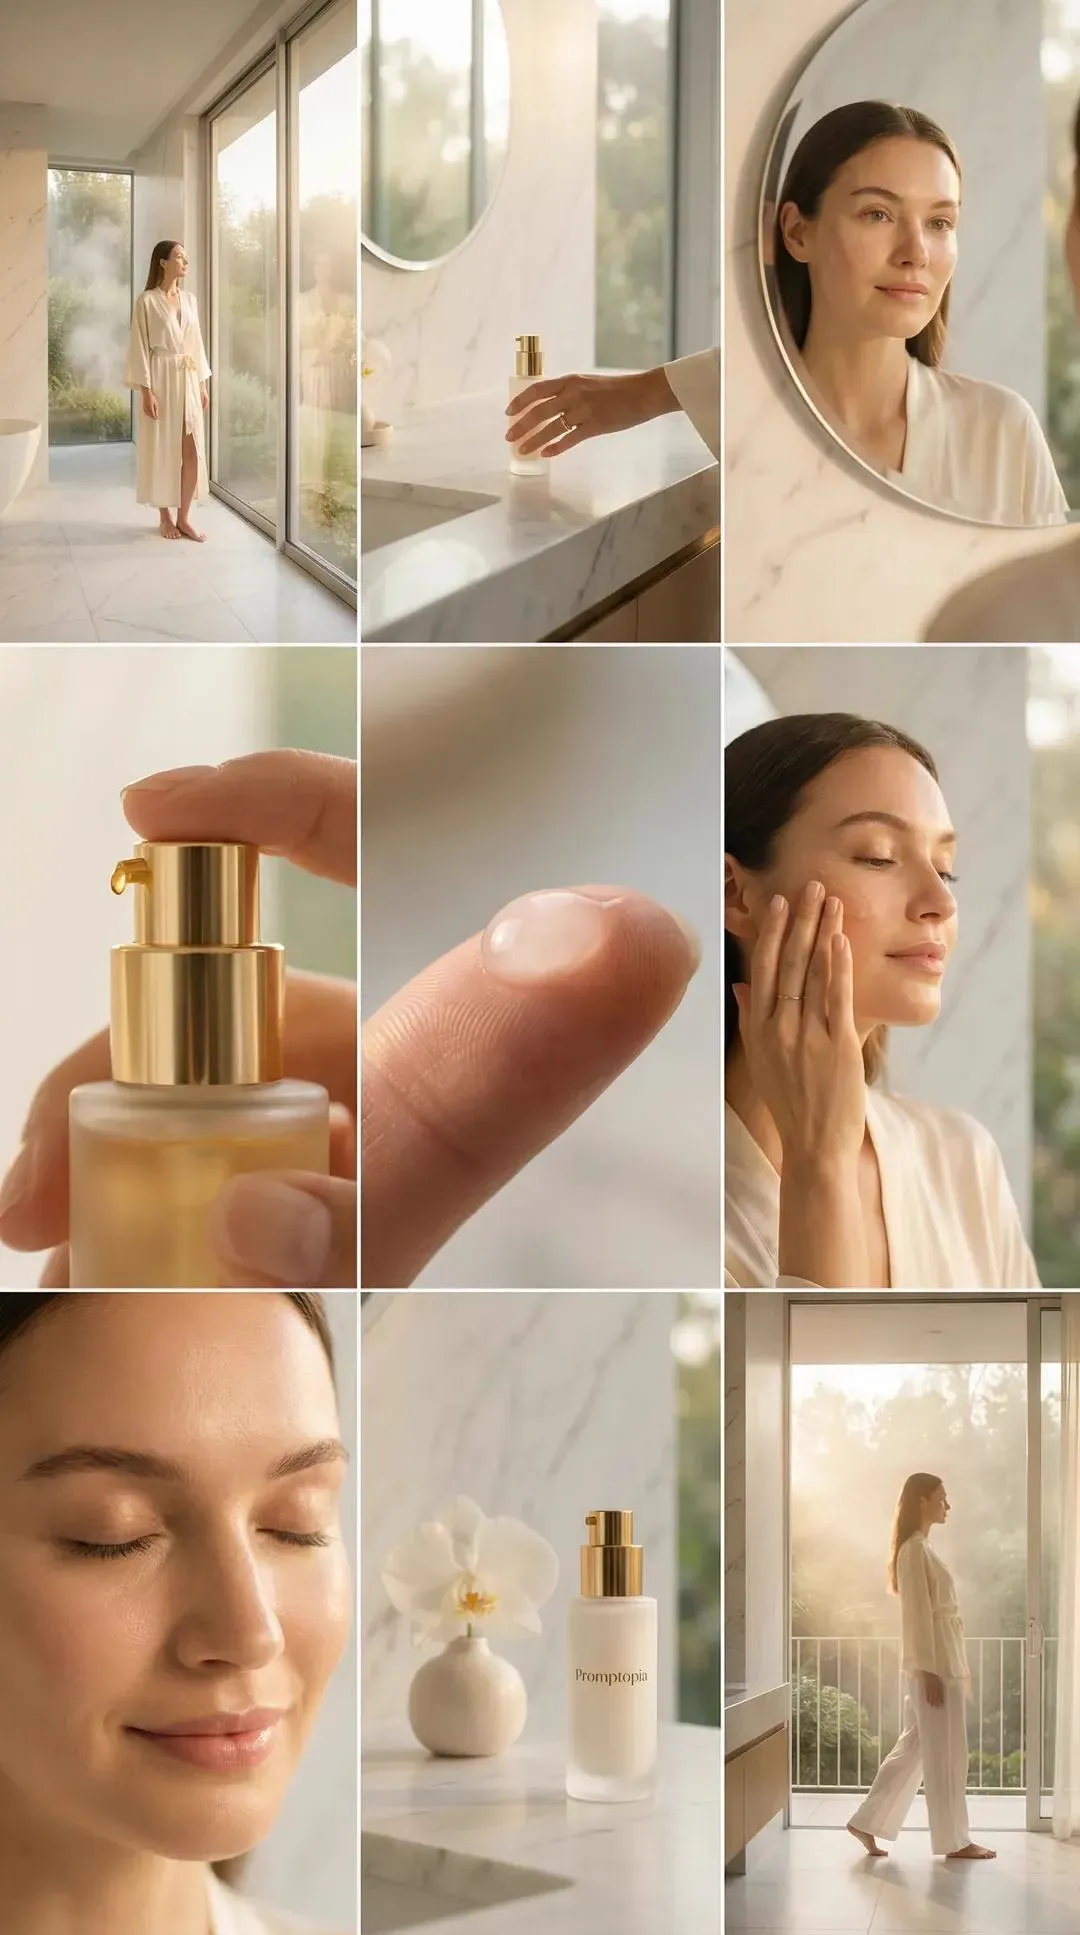
Macro shot of a glass dropper releasing a single amber drop into a ceramic dish on a stone counter, static camera with slight rack focus, soft side light, photorealistic commercial style, amber glass bottle and gray stone, vertical 9:16, no text, no reflections of people.
The template is not a cage. It is a checklist. If a generation fails, you can ask which slot caused the problem. Was the action too complex? Was the movement too fast? Was the style contradictory? Was the continuity anchor missing?
Directing Camera Language in Text
Camera language is where many AI video prompts become generic. You can direct the camera with the same vocabulary a cinematographer uses, but you have to be concrete.
Shot size and angle
Shot size tells the model how much of the subject to show. Extreme wide establishes scale. Wide shows the subject in context. Medium shows gesture and interaction. Close-up shows emotion. Extreme close-up shows texture. Angle adds attitude. Low angle makes a subject powerful. High angle makes them vulnerable. Overhead creates graphic composition. Eye level feels neutral and intimate.
For vertical video, a medium close-up is often the workhorse because it fills the frame and keeps the face readable on a small screen. Use wide shots sparingly unless the environment is the point.
Movement verbs that models understand
Movement verbs work best when they are physical and singular. Dolly in, dolly out, truck left, truck right, pan left, pan right, tilt up, tilt down, crane up, crane down, orbit, arc, push in, pull back, handheld follow, static lock-off. Avoid combining more than one major movement in a short shot. A dolly in with a simultaneous crane up and a whip pan is likely to produce chaos.
If you want energy, use handheld follow or a slight orbit. If you want elegance, use a slow dolly or a static frame with subject movement. If you want a reveal, start tight and pull back, or start wide and push in.
Composition for 9:16
Vertical composition is not horizontal composition cropped. You have less width and more height. Place the subject slightly off-center and use the upper third for eyes. Leave negative space above the head only if you need titles or breathing room. Use foreground elements, such as a doorway or plant, to create depth without crowding the sides.
When directing AI, mention vertical framing in the prompt. Many models still default to landscape. If the model supports aspect ratio settings, set 9:16 explicitly. If it does not, include vertical 9:16 composition in the text.
Keeping Characters and Objects Consistent Across Shots
Consistency is the hardest part of AI video. A model can generate a beautiful face in one shot and a different face in the next. You can reduce drift with references, anchors, and a disciplined continuity process.
Reference images and first-frame control
If the tool supports image references, use them. A clear headshot, a full-body wardrobe shot, and a location plate are often enough. First-frame control is even stronger: provide the exact opening frame you want, then describe the motion. This is useful for transitions, product rotations, and dialogue shots where the composition must match the previous cut.
Multi-image fusion and wardrobe anchors
Some tools allow multiple reference images. Combine a face reference, a wardrobe reference, and an environment reference. Keep the references clean and consistent in lighting. If the face reference is warm and the wardrobe reference is cool, the model may split the difference in odd ways.
Wardrobe anchors are simple but powerful. Repeat the same color, fabric, and silhouette in every prompt. If the character wears a green rain jacket, say green rain jacket in every shot. If the product label faces camera, say label facing camera. The model will not infer continuity from context.
Continuity checklist
Before generating a sequence, write a one-page continuity sheet:
- Character: age, hair, wardrobe, distinguishing features.
- Props: color, material, position.
- Location: time of day, weather, background landmarks.
- Palette: dominant colors, accent colors.
- Camera: preferred lens, movement style, aspect ratio.
- Style: medium, grain, contrast, color grade.
Paste the relevant lines into every prompt. It feels repetitive, but repetition is how you buy consistency.
Model-Specific Prompt Dialects Without Losing Your Style
Different video models respond to different prompt dialects. Some prefer natural language paragraphs. Some respond better to comma-separated tags. Some understand camera terms, while others ignore them unless they are phrased as visual outcomes.
Translating the same idea across engines
Keep a master prompt in your own words. Then create translations for each engine. For a natural-language model, write a short paragraph. For a tag-based model, break the prompt into subject, action, camera, light, style. For a model with limited motion control, replace camera movement with subject movement. For example, instead of dolly in, write subject slowly leans toward camera.
The goal is not to find one universal prompt. The goal is to preserve the same directorial intention across tools.
Testing matrix
When you test a new model, run a small matrix. Generate the same shot with three variations: minimal prompt, detailed prompt, and reference-assisted prompt. Compare motion quality, identity retention, lighting, and composition. Note which phrases improved results and which caused artifacts. Keep a personal prompt log. Over time, this becomes more valuable than any generic prompt list.
Budget-aware iteration without wasting generations
Generation capacity is limited, so treat it like a production budget. Use low-resolution drafts for motion tests. Lock the composition before you render high quality. Generate two or three variations of a shot, not twenty. If all three fail in the same way, the prompt has a structural problem. If they fail in different ways, the model is unstable and you should simplify the action.
Do not chase perfection in a single shot. Assemble a rough cut first. You will often discover that a shot you disliked works perfectly in context.
A Practical Workflow: From Concept to Final Cut
A reliable workflow turns prompt engineering from guesswork into production.
1. Concept and beat sheet
Write the story in five to eight beats. For a fifteen-second short, that might be hook, problem, turn, proof, payoff. For a thirty-second narrative, add character and conflict. Keep the beats visual. If a beat cannot be shown, rewrite it.
2. Look development
Generate still images or very short tests to define the look. Choose a palette, lighting style, lens feel, and level of realism. Approve the look before you generate many shots. This prevents a sequence where every clip feels like it belongs to a different film.
3. Shot list and prompt build
Create a shot list with columns: shot number, description, camera, duration, prompt, references, notes. Fill the prompt template for each shot. Read the sequence aloud. If two adjacent shots have conflicting lighting or wardrobe, fix the prompts before generating.
4. Generate, review, and rank
Generate a few takes per shot. Watch them without sound first to judge motion and composition. Then watch with sound to judge rhythm. Rank each take as keep, maybe, or reject. Do not delete rejects immediately; a fragment from a rejected shot may work as a transition.
5. Assemble, sound, and polish
Edit to the beat. Cut on motion whenever possible. Add sound design, music, and voiceover. AI video often lacks convincing audio, so sound is where you create realism. Add subtle camera shake, grain, or color grading to unify the shots. Export at the correct aspect ratio and check captions on a phone screen.
Troubleshooting Common AI Video Problems
Morphing faces and hands
Morphing usually comes from too much motion, too little reference, or conflicting style cues. Reduce the action to one simple movement. Add a clear face reference. Remove style words that imply distortion, such as surreal or melting, unless that is the intent. For hands, keep them out of the main action or specify hands resting on a table.
Camera drift and unwanted movement
If the camera moves when you asked for static, repeat static tripod shot and remove movement words. Some models interpret atmospheric words like sweeping or dynamic as camera instructions. Replace them with concrete descriptions of the subject or light.
Flat lighting or wrong mood
Flat lighting often means the prompt described content but not light. Add direction, quality, and color. For example, warm window light from the left, soft shadows, golden highlights. If the mood is wrong, change the light before you change the subject.
Inconsistent style between shots
Inconsistent style comes from changing too many variables. Lock the style phrase and the palette. Generate all shots in one session if possible. If the model drifts, use the previous shot's last frame as the first frame of the next shot.
Advanced Techniques for Narrative Short-Form
First-frame control for transitions
First-frame control lets you match a cut precisely. Generate a still that matches the end of shot one, then animate it as the beginning of shot two. This creates seamless match cuts, object reveals, and costume changes.
Reference-to-video for product or character shots
Reference-to-video is useful when identity matters. Provide a product photo or character sheet, then describe only the motion and lighting. Keep the reference clean and the prompt simple. The model already knows what the subject looks like; it needs to know what happens next.
Layered prompts for complex scenes
For complex scenes, separate the prompt into background, midground, and foreground. Direct each layer with its own light and motion. For example, background city lights bokeh, midground subject walking, foreground rain droplets on glass. This gives the model a depth plan instead of a flat image.
Quality Checklist Before You Publish
- The first frame stops the scroll.
- The subject is readable on a phone without zooming.
- Camera movement has a purpose.
- Lighting is consistent across cuts.
- Wardrobe and props remain stable.
- The action resolves within the shot length.
- Sound design supports the visuals.
- Captions are safe within the vertical frame.
- The ending invites a rewatch or a share.
FAQ
How long should an AI video prompt be?
Most models work well with 30 to 80 words. Start with a clear subject, action, camera, and light. Add style and continuity anchors only if they improve the result. Longer prompts can help with complex scenes, but they also increase the chance of contradictions.
Can I use the same prompt for every shot?
No. Reuse the style, palette, and continuity anchors, but change the shot size, action, and camera movement. A sequence needs visual variety, even if the world stays consistent.
What is the fastest way to improve consistency?
Use references and repeat continuity anchors. If the tool supports first-frame control, use the last frame of the previous shot as the first frame of the next one. This single habit can dramatically reduce visual drift.
Should I write prompts in English?
English is widely supported by video models, but you can write in your own language if the model handles it well. Test both. The important thing is clarity, not vocabulary. Short, concrete sentences usually beat poetic descriptions.
How many variations should I generate?
Two or three per shot is enough for most projects. If all variations fail, fix the prompt. If one variation works, move on. Generating endlessly wastes time and makes editing harder because you have too many similar clips.
Do negative prompts really matter?
They help with common artifacts such as text overlays, watermarks, and extra limbs. They are less useful for style control. Use a short list of negatives and put your energy into positive description.
How do I make AI video look less artificial?
Add motivated lighting, sound design, subtle grain, and camera imperfections. Keep motion simple. Cut on action. Use real reference images when possible. Artificiality often comes from over-smooth motion and inconsistent detail, not from the model itself.
What is the best way to learn prompt engineering?
Build a small library. For each project, save the prompt, the model, the settings, and a note about what worked. Review the library before starting a new project. Patterns will emerge faster than any tutorial can teach them.
Prompt engineering for short-form video is a craft of narrowing possibilities. You are not writing a poem to a machine. You are directing a shot. Be specific about what matters, stay consistent about what repeats, and iterate in small, deliberate steps. With a reusable template, a continuity sheet, and a disciplined review loop, you can turn unpredictable generations into a coherent visual story that holds attention from the first frame to the last.
