
Why text-to-video became a real production tool
A few years ago, generating a moving image from a sentence was a party trick. The clips were short, the faces melted, and the camera moved like it was attached to a drifting balloon. That era is over. Modern text-to-video models understand long, messy, natural-language descriptions, keep characters on-model across multiple shots, and produce footage that survives being cut into a real edit with sound design and color grading on top.
The practical consequence is that the bottleneck has moved. It is no longer "can the model make a video?" It is "can you describe, direct, and assemble the video you actually need?" The people getting the best results are not the ones with access to the most exotic model. They are the ones with a repeatable pipeline: a shot list, a prompting vocabulary, a consistency strategy, and a review loop that catches failures before they waste an afternoon.
This guide is built around that pipeline. It covers how the model landscape is organized, how to pick a tool per shot rather than per project, how to write prompts that behave predictably, and how to assemble output into something you would actually publish.
How the current model landscape is organized
It helps to stop thinking in terms of a single ranking and start thinking in families. Most leading tools cluster into three groups, and each group is good at a different job.
Cinematic realism and narrative coherence
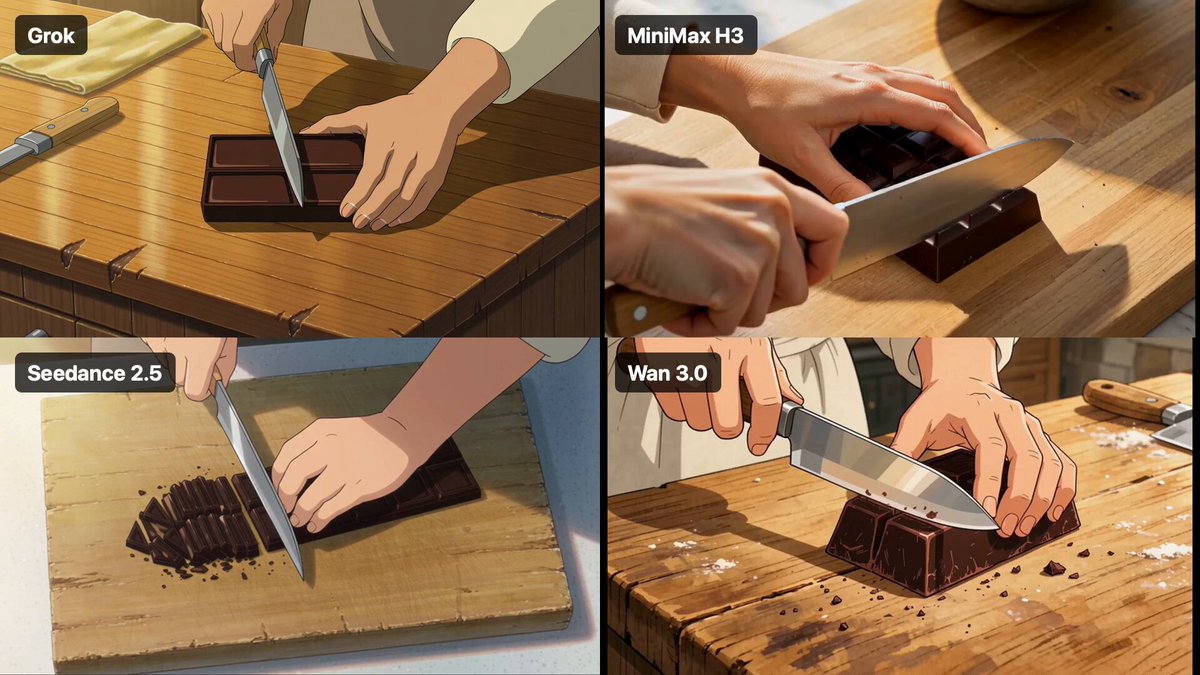
Flagship models such as Sora and Kling sit at the top of this group. Their strength is the ability to hold a long, layered prompt together: a specific subject, a specific action, a camera move, a lighting condition, and a mood, all at once. They tend to produce physically plausible motion, sensible shadows, and faces that stay recognizable across a cutaway.
These models are the right choice when the shot carries emotional weight: a hero close-up, a product reveal, a slow push-in on a character who has to look like the same person in the next scene. They are also the slowest and most resource-hungry option, which matters when you are generating forty shots instead of four.
Efficiency-first models
A second group optimizes for speed, iteration count, and predictable output. Runway, PixVerse, and similar tools are built for the stage where you are still deciding what the shot should be. You can generate eight variations in the time a flagship model takes to produce two, which makes them ideal for animatics, mood exploration, and social-first vertical content where a small imperfection is invisible on a phone screen.
The trade-off is fidelity under scrutiny. Fast models often struggle with crowded scenes, complex hand interactions, and long camera moves. Use them to find the shot, then re-render the winner elsewhere if the project needs polish.
Multimodal, control-heavy, and open models
A third group is defined by how much control it gives you rather than how beautiful the default output is. Luma Ray and Vidu are strong on image-to-video and keyframe conditioning, which means you can draw or generate a starting frame and an ending frame and let the model interpolate the motion between them. Open-weight options such as Alibaba's Wan and the Hunyuan family let teams run generation locally or fine-tune on their own footage.
Stylized specialists like Framepack and MAGI-1 sit in the same broad category: they are not general-purpose cinematographers, but they are excellent at a particular look or a particular editing task.
| Family | Best for | Watch out for |
|---|---|---|
| Flagship realism | Hero shots, character continuity, trailers | Slow iteration, higher compute spend |
| Efficiency-first | Animatics, social cuts, rapid exploration | Weak fine detail, unstable hands |
| Control and open models | Keyframe animation, brand-specific styles, local runs | Setup effort, prompt format quirks |
Choosing a model per shot, not per project
The most common mistake in AI video production is committing to one tool for an entire project. Real pipelines are mixed. A thirty-second brand film might use three different models, and that is a feature, not a compromise.
Use these questions as a quick decision filter:
- Does this shot need a recognizable face or a continuous character? Use a flagship realism model and lock the character with a reference image.
- Is this shot purely atmospheric? Fog, sky, water, abstract motion, and texture plates are cheap to generate and easy to fix later. A fast model is fine.
- Does the shot need a precise start and end pose? Use a keyframe-capable model so you control the blocking instead of hoping for it.
- Will the shot be seen at full resolution on a large screen? Raise quality, reduce ambition, and generate fewer, better takes.
- Is the shot a repeating element, like a logo sting or a lower-third animation? Generate once, then reuse the asset instead of regenerating it every time the model is updated.
A useful habit is to keep a running shot ledger: shot number, duration, model used, prompt version, and a one-line note about what was wrong with take one. After two or three projects, that ledger becomes your personal style guide.
Anatomy of a good text-to-video prompt
Prompting for video is not the same as prompting for images. A still image prompt describes a moment. A video prompt has to describe a moment, a motion, and a camera, and it has to do so without contradicting itself.
Subject, action, and camera
Start with a single clear subject. Not "a busy street," but "a courier in a wet yellow raincoat." Then give one primary action: "steps off a curb and looks up." Then specify the camera: "handheld medium shot, slight drift left, shallow depth of field." One subject, one action, one camera move. Everything else is seasoning.
When you stack three actions on one subject, models average them into mush. When you omit the camera, you get whatever the training data considered a default, which is usually a slow push-in.
Lighting, lens, and grade
Lighting language transfers surprisingly well from photography. "Overcast soft light," "hard noon sun with deep shadows," "warm tungsten interior with practical lamps," "blue hour with a single streetlight rim" — these phrases reliably steer the look. Lens language helps too: "35mm, slight barrel distortion" reads differently from "85mm, compressed background."
Add a color note at the end if the project has a look: "cool teal shadows, warm skin tones, film grain." Keep it to a phrase or two. Long lists of adjectives dilute each other.
Negative constraints and continuity locks
Telling the model what to avoid is often more useful than adding praise. Phrases like "no text overlays, no lens flare, no extra people in frame, no camera shake" prevent the specific failures that ruin otherwise good takes.
Continuity locks are the other half of the job. If a character appears in four shots, reuse the same reference image, the same wardrobe description, and the same lighting phrase in all four prompts. Small variations in wording produce small variations in faces, and small variations in faces are very visible in an edit.
A repeatable end-to-end workflow
The following sequence is boring on purpose. Boring pipelines are what let you take creative risks on the shots that matter.
Step 1: Script to shot list
Write the piece as prose first, then break it into shots with durations. Five to eight seconds per shot is a comfortable default, because that is where most models are most stable and where editors naturally cut.
For each shot, define three things: what changes on screen, what the audience must notice, and how the shot connects to the next one. If you cannot state the change in one sentence, the shot is probably two shots.
Step 2: Keyframes and references
Generate or select a still frame for any shot that needs a specific composition, character, or product. Even a rough reference image dramatically improves the odds of a usable first take, because it removes ambiguity about framing and scale.
For keyframe-capable models, create both a start and end frame. This is the single biggest quality lever available to non-technical creators: you are no longer hoping the model invents good blocking, you are telling it where to begin and end.
Step 3: Generation passes
Run wide first, narrow second. Generate several low-commitment variations to explore interpretation, then lock the best interpretation and re-run at higher quality with a tightened prompt.
Keep prompt changes isolated. If you adjust the camera and the lighting at the same time and the take improves, you have learned nothing. Change one variable per pass.
Step 4: Selection, assembly, and sound
Cut your selects against temp music before you fall in love with any individual shot. A shot that looks stunning in isolation often dies in a sequence, and a mediocre shot that carries the story often becomes invisible once it is cut in.
Sound is not decoration. Room tone, footsteps, cloth movement, and a light score change how motion is perceived. Many clips that feel "AI-ish" feel that way because they are silent, not because they are badly generated.
Consistency across shots: the hardest problem
Everything else in this guide is a workflow problem. Consistency is a research problem, and it is where most projects quietly fail.
Three tactics work reliably in practice:
- Reference-anchored characters. Reuse one canonical image per character and per costume. Do not regenerate the reference between shots.
- Locked environment language. Write your location description once and paste it verbatim into every prompt that takes place there. Do not paraphrase.
- Shot design that respects the limits. If a character must turn from profile to face, break it into two shots with a cut rather than asking one shot to do the rotation. Cuts hide inconsistencies; continuous motion exposes them.
When a model simply cannot hold a face, an acceptable fallback is to keep the character in silhouette, in profile, or partially framed. Restriction is a legitimate creative tool, not a defeat.
Common mistakes that waste hours
- Overloading a single prompt. Five actions, three characters, and a complex camera move in one generation produces average mush.
- Changing prompt wording between related shots. Paraphrasing breaks continuity more often than it fixes it.
- Judging takes in isolation. Always evaluate against the neighboring shots.
- Ignoring audio. Silent clips read as artificial regardless of visual quality.
- Chasing the perfect take forever. Set a take limit per shot and move on. Unfinished projects teach nothing.
- Forgetting aspect ratios early. Decide vertical, square, or widescreen before generation, not after.
Time, quality, and compute trade-offs
Every project has three budgets: time, quality, and compute. You can maximize two.
A practical allocation for a one-minute brand piece: spend roughly half your generation effort on the six to eight shots that carry the story, and treat the rest as connective tissue generated quickly. Nobody remembers the transition shot, but everybody notices when the hero shot is blurry.
It also helps to separate exploration from production. Exploration can be messy, fast, and low fidelity. Production should be a locked prompt set run through a stable pipeline with no experimentation left in it. Mixing the two phases is how teams end up with fourteen half-finished versions of the same scene.
FAQ
Do I need multiple models to get good results?
No, but most professionals end up with two or three: one for hero shots, one for fast iteration, and sometimes one for a specific look or local processing need.
How long should an AI-generated shot be?
Five to eight seconds is the sweet spot. Longer shots are possible but tend to drift in detail and are harder to edit around.
Why does my character's face change between shots?
Almost always because the prompt wording, reference image, or lighting description changed. Lock all three, then reuse them exactly.
Is image-to-video better than text-to-video?
For anything with a specific composition or product, yes. Text-to-video is best for atmosphere, motion, and discovery. Most strong pipelines start with an image and animate it.
How do I make output look less artificial?
Add sound design, cut more often, avoid long continuous camera moves, and keep a consistent color grade across all shots. Grade and audio do more for perceived realism than resolution.
Should I generate at the final resolution immediately?
No. Explore at lower settings, lock the take, then re-run at final quality. It saves substantial time and compute.
Key takeaways
Treat text-to-video as a directing problem, not a slot-machine. Split the work into phases — script to shot list, keyframes, wide generation, narrow generation, assembly — and keep one variable changing at a time. Choose models per shot: flagship realism for hero moments, fast models for exploration and connective tissue, control-capable and open models when you need precise blocking or a specific look. Lock character references and location language so continuity survives the edit. Finally, finish the video: sound, grade, and pacing are what separate a demo from something an audience will watch to the end.
