
Why Static Photos Are Suddenly Valuable Raw Material
Every content team is under pressure to publish more video than it could ever shoot. A product launch needs six vertical cutdowns. A travel brand needs a daily story. A small studio needs a sizzle reel before the client meeting tomorrow. Meanwhile, the archives are full of perfectly good stills: product photography, location scouting shots, wedding portraits, character sheets, book covers, museum scans.
Image-to-video generation closes that gap. Instead of treating a photo as a dead asset, you treat it as the first frame of a shot and let a model extrapolate motion forward. Done well, the result looks like footage someone filmed. Done badly, it looks like a melting wax figure sliding across the screen.
The difference between those two outcomes is almost never the model alone. It is preparation, prompt discipline, shot selection, and post-production. This guide walks through the entire pipeline as a practical workflow you can repeat, review, and hand to a teammate.
What Actually Happens When AI Animates a Photo
Under the hood, most image-to-video systems share the same skeleton. The source photo is encoded into a latent representation, the model adds temporal layers that reason about how pixels should move between frames, and a diffusion process denoises a sequence conditioned on that first frame. Some systems add explicit camera controls, some accept depth or optical-flow hints, and a few can accept a driving performance video to transfer motion onto a still face.
The Four Problems Every Model Is Solving at Once
- Motion plausibility — do objects accelerate, settle, and overlap the way real objects do?
- Identity preservation — does the face, logo, or texture stay the same person or thing?
- Scene physics — do water, hair, fabric, smoke, and reflections behave sensibly?
- Style consistency — does the grade, grain, and rendering style hold across the full clip?
Models trade these against each other. A prompt that produces gorgeous camera movement often destabilizes identity. A model optimized for facial realism may barely move anything else.
Why Duration Is the Hardest Constraint
The longer the clip, the more chances the model has to drift. Drift shows up as clothing changing color, background objects appearing or vanishing, or a slow morph of facial features. This is why the practical sweet spot for a single generated shot is usually a few seconds, and why editors stitch several short generations together rather than requesting one long take.
Choosing the Right Model for Your Shot
There is no single best tool. There is a best tool for a specific shot type, and you should expect to route different shots to different models.
Model Families and What They Excel At
- General image-to-video models such as Runway, Kling, Luma Dream Machine, Pika, Veo, and open models like Wan or Stable Video Diffusion. Best for landscapes, establishing shots, product beauty shots, and stylized footage.
- Performance and motion-transfer tools such as LivePortrait-style pipelines or face-driven capture features. Best for portraits where a still face must speak, blink, or turn.
- Talking-head and avatar tools from HeyGen, Synthesia, D-ID and similar. Best for explainers, training content, and localization where lip-sync accuracy matters more than cinematic movement.
- Depth-based 2.5D parallax approaches such as depth-driven parallax in After Effects or dedicated depth tools. Best when you want subtle, photoreal camera drift with zero risk of morphing.
- Traditional compositing in After Effects or DaVinci Resolve. Often the right answer for packshots, UI screenshots, and text-heavy images where any AI hallucination is unacceptable.
Decision Criteria You Can Apply in Thirty Seconds
| If your shot is... | Reach for... | Because... |
|---|---|---|
| A wide landscape or cityscape | General image-to-video | Motion is ambient, identity risk is low |
| A close-up human face | Motion transfer or avatar tool | Identity preservation beats spectacle |
| A product on a plain background | Parallax or compositing | Precision matters more than realism |
| A stylized illustration | General image-to-video with strong style prompt | Models handle painterly motion well |
| A text-heavy graphic | Manual compositing | Any warping is immediately visible |
When in doubt, generate the same shot with two different models and compare only the first two seconds. That comparison usually decides it.
Preparing the Source Photo: The Step Most People Skip
Most disappointing generations trace back to the input image, not the prompt.
Resolution, Aspect Ratio, and Crop
Feed the model enough pixels to work with, ideally at least 1080 pixels on the short side, but not so many that the model invents detail. Match the aspect ratio of your target platform before generating, not after. Cropping a 16:9 generation into 9:16 destroys framing you carefully prompted for.
Fixing Problems Before They Get Animated
- Remove dust, sensor spots, and compression artifacts.
- Separate the subject from a busy background if you can, or choose a shot where the background won't distract.
- Straighten the horizon; a tilted horizon becomes a swaying horizon in motion.
- Neutralize heavy filters. Oversaturated HDR looks like a rendering error once it moves.
- Upscale cleanly rather than sharpening aggressively. Sharpening halos flicker badly frame to frame.
When to Composite Instead of Animate
If the image contains a logo, readable text, or a face that must be pixel-accurate, consider animating only a portion of the frame and compositing it back into a mostly static shot. This hybrid approach gives you motion where it reads and safety where it matters.
Prompting for Believable Motion
Prompts for video are not prompts for images. You are describing change over time, not content.
The Four Variables Worth Specifying
- Camera — static tripod shot, slow push in, slow dolly out, handheld drift, crane up, orbit left.
- Subject — what moves, how much, and in what direction. "She turns her head slightly toward camera" beats "she moves."
- Environment — wind in the trees, rippling water, drifting dust motes, passing clouds, flickering neon.
- Style and grade — documentary handheld, 35mm film grain, cool teal grade, soft overcast light.
Name a small number of movements. Three concurrent motions is usually the ceiling before the model produces mud.
Camera Language That Models Understand
Phrases like "slow push in," "static shot," "subtle handheld sway," and "slow tilt up" map to recognizable motion patterns in most systems. Exotic camera terminology from film sets often does nothing.
Negative Prompts and What to Exclude
When the tool supports negative prompting, use it. Common exclusions: extra limbs, distorted faces, warping text, jitter, flicker, morphing, duplicate objects, sudden zoom, oversaturated colors. Even without a dedicated negative field, an affirmative instruction like "stable camera, steady framing, consistent lighting" helps.
Duration, Frame Rate, and Seed Discipline
Generate the shortest clip that tells the story. Keep frame rate consistent across every clip in a project. Lock your seed when you want reproducibility and vary it deliberately when you want options. Record the seed, model version, and prompt for every keeper so you can regenerate or extend it later.
A Repeatable End-to-End Workflow
Here is the sequence that keeps quality predictable and review cycles short.
Step 1 — Define the shot list first. Write down what each clip must communicate in the edit. Animating photos without a shot list produces beautiful clips that don't cut together.
Step 2 — Audit and rank your source images. Score each on sharpness, subject separation, and how much motion you can plausibly invent. Reject anything blurry or cluttered early.
Step 3 — Prepare and standardize. Batch-process crop, exposure, and cleanup so every image is consistent before generation.
Step 4 — Generate a motion test at low resolution. Two seconds, cheapest settings, one variable changed at a time. This is your storyboard.
Step 5 — Promote the winners. Re-run the best prompts at full resolution and full duration with the same seed.
Step 6 — Generate three to five takes per shot. You are casting, not engineering. Selection is faster than iteration.
Step 7 — Assemble a rough cut immediately. Motion that looks great in isolation can feel wrong in sequence. Edit early.
Step 8 — Repair the weak shots. Re-generate only the specific clip that fails, keeping everything else untouched.
Step 9 — Finish and deliver. Upscale, interpolate, grade, add sound, and export platform-specific versions from one master timeline.
Keeping Characters and Products Consistent Across Shots
Consistency is where most multi-shot projects collapse. A character who looks slightly different in every clip breaks the illusion instantly.
Practical countermeasures:
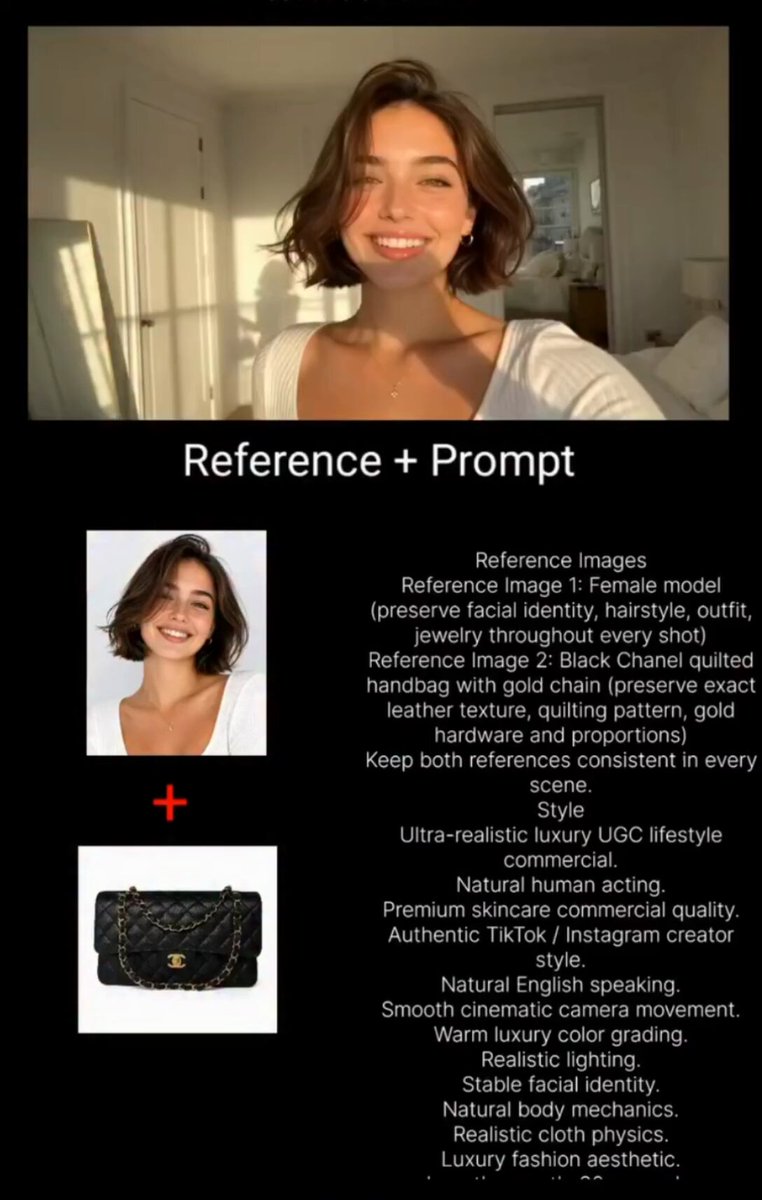
- Build a reference pack: three to five images of the same subject from different angles, in consistent lighting.
- Reuse the same seed and model version for every shot featuring that subject.
- Keep prompt structure identical. Change only the camera and motion lines between shots.
- Train or apply a style adapter if your tool supports it, rather than describing the style in words every time.
- Lock a color pipeline so every clip passes through the same grade, grain, and lens treatment.
- For products, generate motion on a plate and composite the real product photography on top when label accuracy is non-negotiable.
Post-Production: Making AI Clips Look Finished
Raw generations rarely ship as-is. A short finishing pass does more for perceived quality than another hour of prompting.
- Upscale with a video-aware upscaler such as Topaz Video AI or a comparable tool. Video-aware models handle temporal consistency better than image upscalers applied frame by frame.
- Interpolate frames with RIFE-based tools when you need smoother motion, but use restraint — interpolation amplifies artifacts in warping areas.
- Stabilize and deflicker to remove the low-frequency wobble that many generations exhibit.
- Add grain or texture to unify synthetic and real footage in the same timeline.
- Grade everything together in Resolve or Premiere so the AI clips and any live-action shots share a look.
- Design sound. Ambience, foley, and a music bed do more to sell motion than most visual tweaks. A clip that feels flat often just needs wind, footsteps, or room tone.
- Caption and re-frame last, exporting vertical, square, and widescreen versions from one master.
Common Mistakes and How to Fix Them
The subject melts. Usually caused by extreme motion, low-resolution source, or too long a duration. Shorten the clip, reduce motion amplitude, and upscale the input first.
Everything flickers. Often a sharpening artifact or an unstable seed. Ease off sharpening, generate at a consistent resolution, and enable deflicker in post.
The camera drifts when you asked for static. Add explicit static-camera language, reduce duration, and avoid prompts that imply movement in the environment.
Background objects appear and disappear. Long durations and vague environment prompts. Specify the environment once, keep the clip short, and avoid describing new objects mid-prompt.
The style changes halfway through. Split the shot into shorter generations and cut between them, or reduce the number of competing style adjectives in the prompt.
It looks like AI. Usually a combination of over-smooth textures, perfect symmetry, and no sound design. Add grain, slight camera imperfection, realistic audio, and a grade that matches your other footage.
FAQ
How long should a single generated clip be?
Start at two to four seconds. Extend only when the shot genuinely needs it, and expect to cut between shorter generations instead of relying on one long take.
Can I animate a low-resolution or old photograph?
Yes, but restore and upscale first. Scanned family photos and archival images often animate beautifully once grain and scratches are cleaned up, because the motion is subtle.
Do I need to learn prompt engineering to get good results?
You need a small, repeatable vocabulary: camera move, subject action, environment motion, style. That is most of it. Consistency comes from seeds and references far more than from clever wording.
What about text and logos in the source image?
Treat them as untouchable. Animate a plate behind them or animate a region and composite the clean text back on top in your editor.
How many takes should I generate per shot?
Three to five is a healthy range. Fewer and you accept mediocre motion; more and you spend time reviewing instead of editing.
Is image-to-video a replacement for shooting?
No. It is a gap-filler, a previsualization tool, and a way to revive archives. For hero footage with people speaking on camera, filming is still faster and safer.
What is the fastest way to improve quality?
Fix the input image, shorten the clip, and add sound. Those three changes consistently outperform switching models.
Where to Take This Next
Pick one photo you already own and run the full loop: prepare it, write a four-line prompt with camera, subject, environment, and style, generate three short takes, pick the best, then upscale and add sound. That single exercise teaches more than reading another comparison of models.
From there, build a small internal library: your preferred prompt templates, the seeds that worked, the reference packs for recurring characters and products, and the finishing chain that makes synthetic footage match your real footage. The teams that get the most from image-to-video treat it as a production pipeline, not a magic button. The magic is in the repetition.
