
What "Unrestricted" Actually Means for AI Video
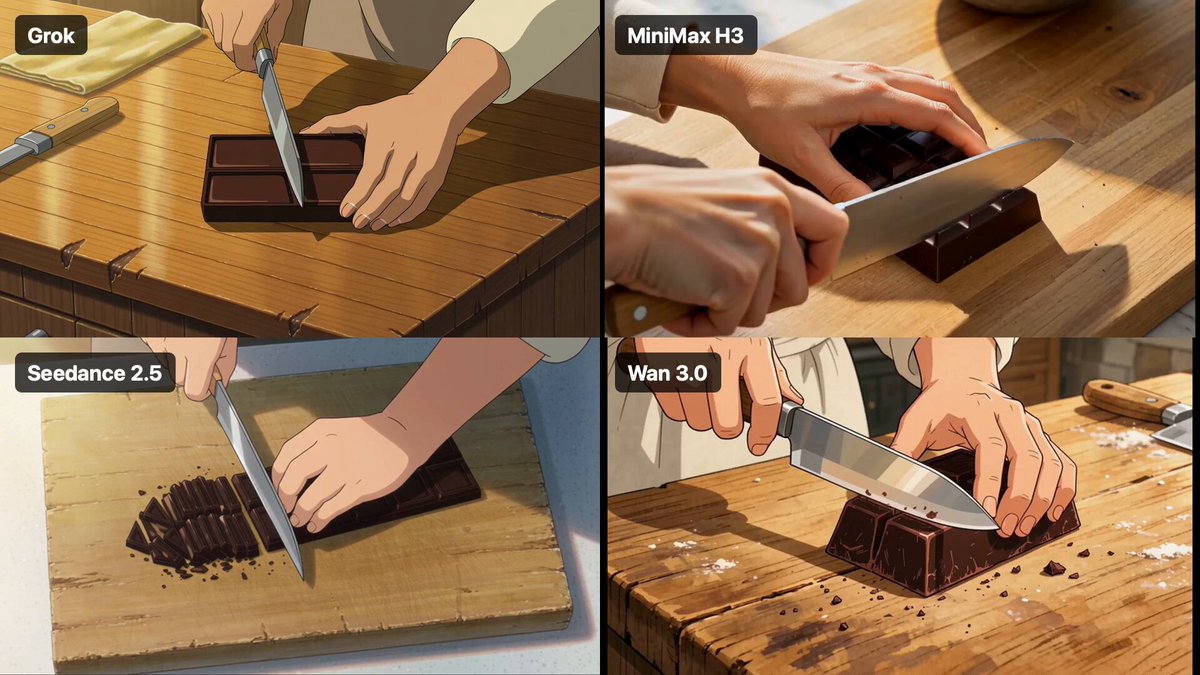
The phrase "unrestricted AI video" gets thrown around as if there is a secret menu of tools that will render anything you type. In practice, almost every serious creator means something more specific: they want maximum creative latitude inside a reliable production pipeline. That means flexible shot duration, the ability to swap keyframes, support for unusual art styles, freedom to combine models, and no hard stop when a project outgrows a single tool.
Freedom in AI video comes from three places, and only one of them is the model itself.
- Model capability. How well the generator handles motion, physics, camera language, and unusual aesthetics.
- Pipeline design. Whether you can move a shot between tools, regenerate one element, or layer a video model on top of an image model without destroying continuity.
- Rights and hosting. Whether you can run the model locally, keep your footage private, or use outputs commercially without an unclear license.
A generator that refuses a prompt is annoying for thirty seconds. A pipeline that cannot accept a revised shot is expensive for a week. Most of the frustration people attribute to "restrictions" is really a workflow problem: they built a one-way street from prompt to final render, with no branch points for iteration.
This guide treats the model landscape as a set of interchangeable parts. It covers the major families of video generators, how they differ in practice, how to choose between them, and how to build a pipeline that stays flexible even as individual tools evolve under you.
The Four Families of Video Generators Compared
Almost every model you will encounter falls into one of four practical categories. The category matters more than the brand name, because it determines how the model fits into your workflow.
Hosted flagship models
This is the group most people mean when they say "AI video": large hosted models with strong realism, good prompt adherence, and cinematic motion. Examples include Runway's Gen-3 and Gen-4 lines, OpenAI's Sora family, Google's Veo line, and Luma's Dream Machine.
Strengths:
- Excellent physical plausibility — water, cloth, smoke, and crowds behave convincingly.
- Strong camera control vocabulary: dolly, crane, handheld, rack focus.
- Reliable image-to-video, which is the single most useful feature for narrative work.
Trade-offs:
- Outputs live on someone else's infrastructure, with terms that vary by plan.
- Latency can be significant for high-resolution renders.
- Style range is broad but often leans toward a polished, slightly glossy "AI look" unless you push against it.
Best used for: hero shots, character close-ups, and anything where realism sells the story.
Style-and-control specialists
A second group competes on controllability rather than raw fidelity. Kling, PixVerse, and Pika sit here, along with several regional models that dominate in specific markets.
What they do well:
- Precise adherence to short, dense prompts.
- Photographic parameter control — lens length, depth of field, lighting direction.
- Fast iteration cycles, which makes them ideal for storyboard exploration.
These models are often the better first stop for a project, because you can audition twenty visual directions cheaply before committing a hero shot to a slower flagship render. Treat them as your sketchbook, not your final camera.
Open-weight and self-hosted models
The most genuinely "unrestricted" option is a model you run yourself. Wan, HunyuanVideo, LTX-Video, Mochi, and various distilled derivatives can be installed locally or on rented GPU instances. Because the weights are downloadable, the practical constraints change completely:
- No prompt queue, no waiting on someone else's capacity.
- Full control over filters, safety layers, and fine-tuning.
- Your footage never leaves your machine, which matters for client work under NDA.
Trade-offs are real. You need a capable GPU, comfortable VRAM headroom, patience with dependency installation, and a tolerance for occasional broken generations. Output quality on a single consumer card is usually below a hosted flagship, though the gap narrows every few months and shrinks further when you upscale and finish in post.
Image-to-video and hybrid pipelines
Many professionals no longer start with text at all. They generate a still, refine it until it is exactly right, then animate it. This hybrid approach splits the problem: the image model handles composition, lighting, and character design; the video model handles motion.
This is where image generators such as the Flux series earn their place in a video workflow. A strong still model gives you granular control over framing and style, and image-to-video models then need only to animate a scene that is already correct. The result is far more predictable than prompting a scene from scratch.
A Decision Framework: Matching the Model to the Job
Rather than crowning a single best model, decide per shot. Run through these questions in order.
1. Does the shot involve a specific person or product? Use image-to-video. Generate or photograph a reference frame, then animate it. Text-to-video will reinvent your subject on every attempt.
2. Does the shot need physical realism? Splashing water, breaking glass, fabric in wind, large crowds — go to a flagship hosted model. This is where their training budgets show.
3. Does the shot need an unusual aesthetic? Analog grain, stop-motion, painted animation, brutalist architecture — test specialists and open-weight models. Smaller models are often trained on narrower, more distinctive data and produce less generic textures.
4. Is confidentiality a constraint? Open weights only. If the footage cannot leave your network, the decision is made for you.
5. Is volume more important than polish? Open-weight or specialist models with fast iteration. A hundred adequate clips can beat ten perfect ones for social formats.
A practical rule: storyboard with specialists, produce hero shots on flagships, and handle volume, privacy, or unusual looks with open-weight models. Most professional pipelines end up using all three.
Prompting for Flexibility: Structure, Motion, and Camera Language
Prompts fail in predictable ways. They ask for too much at once, they describe mood instead of motion, or they describe motion without anchoring the subject. A flexible prompt is structured, not poetic.
Use a four-part frame:
Subject and action. Who or what, doing what, right now. One primary action per shot. "A cyclist rounds a wet corner" works; "a cyclist reflects on life while racing through a neon city" gives the model five jobs.
Environment and light. Time of day, weather, key light direction, colour temperature. Lighting is the cheapest way to make outputs feel intentional.
Camera. Shot size, angle, and movement. "Medium close-up, eye level, slow push in" is more controllable than "cinematic." Most models respond to a small vocabulary: push in, pull out, pan, tilt, tracking, orbit, static, handheld, drone.
Format cues. Aspect ratio, lens character, grain, frame rate feel. Adding "shot on 35mm, shallow depth of field, subtle grain" changes output character dramatically.
Keep a running prompt library. When a combination works, save it with the exact model version noted. Model updates silently change behaviour, and a prompt that sang last month may drift. Versioning your prompts is the difference between a repeatable style and a lucky accident.
Negative guidance matters too. Most tools accept a list of things to avoid: warped hands, floating limbs, text artifacts, jitter, over-smoothing. Keep the list short — five to eight items — and specific. Long negative lists tend to cancel each other out.
Finally, work in short durations. Four to eight seconds per generation gives you more control, better motion coherence, and easier editing than chasing a twenty-second single pass. You can always extend a shot in the edit; you cannot easily repair a long clip that drifts.
A Practical End-to-End Production Workflow
Here is a workflow that keeps every stage reversible. The goal is that at any point you can change your mind without restarting.
Step 1: Script and shot list
Write the script, then break it into shots with a one-line description each: subject, action, camera, duration. Twenty shots of four seconds is a ninety-second film. Be explicit about which shots are hero shots and which are connective tissue — this determines where you spend render time.
Step 2: Generate keyframes
Before animating anything, produce a still for every shot. Use an image model, a photograph, or a frame grab. Fix composition, lighting, and character design here, where iteration is fast and cheap. Approve all keyframes as a contact sheet before you proceed. This single step prevents most consistency disasters.
Step 3: Animate the shots
Run image-to-video on the approved keyframes. For each shot, generate three variations with slightly different motion prompts and pick the best. Keep the losers — a rejected take often becomes a cutaway or a B-roll insert later.
Step 4: Assemble and edit
Import everything into a non-linear editor. Cut on motion. Trim hard. AI clips often have strong middles and weak edges, so expect to cut the first and last half-second off many takes. Use transitions sparingly; a simple cut hides generation seams better than a dissolve that draws attention to them.
Step 5: Repair and finish
This is where AI video becomes real video. Stabilise shaky outputs, retime clips to match pacing, add speed ramps, mask out artifacts with clean plates from other takes, and grade everything to a single look. A unified grade is the most effective way to make clips from four different models feel like one film.
Step 6: Sound design
Audio is not optional. Room tone, foley, and a music bed transform perceived quality more than another ten hours of rendering. Generate or record voiceover first, then cut picture to the voice, not the other way around.
Keeping Characters and Locations Consistent Across Shots
Consistency is the hardest problem in AI video and the main reason projects collapse into incoherence. Four tactics in combination solve most of it.
Reference locking. Use the same reference image for every shot featuring a character. Some models accept multiple reference images; supply front, three-quarter, and profile views.
Wardrobe rules. Describe clothing in identical wording every time. Change one word and the model changes the jacket.
Location anchors. Keep a distinct architectural or lighting feature in frame — a particular window, a specific wall colour. Models drift less when a scene has a recognizable landmark.
Shot-size discipline. Avoid extreme close-ups of faces early in a project. Medium shots are more forgiving and give viewers enough context to accept minor variation.
If a character still drifts, switch strategy: cover the scene with a body double, silhouettes, over-the-shoulder framing, or hands and objects. Restriction breeds style — many acclaimed AI shorts hide identity entirely and are stronger for it.
Working With Open-Weight Models Without a Data Center
Self-hosting sounds intimidating, but the practical setup is simpler than it was even recently. Two viable routes exist.
Rented GPUs. Hourly cloud GPU instances let you run open-weight models without buying hardware. You pay for what you render, you control the environment, and you can shut it down between sessions. Good for intermittent project work.
Local workstation. A modern consumer GPU with generous VRAM handles quantized versions of video models at lower resolutions. Render at 480p or 720p, then upscale. This is slower but costs nothing per shot and keeps everything private.
Practical tips for either route:
- Start with a distilled or low-step variant. They render many times faster and are surprisingly close in quality for stylised content.
- Batch your generations. Loading a model into memory is the expensive part; producing ten clips in one session is far more efficient than ten separate runs.
- Keep a fixed seed library for recurring characters and locations. Seeded reproducibility is something hosted tools rarely expose as cleanly.
- Upscale and interpolate in post rather than pushing the model to higher resolutions.
Common Mistakes That Kill Flexibility
Single-tool dependency. If your entire project lives in one generator, a policy change, outage, or model update can strand it. Keep keyframes and project files portable and model-agnostic.
Over-prompting. Five stylistic modifiers fight each other. Two or three deliberate choices beat a sentence stuffed with adjectives.
Chasing length. Long single generations drift, morph, and invent new characters. Short shots edited together look better and are easier to repair.
Skipping keyframe approval. Animating an unapproved still wastes the most expensive resource you have: render time.
Ignoring aspect ratio. Generate in the ratio you will deliver. Cropping a 16:9 clip to vertical destroys framing and cuts off faces.
No sound pass. Silent AI video reads as a technical demo. Sound makes it read as a film.
Ignoring the grade. Mixed model outputs have mixed colour science. A single grade with matched contrast and white balance is the fastest quality upgrade available.
Policy, Copyright, and Platform Reality
Creative latitude is not the same as legal latitude, and this distinction matters most when money is involved.
- Read the terms for your specific plan. Commercial use, output ownership, and training-data clauses differ between free, professional, and enterprise tiers, and they change without much fanfare.
- Avoid protected characters, logos, and living people's likenesses. Beyond legal risk, most platforms filter them anyway, and a filtered shot mid-project is a scheduling disaster.
- Check distribution rules. Many social platforms now require disclosure of synthetic media, particularly for realistic depictions of people. Disclose it; audiences rarely punish honesty and frequently punish the opposite.
- Keep records. Save prompts, seeds, model versions, and source references per shot. If a client asks how a frame was made, you want the answer in a folder, not in your memory.
Open-weight models shift some of this responsibility to you rather than removing it. Self-hosting gives you control over filters, which means the ethical decisions become yours to make deliberately.
FAQ
Is there a model that will generate literally anything?
No hosted service operates that way, and open-weight models still reflect their training data and licence terms. The practical version of "unrestricted" is a pipeline with many options and few dead ends.
Which model is best overall?
Whichever one finishes your current shot. For realism, hosted flagships lead. For control, specialists. For privacy and unlimited iteration, open weights.
How do I keep a character consistent across twenty shots?
Lock a reference image, keep wardrobe descriptions word-for-word identical, use the same seed family where available, and stay in medium shots. Consistency is a system, not a prompt.
Can I mix models in one project?
Yes, and you probably should. Match the grade and sound design across clips and audiences will never notice the seams.
What hardware do open-weight models need?
A modern GPU with substantial VRAM for local work, or a rented cloud instance. Render at reduced resolution and upscale in post.
How long should each generated shot be?
Four to eight seconds. Short generations keep motion coherent, give you more editing control, and make regeneration cheap.
Do I need a video editor if I use AI generators?
Absolutely. Cutting, stabilising, retiming, masking, grading, and sound design are where AI clips become watchable video.
Building a Pipeline That Outlives Any Single Model
Models will keep changing. Names will shift, capabilities will blur, and whatever leads today will look dated soon enough. What survives is architecture: a keyframe-first approach, short generations, portable project files, a fixed grade, and disciplined sound design.
Build that pipeline once and every new model becomes an upgrade rather than a migration. You will evaluate releases by one question — does this improve a specific stage of my workflow? — instead of rebuilding your process around whichever tool happens to be trending.
Start small. Take one thirty-second scene, run it through the full pipeline from shot list to sound pass, and note where you lost the most time. That bottleneck is your next investment: a better keyframe model, a faster specialist for drafts, or an open-weight setup for volume and privacy. Flexibility is not a feature you buy. It is a habit you build, one reversible decision at a time.
