
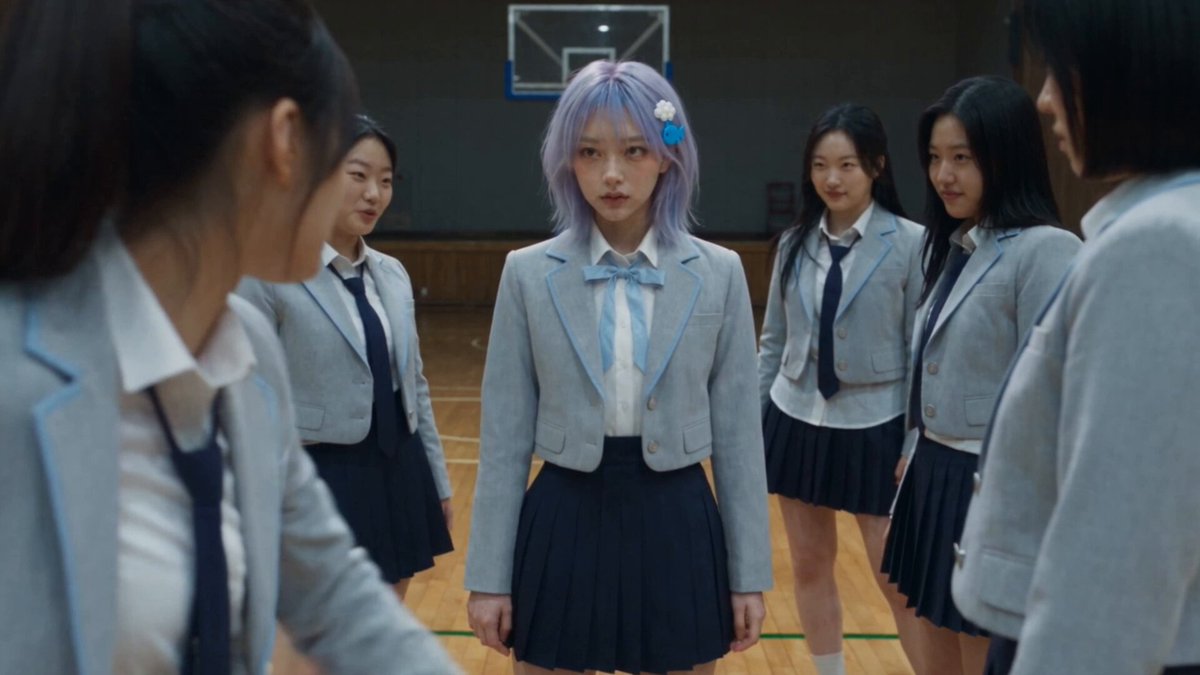
Why Anime Art Generation Became a Production Skill
Anime-style illustration used to sit behind a steep gate: years of line practice, an instinct for cel shading, and the patience to redraw a face until it reads correctly at thumbnail size. Generative models changed the economics of the first draft. A character concept that once took a full day to block out can now be explored in twenty directions before lunch, and the artist's job shifts from rendering every line to directing, selecting, and correcting.
That shift is not a downgrade. It changes where the skill concentrates. The people getting the best results from anime image models are rarely the ones typing the longest prompts. They are the ones who can look at a grid of outputs and say precisely what is wrong: the eyes sit too far apart, the shading is muddy along the jaw, the silhouette collapses when scaled down. Model steering rewards visual judgment more than vocabulary.
This guide walks through a complete workflow for generating anime art with AI and then pushing it into motion. It covers how the underlying models behave, how to choose between tools, how to structure prompts so results repeat, how to keep one character recognizable across dozens of images, and how to catch the failures that make AI art look like AI art.
What Actually Happens Inside These Models
It helps to have a rough mental model before touching a prompt box. Most anime image generation today runs on diffusion: the system starts from noise and progressively denoises it, guided by a text encoder that converts your description into a numerical direction. Style, then, is not a single switch. It is the accumulated result of many small conditioning signals.
Text conditioning and style tokens
Words like cel shaded, thick lineart, 90s TV animation, or soft airbrushed shading push the denoiser toward different visual distributions. This is why generic prompts produce generic art. "Anime girl" gives the model almost nothing to work with and it defaults to the average of its training set — usually a glossy, slightly plastic look with generic lighting.
Reference and structure conditioning
Text alone cannot guarantee a pose, a silhouette, or a specific face. That is where structural conditioning comes in: pose skeletons, depth maps, edge maps, and character reference images. A depth map can lock a composition while your prompt changes the outfit. A character reference can hold facial identity while your prompt changes the camera angle. Structure conditioning is the difference between a lucky image and a repeatable one.
Fine-tuned styles and small adapters
Lightweight adapters trained on a narrow set of images can teach a base model a specific line weight, palette, or eye style without retraining the whole network. If you find yourself writing the same forty words of style description in every prompt, that is a signal an adapter would serve you better.
The video side
Once a still exists, image-to-video models handle motion. They read the frame as a starting condition and generate a short sequence, keeping the character anchored while animating hair, cloth, camera drift, or ambient effects. Motion models are far more sensitive to input quality than still models. A slightly broken hand that nobody notices in a still becomes an obvious disaster after three seconds of movement.
Choosing the Right Tool for the Job
There is no single best anime generator. There are tools optimized for different bottlenecks. The honest decision framework is to identify which bottleneck is costing you the most time.
| Bottleneck | What to look for | Typical approach |
|---|---|---|
| Idea exploration | Fast iteration, low friction, wide variety | Hosted text-to-image tools with simple prompt boxes |
| Style precision | Structural conditioning, adapters, seed control | Node-based pipelines with pose and depth inputs |
| Character consistency | Reference conditioning, saved character profiles | Pipelines with identity conditioning plus a fixed seed plan |
| Production resolution | Tiled upscaling, face restoration, detail passes | Dedicated upscaler plus a final cleanup pass |
| Motion | Image-to-video with strong first-frame adherence | Short clips, then edit and assemble |
Large cloud providers have also pushed general-purpose image models toward stylized illustration, and Tencent's generative research is part of that broader wave — hosted, API-accessible models that anyone can call. The practical takeaway for a creator is not brand loyalty but access: a hosted model with a clean API removes the setup cost of running local inference, while local pipelines give you control a hosted endpoint will not.
If you are producing a single illustration, a hosted generator is usually fastest. If you are producing a consistent series — a comic, a short film, a channel identity — invest early in a pipeline you control, because reproducibility matters more than any single output.
A Step-by-Step Anime Art Workflow
The following sequence works whether you are using a hosted web tool or a local node graph. The order matters more than the specific software.
Step 1: Define the shot, not the vibe
Write one sentence describing what the image must communicate. Not "cool anime warrior" but "a lone swordsman at the edge of a rain-soaked rooftop, seen from below, looking at something out of frame." Shot type, subject, environment, and emotional beat. Everything downstream is easier when the intent is already clear.
Step 2: Collect two or three style references
Pick references for different reasons: one for line weight, one for color temperature, one for lighting logic. Do not describe them in words first — look at them, then write only what they have in common. "Ink-heavy lineart, muted teal palette, hard rim light from the left" is a much stronger instruction than a paragraph of adjectives.
Step 3: Write a structured prompt
Use consistent field order so you can change one variable at a time. A reliable order is: subject and action, character details, environment, lighting, style descriptors, composition and camera, output format notes. Changing field order between runs makes debugging impossible, because you never know which change caused the shift.
Step 4: Generate broadly, then cull hard
Run four to eight images, not forty. Cull to keep only compositions that work if you squint. If nothing survives the squint test, the prompt is the problem, not the seed. Fix the prompt before you spend time on volume.
Step 5: Lock structure, then vary style
Once a composition works, capture its structure — pose, depth, or edges — and reuse it while changing palette, outfit, or lighting. This is how you build a coherent set instead of a folder of unrelated images.
Step 6: Fix the small anatomy problems early
Anime models are forgiving about stylization and unforgiving about hands, hands holding objects, ears, and hair strands crossing the face. Repair these before upscaling. Inpainting a hand at 1024 pixels takes two minutes; fixing it after you animate is much harder.
Step 7: Upscale with intent
A tiled upscaler plus a light detail pass at low strength is usually enough. Push detail strength too high and skin develops a crunchy, over-sharpened texture that reads as artificial. Detail should be visible at 100% zoom and invisible at thumbnail size.
Step 8: Prepare for motion
The final still should be clean, high-contrast, and simple in the areas that will move. Overly busy backgrounds make motion models hallucinate. If a scene will animate, simplify the background during generation rather than fixing it afterward.
Prompt Anatomy for Anime Styles
A useful anime prompt behaves like a shot list rather than a poem. Seven fields cover almost everything:
- Subject and action — who, doing what, facing which way.
- Design details — hair shape, eye style, outfit silhouette, accessories.
- Environment — location, weather, time of day, background complexity.
- Lighting — key direction, rim light, color of shadows, contrast level.
- Rendering style — line weight, shading model, level of detail, palette.
- Camera and composition — framing, angle, focal length feel, negative space.
- Constraints — what to avoid: extra fingers, text, watermark, cluttered background.
Two practical habits make this far more effective. First, keep a personal snippet library of style descriptions that have worked and paste them verbatim instead of rewriting from memory. Second, change exactly one field per experiment. Creators who change five things at once and get a better image learn nothing they can reuse.
Negative constraints deserve their own note. Generic negative lists are weak. If a specific failure keeps appearing — hair merging into a dark background, or a shirt shading into the same value as the skin — add a targeted constraint addressing that exact overlap.
Keeping a Character Consistent Across Many Images
Consistency is the hardest part of any multi-image project, and it breaks in predictable ways: the face drifts, the outfit morphs, the proportions change between full-body and close-up shots.
A workable method has four layers. First, write a character sheet in plain text — age range, face shape, eye color and shape, hair length and parting, signature outfit, distinguishing marks — and reuse the same wording every time. Second, keep a fixed seed or identity reference so the model starts from a similar region of its output space. Third, generate a small reference set of the character from five angles and keep those images as inputs for later scenes. Fourth, accept controlled variation: lighting and pose should change scene to scene, but silhouette landmarks should not.
It also helps to define what you will not change. Nose shape and jawline are the two features audiences read fastest for identity. If those drift, the character looks like a different person even when the outfit is identical.
From Still to Motion: Animating Anime Frames
Image-to-video has become genuinely usable for anime-adjacent work, with one major caveat: short clips succeed, long clips compound errors.
Start with three to four second shots. Describe only the motion you need — hair moving in wind, slow camera push-in, cloak fluttering, rain falling. Resist listing ten simultaneous motions; each one competes for the model's attention and increases the chance that the character's face warps.
A few field-tested practices:
- Keep the face still if you can. Head turns are the most common source of identity loss. Let the body and background carry the motion.
- Match motion to the frame's composition. A wide shot tolerates camera drift; a close-up does not.
- Generate more than you need and cut ruthlessly. Sixty percent of clips will have a usable three seconds inside them.
- Stabilize in editing, not in the model. Adding a subtle push or drift in your editor is cleaner than asking the model for a complex camera move.
- Keep aspect ratio consistent. Mixing ratios mid-sequence forces awkward crops and breaks character framing.
When a clip fails — face melting, limbs duplicating, background crawling — the fix is usually to simplify the input frame rather than change the motion prompt.
Quality Control Checklist Before You Publish
Run every image and clip through the same checklist. The failures that damage credibility are consistent across projects.
- Hands and fingers — count them, check joint direction, check objects being held.
- Eyes — both looking the same direction, same size, pupils aligned with the light source.
- Feet and ground contact — characters should not float or sink.
- Hair edges — no merging into similarly-valued backgrounds.
- Shading direction — shadows should agree with the stated key light.
- Line weight consistency — no single area rendered in a completely different drawing style.
- Text and symbols — remove any invented lettering; models produce decorative nonsense.
- Thumbnail test — squint or scale down. If the silhouette is mud, the image is not finished.
Common Mistakes and How to Avoid Them
Overloading a single prompt. Ten style adjectives fight each other. Three targeted ones reinforce each other.
Skipping structure conditioning. Without pose or depth control, every generation is a lottery. Free variation is fine for exploration and expensive for production.
Fixing problems at the wrong resolution. Repair anatomy at working resolution, then upscale. Inpainting after upscaling wastes time and produces seams.
Upscaling too aggressively. More detail is not better detail. Over-sharpened faces read as artificial and lose the clean flatness that defines the style.
Animating a weak still. Motion amplifies flaws. If the still has a broken hand, the clip will have a broken hand for its entire duration.
Ignoring color consistency across a set. Build a small palette reference and grade your final images toward it, in the same way you would for a photo series. This single step does more for a cohesive look than any prompt tweak.
Frequently Asked Questions
Do I need a powerful computer to make anime art with AI?
No. Hosted generators run entirely in the browser. Local pipelines offer more control and cost nothing per run, but they need a capable GPU and some setup patience. Many creators start hosted and move local only when consistency becomes a recurring problem.
Can AI anime art be used commercially?
It depends on the model's license and your jurisdiction. Read the terms of the specific model you use, keep records of your generation process, and treat the output as a draft that you substantially shape. Your own editing, compositing, and layout work is often what makes a piece defensibly yours.
How do I stop characters from looking different in every image?
Use a written character sheet, a fixed identity reference, and a consistent seed strategy. Then test the character from five angles before committing to a full scene.
How long should AI animation clips be?
Three to four seconds per shot is the practical sweet spot. Assemble longer sequences in your editor from multiple short, reliable clips rather than generating one long shot.
Should I learn prompt engineering formally?
Learn prompt structure rather than a list of magic words. Consistent field order, one-variable-at-a-time testing, and a personal snippet library will outperform any copied prompt list.
Why do my images look generic?
Usually because the prompt describes a category rather than a specific moment. Add a camera angle, a lighting direction, an emotional beat, and a concrete environment. Specificity is what separates a striking image from a stock one.
Turning the Workflow Into a Habit
The tooling in this space changes quickly, but the workflow does not. Decide the shot, gather references, write a structured prompt, cull hard, lock structure, repair anatomy, upscale with restraint, then animate only the frames that survive scrutiny. Each step is cheap on its own; skipping one is expensive later.
If you take only one thing from this guide, make it the discipline of changing one variable at a time. That habit converts AI anime generation from a slot machine into a craft you can actually direct.
