
Why Free AI Video Generation Finally Became Practical
Video is the most demanding format on the internet, and for years the gap between wanting to publish it and being able to produce it was enormous. A short clip meant a camera, lighting, a quiet room, a performer, and hours in an editor. Free AI video tools did not close that gap overnight, but they have now closed enough of it that one person can ship a polished sixty-second piece in an afternoon.
Three developments made this practical.
Model efficiency. Video models are far more expensive to run than image models because they predict many frames instead of one. Distillation, smarter sampling schedules, and quantized inference have pushed the cost of a few seconds of generated footage down to something a free tier can realistically absorb.
Layered pipelines. Instead of one enormous model doing everything, modern tools chain smaller specialists: a scripting assistant, an image generator, a motion model, an upscaler, a speech synthesizer. Each layer is cheap alone, and the tool only pays for the layers you actually invoke. That composition is what makes a generous free tier economically survivable.
Open research and shared weights. Publicly released model families gave smaller products something strong to build on, so the quality floor rose everywhere at once. A weekend project can now produce footage that would have looked professional a few years ago.
The upshot: free access is no longer a novelty tier. It is a genuine on-ramp — with conditions attached.
What "Free" Actually Means in Practice
Before committing to any tool, read the fine print on four axes. They determine whether a free tier is a sandbox or a real production option.
Render allowance. Most free tiers cap you by minutes per day, seconds per generation, or a queue priority system. A tool that gives you ten seconds per clip is fine for social cutdowns and terrible for a five-minute explainer. Check whether the cap resets daily, monthly, or never.
Watermarks and attribution. Some tools watermark every export until you upgrade. Others watermark only lower resolutions, which is a workable compromise: draft freely, then produce the final at a paid resolution. Know which one you are dealing with before you storyboard around a look you cannot export.
Commercial rights. This is the clause people skip. Some free tiers restrict output to personal or non-commercial use, or require attribution in the description. If you are producing for a client, that restriction can invalidate the whole deliverable.
Data and training terms. Ask whether your prompts and uploaded images may be used to improve the service. For personal experiments it rarely matters. For unreleased product photography or a client's brand assets, it matters a great deal.
A useful mental model: treat free tiers as your pre-production and pitching environment, and treat paid access as the finishing room. If a project needs broadcast-safe output, licensed music, and a clean file, budget the paid path from day one instead of discovering the limitation at export.
The End-to-End AI Video Workflow
The biggest mistake beginners make is opening a generator first. Generation is step three, not step one. Here is a workflow that survives contact with real deadlines.
Step 1: Write the script before you touch a generator
Generation is cheap; revision is not. Write the script as plain text, read it aloud, and cut anything that does not earn its place. Sixty seconds of finished video is roughly 130 to 160 spoken words. Knowing that number keeps you honest.
Mark each line with its purpose: hook, context, proof, payoff, call to action. If a line does not map to one of those, delete it. Scripts written for video also need shorter sentences than written articles, with deliberate pauses where a visual will carry meaning.
Step 2: Build a shot list and storyboard
Convert the script into shots, one per beat. A sixty-second piece typically needs ten to sixteen shots; fewer if shots are long and atmospheric, more if you are cutting fast for social. For each shot, write one sentence describing subject, action, framing, and lighting.
Then decide how each shot will be produced. Some shots are generated. Some are screen recordings. Some are stills with slow zooms. Some are simple text cards. Mixing these sources is normal and keeps the generation budget for the shots that truly need it.
Step 3: Generate assets in batches
Generate more than you need. Models are non-deterministic, so the same prompt produces different results each run. Produce three or four variations per shot, name files by shot number, and keep a simple spreadsheet mapping shot to prompt so you can regenerate later without guessing.
Generate your hardest shots first. If a specific camera move or character interaction refuses to cooperate, you want to learn that early, while you still have room to rewrite the shot list.
Step 4: Assemble in an editor, not in the generator
Most generators are poor editors. Export clips and bring them into a real timeline where you can trim, control speed, add transitions, and layer graphics. This separation also protects you: if you switch tools next month, your edit survives.
Step 5: Layer audio deliberately
Build audio in three layers: a music bed, a voice track, and spot effects. Music first sets the pacing. Voice next tells you where the music must duck. Effects last, used sparingly to sell transitions and actions.
Step 6: QA and export
Watch the full piece once with your eyes closed. Listen for level jumps, clipped words, and a music bed that overwhelms speech. Then watch it muted to confirm the story reads visually. Finally, export two versions: a high-quality master and a compressed social cutdown.
Generation Modes Compared
Free tools typically expose several modes. Choosing the right one saves more time than any prompt trick.
| Mode | Input | Best for | Watch out for |
|---|---|---|---|
| Text to video | Prompt only | Abstract visuals, establishing shots, mood | Weak subject consistency across shots |
| Image to video | Still plus prompt | Product shots, characters, brand assets | Motion can look rubbery if the prompt is vague |
| Video to video | Existing clip plus prompt | Restyling, upscaling, converting live action to animation | Source artifacts get amplified |
| Keyframe driven | Start and end frames | Precise transitions, before-and-after reveals | More setup per clip |
As a rule, start from an image whenever the shot contains a specific subject you must keep consistent. Use text-to-video for atmosphere and backgrounds, where small variations between shots read as intentional texture rather than error.
Prompting for Motion, Not Just Stills
Image prompts describe what is in frame. Video prompts must also describe what changes. That single distinction fixes most disappointing output.
Structure a video prompt in four parts:
- Subject — who or what, with two or three concrete details.
- Action — a single continuous movement, described in the present tense.
- Camera — static, slow push in, tracking left, handheld, drone reveal.
- Look — lighting, palette, film stock, lens character.
One action per clip. If you ask for someone walking, turning, and opening a door, the model will average those into mush. Split into three shots and cut them together; the edit will look more intentional than a single overloaded generation.
Camera language carries surprising weight. Words like slow, subtle, drift, and ease produce calmer motion. Words like whip, snap, and crash produce instability that often reads as artifact rather than energy. When a clip looks broken, the camera term is usually the culprit.
Negative guidance helps too: no text, no logo, no extra limbs, no distorted faces. Keep the list short. Long negative lists cause models to drift toward the very thing you are excluding.
Keyframes, Continuity, and Character Consistency
Consistency is the hardest problem in AI video, and it is where free tiers show their limits. Three techniques buy you a lot.
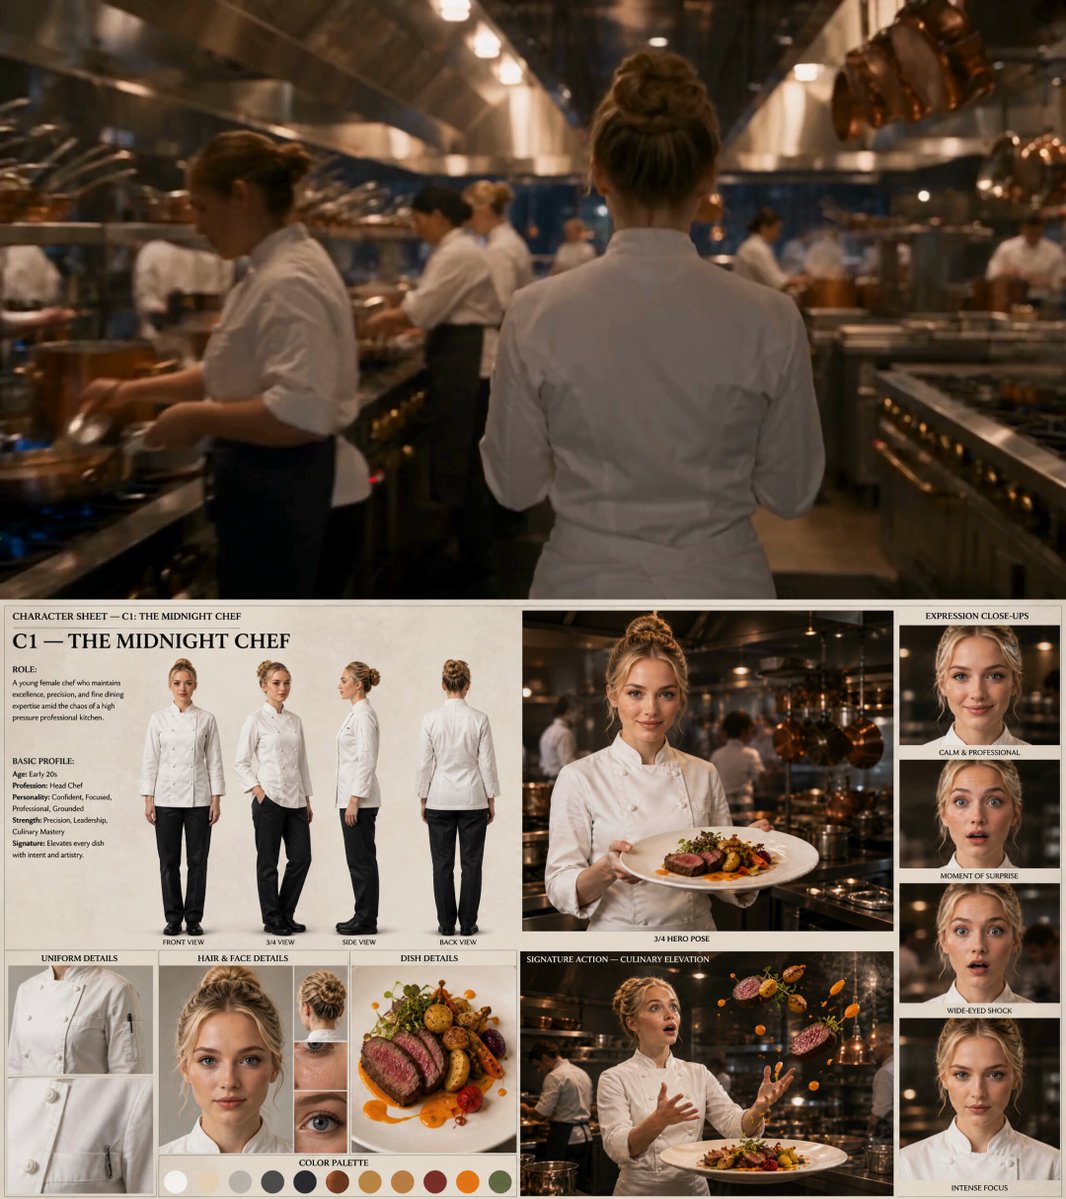
Lock a reference image. Generate one strong image of your subject and reuse it as the starting frame for every shot they appear in. This is the single highest-leverage habit in the entire workflow.
Vary the shot, not the person. Instead of asking a model to reinvent your character in a new pose, change the framing: wide, medium, close, over-the-shoulder. The subject stays the same because the source image stays the same.
Design around cuts. If two shots cannot match, put a cut between them rather than a continuous move. Audiences accept cuts. They notice continuity errors.
Do not show the face if you do not need it. Hands, silhouettes, back-of-head shots, and environmental inserts are cheap, consistent, and often more cinematic than a shaky generated close-up.
For longer pieces, maintain a continuity sheet: wardrobe, hair, key props, time of day, and color temperature. It takes ten minutes and prevents the most common revision request.
Audio, Voice, and Lip Sync
Audio is where amateur AI video gives itself away. Visual oddities are forgiven; bad sound is not.
Synthesized voice works best when you write for it. Short sentences, natural contractions, and explicit pauses outperform long flowing prose. Generate line by line rather than as one block, so you can regenerate a single bad take without redoing the whole read. Keep a consistent voice across the project and resist the temptation to switch voices mid-piece for variety.
Music selection matters more than music quality. Match tempo to edit rhythm: roughly 90 to 110 beats per minute for calm explainers, 120 and up for energetic social content. Duck the bed by six to ten decibels under speech, and use a gentle sidechain rather than hard volume automation.
Lip sync is the least reliable component of free tooling. If accuracy matters, favor shots where the mouth is small in frame, partially turned away, or covered. Voiceover over b-roll is almost always a safer choice than a close-up talking head generated on a free tier.
Choosing a Tool: Decision Criteria
Feature lists are marketing. These questions are practical.
What is the failure mode? A tool that occasionally produces beautiful output but fails unpredictably is worse for deadlines than a predictable tool with a lower ceiling. Test with five prompts before you commit a project.
How fast is iteration? Speed of revision beats quality of first attempt. If a small prompt change takes ten minutes to render, your workflow will stall.
Can you export cleanly? Check resolution, frame rate, codec, and whether alpha channels or separate audio tracks are available. A beautiful clip you cannot composite is useless.
Does it fit your editor? Direct export to common formats and resolutions saves an entire conversion step.
What does the upgrade path look like? You want a tool where the skills transfer. Prompting technique, shot planning, and reference-image discipline carry across every platform; interface familiarity does not.
A reasonable stack for a solo creator is one generalist generator for most shots, one image tool for reference frames, one speech synthesizer, and one editor. Fewer tools, deeper familiarity.
Common Mistakes and How to Fix Them
Generating before scripting. Fix: write the script first, always. It is the cheapest step and the one that saves the most renders.
Overloading single prompts. Fix: one action, one camera move, one clip. Cut the results together.
Ignoring aspect ratio. Fix: decide vertical, square, or widescreen before generating. Cropping a widescreen composition to vertical destroys framing that took effort to build.
Chasing perfection on free tiers. Fix: accept eighty percent and fix the rest in the edit. A slightly imperfect clip cut on the beat often outperforms a clean clip that does not fit the rhythm.
Skipping audio until the end. Fix: lay a scratch voice track early. It changes how long your shots need to be and prevents re-rendering everything at the finish.
No naming convention. Fix: name files by project, shot, and version. Future you will be grateful.
FAQ
Can I really produce commercial work with free tools? Sometimes, but verify the license on every tool you use. Many free tiers allow commercial output with attribution; others restrict it. When a client deliverable is involved, read the terms and consider upgrading for the finishing pass.
How long does a one-minute video take? With a finished script, expect two to four hours for a simple piece and a full day for something with character consistency and custom audio. Most of the time goes to shot selection and editing, not generation.
Why does my character change between shots? Because each generation starts fresh. Lock a reference image, reuse it as the starting frame, and vary the camera rather than the subject.
What if a clip looks distorted? Simplify the prompt, remove aggressive camera terms, shorten the clip duration, and regenerate. Motion artifacts usually come from asking for too much change in too few frames.
Do I need to learn prompting deeply? You need to learn structure: subject, action, camera, look. Beyond that, iteration teaches more than theory. Keep notes on what worked and build your own prompt library.
Bringing It Together
Free AI video generation is genuinely useful now, but it rewards planning rather than enthusiasm. Script first. Storyboard second. Generate in batches with reference images. Assemble in a real editor and spend disproportionate effort on audio. Treat free tiers as your development environment and reserve paid finishing for the moments that need a clean, licensed, watermark-free export.
Start with a thirty-second project. Pick one topic you already understand, write 80 words, break it into eight shots, and take it all the way to a final export. The workflow lessons from that one small piece will teach you more than any feature comparison, and you will know exactly which tool to reach for the next time.
