
A viewer forgives a soft background, a blurry extra, a lighting shift between takes. What they do not forgive is the hero of the story changing faces between the third shot and the fourth. In AI video generation that is the most common reason a promising multi-scene project falls apart: each clip looks excellent on its own, yet the sequence feels like a casting accident. Multi-image fusion is the practice that solves it — not by luck, but by deliberately supplying several reference images of the same character and controlling how that identity travels into every new shot.
This guide walks through how the technique works, how to prepare a reference set, how to anchor scenes with keyframes, and how to debug drift when it inevitably appears.
Why Character Consistency Decides Whether a Multi-Scene Video Works
Raw visual quality stopped being a differentiator a while ago. Most current video models produce crisp, plausible frames; the gap between them shows up in continuity, not in resolution. An audience tracks a character by a handful of anchor features — face shape, hairline, eye spacing, skin tone, a signature garment — and the moment two of those anchors disagree between shots, the viewer's brain registers 'different person' and the story breaks.
That has practical consequences. A brand spot with a recurring spokesperson loses its authority if the spokesperson morphs. A serialized short-form series loses its returning audience if the protagonist is unrecognizable in episode two. A product demo with a consistent human guide builds trust faster than an anonymous voiceover, because repetition is what makes a face feel familiar.
Consistency also changes how you budget time. Teams that treat each shot as an isolated generation spend most of their editing hours on repair: regenerating, masking, blending, or quietly abandoning shots. Teams that treat the whole sequence as one identity pipeline spend those hours on storytelling instead. The difference is rarely the model. It is the workflow wrapped around the model.
How Multi-Image Fusion Actually Works
Instead of describing your character in words and hoping the model lands on the same face twice, multi-image fusion gives the model actual pixels to match. You supply a small set of photographs or renders of the same person from different angles, with different expressions, under different light. The system extracts a compact representation of that identity — geometry, texture, proportions — and applies it as a constraint whenever it renders a new frame.
Practically, two things then happen at once. The model still follows your prompt for pose, action, camera, and setting, but a separate identity signal pushes every generated face back toward the reference set. When the two signals conflict — say, the prompt asks for a dramatic upward angle while your references are all eye-level — the identity signal usually wins on structure and loses on expression. Understanding that trade-off is most of the skill.
Identity embeddings versus direct reference merging
The simpler approach blends reference images directly into the conditioning. It is fast and transparent, but gets noisy past three or four references and tends to drag background details from the references into your scene. The more robust approach distills the references into an identity embedding first, then conditions on that embedding. Embeddings are more stable across angles and harder to contaminate with background clutter, though they can flatten subtle features if your reference set is small or stylistically inconsistent.
What a strong reference set looks like
Ten to twenty images is a comfortable range. Include at least one clean frontal, two three-quarter views from opposite sides, one profile, and a mix of neutral and expressive faces. Vary the lighting — studio, daylight, warm interior — so the identity signal learns what stays constant. Avoid sunglasses, heavy shadows, extreme wide-angle distortion, and images where another person's face takes up meaningful space. Crop tightly. If a reference contains two faces, the model has to guess which one you meant, and it will sometimes guess wrong.
Building a Character Bible Before You Generate Anything
The cheapest fix for continuity problems happens before you touch a video model: write a one-page character bible. It should include a locked description of immutable features, a list of variable features, and the exact wording you will reuse in every prompt.
Immutable: face shape, eye color, hair color and length, skin tone, distinguishing marks, age range, body build. Variable: clothing, hairstyle arrangement, expression, props, injuries, dirt, weather effects.
Then write the prompt fragment you will paste into every scene. Something like: 'woman in her early thirties, oval face, dark brown eyes, straight black hair to the collarbone, warm medium skin tone, slim build.' Keep that string identical across shots. Small rewordings — 'warm medium skin tone' versus 'olive complexion' — pull the model toward different faces, and those differences accumulate over a long sequence.
Name your assets consistently too: character-a-front.png, character-a-profile-left.png, and so on. When you are forty generations deep and three characters are in play, file naming is the only thing keeping you sane. Add one line per character documenting which clips are already approved, so you always know where to pull a repair keyframe from.
Keyframes, Phases, and Motion: Keeping Faces Stable Through Movement
Identity gets hardest when the character moves. A still portrait is easy; a running figure turning away from camera is where models improvise and faces drift.
Anchor each shot with a keyframe
Generate or select a first frame for every shot that already contains your character, in the right costume, in the right environment. Then animate from that frame rather than generating from text alone. Because the opening frame is fixed, the model's job narrows to plausible motion instead of inventing a person. For shots longer than four or five seconds, add a mid-shot keyframe and split the clip into two generations; long single-pass renders are where identities degrade most.
Control motion amplitude per shot
Ask for moderate, specific actions: 'turns her head slowly to the left and smiles' beats 'moves dynamically.' Wide, fast motion forces the model into heavy interpolation, which smears facial geometry. If your scene needs a sprint or a spin, cover it with a cut — a close-up before, a wide after — and keep the character's face out of the highest-motion frames.
Hair is the classic tell. Loose long hair in wind flickers between frames; braids, tied-back styles, and short cuts render far more consistently. If your character must have flowing hair, expect to spend extra passes and consider keeping those shots short.
A Practical Multi-Scene Workflow, Step by Step
Here is a sequence that reliably produces a coherent multi-scene video without wasting generations.
- Lock the storyboard first. List every shot with a one-line description, camera angle, and costume state. Do not start generating until the list is stable; identity work is wasted on scenes you will cut.
- Assemble references. Ten to twenty images per character, cropped tightly, renamed clearly, checked for duplicate angles.
- Generate a character sheet. Produce a grid of test portraits — frontal, three-quarter, profile, smiling, serious — and pick the ones that match your intent. Regenerate until the sheet looks like one person, not five siblings.
- Render static keyframes for every shot. Approve them as stills. This is the cheapest place to catch costume and continuity errors.
- Animate shot by shot, shortest first. Short clips confirm the identity holds; only then attempt the long, complex shots.
- Check continuity at the cut. Place consecutive clips side by side and watch the transition, not the clips. Most drift is invisible inside a clip and obvious across a cut.
- Repair in isolation. When one shot drifts, regenerate only that shot using a keyframe pulled from a neighboring approved clip. Repairing one shot is cheap; re-rendering a sequence is not.
- Finish with color and grain. A light grade and consistent grain across all shots makes minor differences in skin tone and contrast read as intentional cinematography rather than model error.
The order matters. Teams that animate before approving stills pay for identity fixes twice: once in keyframes, once in motion.
Environment, Lighting, and the Same Person in a Different Room
Characters do not exist in a vacuum, and environments are a major source of accidental identity change. A character lit with warm practicals in a kitchen, then lit with cold blue window light in a bedroom, will look different even if the geometry is identical. Audiences read that as a different person unless you manage it.
Keep the direction of your key light consistent across shots in the same scene, even when the location changes. Keep skin tone rendering consistent by including a short lighting phrase in every prompt for that scene — 'soft window light from camera left' — and repeating it verbatim. If a sequence spans day and night, plan a gradual shift rather than an abrupt flip.
Watch scale, too. A character shot at 24mm looks subtly different from one shot at 85mm; distortion changes the face. Pick one focal length feel per character and stay near it, reserving wide lenses for establishing shots where the face is small and identity matters less.
Style Consistency Across Models and Renders
Mixing models inside one project is tempting — one handles crowds well, another nails close-ups — but every model has its own color science, contrast curve, and facial prior. The result is a cast that looks like it wandered in from different productions.
If you must mix, treat each model's output as raw footage and unify it in post: match black levels, apply one shared look-up table, add a grain layer, and standardize sharpness. Better still, use one primary model for all character shots and reserve others for inserts, landscapes, and effects where faces are absent or tiny.
Style consistency also means keeping your prompt grammar consistent. If scene one used a terse prompt and scene five used a lyrical paragraph, the renders will differ in mood even with the same references. Pick a template, fill in the blanks, and resist rewriting it from scratch each time.
Common Failure Modes and How to Fix Them
The face drifts mid-clip. Usually motion amplitude, clip length, or a weak reference set. Shorten the clip, lower the motion intensity, add a mid-shot keyframe, and add three or four more reference images shot from angles similar to the camera position.
The character ages or de-ages between shots. Your prompt wording for age is inconsistent, or your references span too wide an age range. Trim the reference set to one era and keep the age phrase identical everywhere.
Costume changes color. Colors are described with vague words like 'dark jacket.' Use specific, repeatable terms — 'charcoal wool jacket with matte finish' — and lock costume changes to explicit cuts.
The face is right but the hair is wrong. Hair is the least stable feature. Specify style, length, and whether it is tied or loose, and prefer tied styles for action shots.
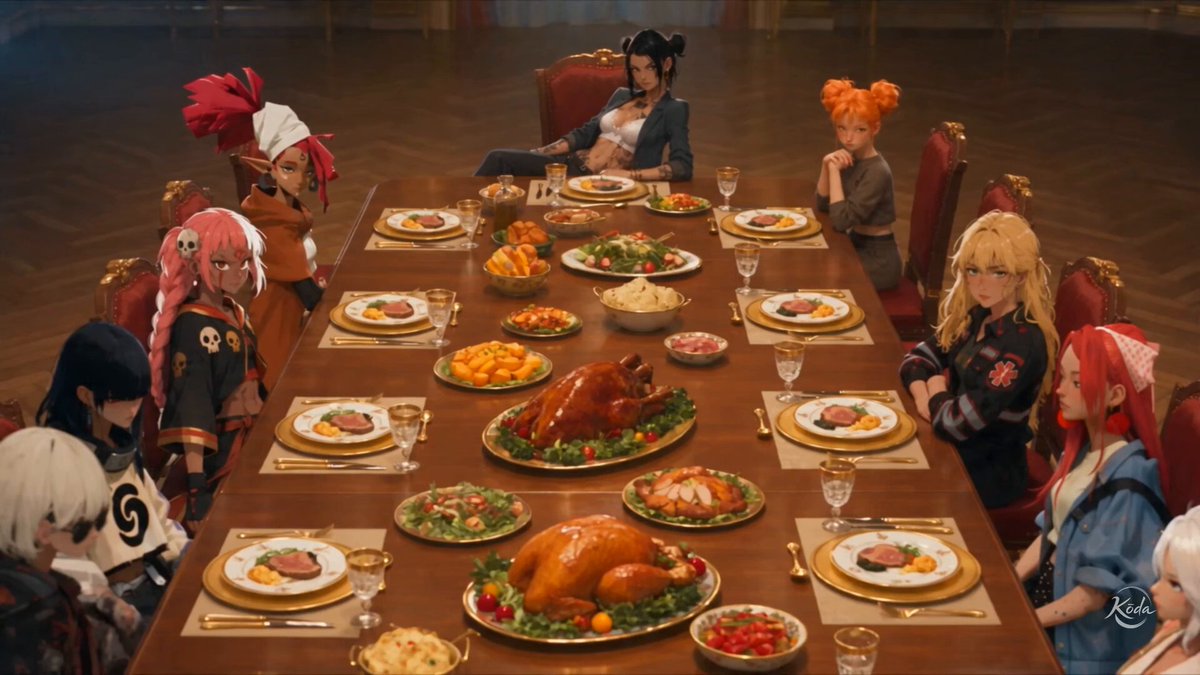
Two characters swap traits. With multiple people in frame, identity signals blur. Render them in separate shots when possible; if they must share a frame, keep them at different depths or angles so their faces are not adjacent at similar size.
The background person has a melting face. Background figures receive less model attention. Keep crowds out of focus, keep them small, or shoot around them entirely.
Everything looks fine but feels off. This is often frame rate or motion cadence rather than identity. Standardize clip frame rates before editing and avoid mixing 24fps and 30fps inside one scene.
A Quality-Check Pass Before You Publish
- Does the character's face hold at every cut, watched at normal speed rather than frame by frame?
- Is skin tone consistent across locations, and does it match the intended grade?
- Are hairline, eye color, and brow shape stable in close-ups?
- Do costume details — buttons, collars, jewelry — match between adjacent shots?
- Do reflections, mirrors, and screens show the correct face?
- Does the character's height relative to the environment stay plausible?
- Does the sequence survive watching on a phone screen at small size?
If a shot fails any of these, fix it before moving on. Continuity errors compound: one accepted mismatch tells you nothing, but five accepted mismatches destroy the illusion and send viewers to the comments to point out the wrong face.
FAQ
How many reference images do I actually need?
Twelve to twenty is the practical sweet spot for a lead character. Fewer than six produces unstable results in profile and three-quarter views; more than thirty rarely helps unless the extra images cover genuinely new angles, lighting conditions, or expressions.
Can I keep a character consistent without training anything?
Yes. Reference conditioning and identity embeddings work without a dedicated training run, which is what makes the approach usable for short projects. Dedicated training helps most when you need one character across dozens of scenes with unusual angles or stylization.
Why does the character look right in stills but wrong in motion?
Motion forces the model to interpolate between frames, and interpolation is where identity constraints weaken. Shorter clips, lower motion amplitude, and mid-shot keyframes reduce this dramatically. Turning shots hide the face temporarily, which the model may use to 'reset' it.
Should I generate the character or use a real person as reference?
Either works. Real photographs carry richer identity detail, including asymmetries that make a face convincing. Synthetic renders give you cleaner licensing, unlimited angles, and total control over costume and expression. Many teams generate a synthetic character sheet first, then use it as their permanent reference set.
How do I handle aging a character across a long timeline?
Build two or three distinct reference sets — young, middle, old — and switch between them at explicit story beats such as a fade or a time-skip title. Gradual aging inside a single reference set confuses the identity signal and produces faces that look slightly off in every scene.
What is the fastest way to fix one bad shot?
Pull a clean frame from an approved neighboring shot, use it as the first-frame keyframe, and regenerate only that clip. Never regenerate the whole sequence to fix one moment; you will introduce new drift elsewhere and lose the shots that already worked.
Do I need different workflows for different video models?
The principles transfer; the parameters differ. Motion intensity, reference count limits, and prompt length tolerances vary between models, so keep a short notes file on what works for each one you use regularly. That file becomes the most valuable asset in your pipeline.
