
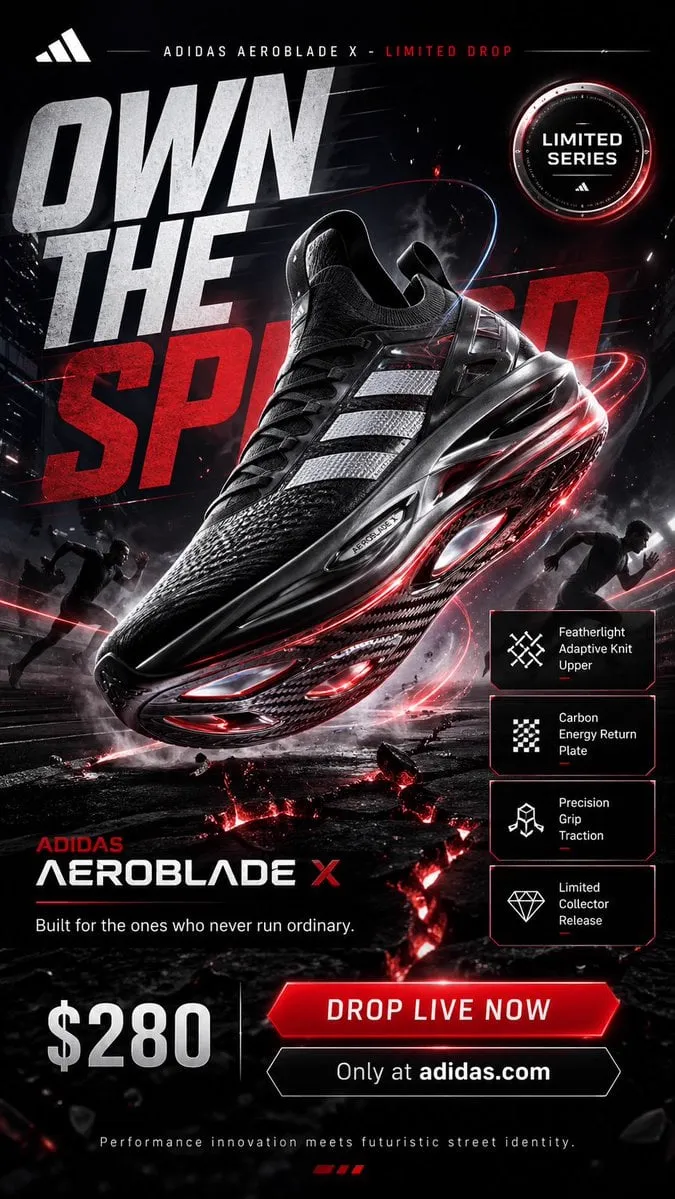
A video brand is not a logo sting at the end of a clip. It is a set of decisions — palette, pacing, framing, typography, sound — that a viewer recognizes before they read a single word. When those decisions are made once and reused across every asset, production accelerates and recognition compounds. When they are improvised video by video, every upload restarts the audience relationship from zero.
The concept-to-thumbnail pipeline is the practical system that connects an abstract idea to a finished, clickable, on-brand asset. It covers the written concept, the character and style rules, the generation approach, the cinematic polish, and finally the thumbnail that decides whether anyone watches at all. This guide walks the whole route with concrete checkpoints, tool-agnostic techniques, and the mistakes that quietly drain performance.
Why the Concept-to-Thumbnail Pipeline Decides Performance
Most teams do not have a production problem. They have a consistency problem. A single strong video with a weak thumbnail underperforms a merely decent video with a clear, branded, well-composed thumbnail — because the thumbnail is the gate. If the gate is off-message, the content behind it never gets evaluated.
The pipeline approach solves three recurring failures at once.
Failures of recall. If your vertical shorts use a cool blue grade and your long-form uses a warm amber one with different type, no viewer builds a mental file for your brand. Recall requires repetition of a small number of distinctive cues, not novelty per upload.
Failures of speed. Without a documented concept, every new video triggers the same debates: what should the character wear, what font, what aspect ratio, what hook. Those debates cost more time than rendering.
Failures of scale. AI generation makes it easy to produce forty variations and impossible to keep them coherent. A concept layer is what turns generative volume into a brand asset instead of a folder of unrelated clips.
The practical takeaway: treat branding as a specification, not a vibe. Specifications can be handed to a collaborator, a freelancer, or a model. Vibes cannot.
Step 1 — Write a Visual Concept Both Humans and Models Can Follow
Begin with a one-page visual concept. Not a mood board, not a playlist of references — a page of decisions written as plain sentences that describe what must always be true and what may vary.
A workable concept page covers:
- Core idea in one sentence. Example: a calm, documentary-style explainer hosted by a recurring narrator character in a clean studio environment.
- Palette. Two dominant colors, one accent, one neutral. Named with approximate values so a designer or a prompt can reproduce them.
- Type system. One display face for thumbnails, one text face for captions and overlays. Specify weight and casing rules.
- Framing rules. Where the subject sits, how much headroom, whether text lives left or right.
- Motion signature. One identifiable transition or camera behavior used consistently, such as a slow push-in at the start of every segment.
- Sound signature. One recurring audio element — a two-second motif, a narrator voice profile, a room tone.
Turning the concept into prompt-ready language
The concept page has a second life as a prompt library. Translate each rule into a reusable phrase: a color description, a lighting description, a lens description, a character description. Keep the phrases short, concrete, and stable. Models respond better to a consistent vocabulary than to poetic variation, and a fixed vocabulary is also what makes outputs comparable across sessions.
Deciding what is allowed to change
Explicitly list the variables: location, wardrobe within a defined range, supporting props, background music, guest characters. Anything not on the variable list is locked. This one distinction prevents the most common branding failure — a slow drift where each video is 5 percent off until the channel no longer resembles itself.
Step 2 — Lock Down Character and Style Consistency
Character consistency is the hardest technical problem in AI-assisted video, and it is also the most emotionally important. The moment a host's face, hair, or jacket changes between shots, the viewer stops tracking the story and starts tracking the error.
Three techniques carry most of the weight.
Reference-first generation. Create one canonical reference image of the character at high resolution: neutral lighting, frontal and three-quarter views, consistent wardrobe. Feed that reference into every subsequent image or video generation rather than re-describing the character in text. Text descriptions drift; images anchor.
Seed and model discipline. Record the exact model, seed, and parameter set used for the reference. If the platform supports locking a seed, do it. Changing models mid-series is the equivalent of recasting an actor between scenes.
Scene continuity shoots. Generate connected shots in the same session with the same environment prompt, then only change the action. Batch generation keeps lighting and background stable.
For style consistency at the video level, define three anchors: grade, grain, and gate. Grade is color and contrast. Grain is texture and noise level. Gate is the frame — aspect ratio, crop, and any border or safe-area treatment. If those three stay fixed, shots generated weeks apart will still cut together.
When consistency is not worth the cost
Not every format needs a recurring character. Educational clips, data visualizations, and product demos can build recognition through layout, color, and typography alone, which is far cheaper and faster. Choose the character route only when the format genuinely benefits from a human anchor — narrative explainers, commentary, serialized storytelling, or personality-led marketing.
Step 3 — Match Each Shot to the Right Generation Approach
The biggest efficiency gain in modern video work comes from not treating every shot the same way. Four approaches cover almost all needs.
Text-to-video is best for establishing shots, abstract transitions, environment plates, and anything without a specific recurring character. It is fast, flexible, and ideal for B-roll.
Image-to-video is the workhorse for character work. You control composition and identity in the still frame, then animate. This is the most reliable path to consistent performances.
Video-to-video and restyling is for transforming existing footage, matching a grade across mixed sources, or converting live-action tests into a stylized look. Useful when you already have strong performances but the wrong aesthetic.
Hybrid compositing — generating elements and assembling them in an editor — remains the most controllable option for anything with text on screen, precise product shots, or brand-critical detail. Generation handles the expensive, expressive parts; traditional editing handles the parts that must be exact.
A practical selection rule
Ask one question per shot: does the viewer need to recognize a specific person or object? If yes, generate a still first. If no, generate directly from text. This single rule reduces re-rolls dramatically, because identity-critical shots stop depending on luck.
Step 4 — Cinematic Fine-Tuning: Lens, Light, Motion, Sound
Amateur AI video tends to fail in the same four places, and all four are controllable.
Lens language. Specify focal length behavior in plain terms: a wide establishing lens with deep focus for context, a longer lens with shallow depth of field for intimacy. Mixing these deliberately creates rhythm. Using one for everything creates flatness.
Lighting continuity. Decide the time of day and light direction before generating, and keep them consistent across a sequence. Motiveless changes in light direction are the fastest way to make a scene feel assembled rather than filmed.
Motion economy. One camera move per shot. Push in, pull out, pan, or hold. Generated motion multiplies quickly into visual noise, and viewers interpret chaotic camera work as amateur production.
Sound design. Audio does more branding work than most visuals. A consistent narrator voice, a signature room tone, and a recurring two-second musical motif can make an otherwise generic clip feel unmistakably yours. Generate or record audio separately and mix it deliberately rather than accepting whatever ships with the video model.
Pacing as a brand property
Edit for a target rhythm. A common and effective pattern for short-form is a hook in the first 1.5 seconds, a context beat by second 5, a payoff at 15–20 seconds, and a call to the next action before the end. For long-form, a recognizable segment structure — cold open, title beat, three content blocks, close — does more for retention than any single visual choice. When the structure repeats, viewers know what they are getting, and predictability is a feature, not a compromise.
Step 5 — Design Thumbnails as the First Brand Touchpoint
A thumbnail is a brand impression, a promise, and a compression test of your whole visual system. It also has the strictest constraints of anything you will produce: it must survive at roughly 200 pixels wide, in a crowded feed, next to competing images designed to steal the same glance.
Six rules carry most of the results.
One idea per thumbnail. If the image requires explanation, it fails. Choose a single subject, a single emotion, and a single focal point.
Contrast against the feed. Most feeds are busy and bright. A dark, simple thumbnail with one lit subject often outperforms a colorful, detailed one. Check your thumbnail against the actual surrounding content before publishing.
Face or object, rarely both. Human faces attract attention, but only when large and legible. If the face is small, a clear object or bold shape works better.
Text as a supplement, not the message. Three to five words maximum, high contrast, generous stroke or backing plate, and readable at thumbnail scale. The text should sharpen curiosity, not restate the title.
Consistent type and placement. Same face, same weight, same corner or baseline across every upload. This is how a viewer scrolling at speed recognizes your content before reading a word.
Emotional specificity. Surprise, tension, curiosity, delight — pick one and commit. Neutral expressions read as filler.
A thumbnail test loop that takes ten minutes
Generate five thumbnail variants from the same hero frame. Scale all of them down to 200 pixels wide. Look at them with the rest of the feed blurred or visible around them. Pick the one you can identify in under half a second. Publish, then compare click-through against your channel average rather than against a single previous video. If a variant wins twice, promote its composition pattern into the brand system.
Step 6 — Adapt One Concept Across Vertical, Square, and Landscape
Reframing is not resizing. Each aspect ratio changes what the audience expects and what the composition can carry.
Vertical (9:16). Subject centered and large, minimal background information, text in the upper third, captions burned in or placed well above platform UI. Assume sound-off viewing and design the first frame as a thumbnail in its own right.
Square (1:1). Works well for feed posts, carousels, and community updates. Composition tolerates a wider subject plus a headline. Often the best format for a brand statement or a quote card.
Landscape (16:9). Allows context, multiple subjects, and on-screen graphics. Requires more deliberate pacing because the eye has more to scan. This is the format where establishing shots and wide environments pay off.
Vertical long-form and mid-roll formats. Increasingly common on mobile-first platforms. Keep the subject centered with generous headroom and never place critical text near the bottom edge.
The two-frame method for cross-platform shoots
Rather than generating separately for each platform, design a composition that works in both. Place the subject slightly off-center so a vertical crop still frames them well, keep the top and bottom of the frame free of essential information, and generate at the highest resolution you can. Crop for each platform in post. One generation, three deliverables, one consistent look.
Mistakes That Quietly Break Video Branding
Drifting visual vocabulary. Each video uses new prompt language, producing subtle style changes that accumulate. Fix: freeze the prompt library and version it.
Over-branding. Intros longer than three seconds, watermarks over faces, logo animations on every cut. Branding should be present, not obstructive.
Inconsistent captions. Different fonts, positions, and casing per video. Captions are the most-seen element on silent autoplay, so they carry disproportionate brand weight.
Ignoring the first frame. On most platforms the first frame is a de facto thumbnail. Export it intentionally instead of letting the editor choose.
Chasing every trend with the whole identity. Trends are useful for format and pacing. Letting them rewrite your palette and type system every month destroys recall.
No measurement. Without tracking click-through, average view duration, and returning-viewer share, you cannot tell whether a branding change helped. Pick three metrics and watch them per format.
A Production Rhythm That Keeps Quality Stable
Consistency comes from cadence more than from talent. A workable weekly rhythm looks like this.
- Concept session (30 minutes). Choose topics, write one-line concepts, confirm they fit the locked visual system.
- Script and shot list (60–90 minutes). Break each video into 6–12 shots with a stated purpose per shot.
- Batch generation (2–3 hours). Generate all stills first, then animate. Batching keeps style stable and reduces context switching.
- Assembly and sound (1–2 hours). Cut to the pacing template, lay in narration and music, add captions.
- Thumbnail pass (30 minutes). Produce five variants, test at small size, pick one.
- Adaptation pass (30 minutes). Crop and re-export for each platform, check safe areas.
- Review (20 minutes). Record metrics from last week's posts and note one change to test.
The rhythm matters more than the exact hours. What breaks brands is not a slow week — it is an inconsistent one, where a rushed upload ships with off-system type and a random grade.
FAQ
How many visual rules should a brand system contain?
Fewer than you think. Five to seven locked rules are enough to create recognition: two colors, one accent, one type pair, one framing convention, one motion signature, one audio motif. Systems with thirty rules collapse under their own weight because nobody can apply them consistently.
Do I need a recurring character to build a recognizable video brand?
No. Character-led branding is powerful for narrative and commentary formats, but layout, color, typography, and pacing can carry recognition in tutorials, product content, and data-driven videos. Choose the character route only when a human presence genuinely improves the format.
How do I keep a generated character consistent across many videos?
Create one canonical reference image at high resolution with neutral lighting, lock the model and seed you used for it, and always generate from that reference rather than from a text description. Generate connected shots in the same session, and avoid switching models mid-series.
What makes a thumbnail work at small sizes?
One subject, one emotion, strong contrast against the surrounding feed, and text of three to five words in a consistent type treatment. The reliable test is to shrink the image to roughly 200 pixels wide and check whether you can identify the subject and the emotion in under half a second.
Should I generate separate videos for vertical and landscape?
Usually not. Compose with a subject slightly off-center, keep essential information away from the top and bottom edges, generate at the highest available resolution, and crop per platform in post. This preserves the visual system and saves significant production time, with a note that mobile-first vertical formats may still justify a dedicated composition.
How do I know whether a branding change actually helped?
Track three metrics per format: click-through rate, average view duration, and returning-viewer share. Change one variable at a time and compare against a rolling channel average, not against a single prior video. Isolated wins are noise; repeatable patterns are signal.
Where does AI generation fit best in this pipeline?
Generation excels at expressive, expensive, or impossible-to-shoot material: environments, stylized B-roll, character performances, and visual effects. Keep exact tasks — typography, product detail, legal text, precise branding — in traditional editing tools where you have frame-level control.
