
Text-to-video tools feel like magic the first time you use them. You type a sentence, wait a minute, and a clip comes back with drifting camera movement, believable lighting, and a character who almost keeps the same face from start to finish. The second time you use them, the illusion usually breaks: hands melt, backgrounds morph, and the same prompt produces a completely different result.
That gap between "magic" and "unreliable" is not random. It comes from the pipeline underneath: diffusion models that denoise noise into images, temporal layers that try to keep those images consistent over time, and conditioning systems that let you steer the result. Once you understand those layers, you stop guessing at prompts and start diagnosing problems. You learn which failures come from your wording, which come from the model's motion understanding, and which come from asking for something the architecture simply cannot hold together yet.
Why Understanding the Pipeline Beats Memorizing Prompt Tricks
Prompt libraries circulate constantly, but they decay fast. A phrase that produced a beautiful cinematic pan on one model version behaves differently after the next update, because the model was retrained on different data with different captioning. Copy-paste prompting treats video generation as a black box with magic words inside. Understanding the pipeline treats it as a system with inputs, constraints, and failure modes.
The practical difference shows up when something goes wrong. If you know that motion is largely inferred from a training prior rather than from your prompt, you stop writing "she walks three steps, then turns left, then sits" and start writing a shot that the model can plausibly render in a single continuous take, then cutting the rest in an editor. If you know that your first frame dominates the look of the clip, you stop relying on text to describe a wardrobe and start supplying a reference image.
This guide walks through the whole stack: the diffusion core, the temporal machinery, the text-encoding stage, conditioning controls, consistency techniques, and the decision criteria that separate tools built for different jobs. It ends with a repeatable workflow and a troubleshooting table you can use on real projects.
The Engine Room: Diffusion, Latent Space, and Motion Priors
Almost every modern video generator is built on image diffusion. The core idea is simple: take a clean image, progressively destroy it with noise, then train a network to reverse that destruction. At generation time you start from pure noise and run the reverse process, guided by your prompt, until a coherent image appears.
Denoising in latent space
Running that process directly on pixels would be prohibitively slow, so models work in a compressed representation called latent space. A variational autoencoder squeezes each frame into a much smaller set of numbers that preserve structure and color while discarding fine detail. The diffusion network denoises inside that compressed space, and a decoder expands the result back into pixels at the end.
This is why resolution and duration scale so aggressively. A four-second clip at 24 frames per second is roughly a hundred frames, each with thousands of latent values, all of which have to be jointly plausible. Doubling duration roughly doubles the compute and multiplies the chances of drift.
Why motion priors matter
Diffusion alone produces stills. To get motion, models are trained on video data where the network learns statistical regularities: clouds drift slowly, water flows downward, hair follows head rotation, crowds move in loose streams. These learned regularities are the model's motion prior.
Your prompt can request motion, but it cannot invent physics the model has never internalized. That is why "a chef flips a pancake and catches it in the pan" often fails: the prior for object trajectories across a fast arc is weak. "A chef slides a pan forward on a flattop" succeeds, because the motion is simpler and better represented in training data. Writing prompts that respect the prior is the single highest-leverage skill in AI video.
Temporal Coherence: The Hardest Problem in Video Generation
An image model optimizes each frame independently. A video model has to make frame 1, frame 47, and frame 96 agree about who is in the shot, what they are wearing, where the light comes from, and which direction the camera is facing. That agreement is temporal coherence, and it is where most visible failures live.
Attention across frames
Most current approaches add temporal attention layers or 3D attention blocks that let the network look at neighboring frames while denoising the current one. Some architectures factor this into spatial and temporal passes; others use a transformer that treats time as an extra dimension. The shared goal is the same: propagate identity, texture, and lighting forward while allowing motion.
Attention is expensive. Looking at every frame pair scales quadratically, which is why long clips are usually produced by generating overlapping segments and blending them, or by generating a shorter clip and extending it with a motion-aware continuation pass.
Drift, morphing, and how to spot them
Coherence failures come in recognizable flavors. Identity drift makes a face subtly change across a shot. Texture crawling makes skin, fabric, or foliage shimmer as if it is boiling. Background morphing rewrites architecture between cuts. Object permanence errors make props appear, vanish, or duplicate. Knowing which one you are seeing tells you what to change: reduce motion, shorten the clip, add a reference image, lock the camera, or split the shot into two generations you can cut together.
From Prompt to Playable Clip: The Processing Pipeline
Text encoding and semantic mapping
Your prompt first passes through a text encoder that converts words into vectors, then through cross-attention layers that bind those vectors to regions of the latent representation. This is why word order and specificity matter. Nouns and concrete adjectives map well; abstract instructions like "make it feel more alive" map poorly.
A useful mental model: the encoder gives the model a fuzzy concept cloud, not a storyboard. Anything that requires precise spatial reasoning, like "the red mug is to the left of the laptop, slightly behind it," is a request the cross-attention may only partially honor.
Latent initialization and noise seeding
Generation starts from a random latent, controlled by a seed. The same prompt with a different seed can yield a different composition, lighting, and even perceived identity. Locking the seed is how you iterate on a shot without losing what already worked. Changing the seed is how you explore alternatives when a composition is fundamentally wrong.
The denoising loop
Over dozens of steps, the network progressively removes noise while your prompt and any conditioning inputs steer the result. Guidance scales control how strictly the model follows the prompt: low values give more natural motion and looser adherence, high values give tighter prompt fidelity with more artifacts and stiffer movement. Most quality problems attributed to "bad models" are actually mis-set guidance.
Decoding, interpolation, and finishing
The latent sequence is decoded into frames, then often smoothed. Many tools generate at a lower frame rate and interpolate up to 24 or 30 frames per second. Interpolation can create ghosting around fast motion, so if a clip looks fine frame-by-frame but mushy in playback, try disabling interpolation and delivering at the native rate.
Conditioning Controls That Give You Directorial Power
Text is the weakest control surface. Stronger controls exist, and using them is what separates consistent output from lucky output.
First-frame and last-frame anchoring
Supplying a start image locks composition, palette, and identity immediately. Supplying an end image as well turns generation into an interpolation problem: the model has to find a plausible path between two known states, which dramatically reduces drift. This is the most reliable technique for product shots, character intros, and match cuts.
Depth, pose, and motion transfer
Depth maps, pose skeletons, and optical-flow guides let you drive the structure of a shot from real footage. You can film a colleague walking through a hallway on a phone, extract pose, and restyle the scene while keeping the movement. Motion transfer is also the cleanest way to get complex choreography, because you are no longer asking the model to invent the physics.
Camera moves and shot language
Camera instructions work best when expressed as physical descriptions rather than film jargon. "Slow push in" is understood more often than "dolly zoom," and jargon-heavy prompts occasionally produce literal, unwanted objects. Pair one camera instruction with one subject action, and avoid stacking three moves in one clip.
Consistency Across Shots: Characters, Wardrobes, and Sets
A single good clip is not a video. Sequences need continuity, and continuity in AI video is engineered rather than assumed.
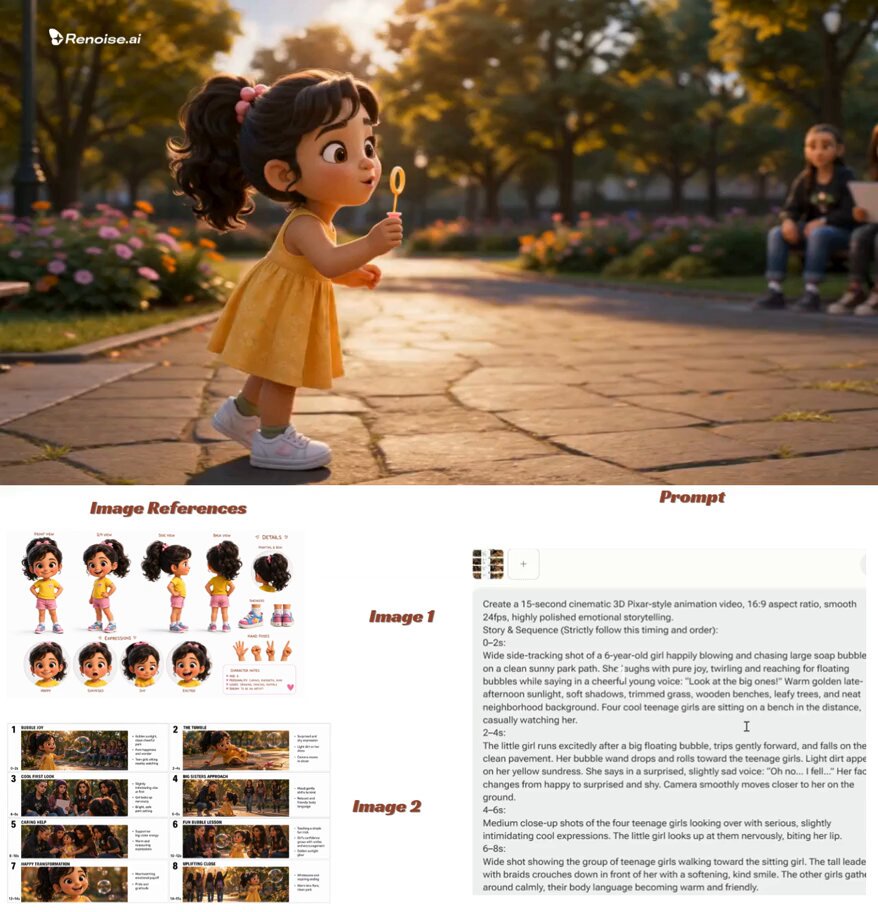
The most dependable approach is a reference kit: three to five well-lit images of each character from different angles, a couple of environment plates, and a short written style note covering palette, lens feel, and lighting direction. Feed the same references into every generation for that scene. Some tools accept multiple reference images and fuse them, which helps hold a face while changing the background.
Naming also matters more than people expect. Give each character a short, distinctive descriptor and reuse it verbatim across prompts rather than paraphrasing. Consistency in wording costs nothing and measurably reduces the model's tendency to reinterpret.
Finally, accept that perfection across a whole sequence is unlikely in a single pass. Professional AI video work is assembled, not generated: you produce more footage than you need, keep the shots that hold up, and cut around the ones that do not.
Choosing a Generator: A Decision Framework
Tools differentiate on five axes. Score your project against each before you commit.
- Duration and extension. Some tools excel at short, dense, high-quality clips; others handle longer sequences with weaker per-frame fidelity. If your scene needs a twelve-second continuous take, this axis decides the tool.
- Control surfaces. Look for image conditioning, start and end frames, motion or depth guidance, and camera controls. Text-only tools are fast but brittle.
- Subject consistency. Multi-reference image support is the strongest signal that a tool is built for narrative work rather than one-off clips.
- Iteration speed and predictability. Fast generations with stable seeds let you refine. Slow generations push you toward careful planning, which is fine for hero shots but painful for social content.
- Audio and post-friendliness. Native audio generation, clean exports, alpha channels, and predictable codecs save hours in the edit.
Match the tool to the shot, not the project. Many teams use one model for fast ideation, another for hero frames, and a third for motion-driven sequences.
A Repeatable Production Workflow
Pre-production: shot list and style bible
Write the sequence as discrete shots, each with one action and one camera move. For each shot, decide which conditioning inputs you will use: still frame, reference images, depth guide, or text only. Build a style bible with three to five reference images and a single paragraph describing light and palette. This takes an hour and saves a day.
Generation: batch and iterate
Lock the seed for any shot that is close to working. Generate in batches of four to six variations with small prompt changes rather than rewriting the whole prompt each time. Keep a simple log: prompt, seed, reference images, guidance setting, and outcome. Within a week that log becomes more valuable than any prompt list you could download.
Post: assemble, sound, and finish
Edit in a standard timeline, not in the generator. Cut on motion, use short clips to hide drift, and let sound carry continuity across cuts. Light color grading across the whole sequence hides small inconsistencies in white balance and contrast between generations. If a shot needs more punch, upscale and interpolate in dedicated tools rather than regenerating and hoping.
Common Artifacts and How to Fix Them
- Melting hands and faces. Reduce motion complexity, shorten the clip, add a first-frame reference, and avoid extreme close-ups on hands during fast movement.
- Flickering textures. Lower the guidance scale slightly, reduce motion strength, or disable interpolation and deliver at the native frame rate.
- Sudden identity shifts. Split the shot, anchor each segment to the same reference images, and cut between them.
- Warped architecture in pans. Reduce pan distance per clip, use start and end frames, or generate in place and fake the pan in post with a wider source frame.
- Unwanted text and logos. Describe the surface instead of the sign, remove the word from the prompt entirely, and paint out artifacts in post.
- Composition that ignores the prompt. Change the seed before changing the wording; most layout complaints are seed problems.
- Stiff, lifeless movement. Lower guidance, simplify the prompt, and add one clear motion verb.
FAQ
How long can a single AI-generated clip be?
Practical limits vary by tool, but coherence generally degrades as duration grows. Generating four to eight second segments and stitching them with matched references is more reliable than pushing one long generation far past its comfort zone.
Do I need a powerful GPU?
Not for hosted tools, which run generation on remote hardware. Local generation demands a strong GPU with substantial memory, and the tradeoff is usually control and privacy versus speed and convenience.
Why does the same prompt give different results every time?
Because generation begins from a random latent seed. Fix the seed to reproduce a composition, and vary it when you want alternatives. Small differences in tool version, resolution, and duration can also change output.
Is prompt engineering still worth learning?
Yes, but it is now only one control among several. The highest-return skills are reference-image conditioning, start and end frame anchoring, and editing discipline. Prompting gets you the first 60 percent; the rest is pipeline knowledge.
How do I keep a character consistent across many shots?
Build a reference kit with multiple angles, reuse one exact descriptor in every prompt, keep lighting and lens language consistent, and accept that assembly in the edit is part of the workflow rather than a failure of the model.
Will AI video replace traditional shooting?
It is replacing specific tasks first: storyboards, animatics, b-roll, concept visualization, and social cutdowns. Live-action remains stronger for performance, complex physical interaction, and authentic documentary texture. The practical future is hybrid, with generated elements composited into footage rather than either approach replacing the other.
