
Generating a single breathtaking AI video clip has become routine. Generating twelve clips that all look like they belong to the same film is still where most projects fall apart. That gap — between a good shot and a coherent sequence — is what multi-image fusion was built to close.
This guide is a practical workflow for anyone producing narrative, commercial, or episodic AI video: how reference images work as identity anchors, how to structure prompts when the model already sees your references, how to plan coverage so continuity problems never arise, and how to fix the failures that slip through anyway. No platform hype, no model leaderboard — just the mechanics you can apply today across whatever generation tools you already use.
Why Character Consistency Breaks in AI Video
Text-to-video models have no memory. Each generation is an independent roll of the dice conditioned on whatever text you typed. If you write "a woman in a red coat walking through a market" in shot one and "a woman in a red coat turning toward the camera" in shot five, nothing in the system guarantees those two women share a jawline, hairline, eye color, or coat cut.
The randomness is not a bug you can prompt away. The model samples from a distribution. The distribution contains thousands of plausible women in red coats. Your prompt narrows the field but rarely collapses it to one person.
Several forces compound this:
Seed instability. Many tools accept a seed, but the same seed does not mean the same subject when motion, camera angle, or duration changes. The seed stabilizes texture and lighting more reliably than identity.
Pose-dependent generation. A face generated in profile uses different learned features than the same face generated frontally. Small differences compound until the character reads as a different actor.
Lighting-driven interpretation. Warm sunset light and cold fluorescent light push a model toward different skin tones and feature emphasis. If your scene cuts between lighting setups, identity drifts with the light.
Wardrobe inference. If you describe clothing in words, the model re-invents it every shot. "Leather jacket" is a category, not a garment. Seams, collar shape, and hardware will change.
Context loss over long clips. Even models that hold coherence for eight seconds tend to soften details past that window.
The practical result for a creator is a painful loop: generate, notice the face changed, regenerate, notice the outfit changed, regenerate, and slowly lose an afternoon. Multi-image fusion exists to interrupt that loop by giving the model something stronger than words to hold onto.
What Multi-Image Fusion Actually Does
Multi-image fusion means conditioning one generation on several reference images at once, with each image contributing a different kind of information. Instead of describing a character in adjectives, you hand the model a picture of that character and say: use this as the source of truth.
Under the hood, reference images are encoded into the model's conditioning space and combined through cross-attention with the text prompt. Each reference contributes an attention weight. When references agree — two photos of the same person in similar light — the signal reinforces itself and identity locks in tightly. When references disagree, the model blends them, producing a face that resembles a cousin rather than a twin.
Reference roles: identity, wardrobe, lighting, and set
The most reliable approach is to assign each reference a job instead of dumping a folder into the tool and hoping:
- Identity anchor. A clean, evenly lit frontal or three-quarter portrait. This is the reference that matters most. Keep it neutral in expression and free of heavy styling.
- Secondary identity. A second angle — profile or a slightly different three-quarter — to prevent the model from flattening the face into a single viewpoint.
- Wardrobe reference. A garment shot flat or photographed on a mannequin, plus at least one image of it worn so the model understands drape and fit.
- Lighting reference. A frame that tells the model what kind of light the shot should have: hard direct flash, soft window light, neon spill, overcast. This is separate from identity and should not double as a face reference.
- Set or environment reference. A plate of the location, ideally without the character in it, to keep backgrounds stable across cuts.
A four-to-six reference set with these roles outperforms a twenty-image dump every time. Overloading the conditioning space dilutes attention and increases the chance of blending.
How many references is enough
Start with one strong identity anchor and add references only when a specific problem appears. If the face drifts in profile shots, add a profile reference. If the jacket keeps mutating, add a flat garment shot. This incremental method keeps you in control of what the model is actually weighting.
Building a Reference Pack Before You Generate
Five minutes of preparation saves hours of regeneration. Before you touch a video model, build a reference pack — a small, versioned folder for each recurring element in your project.
For a character:
- Generate or shoot a character sheet: neutral expression, even lighting, no dramatic shadows, hair pushed back off the face if it can be done without changing the silhouette.
- Capture at least three angles: frontal, three-quarter left, three-quarter right. Add profile if the character appears in profile shots.
- Add one full-body image with the default wardrobe, standing straight, arms slightly away from the torso.
- Add one flat or mannequin image of the signature garment.
- Note the skin tone, hair color, eye color, and any distinguishing marks in a text file so your prompts never contradict the images.
For a location:
- One wide plate, one mid shot, one detail.
- Note the dominant light direction in words: "window light from camera left."
Naming and versioning. Use a naming convention like character_elena_identity_v3.png. When you change something — a haircut in episode four — create a new version rather than overwriting. You will need to know which pack produced which shot when a sequence starts looking inconsistent.
Avoid cross-contamination. Do not mix identity references from wildly different lighting conditions. A portrait in golden hour and a portrait under fluorescent light teach the model two different faces.
Prompt Structure for Multi-Reference Shots
Once references carry identity, your prompt's job changes. It should describe action, camera, and mood — not appearance. The single biggest cause of broken faces is a prompt that fights the reference.
Describing the shot without fighting the references
Use a consistent skeleton:
[subject action] + [camera and framing] + [lighting] + [grade and format] + [reference directive]
For example:
Woman pauses mid-stride and glances left over her shoulder, medium close-up, slight handheld drift, hard direct on-camera flash, 35mm color negative look with visible grain. Use the identity reference as the source of truth for the face and the wardrobe reference for the jacket.
Notice what is absent. No hair length, no skin tone, no eye color, no garment adjectives. Every appearance detail you add is a chance to contradict the reference and trigger blending.
If you must describe appearance — for instance when no reference exists for a background extra — keep it broad and non-conflicting. "Short dark hair" is fine when no reference says otherwise. It is fatal when the identity anchor shows a long bob.
Guard clauses, negatives, and what not to over-specify
Add a short guard clause to signal how strongly the model should hold the reference:
- "Preserve facial identity exactly as in the reference."
- "Do not alter the garment design."
- "Keep the background consistent with the location plate."
Keep negative prompts minimal and targeted. Common useful additions: "no face morphing, no identity blending, no changing wardrobe, no text, no watermark." Long negative lists tend to degrade overall image quality and are rarely worth the trade.
Over-specification is the most common mistake in this stage. A prompt that is 300 words of hairstyle, accessories, and skin detail leaves no room for the reference to do its job — and when text and image conflict, results become unstable across a batch.
Shot Planning: From Script to Continuity Map
Consistency problems are cheaper to fix in a spreadsheet than in a render farm. Build a continuity map before you generate anything.
The map is a table with one row per shot and the following columns: shot ID, story beat, framing, character references used, wardrobe references used, location plate, prompt skeleton, seed, duration, and notes. Filling this in forces you to notice, for example, that you have nine consecutive close-ups of the same face — which is exactly where drift is most visible and most exhausting to fix.
Designing coverage that hides the seams
AI video rewards a specific kind of shot planning:
- Vary distance deliberately. Close-ups are the hardest shots to keep consistent. Use them for emotional beats only, and break them up with wides, inserts, and over-the-shoulder frames.
- Plan cutaways early. Hands, objects, environment details, and reaction shots give you edit-friendly material that carries no identity risk.
- Block movement across cuts. If a character exits frame right, the next shot should enter from frame left. This costs nothing and makes the sequence feel intentional.
- Keep clips short. Four to six seconds of strong motion beats ten seconds of drifting motion. You can trim anything; you cannot repair a face that changes at second seven.
Reusing camera language
Pick two or three camera behaviors for the whole project — for example, locked-off tripod, slow push-in, and slight handheld drift — and reuse them. Repeating camera language makes separate generations feel like they came from one shoot, and it reduces the number of variables the model has to resolve per shot.
A Step-by-Step Workflow for a 30-Second Scene
Here is the full pipeline, from script to assembly, in the order that minimizes rework.
1. Lock the script and shot count. Decide the beats first. Rewriting the script after generation is the fastest way to waste a day.
2. Build and organize the reference pack. Character identities, wardrobe, lighting, and location plates, all named and versioned.
3. Generate keyframes as stills. This is the most important step. Use an image model with multi-image reference support to generate one still per shot. Stills are fast, cheap to iterate, and easy to compare side by side. Fix identity problems here, where fixing costs seconds.
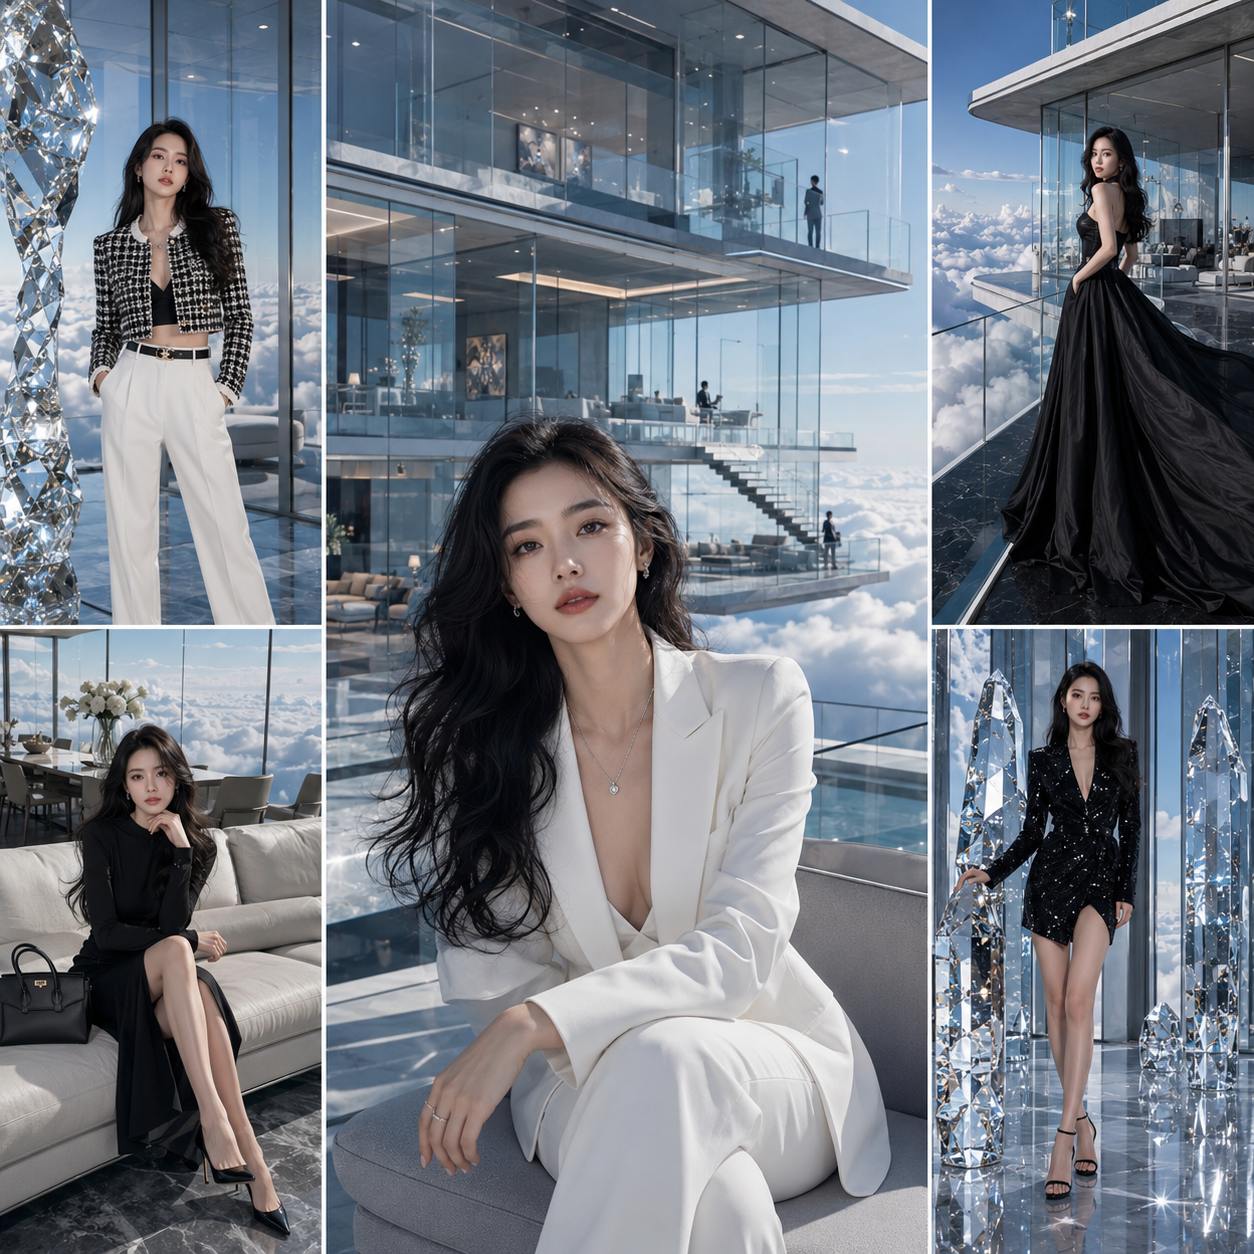
4. Approve keyframes as a contact sheet. Lay all stills out in sequence order and look at them as a grid. Drift is far more obvious in a grid than in isolation. If shot seven reads as a different person, regenerate shot seven's still before going any further.
5. Animate approved keyframes. Use image-to-video rather than text-to-video for every shot where identity matters. Your approved still becomes the first frame, which anchors composition, wardrobe, and face simultaneously.
6. Keep parameters stable across the batch. Same resolution, same aspect ratio, same motion strength where possible, same duration. Changing quality settings mid-sequence is a hidden source of tonal drift.
7. Generate three takes per shot. Accept that you will discard two. Reviewing three options takes less time than regenerating a single failed attempt five times.
8. Trim and assemble. Cut on motion, not on stillness. A cut during movement hides small continuity imperfections.
9. Color and grain match. A single pass of contrast, saturation, and grain across every clip glues mismatched generations together more effectively than any prompt trick.
10. Review against the continuity map. Check face, wardrobe, props, background, and screen direction, in that order, before you export.
Quality Control and the Most Common Consistency Failures
Reviewing AI video is a skill. Watching a clip for enjoyment hides errors; watching it for continuity finds them. Pause on the first frame and the last frame of every clip, because those are the frames most likely to be cut against a neighbor.
Face drift
The most visible failure. Symptoms: jaw width changes, eye spacing shifts, hairline recedes or advances, skin tone warms or cools.
Fixes: strengthen the identity reference; reduce descriptive text about the face; drop the clip duration; regenerate only the drifted segment; and check whether the lighting in the prompt contradicts the identity reference's lighting.
Wardrobe and prop mutation
Jackets change pocket placement, logos vanish, watch straps swap sides. Any object described only in words is at risk.
Fixes: add a flat garment reference; add a prop reference image; explicitly instruct preservation of the garment; and avoid describing the item again in the prompt once a reference exists.
Set and lighting drift
Backgrounds shift from brick to concrete, windows move, time of day changes between cuts.
Fixes: use a location plate as a reference, keep the lighting clause identical across all shots in a scene, and add small foreground or background elements in your edit — a chair, a pillar, a passing figure — that give the eye a consistent landmark.
Motion artifacts
Warping hands, melting limbs, faces that snap back into shape after a fast turn.
Fixes: reduce motion magnitude, choose slower actions, shorten the clip, use a higher-resolution source still, and avoid fast rotations of the head. When motion quality is the priority, generate the moment at lower motion strength and cut around the difficult frames.
Choosing and Combining Video Models
Model choice matters less than pipeline design, but the criteria below determine what your pipeline can do.
- Reference support. How many images can be conditioned at once, and can each play a defined role?
- Image conditioning strength. Does the model respect an input frame closely, or treat it as a loose suggestion?
- Native clip length. Longer native clips reduce the number of seams you must hide.
- Motion realism. Look at hands, cloth, and hair in the demo before you commit.
- Parameter stability. Can you reproduce a setting exactly across a batch?
- Batch and API access. Producing twenty variants manually does not scale.
- Effective cost per usable second. Not the headline rate — the rate after retries.
- Licensing. Commercial use, model training restrictions, and output ownership matter for client work.
A hybrid pipeline usually wins: generate keyframes in an image model with strong multi-reference support, animate them in a video model with the best motion, then upscale and grade in a post tool. Treating these as separate stages rather than one all-in-one service gives you far more control and makes swapping tools painless when something better arrives.
Scaling a Series Without Losing the Look
When you move from one scene to a ten-episode run, process discipline beats raw model quality.
Maintain a look bible. One document containing your identity references, wardrobe plates, location plates, camera behaviors, color palette, grain settings, and the exact wording of your style clause. Every new shot starts from this document.
Build a prompt library. Save your prompt skeletons — close-up, wide, insert, transition — with slots for action and beat. Cutting and pasting a known-good skeleton is faster and far more consistent than writing each prompt from scratch.
Set review gates. Approve keyframes before animating. Approve takes before editing. Nothing moves to the next stage on a hope.
Track what produced what. Record which reference pack version and which parameters generated each approved shot. When a character subtly changes in episode six, you need to trace it back.
Batch similar shots. Generate all the close-ups of a character in one sitting with identical settings. Batching reduces variation caused by parameter drift between sessions.
Archive your winners. Keep approved stills as future references. The best identity anchor for episode ten is a frame from episode three that already worked.
FAQ
How many reference images do I actually need?
Two to four for a character is typical: one strong frontal or three-quarter identity anchor, one secondary angle, one wardrobe reference, and optionally one lighting reference. Add images only to fix a specific recurring problem. Large reference dumps dilute attention and increase blending.
Why does the face change between shots even with the same reference?
Usually because the prompt is describing the face in words that conflict with the reference, or because camera angle and lighting changed more than the model can reconcile. Remove descriptive face language, keep lighting consistent within a scene, and use image-to-video from an approved still rather than text-to-video.
Do I need to train a custom model to get consistency?
Not necessarily. Reference-conditioned generation with a well-built pack handles most narrative work. Training or fine-tuning becomes worthwhile when you need hundreds of shots of the same character with near-zero drift, or when you want a very specific visual style baked in.
Can multi-image fusion work for product video instead of characters?
Yes, and it is often easier. Use a hero product shot as the identity anchor, a detail shot for texture and material, and a lighting reference for the studio look. Keep the product described in words only for function, never for shape or finish.
What is a realistic clip length for consistency?
Four to six seconds is the sweet spot for most models. Shorter clips mean more cuts, but each cut resets the drift clock. Where you need a longer feel, generate two short clips from the same still with a small prompt variation and cut them together.
Should I ever generate video straight from text?
For establishing shots, backgrounds, textures, and abstract transitions, yes — it is fast and the identity risk is zero. For any shot where a recurring character or product is on screen in a recognizable way, keyframe first.
How do I handle a character who changes appearance deliberately?
Version the reference pack. Episode four's haircut becomes identity_v4, and shots from that point use it. Documenting the change prevents confusion later and keeps the model's conditioning aligned with the story.
What single change improves consistency the most?
Approving keyframe stills before animating anything. It converts an expensive, slow problem into a fast, visual one, and it makes every downstream stage easier to control.
