
What a Photo-to-Anime Generator Actually Does
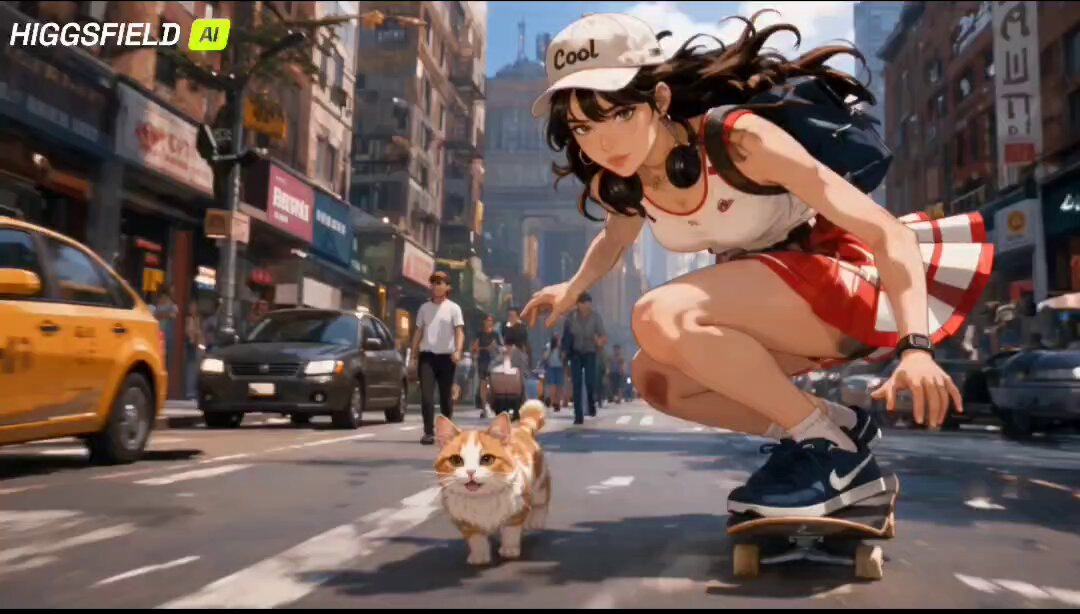
A photo-to-anime generator takes an ordinary photograph — a selfie, a portrait, a street shot, a cosplay photo — and re-renders it in the visual language of Japanese animation: crisp line work, flat cel shading, saturated but controlled palettes, enlarged and simplified eyes, minimal noses, and hair rendered with graphic highlight bands instead of individual strands. The result is not a filter. Filters remap color and contrast on top of the original pixels. A generative model throws the original pixels away and paints a new image that follows the composition of the photo.
That distinction sets expectations correctly. Because the model rebuilds the picture from scratch, it can turn a denim jacket into a school uniform, a parking lot into a shrine courtyard, and a cloudy afternoon into a golden-hour sky. It also means small specifics — a logo, a scar, a particular ring — will be interpreted rather than preserved. If a detail is not described or locked down structurally, the model treats it as optional.
Most tools on the market fall into three families. The first is classic style transfer, built on older adversarial architectures, which keeps the photograph's geometry almost perfectly intact but produces a flatter, less expressive look. The second is diffusion-based conversion, where the photo is used as an initial latent state and partially denoised toward an anime distribution. The third is a hybrid pipeline: a face-preserving pass that keeps identity stable, followed by a style pass that repaints everything else. Hybrids tend to win for portraits, while pure diffusion wins for scenery and full-body compositions.
The practical takeaway: treat your photo as a scaffold, not as a source of truth. The better your scaffold, the more freedom the model has to make something striking without losing the person underneath.
How Anime Image Models Work Under the Hood
You do not need to read a research paper to get good results, but understanding the pipeline explains almost every frustrating artifact you will run into.
Diffusion, denoising, and latent space
A diffusion model learns to reverse noise. During training it sees millions of images progressively degraded into static, and it learns the reverse mapping — how to peel noise away until an image appears. At generation time, the tool starts from noise (or from your photo plus noise), then runs a sampling loop that denoises step by step. A text encoder converts your prompt into a numeric representation that steers each step, and guidance strength determines how aggressively the model obeys the text rather than its own aesthetic instincts.
Anime-specific checkpoints exist because the average anime frame has statistical properties that differ from photographs: large regions of near-flat color, very thin high-contrast outlines, gradient-free shading bands, and screen-tone textures. Generic photo models tend to render anime prompts with a soft, semi-realistic sheen. Models tuned on illustration data produce the correct hard edges and clean fills.
Control layers and conditioning
Text alone cannot hold a pose. That is why serious workflows layer in conditioning signals: a depth map derived from the photo, an edge or line-art extraction, a pose skeleton, a segmentation mask for hair versus clothing. Each signal constrains a different aspect of the output. Depth controls volume and perspective, line art controls outline placement, pose controls limb angles, and masks let you repaint only the background while leaving the face untouched. When someone says a tool "understands composition," this is usually what they mean.
Why faces and hands break first
Faces carry the most perceptual weight — a two-pixel shift in pupil position reads as "wrong" instantly. During heavy denoising, the model has fewer constraints on small features, so eyes drift, pupils duplicate, and the iris gains an extra highlight ring. Hands fail for a different reason: they are self-occluding, high-articulation geometry with enormous variation in training data. Anime styles also render hands with only three or four visible fingers, which confuses models that learned from both illustration and photographs.
The fix is not to shout at the prompt. It is to reduce denoising strength on the regions that matter, generate at higher resolution, and use a face-restoration pass after the main render.
Choosing a Tool: Seven Decision Criteria
Tool choice is less about brand and more about which constraints you can live with. Score candidates against these criteria before committing to a subscription.
- Style range. Does the tool have distinct anime checkpoints or style presets, or one house style you cannot escape? One style is fine if it matches your project exactly, and a liability if you need range.
- Structural control. Look for depth, edge, pose, and mask inputs. Without them, you are negotiating with the model instead of directing it.
- Identity preservation. For portraits, a face-consistency feature matters more than raw image quality. A slightly softer render that still looks like the subject beats a gorgeous render of a stranger.
- Iteration speed. You will generate dozens of variants per finished image. If a single render takes ninety seconds, your creative rhythm dies.
- Resolution ceiling. Native high-resolution generation avoids the softness and artifact amplification that comes from upscaling a small base render.
- Export and rights. Confirm commercial usage terms, output formats, and whether the tool embeds metadata or watermarks that you would need to remove.
- Cost model. Flat monthly pricing rewards experimentation. Usage-metered pricing punishes it. Estimate how many generations a real project needs — usually ten to thirty per final asset — and multiply.
A quick comparison frame helps:
| Use case | Priority signals | Best-fit approach |
|---|---|---|
| Portrait headshots | Face preservation, eye detail | Hybrid pipeline with low-strength face pass |
| Full-body character sheets | Pose control, consistency | Diffusion plus pose conditioning and fixed seeds |
| Backgrounds and scenery | Depth, resolution | Depth-conditioned diffusion, heavy upscale |
| Social media stickers | Speed, transparent export | Lightweight app-style generator |
The Complete Photo-to-Anime Workflow
This is the sequence that consistently produces usable results, regardless of which tool you prefer.
Step 1: Prepare the source photo
Garbage in, slightly stylish garbage out. Choose a photo with a single clear subject, even lighting, and no heavy motion blur. Avoid strong colored light — a magenta neon wash on someone's face will be reinterpreted as hair or clothing color. Shoot or select at the highest resolution you have. If the background is cluttered, either simplify it in editing before conversion or plan to regenerate it entirely with a mask.
Step 2: Build the prompt in layers
Write the prompt as four stacked layers: subject, style, lighting, and technical framing. Subject describes who and what. Style names the era and medium. Lighting sets mood. Technical framing covers shot type, lens feel, and aspect ratio.
Example of a layered prompt:
young woman, short black bob, round glasses, oversized knit sweater, seated at a window / 1990s TV anime cel, hand-painted background, three-tone cel shading, thick clean outlines / overcast daylight with warm interior lamp fill / medium shot, eye level, 4:5 vertical
Notice there are no quality incantations. Words like "masterpiece" and "best quality" do almost nothing in modern samplers and consume attention budget that could describe the actual image.
Step 3: Add structural control
Attach your photo as the structural reference. Set the conditioning strength to roughly 0.6 to 0.8 if you want the pose and proportions preserved but the style fully repainted. Drop below 0.4 when you want the model to improvise more freely and above 0.9 when identity matters more than style. Use a mask to isolate the background if you want a completely different environment without touching the subject.
Step 4: Iterate with seeds, strength, and sampler settings
Run a seed sweep first: hold the prompt fixed, generate four to eight seeds, and pick the composition that reads best at thumbnail size. Then lock that seed and vary only one parameter per run — style weight, denoising strength, or guidance scale. This turns a chaotic search into a controlled hill climb. Most people fail here because they change five variables at once and learn nothing about which one mattered.
Step 5: Clean up, upscale, and export
After the render lands, fix hands and eyes with a targeted repaint at low strength rather than regenerating the whole frame. Then upscale in two stages — a modest 2x pass, followed by a detail refinement — instead of one aggressive jump that amplifies line noise. Export a lossless master, then produce platform-specific sizes. Keep the seed, prompt, and model version in a project note; you will want to reproduce that exact look three weeks later when the client asks for "one more in the same style."
Prompt Patterns for Six Popular Anime Looks
Different anime traditions have different visual grammars. Swap the style layer while keeping the rest of the prompt identical, and you get a fast style survey.
Retro television cel. 1990s TV anime cel, muted earth palette, visible film grain, painted background, thick uniform outlines, three-tone shading. Best for nostalgic portraits and slice-of-life scenes. Avoid modern glossy highlights here.
Modern theatrical film still. anime film key visual, volumetric light, shallow depth of field, detailed irises with multiple highlights, painterly background, widescreen crop. Great for dramatic hero images where the background should feel expensive.
Shoujo illustration. shoujo manga aesthetic, delicate line weight, screentone accents, sparkle highlights, pastel palette, floral vignette, soft diffused light. Pairs beautifully with close-up portraits and soft expressions.
Retro mecha OVA. 80s mecha OVA, hard shadows, industrial background, dynamic low-angle perspective, high contrast, mechanical detail, chrome accents. Push denoising strength higher so the model commits to harder edges.
Chibi sticker style. chibi proportions, two-and-a-half heads tall, simple two-tone shading, thick outline, transparent background. Generate square, then cut out and export as a sticker pack.
Slice-of-life key visual. slice-of-life key visual, warm late-afternoon light, cluttered room detail, soft cel shading, natural color balance, wide establishing shot.
For every style, also build a negative list: extra fingers, fused limbs, duplicate eyes, watermark, signature, text, jpeg artifacts, plastic skin, oversharpened. Negatives are not magic, but they reliably remove recurring annoyances so you spend your iterations on composition instead of cleanup.
Keeping Characters Consistent Across a Series
Consistency is the hardest part of any multi-image anime project. A viewer will forgive a slightly odd hand; they will not forgive a protagonist who changes eye color between panels.
Build a character bible before you generate anything. Record eye color with a hex value, hair length and shape, outfit layers in order, distinctive accessories, and height relative to a reference line. Then create an expression sheet — neutral, smiling, angry, surprised, side profile — using a single fixed seed and a single style preset. That sheet becomes your visual anchor.
For subsequent images, reuse three things: the seed, the style preset, and a reference image of the face. If your tool supports trained character adapters or reference-based conditioning, train one on the expression sheet. Five to fifteen reference images are usually enough for a usable adapter, and it will preserve identity far more reliably than prompt text alone.
A practical trick: generate turnarounds (front, three-quarter, profile, back) as a single wide canvas before splitting it. Models handle character consistency better within one generation than across separate generations, and you can crop the clean panels afterward.
Common Mistakes That Ruin Anime Conversions
Most disappointing outputs trace back to a handful of repeatable errors.
- Over-stylizing the source. If the photo already has heavy filters or extreme contrast, the model inherits the damage. Start clean.
- Cranking denoising strength to maximum. This abandons the photo entirely and produces a generic anime portrait with your subject's vague silhouette. Keep strength moderate and add style through the prompt instead.
- Ignoring aspect ratio. Generating a tall portrait into a square canvas crops feet or hair. Set the ratio deliberately before you render.
- Fighting artifacts with more words. If hands keep failing, change resolution or use a targeted repaint. More adjectives will not fix anatomy.
- One-and-done generation. The first output is a draft. Professionals generate ten to thirty variants per final asset.
- Forgetting the background pass. A perfectly rendered character against a photo-derived blur looks unfinished. Mask and regenerate the background separately.
- Upscaling too aggressively in one step. A 4x jump from a low-resolution base multiplies line artifacts and creates halos. Upscale in stages.
- Losing your settings. Without a record of seed, model version, and prompt, you cannot reproduce a look the client loved last month.
- Neglecting color harmony. Anime palettes are deliberately limited. If your output feels noisy, restrict the palette in the prompt (
muted teal and dusty rose, limited palette) rather than adding more detail.
Legal, Ethical, and Practical Guardrails
Before publishing AI-converted anime art, work through three questions.
First, whose face is it? Converting a photo of yourself is straightforward. Converting a photo of a friend, client, or public figure requires consent, and in some jurisdictions a documented agreement if the image will be used commercially. Photographs of real people carry likeness rights independent of copyright.
Second, what are the tool's terms? Most generators specify whether outputs may be used commercially, whether you retain ownership, and whether the provider claims any license over generated images. Read that section before you build a product on top of it. Also check how the tool handles input photos — whether they are stored, used for training, or deleted.
Third, what are you referencing? Reproducing a specific protected character design crosses from style inspiration into infringement territory in many markets. Style itself is generally not protected; specific characters, logos, and costume designs often are. If a project involves an existing franchise, get permission or keep the reference purely stylistic.
A fourth, softer consideration: disclose AI involvement when context calls for it. Art communities, clients, and platforms increasingly expect transparency, and a short note in the description costs nothing while preventing awkward surprises later.
A Two-Week Practice Plan
Skill with these tools comes from deliberate repetition, not from collecting subscriptions.
Days 1–2: Convert ten photos across three style presets. Change nothing but the preset. Learn what each one does naturally.
Days 3–4: Fix the seed and vary denoising strength from 0.3 to 0.9 in seven steps. Note exactly where identity dissolves and where style takes over.
Days 5–6: Practice prompt layering. Build five prompts using the four-layer structure and compare them against vague one-line prompts on the same photo.
Days 7–8: Work on backgrounds. Mask the subject, generate three different environments, and composite the best one.
Days 9–10: Build a character bible and an expression sheet. Then generate five new images of the same character in different poses.
Days 11–12: Study hands and eyes. Deliberately create failures, then repair them with low-strength local repaints. Document what worked.
Days 13–14: Ship a complete set — six images, consistent character, unified palette, exported at final sizes. Write a short production note recording every setting you used.
By the end you will have a personal preset library and, more importantly, an intuition for which knob to turn when something looks wrong.
FAQ
Do I need a powerful computer? Only if you run models locally. Cloud tools handle the computation, which is the practical choice for most creators. Local setups offer more control and privacy but require a capable GPU and patience for installation.
Why does my subject stop looking like themselves? Identity loss almost always comes from denoising strength that is too high or from a style preset with a strong face bias. Lower the strength, add a face-preservation pass, and consider a reference-based character adapter.
Can I convert a group photo? Yes, but generate at higher resolution and expect to repair overlapping limbs. Group conversions benefit enormously from pose conditioning, since the model otherwise tends to merge figures.
How many generations does one good image take? Budget ten to thirty. A quick sticker conversion might take three; a polished key visual with a custom character adapter can take fifty or more across multiple sessions.
Should I upscale before or after stylistic cleanup? Clean first, upscale second. Upscaling locks in whatever is already there, including mistakes, so fix anatomy and line noise at base resolution.
Why do my colors look muddy? Too many competing hues in the prompt, or a source photo with mixed lighting. Constrain the palette explicitly and simplify the light description to one dominant source.
Is it better to convert a photo or generate from text alone? If you need a specific person or a specific composition, start from a photo. If you need a mood or a scene, text-only generation is faster and gives the model more freedom.
What file format should I deliver? A lossless master for archival, plus PNG for anything needing transparency and high-quality JPEG or WebP for web delivery. Avoid re-encoding the same file repeatedly.
Where to Go From Here
Photo-to-anime conversion rewards a boring, disciplined process more than clever prompting. Prepare the source carefully, layer structure on top of text, iterate one variable at a time, and keep meticulous notes so every good result is reproducible.
The most valuable habit is the simplest: build a small personal library of presets, prompts, and reference sheets, then reuse them relentlessly. Style consistency across a portfolio is worth more than any single spectacular render. Start with one photo, one style, and a fixed seed — then change exactly one thing at a time until you know precisely what each control does.
