
Why Photorealism Became the Default Expectation
Audiences have quietly recalibrated what they consider "real." A decade ago, a synthetic shot only had to avoid obvious tells — melted faces, rubbery motion, impossible shadows. Today, viewers scroll past thousands of high-fidelity moving images a day, and their tolerance for anything that looks generated has collapsed. A commercial, a product demo, a music video, or a social spot that reads as artificial loses attention in the first two seconds.
The practical consequence is that photorealism is no longer a flex reserved for large studios. It is the entry ticket. Generative video models have improved to the point where a single creator with a clear plan can produce footage that holds up on a large screen — provided they treat generation as a production discipline rather than a slot machine.
This guide lays out a full workflow: what photorealism actually means technically, how to plan shots before you generate anything, how to choose between models, how to keep characters and locations stable across a sequence, and how to finish footage so it looks intentional rather than lucky.
What "Photorealistic" Actually Means in AI Video
Photorealism is not one property. It is the simultaneous satisfaction of four visual systems. When any one of them fails, the whole image collapses into "uncanny" regardless of how good the others are.
Optics: how a lens sees the world
Real cameras impose physics on an image. Depth of field falls off in a predictable way. Wide lenses stretch perspective and distort edges. Long lenses compress space and flatten faces. Highlights bloom slightly. Fast movement smears according to shutter angle.
Generated video frequently ignores these constraints. The result is footage that looks uniformly sharp front to back, with no focal hierarchy — the visual signature of a render, not a photograph. Fixing this is usually a matter of prompting for a specific lens and aperture, or of using a reference image that already carries the optical character you want.
Materials: surfaces doing believable things
Skin has subsurface scattering. Metal reflects the environment around it. Fabric has weight, weave, and drape. Glass refracts and caustics. When a model gets skin right but treats a jacket like painted plastic, the eye notices within a frame or two.
Material realism is heavily dependent on reference. If you want a leather jacket that behaves like leather, show the model leather in the lighting you intend to shoot in.
Motion: weight and inertia
Human motion has follows-through. Hair lags behind a turn. A coat swings after the body stops. Hands hesitate before gripping. This is the hardest category for generated video because it requires temporal coherence, not just per-frame plausibility.
Light: motivated sources and consistent direction
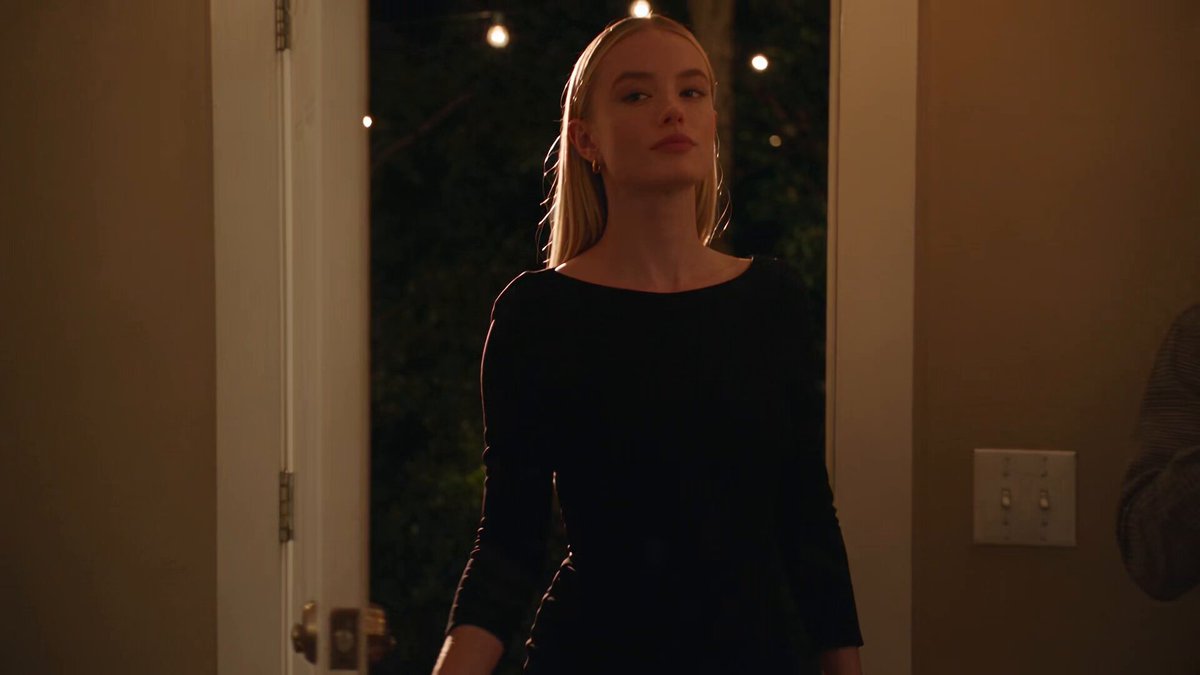
Every shot needs an answer to the question "where is the light coming from and why?" Motivated lighting — a window, a practical lamp, a phone screen, a streetlight — instantly reads as documentary. Unmotivated lighting reads as a render farm.
The practical takeaway: instead of prompting "photorealistic, 8K, cinematic," prompt the four systems explicitly. Name the lens, the light source, the material, and the motion quality. Vague adjectives produce vague images.
Pre-Production: The Layer Most People Skip
The single biggest predictor of success in AI video is not which model you use. It is how much thinking happened before the first generation.
Build a shot list, one idea per shot
Write your sequence as a list of shots, and give each shot exactly one job. "Woman walks into a bakery and orders bread, then looks out the window and smiles" is four shots, not one. Models handle single intentions far more reliably than compound actions, and you keep editorial control when each generation is a discrete building block.
For each shot, note: subject, action, setting, time of day, lens, camera movement, and duration. A ten-column spreadsheet is enough.
Assemble a reference board per scene
Collect still images that match your intended look: real photographs, film stills, mood-board frames, previous generations you liked. Group them by scene, not by project. A scene board typically needs:
- Two to three character references (face, full body, wardrobe)
- One or two location references (wide and detail)
- One lighting reference (the specific quality of light you want)
- One grade reference (contrast, saturation, color cast)
Keep the boards small. Ten images that agree with each other beat fifty that don't.
Write prompts as camera briefs, not poetry
A useful prompt has a consistent internal order: subject and wardrobe, action, environment, lighting, lens and framing, camera movement, mood, and negative constraints. Written as a brief, it looks like this:
Mid-30s woman in a charcoal wool coat, walking away from camera through a wet city street at dusk. Overcast ambient light plus warm shop-window spill from the left. 50mm lens at f/2, shallow depth of field, slight handheld drift. Cool grade with warm highlights. No text, no logos, no additional people in focus.
Notice what is absent: no "masterpiece," no "hyperrealistic," no stacked style adjectives. Specificity does the work.
Design continuity before you need it
If a character appears in more than one shot, decide in advance: hair length and part, jacket color, jewelry, scars, glasses, the bag they carry. Write it down. Continuity errors are the most common reason a sequence feels generated rather than shot.
Choosing the Right Model for Each Shot
There is no best model. There is a best model for a shot type, and the gap between them is often larger than the gap between generations of the same model.
The three generation modes
Text-to-video gives you maximum exploratory freedom. Use it for concepting, for establishing shots where identity doesn't matter, and for environments.
Image-to-video is the workhorse of photorealistic work. You lock the look with a still — either a real photograph, a rendered frame, or a generated image — and the model animates it. Because composition and lighting are already correct, the model only has to solve motion.
Video-to-video (including re-styling and motion transfer) is best for fixing footage you already have: changing grade, adding weather, altering wardrobe, or converting live-action plates into a different look while preserving real motion.
Matching model to shot
| Shot type | Mode | What to prioritize |
|---|---|---|
| Establishing wide | Text-to-video | Environmental detail, atmosphere |
| Character close-up | Image-to-video | Facial stability, skin texture |
| Dialogue-adjacent reaction | Image-to-video | Micro-expression control |
| Action beat | Text-to-video with strong refs | Motion coherence, no morphing |
| Product beauty shot | Image-to-video | Material accuracy, reflections |
| Re-grade of live footage | Video-to-video | Color fidelity, detail retention |
Draft cheap, finish expensive
Every pipeline benefits from a two-tier approach: fast, low-resolution drafts to test composition and motion, then high-quality renders only for shots that survive review. Generating finals on unproven shots is the fastest way to waste time and compute.
Character and Scene Consistency Across Shots
Consistency is the hardest problem in AI video, and it is solved with anchoring rather than luck.
Identity anchors
An identity anchor is the smallest set of images that uniquely describes a person. In practice, three to five images work well: a clean frontal, a three-quarter view, a profile, and one full-body shot. The lighting across these images should be neutral and similar — mixing a sunset portrait with a studio headshot teaches the model two different people.
When generating, pass the anchor set alongside an image-to-video start frame. The start frame defines pose and composition; the anchor set defines who the person is.
Multi-image fusion
Feeding multiple references into a single generation lets you combine attributes: face from one image, wardrobe from another, environment from a third. The trick is keeping the references mutually consistent in lighting and grade. If your face reference is warm daylight and your location reference is cold dusk, the model will average them into mud.
Wardrobe, props, and continuity bibles
Before production, build a short continuity document. For each character: hair, wardrobe per scene, key props, gait, handedness. For each location: time of day, weather, light direction, background activity. This is unglamorous and it is the difference between a sequence that reads as film and one that reads as a demo reel.
Hands, crowds, and background text
These remain predictable failure points. Practical mitigations:
- Hands: compose shots so hands are occupied, partially cropped, out of frame, or in motion blur. Full open-hand close-ups are the riskiest composition in the medium.
- Crowds: keep background people out of focus, silhouetted, or facing away. Prompt for depth-of-field separation so the model doesn't have to resolve faces it can't.
- Text: remove it from the shot. Add signage and UI in post, where you control spelling.
Lighting, Lenses, and Camera Language
Photorealism lives or dies in the language of cinematography. Learn to speak it in prompts.
Focal length and depth of field
Specify a lens: 24mm for environmental wides, 35mm for verité coverage, 50mm for portraits, 85mm for compressed close-ups. Then specify aperture. At f/1.8 a face has one razor-thin plane of focus; at f/8 everything is legible. Most generated video defaults to an unnaturally deep depth of field, so explicitly asking for shallow focus is often the single biggest realism upgrade.
Shutter and motion feel
A 180-degree shutter produces natural motion blur. Higher shutter speeds look sharp and clinical — useful for action, wrong for intimate scenes. Ask for "natural motion blur" or "slight motion smear on fast movement" when motion looks too crisp or strobing.
Motivated lighting
Anchor every shot to a source you can name: overcast sky, window light, a desk lamp, neon signage, headlights, a phone screen. Then describe the direction and quality: soft and directional from the left, hard and toppy, warm spill from behind.
Film emulation and grade
Final realism often comes from the grade, not the generation. Apply a film emulation look with halation on highlights, slight grain, gentle roll-off in highlights, and a mild color cast. Add subtle lens artifacts — a touch of vignette, chromatic aberration at the frame edges — but keep them restrained. Overdone artifacts read as a filter; restrained artifacts read as a camera.
The Rendering Pipeline: Draft to Final
A repeatable pipeline beats improvisation. Here is one that works for short-form and long-form alike.
Step 1 — Assemble assets
Collect anchors, location plates, and lighting references. Normalize them: same aspect ratio, similar grade, no watermarks.
Step 2 — Generate low-cost drafts
Produce short, low-resolution clips for every shot in the list. Two to three variants each. Judge on composition and motion, not detail.
Step 3 — Select and lock
Pick the winning variant per shot and freeze it. Record the prompt, references, seed, and settings so the shot is reproducible.
Step 4 — Re-render picks at high quality
Re-run the selected configurations at full resolution and duration. Because the composition is already validated, this pass rarely surprises you.
Step 5 — Repair problem frames
Use localized fixes — masking and re-rendering a region, extending a clip, splitting a shot at a cut point — rather than regenerating an entire shot. Repair is cheaper than replacement.
Step 6 — Upscale and interpolate
Upscale to delivery resolution, then interpolate frames if you need smoother motion or slow motion. Interpolate after upscaling, and check for warping on fast movement.
Step 7 — Assemble and finish
Edit in your NLE, then add sound. This is underrated: clean foley, room tone, and a coherent ambience track will convince an audience of realism faster than another render pass. Add grain and grade across the full sequence so all shots share one visual fingerprint.
Common Mistakes and How to Avoid Them
Chasing realism with adjectives. "Hyperrealistic, ultra-detailed, 8K" adds nothing. Describe the lens, light source, and material instead.
Generating finals on unproven shots. Always draft first.
Inconsistent references. Mixed lighting in your anchor images produces a character who changes between shots.
Compound actions in a single shot. One intention per generation.
Ignoring the cut. Realism is partly editorial. Cutting on motion and matching eyelines hides generation flaws better than any model upgrade.
Perfect sharpness everywhere. Real footage has focal falloff, grain, and slight imperfection. Adding them back is part of finishing.
Skipping audio. Silent perfection still reads as synthetic. Sound design closes the gap.
No continuity document. Consistency is a documentation problem before it is a model problem.
A Repeatable Workflow Checklist
Before you generate: shot list written, reference boards built, continuity document complete, lens and lighting specified per shot.
During generation: drafts first, two to three variants per shot, settings logged, identity anchors attached to every character shot.
After generation: winners locked and re-rendered at full quality, problem frames repaired locally, upscale then interpolate, assemble, grade as a whole, add foley and ambience.
Review passes: watch the sequence muted to check visual continuity. Then listen with your eyes closed to check audio continuity. Then watch on a phone screen at small size — if it still reads as real there, it will read as real anywhere.
FAQ
How long does a photorealistic AI video shot take?
Draft generations take seconds to a couple of minutes. A finished, graded shot typically involves several drafts, one or two high-quality renders, upscaling, and repair — plan on a working session per shot for complex close-ups, less for wides.
Do I need image references, or can I just write prompts?
Text-only generation works for environments and establishing shots. For anything with a recurring person or a specific product, image-to-video with references is dramatically more reliable.
How do I stop faces from morphing mid-shot?
Shorten the shot, keep the camera movement modest, use an identity anchor set with consistent lighting, and avoid extreme head rotations. If a face still drifts, split the shot at the point of failure and cover it with a cut.
Is upscaling or frame interpolation more important?
Upscaling, usually. Viewers tolerate slightly uneven motion far more than soft or noisy detail. Interpolate only when you need slow motion or smoother camera movement.
Can I mix generated shots with live-action footage?
Yes, and it is often the strongest approach. Match the grade, grain, lens character, and motion blur of your live plates, and cut on action so the audience's eye carries across the transition.
What resolution should I deliver?
Deliver at the resolution your distribution channel actually benefits from, and keep a higher-resolution master for future re-crops. Photorealism depends more on correct optics, grain, and grade than on pixel count.
How do I keep a character consistent across a long sequence?
Treat it as asset management: one locked anchor set per character, one continuity document, and a habit of re-using the same reference images and seeds for every shot in that scene. Consistency is a process, not a prompt.
