
AI Animation Character Generator: Build Consistent Heroes
Oct 15, 2026
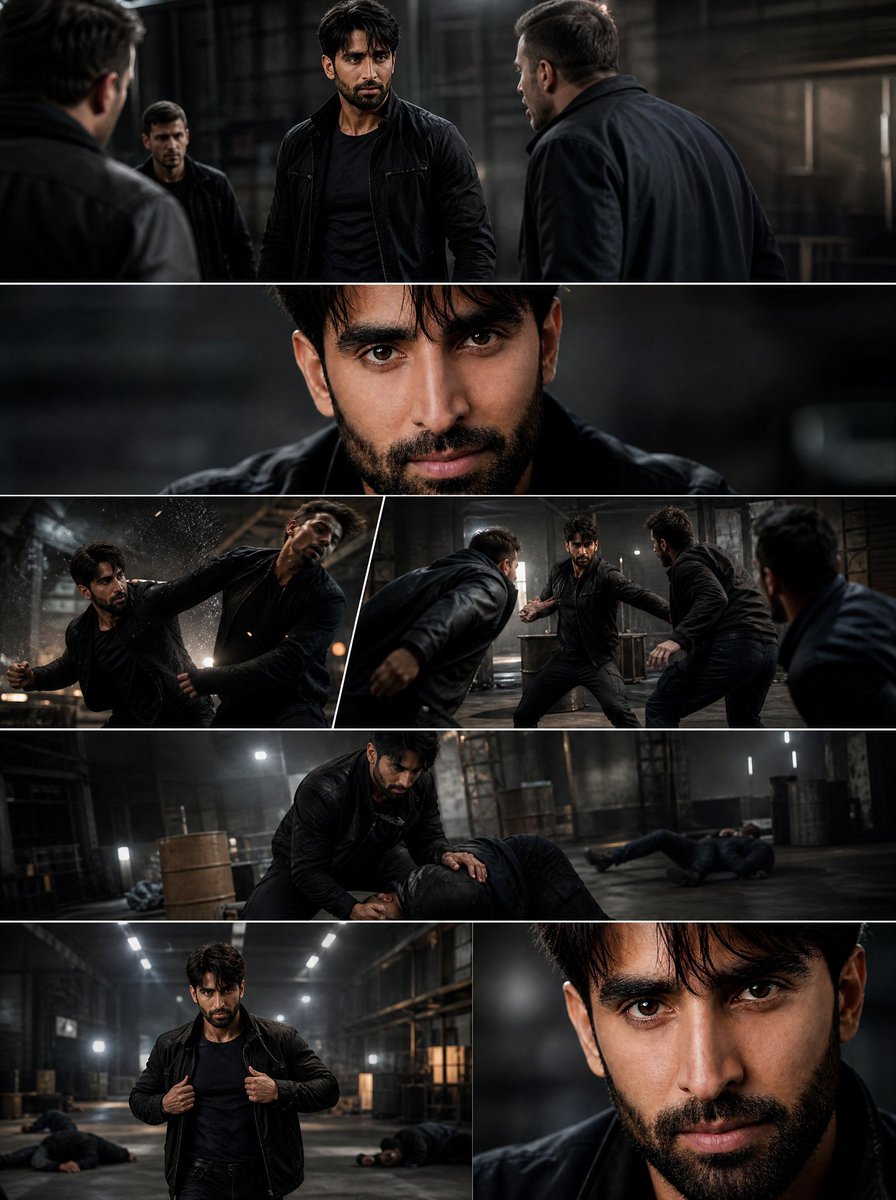
Generating one striking character portrait is nearly effortless now. Generating the same character across twelve shots — walking, turning, speaking, reacting — is where most AI animation pipelines fall apart. That gap between a beautiful still and a believable performance is the real work of an AI animation character generator, and it is what separates a demo clip from a finished piece.
The good news is that the process is learnable. It is less about finding a magic model and more about building a repeatable pipeline: define the character, lock the look, generate short beats, keyframe the transitions, and clean up in the edit. This guide walks through that pipeline end to end, including the decision points where most projects go wrong.
Why Character Consistency Is the Real Bottleneck
Most creators begin with the wrong question. They ask which tool produces the prettiest single frame. A better question: which tool holds a face, a costume, and a silhouette steady while the camera moves and the character acts?
Identity drift is the term worth knowing. It describes the slow mutation of a character across generated frames — the jaw widens, the jacket changes shade, the hairline creeps, the eye color shifts. Drift is not a bug you can prompt your way out of with a longer description. It comes from how diffusion-based video models reinterpret the same text prompt differently at every timestep, and from how little visual information a text prompt actually carries.
The practical consequences are predictable. A character who looks like a different cousin in every shot destroys continuity. Audiences may not consciously notice, but they feel it immediately: the scene reads as a montage of unrelated clips rather than a story. For episodic content, brand mascots, explainer series, or anything with a recurring protagonist, consistency is the product.
There is a second bottleneck that compounds the first: motion quality. A model that nails identity but produces rubbery limbs or sliding feet will still fail. Strong pipelines solve both problems at once by giving the model more visual anchoring and less freedom to improvise.
How AI Animation Character Generators Actually Work
It helps to think of these systems as three cooperating layers rather than a single model. Different products package the layers differently, but the anatomy is broadly the same.
Conditioning: text, image, and pose
Conditioning is how you tell the system what to make. Text conditioning is the most flexible and the least precise — a paragraph can imply a character but rarely reproduces a specific face. Image conditioning supplies an actual reference: a portrait, a turnaround sheet, a rough sketch, or a previous frame. Pose or depth conditioning constrains the body, so you can control the silhouette without describing it in words.
The strongest character work usually stacks two or three conditioning types. An image reference carries identity, a short prompt carries style and action, and a pose hint carries staging. When drafts go wrong, the fix is almost always to add a conditioning channel rather than to write more adjectives.
Temporal modeling and identity drift
Video models add a temporal layer that predicts how frames relate to one another. Early implementations simply blended neighboring frames, which looked smooth but smeared detail. Modern approaches use attention across time, which preserves texture better but can still let identity wander over long durations.
A useful rule of thumb: the longer the clip, the more identity drifts. A four-second shot is easy to keep clean. A twenty-second continuous shot will usually require keyframing, re-anchoring, or splitting into shorter beats. Designing your storyboards around that constraint costs nothing and saves hours of repair work later.
Style transfer without losing the character
Style transfer applies a visual language — ink line, cel shading, clay, painterly oil — to generated output. The trap is applying it so aggressively that the character's identity disappears into the aesthetic. Keep style and identity as separate controls: fix the character first in a neutral render, then push style in a second pass with the character reference still attached. This ordering makes regressions far easier to spot.
Choosing the Right Model for the Job
Not every generator is built for the same task. Broadly, you will meet two families.
Character-first tools versus cinematic video models
Character-first tools prioritize a reusable identity: you create or upload a character, store it, and then reuse it across many generations. They tend to be excellent for series, mascots, and talking-head content, and weaker at complex camera work.
Cinematic video models prioritize motion, lighting, and camera language. They produce gorgeous establishing shots and action beats, but they treat each generation as a fresh interpretation unless you feed them strong references. Many teams use both: character tools for recurring identity, cinematic models for spectacle, with the edit tying them together.
Four specs that decide your pipeline
- Reference capacity. How many images can you supply at once? Two or three references (front, three-quarter, profile) dramatically outperform one.
- Clip length. Longer maximum durations invite drift. Shorter limits force good storyboarding habits.
- Motion range. Some models excel at subtle acting, others at running and fighting. Match the model to the shot.
- Output resolution and aspect ratio. Vertical social formats and wide cinematic formats often need different upscaling paths.
Test these four against a single test scene before committing a project to any tool. Spend an hour on the comparison; it will save you a week.
Build a Character Bible Before You Generate Anything
The single highest-leverage habit in AI character animation is writing a character bible. It is a short document, five to ten minutes of work, that pays for itself within the first hour of generation.
Reference sheets and turnaround views
Produce or commission a turnaround: front, side, three-quarter, and back views of the character in a neutral pose with flat lighting. Add two expression variants — one calm, one heightened — and one full-body action pose. Save these as clean, tightly cropped images with consistent framing. Models read cropped, well-lit references far more accurately than busy composition boards.
Prompt blocks, palettes, and negative lists
Next, write a reusable prompt block. Keep it under about forty words so it does not crowd out the action description. Include hair, skin, costume silhouette, a signature accessory, and an overall art direction. Then fix a color palette of four to six hex values so lighting changes do not drift the costume color.
Finally, build a negative list. Typical entries: extra fingers, deformed hands, warped face, text overlays, watermark, sudden costume change, inconsistent eye color. Negative terms are not a cure, but they reduce the frequency of the most common failures.
A Repeatable Text-to-Video Workflow
Here is a workflow that scales from a thirty-second short to a multi-episode series.
Lock the look with a hero still
Start with still generation only. Produce ten to twenty candidate portraits, then choose one hero image. This is your anchor: every subsequent generation references it. Do not move to video until the hero still is genuinely on-model, because video models amplify whatever mistakes exist in the reference.
Animate short beats, not whole scenes
Break each scene into beats of two to five seconds: an entrance, a reaction, a turn, a line of dialogue, an exit. Generate each beat separately using the hero still plus one secondary reference. Short beats keep identity tight, make retries cheap, and give you editorial flexibility that a single long generation never provides.
Keyframe the transitions with multi-image fusion
When two beats must connect seamlessly, use a first-and-last-frame workflow: supply the ending frame of beat one as the starting frame of beat two, or hand the model both endpoints and let it interpolate the motion. This technique removes the jump cut problem and keeps costume details aligned across the splice.
Assemble and stabilize in the edit
Bring every beat into an editor. Trim to the strongest frames, add subtle speed ramps to smooth motion hiccups, and use stabilization or minor tracking where the camera drifts. A light grain pass or a shared color grade across all clips hides the small inconsistencies that survive generation and makes the sequence feel like one continuous film.
Image-to-Video and Multi-Image Keyframing in Practice
Image-to-video is the workhorse technique for character animation because it offloads identity to the reference and motion to the prompt. In practice, three patterns cover most needs.
Single-reference animation. One portrait, one motion prompt. Ideal for subtle acting: a blink, a head turn, a small hand gesture. Keep camera movement minimal here; ask the model to move the character, not the lens.
Dual-reference interpolation. Two images of the same character in different poses, with the model generating the in-between motion. This is the fastest way to build a walk cycle or a costume change, and it is dramatically more consistent than describing the movement in text.
Reference plus pose hint. A character image plus a rough pose or depth sketch. Use this when the action must hit a specific silhouette — a punch, a jump, a dance move — and text alone keeps missing the staging.
A practical tip: when interpolation produces a morph or a smear, shorten the distance between the two keyframes. Two intermediate frames with a small gap almost always beat one frame with a large gap.
Mistakes That Break AI Character Animation
These are the failures that show up again and again, along with the fix for each.
- Long single-shot generations. Fix: split into beats of a few seconds and stitch in the edit.
- One reference image. Fix: supply front, three-quarter, and profile views simultaneously.
- Overloaded prompts. Fix: keep the character block short and put action, camera, and lighting in a separate sentence.
- Conflicting style words. Fix: choose one art direction per project and remove contradictory descriptors.
- Ignoring the background. Fix: describe the environment explicitly, or the model will invent one that fights your costume palette.
- No version control. Fix: name every generation with character, scene, and beat identifiers so you can compare and roll back.
- Skipping the still stage. Fix: never animate a reference you would not put in a poster.
Stylized Versus Photoreal: Two Different Pipelines
Photoreal characters demand the tightest references, since every viewer has a lifetime of experience reading human faces and will spot a millimeter of asymmetry. Expect to spend most of your time on skin texture, eye highlights, and micro-expressions, and expect to discard more generations per usable second.
Stylized characters — anime, comic, 3D cartoon, stop-motion look — are more forgiving because the visual grammar is already abstracted. Line weight and shape language carry identity more than pore-level detail does. That makes stylized animation an excellent starting point for teams learning the workflow, and it is usually where you can push expression and exaggeration hardest without breaking believability.
A hybrid approach works well for branded content: photoreal environments with a stylized protagonist. The contrast reads as intentional design rather than as an artifact.
Quality Control Before You Deliver
Run a fixed checklist on every finished sequence rather than eyeballing it. Check identity first — face shape, eye color, hairline, signature accessory — across every shot, ideally by pulling a still from each clip and viewing them as a contact sheet. Then check costume color and silhouette, then hand anatomy, then background continuity, then motion smoothness at normal playback speed.
View the sequence once muted, so you judge rhythm and continuity without dialogue masking a jump. Then view it on a phone screen; small inconsistencies that vanish on a monitor often become obvious at thumbnail scale.
Keep a running failure log. Two or three entries about which prompt phrasing or reference combination caused drift will turn your next project into a much faster one.
FAQ
How many reference images do I actually need?
Three is the sweet spot for most models: front, three-quarter, and a full-body or action pose. More than five rarely helps and can confuse the model about which features matter.
Why does my character look right for two seconds and then change?
That is classic drift. Shorten the clip, add a second reference, or use first-and-last-frame conditioning so the model has an endpoint to aim for.
Can I reuse a character across an entire series?
Yes, and this is where the workflow pays off. Keep the hero still, the prompt block, and the palette in a shared folder. Every new episode starts from the same anchors, so a new artist or editor can reproduce the look without guesswork.
Do I need to learn animation principles?
Basic principles — anticipation, squash and stretch, timing, arcs — make your prompts and your keyframe choices much better. You do not need formal training, but an hour of study improves output more than an hour of prompt tweaking.
What about dialogue and lip sync?
Generate the performance first, then align dialogue in post. When lip sync matters, keep the head relatively still, frame the character in a medium or close shot, and drive the mouth with a dedicated lip-sync pass rather than hoping the video model resolves it.
How do I handle camera movement without losing identity?
Move the camera slowly, prefer simple moves like a dolly or gentle push-in, and keep the character large in frame. Fast cuts and whip pans are where drift spikes fastest.
Is it worth building a custom character at all?
If you are producing one clip, no — a strong prompt and a good reference image will do. If you are producing anything recurring, absolutely. The setup cost is small and the consistency gain is large.
Putting It Together
The through-line in all of this is anchoring. Every technique here — turnarounds, short beats, keyframe interpolation, strict negative lists, a shared color grade — exists to give the model less room to improvise and more reason to stay on-model. Treat the generator as a talented animator who has never met your character, and your job becomes obvious: introduce the character properly, give clear direction, and review the work in small pieces.
Start with one character, one scene, and five beats. Lock the hero still, animate three seconds at a time, splice with keyframes, and grade the result as a single sequence. Once that pipeline feels routine, scale it: more episodes, more characters, more complex staging. Consistency stops being a stroke of luck and becomes a repeatable process you control.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.