
AI Avatar Video Generator: Build Custom Digital Personas
Oct 15, 2026
Why Custom Digital Personas Changed Video Production
For most of video history, putting a person on camera required a person. A script needed a presenter, a camera, a room with decent light, and a schedule that aligned everyone's calendar. That constraint shaped what got filmed: talking-head explainers, training modules recorded on a laptop webcam, marketing videos rewritten to fit whoever happened to be free that afternoon. AI avatar video generators remove that constraint. Instead of booking a shoot, you design a persona once — face, voice, wardrobe, tone — and then generate as many videos as you need from that identity.
The important word is "identity," not "clip." Early synthetic presenters looked like puppets: stiff mouths, glassy eyes, a half-second lag between audio and expression. Modern pipelines have moved past that by treating the avatar as a persistent digital character rather than a one-off visual effect. When it works, audiences do not sit there judging photorealism. They judge whether the person on screen holds attention and communicates clearly. Photorealism is one route to that. Strong writing, confident pacing, and consistent character design are others — and they are frequently more reliable than chasing pixel-perfect skin texture.
This guide covers how avatar generation works under the hood, how to pick the right approach for a given project, and a repeatable production workflow you can run for one video or a fifty-episode series. It also covers the parts most tutorials skip: consistency, disclosure, and the small directing decisions that separate a watchable avatar from an unsettling one.
How an AI Avatar Video Generator Actually Works
Most people interact with these tools as a black box: upload a photo, paste a script, click generate. Understanding the three underlying systems makes you dramatically better at troubleshooting, because you will know which lever to pull when something looks wrong.
Neural rendering and expression transfer
Neural rendering is the core technique. A model analyzes facial geometry, skin tone, hair behavior, and the subtle asymmetries that make a face read as human. It then maps those features onto a driving signal — usually audio, sometimes a reference performance video — to produce mouth shapes, blinks, brow movement, and head motion.
The quality ceiling here comes from two places. First, the reference material: a soft, low-resolution selfie gives the model very little structure to work with, so the output looks smoothed and generic. Second, the driving signal: clean audio with consistent volume and minimal background noise produces far more accurate lip sync than a recording with a noisy room and fluctuating levels. If your generated video has drifting mouth shapes, the problem is usually audio, not the model.
Reference-image fusion and identity consistency
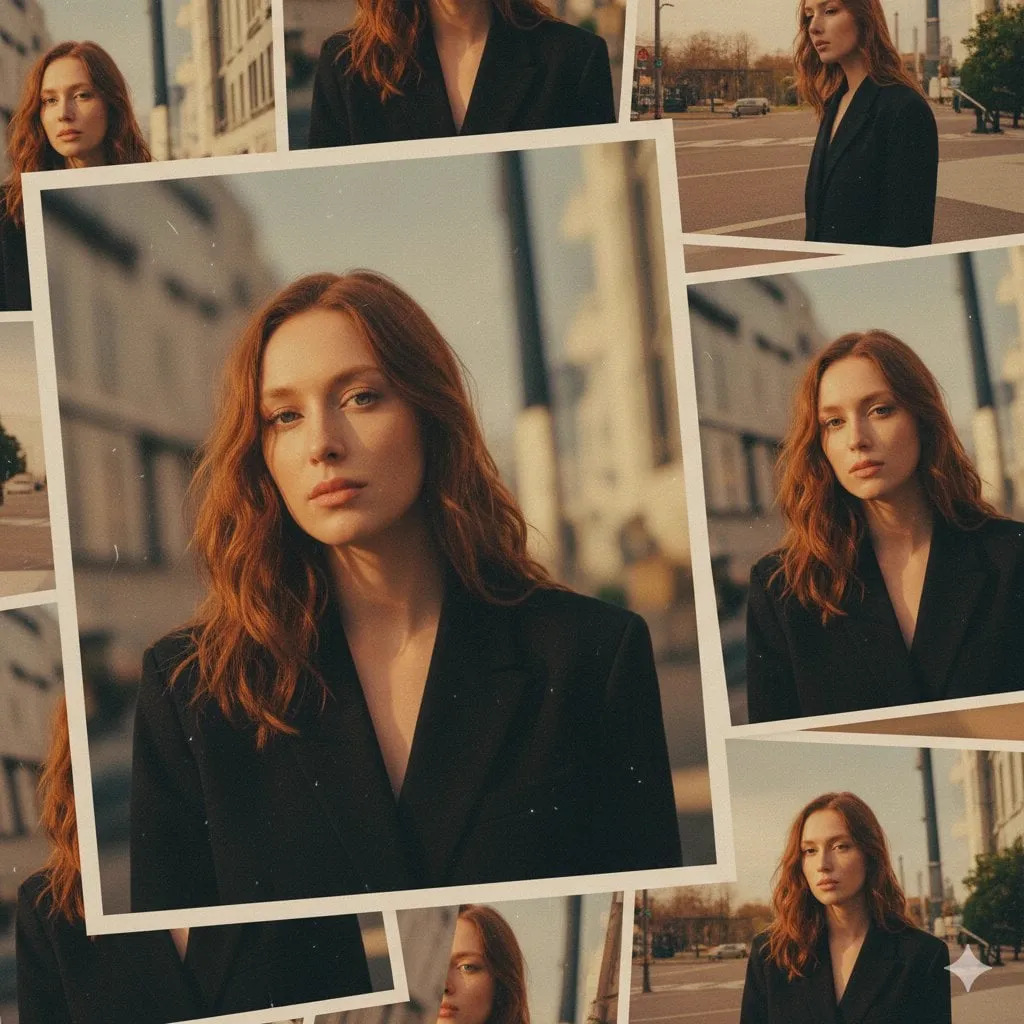
One reference photo is enough to make an avatar. It is rarely enough to make a consistent avatar. Multi-image fusion takes several references — different angles, expressions, and lighting conditions — and blends them into a single unified identity model. That model is what keeps the character's nose, jawline, and eye spacing stable when you switch from a studio background to a park bench.
A practical rule: five to twelve references beats one perfect photo. Include a frontal shot, a three-quarter angle, a profile, a smiling frame, and a neutral frame. Avoid heavy filters, sunglasses, extreme shadows, or anything that hides the structure of the face. If you plan to reuse the persona across many videos, treat this reference set as an asset you maintain, not a one-time upload.
Scene, style, and camera control
Separate from the character model is the environment model. This layer handles backgrounds, lighting direction, depth of field, and framing. Good tools let you change scene without rebuilding the avatar, which is what makes rapid iteration possible: same presenter, new set, ninety seconds of work instead of a half-day reshoot.
Camera language matters more than most creators expect. A slow push-in reads as sincerity. A static medium shot reads as instructional. A slight handheld drift reads as documentary. If your tool exposes shot type, use it deliberately — varying shot type between sections is one of the cheapest ways to make a long video feel edited rather than generated.
Choosing the Right Avatar Approach for Your Project
Not every project wants a photoreal human. The choice of avatar style is a strategic decision about trust, budget, and how the audience will feel about synthetic media.
Photoreal presenter avatars
Best for corporate explainers, product walkthroughs, internal training, sales enablement, and news-style updates. Photoreal presenters borrow credibility from familiarity — viewers relax because the format is recognizable. The tradeoff is that any imperfection is more noticeable. If the mouth shape is slightly off, viewers will notice it precisely because everything else looks real. Photoreal avatars demand clean writing, clean audio, and modest shot lengths.
Stylized and illustrated characters
Best for education, gaming, children's content, and brands with a strong visual identity. A stylized avatar sets expectations differently. Viewers accept exaggeration, so small imperfections disappear. Stylized characters also age better — an illustrated mascot does not look dated the way a hyperreal render from five years ago does.
Voice-first versus face-first production
Some projects need a face; others need a voice and a screen recording. Ask what the audience actually requires. A software tutorial usually works better as a screen capture with a synthetic narrator than as an avatar gesturing at a monitor. A compliance module often benefits from a face because the human presence increases retention. Match the format to the job, not to the novelty of the technology.
A Practical End-to-End Workflow
The workflow below is what a sustainable avatar production pipeline looks like in practice. It is deliberately front-loaded — most of the work happens before you generate anything.
Step 1: Write for the ear, not the page
Read your script out loud. Anything you stumble over will sound wrong coming from an avatar. Cut subordinate clauses, replace nominalizations with verbs, and keep sentences under about twenty words. Write numbers the way you want them spoken ("fourteen hundred," not "1,400") and spell out abbreviations the first time.
Break the script into blocks of two to four sentences. Short blocks give you granular control: if one line generates badly, you regenerate five seconds instead of the whole section. They also make editing far easier later.
Step 2: Build the reference set and lock the identity
Assemble your reference images, generate the base avatar, and then test it before committing. A useful test: generate three short clips in three different scenes — a neutral office, a warm outdoor setting, and a dark studio — and compare them side by side. If the face drifts, your reference set needs work. Fixing this now saves hours later.
Step 3: Choose or clone a voice
Use a stock voice only after listening to it reading your script, not the demo line. Stock voices are recorded to sell themselves and often sound more energetic than they do on dense technical copy. If you clone a voice, make sure you have explicit written permission from the speaker and confirm the tool's consent requirements. Voice cloning without documented permission is a legal risk, not a gray area.
Adjust rate slightly below default for technical content — a slower pace gives viewers a moment to process. Raise pitch variation a touch if the delivery sounds flat.
Step 4: Generate in short blocks and review immediately
Generate block by block and review in one pass with sound on. You are checking four things: lip sync accuracy, pronunciation of names and technical terms, emotional tone, and whether blinks and head movement look natural. Fix problems at the block level rather than trying to patch them in the edit.
Step 5: Assemble, caption, and export
Bring the blocks into an editor. Add small cuts for pacing, insert B-roll or screen recordings over long stretches of talking head, and layer on captions — many viewers watch muted. Export at the highest resolution your platform supports, then verify the file plays correctly on a phone before publishing.
Directing the Avatar: Getting Natural Delivery
Delivery is where amateur avatar videos and professional ones diverge most sharply. Three levers do most of the work.
Punctuation is direction. A period is a full stop. An ellipsis is a hesitation. A comma is a breath. If you want emphasis, break the sentence into a shorter one instead of adding exclamation marks, which most synthesizers interpret as volume rather than intensity.
Vary shot level. Alternate between a wider framing and a closer one every thirty to forty-five seconds. Monotony is the real enemy of an AI presenter; the viewer's eye needs something to reset on.
Write pauses into the script. Blank lines, stage directions like a beat of silence, or a deliberate change of subject all give the model a place to breathe. Continuous narration with no breaks is what makes synthetic presenters feel robotic — not the rendering.
Consistency Across a Series: Build a Persona Kit
If you are producing more than a few videos, formalize the persona. A persona kit is a folder that contains the reference images, the voice profile and its settings, the prompt fragments that produce the character reliably, a color-graded wardrobe reference, the intro and outro templates, and a one-page brand note covering tone and forbidden phrasings.
Three practical benefits come out of this. First, anyone on your team can produce a video that matches the series. Second, you can hand the kit to an editor or freelancer without a two-hour onboarding call. Third, if a tool changes or you switch providers, the kit is portable — you are not locked into one platform's character format.
Review the kit every few months. Faces drift as reference images get replaced piecemeal, and a persona that slowly changes weight or hair color across a series is more distracting than an obvious cut.
Common Mistakes and How to Avoid Them
- Overwriting the script. Long, clause-heavy sentences are the number-one cause of unnatural delivery. If the avatar sounds robotic, rewrite before you re-render.
- Using one bad reference photo. Low light and extreme angles create generic-looking results. Collect references properly.
- Ignoring audio quality. Background hum and uneven levels wreck lip sync. Record or generate clean audio first.
- Rendering the entire video at once. You lose the ability to fix individual lines and you waste time on failed generations.
- Never showing anything but a face. Talking-head fatigue is real. Cut to screen recordings, diagrams, or B-roll every twenty to thirty seconds.
- Forgetting disclosure. Audiences tolerate synthetic presenters; they do not tolerate being deceived about it.
- Skipping captions. A large share of viewers watch without sound, especially on social platforms.
- Mixing uncanny and stylized elements. A photoreal face in a cartoon environment rarely works. Keep the realism level consistent across the whole frame.
Ethics, Disclosure, and Rights
Synthetic media carries obligations that are easy to overlook when you are moving fast.
Consent. Never clone a voice or likeness without documented permission from the person involved. If the subject is a public figure, be especially careful — using a recognizable person to endorse something they have not endorsed is a serious problem regardless of intent.
Disclosure. Add a short on-screen note or a line in the description indicating that the presenter is AI-generated. In many jurisdictions, disclosure rules for synthetic media are tightening, and in all of them, transparency protects your reputation.
Accuracy. An avatar delivering a script sounds authoritative. That authority makes errors more damaging. Fact-check technical claims, numbers, and names before publishing.
Rights to training material. Only use reference images and audio you own or are licensed to use. Scraping a stranger's photos off the internet to build a persona is both an ethical and a legal problem.
Use Cases That Pay Off Fast
Avatar video earns its keep in situations where volume and consistency matter more than novelty.
Localized versions of one video. Generate the same presenter speaking multiple languages. This is often the highest-return application, because it converts a single production into many market-ready assets.
Evergreen training content. Compliance modules, onboarding sequences, and safety briefings need periodic updates. Regenerating two sentences beats rebooking a shoot.
Social variants at scale. Produce vertical cuts with different hooks for A/B testing. Because the presenter is reusable, testing ten hooks costs marginally more than testing one.
Product documentation. Short feature explainers that would never justify a film crew become viable when production takes an afternoon.
Personalized outreach. Named, tailored video messages for high-value prospects, where the presenter stays the same and only the script changes.
FAQ
How many reference images do I need for a consistent avatar?
Five to twelve well-lit images covering several angles and expressions. More is not automatically better — inconsistent references (different ages, weights, or hairstyles) hurt more than they help.
Why does my avatar's lip sync drift?
Usually audio. Check for background noise, uneven volume, or a sample rate that does not match what the tool expects. Re-record or clean the audio before assuming the model is at fault.
Can I use an AI avatar for commercial work?
Generally yes, if you own or have licensed the reference material and the voice, and you comply with the platform's terms. Confirm the licensing terms in writing and keep records of consent for cloned voices.
Do I need to tell viewers the presenter is synthetic?
Disclosing is strongly recommended and increasingly required. A simple caption or description note is enough in most contexts.
Is a stylized avatar less effective than a photoreal one?
Not inherently. Stylized avatars often perform better in education and entertainment, where audiences accept exaggeration and imperfections are less visible.
How long should an avatar video be?
Match length to purpose: sixty to ninety seconds for social, three to five minutes for explainers, and as long as the material requires for training — but break anything past eight minutes into chapters.
What is the fastest way to improve quality?
Rewrite the script for spoken rhythm, clean the audio, and shorten each generation block. Those three changes fix the majority of "uncanny" output.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.