
AI Video Generator Workflow: From Images to Polished Video
Oct 15, 2026
Why AI Video Generation Became a Normal Part of Production
Video has always been the format with the highest cost per finished minute. A single product spot can involve scripting, casting, location scouting, lighting, editing, color work, sound design, and several rounds of review. That math pushes most teams toward one polished video per quarter and a shelf full of ideas that never get made.
Generative video changes the ratio. Instead of budgeting for a shoot, you budget for iteration. A marketer can draft six different openings for the same product story. A solo creator can storyboard an entire series before committing to a visual style. A small studio can present a moving pre-visualization to a client in an afternoon instead of a week.
The important shift is not that AI replaces production. It is that AI moves the expensive decisions later. You can decide what a video should look like after you have watched it move, which is far more reliable than deciding from a static board. Teams that treat generation as a prototyping layer — and keep humans on story, taste, and final polish — get dramatically more usable output than teams that expect a finished film from one prompt.
This guide is about the workflow, not the hype. It covers how these systems actually generate frames, when to use text-to-video versus image-to-video, how to build a repeatable pipeline, where people usually go wrong, and how to choose a tool without locking yourself into a single vendor.
How AI Video Generators Actually Work
It helps to understand the machine at a conceptual level, because most practical fixes come from that understanding. Nearly every modern system combines a few building blocks.
Frames as a prediction problem
A generator does not "know" what a car looks like. It learned statistical patterns from huge volumes of images and video. Given a starting state, it predicts what the next visual state should be, then repeats. Diffusion models start from noise and progressively remove it, guided by your prompt and any reference images. The result is a sequence of frames that look plausible because each one is consistent with the patterns the model absorbed.
Temporal coherence is the hard part
Generating a beautiful single frame is a solved problem. Generating 120 frames where a face, a jacket logo, and a background stay recognizably the same is where the engineering lives. Systems handle this in several ways:
- Temporal attention layers let the model look at neighboring frames while generating the current one, so motion flows instead of jumping.
- Latent-space interpolation keeps the video in a compressed representation and interpolates smoothly between key states rather than generating every frame from scratch.
- Keyframe conditioning anchors specific moments. You define frame one and frame ninety, and the model fills the space between them.
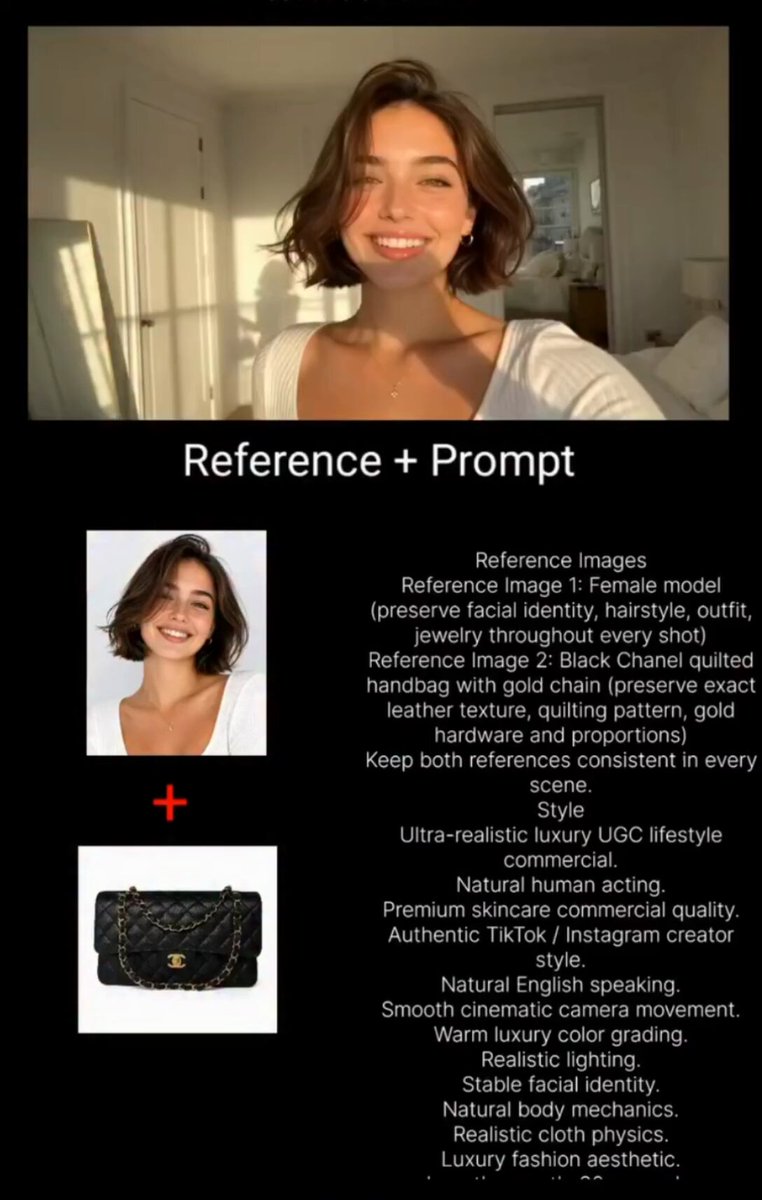
- Reference locking uses an uploaded image — a character sheet, a product photo, a style board — as a persistent constraint across the whole clip.
Conditioning: how your input steers the output
Your prompt and images are not commands; they are constraints. Text conditioning describes subject, action, camera, and mood. Image conditioning describes appearance. Motion conditioning describes how things should move. When output disappoints, it is usually because one of these three channels was vague or contradictory. Saying "cinematic" and "flat documentary lighting" in the same prompt produces mush, not a compromise.
One more concept worth internalizing: resolution and duration are usually traded against coherence. Long clips with many moving subjects are harder to keep stable than short clips with one subject and a slow camera. If a shot keeps breaking, the fastest fix is often to shorten it and generate the rest of the scene separately.
Text-to-Video vs Image-to-Video vs Hybrid
These are three different tools for three different jobs, and choosing correctly saves more time than any prompt trick.
Text-to-video
Best when you are exploring. You have a concept but no visual assets. Use it for mood tests, style discovery, and rough animatics. Weakness: you get whatever interpretation the model prefers, so brand-specific details drift.
Image-to-video
Best when appearance matters. You supply a product shot, a character design, or a location plate and ask for motion. This is the workhorse for e-commerce, explainers, and social storytelling because the visual identity is fixed before generation begins.
Hybrid, keyframe-driven
Best for narrative. You generate or source two to four anchor images, then let the model fill the transitions between them. This gives you editorial control — you decide the beats — while the model handles the motion in between. For anything longer than fifteen seconds, this is the approach that scales.
A simple decision rule: if the viewer must recognize a specific product, person, or logo, start from images. If the viewer only needs to feel a mood, start from text.
A Repeatable Production Workflow
The gap between a fun demo and a usable pipeline is process. Here is a workflow that holds up across short ads, social clips, and narrative pre-visualization.
Step 1: Write a shot list, not a script
Before touching a generator, write what the camera sees. Six to ten shots for a thirty-second piece is a reasonable density. Each line should include subject, action, camera movement, and duration. Example: "Shot 3 — hands open the box, slow push in, 3 seconds, soft daylight." This single habit eliminates most wasted generations, because you know what you are judging before you generate it.
Step 2: Prepare reference images properly
Garbage in, drift out. Reference images should be:
- Clean — remove watermarks, collages, and heavy text.
- Well lit — flat, evenly exposed images condition more reliably than dramatic ones.
- Consistent in aspect ratio — mixing portrait and landscape references confuses framing.
- Limited in count — two to four strong references usually beat ten mediocre ones.
If you need a recurring character, build a small reference set: one full-body, one close-up, one three-quarter view. That set becomes your consistency anchor across every shot.
Step 3: Prompt motion, not just content
Most weak prompts describe a still image. Strong prompts describe change over time. Compare:
- Weak: "a coffee cup on a wooden table, cinematic"
- Strong: "slow dolly-in on a ceramic coffee cup on a wooden table, steam rising and drifting left, warm morning light shifting across the rim, shallow depth of field, 4 seconds"
The second version tells the model what should be different at the end of the clip compared to the start. That difference is the video.
Useful prompt components, roughly in order of impact: subject and action, camera move, lighting direction, environment motion, pace, and style reference. Keep style references to one or two. Stacking five aesthetic adjectives produces an average of all five, which reads as generic.
Step 4: Generate in small batches and judge fast
Generate three to five variations rather than twenty. Watch each clip twice: once for subject integrity, once for motion quality. Score them on a simple three-point checklist — is the subject stable, is the motion plausible, does it match the shot list. Anything failing two of three gets discarded without regret. Iterating on a broken clip is almost always slower than regenerating with a clearer prompt.
Step 5: Assemble, then fix rhythm
Raw generated clips rarely cut together well on the first pass, because each one has its own internal pacing. In the edit:
- Trim the first and last few frames of each clip; models often produce a soft start and a drifting end.
- Cut on motion. If a subject moves right, cut to a shot that continues the motion rather than fighting it.
- Use speed ramps to rescue clips that are slightly too slow rather than regenerating.
- Add one deliberate transition style and stick to it. Mixed transition styles are the fastest way to make AI footage look like a highlight reel.
Step 6: Sound locks the illusion
Audio carries more perceived production value than image quality. Add ambience first (room tone, wind, traffic), then foley (footsteps, cloth, clicks), then music, then voice. A modest clip with layered sound reads as professional. A technically impressive clip with silence reads as a test render.
Step 7: Grade for unity
Generated clips from different prompts will not match in color temperature or contrast. Apply one look across the whole timeline — a subtle curve, a slight desaturation, a consistent white balance — and the sequence suddenly feels like it was shot by one crew. This takes minutes and changes everything.
Working With Multiple Images and Keyframes
Fusing several images into one scene is one of the most practical capabilities in modern generators, and it is worth understanding where it shines.
- E-commerce — combine front, side, and detail shots into a single rotating product sequence so the viewer sees the object from several angles without a hard cut.
- Storyboarding — turn concept art panels into animated previews so stakeholders can judge pacing, not just composition.
- Real estate and interiors — merge room photos into a walkthrough with continuous motion along a plausible path.
- Character work — hold a design sheet as a reference so a character stays the same across unrelated shots.
A few habits make fusion behave:
- Match perspective and lighting across the source images. A top-down shot and an eye-level shot will produce a strange warp between them.
- Keep the subject in roughly the same position in the frame so motion between images reads as camera movement rather than teleportation.
- Describe the transition in the prompt — "smooth arc around the object", "gradual push in" — so the model has a motion target.
- Keep the image count low. Three well-matched images outperform eight loosely related ones.
For keyframe-driven work, define the emotional beats first and generate frames for those, then interpolate. It is far easier to fix a bad transition than to fix a story that only exists as a vague prompt.
Building a Custom Style (Without Overengineering)
Style consistency is what separates a channel from a pile of clips. You do not need to train a model to get there, but training becomes worthwhile when you have a repeatable look and volume demands it.
Start with a style guide instead of a training run. Write down five attributes that define your look: palette, contrast, lens character, motion energy, and typical framing. Then encode them into a prompt template you reuse for every shot. Most creators find that a disciplined template delivers eighty percent of the consistency benefit at one percent of the effort.
When you do move to custom training, apply these criteria before committing:
- Volume — are you producing enough clips that per-shot consistency time is a real bottleneck?
- Rights — do you clearly own or license every image in the training set?
- Diversity — does the set cover the poses, angles, and lighting conditions you actually need?
- Evaluation — can you measure whether the trained result is better, or will you be judging by vibes?
Practical alternatives to full training include reference locking, consistent prompt templates, generating a small library of approved style frames, and using the same seed across related shots. These are cheaper, faster, and easier to reverse.
Common Mistakes and How to Fix Them
Chasing photorealism on every project. Photoreal generation is the most brittle setting. Stylized looks — illustration, clay, paper craft, retro print — hide small artifacts and often read better on mobile. Choose the style your pipeline can actually sustain.
Writing a paragraph of conflicting adjectives. The model averages your descriptors. Pick a lane: either soft natural light or hard directional light, either handheld energy or locked-off precision.
Generating long before generating short. Get a three-second shot right before attempting a twelve-second one. The techniques that make a short clip work are the ones you will reuse.
Ignoring the first and last frames. Most drift happens at the edges. Trim them, or generate with explicit start and end anchors.
Treating the first output as final. The realistic ratio is five to fifteen generations for one usable shot. Budget for it emotionally and in your schedule.
Skipping the edit. A timeline with cuts, sound, and a grade can elevate mediocre footage. No amount of generation quality survives a raw dump of clips with no rhythm.
Using unclear source material. Blurry, watermarked, or mismatched references are the single most common cause of unusable output. Fix the input before rewriting the prompt a tenth time.
Forgetting the audience context. Vertical, muted, three-second-hook viewing changes what works. Design for the smallest screen first and adapt upward.
Choosing a Tool: A Practical Checklist
Feature lists are easy to write and hard to compare. Judge tools against your actual pipeline instead.
- Input flexibility — does it accept text, single images, multiple images, and video references?
- Consistency controls — can you lock a character, a product, or a style across separate generations?
- Duration and resolution — what is the longest clip that stays coherent, and at what output size?
- Iteration speed — how quickly can you see five variations? Speed of feedback matters more than peak quality.
- Commercial rights — can you use the output in paid advertising, and are the terms clear in writing?
- Export format — codec, frame rate, and alpha channel support if you composite.
- API or batch options — relevant if you are producing volume or automating a template.
- Privacy — do your uploads stay private, and what happens to them?
A useful test: take one real shot from your next project and run it through two or three tools in the same afternoon. Compare the usable-shot rate, not the best single frame. The tool with the higher hit rate wins, even if its showreel is less flashy.
Publishing, Repurposing, and Measuring
Generated video is cheap enough that distribution strategy becomes the bottleneck. Plan for repurposing from the start.
- Master at the highest quality you can, then cut down. Vertical shorts, square social versions, and a horizontal hero piece can all come from one timeline.
- Vary the hook, not the body. Reuse the same core thirty seconds with three different first three seconds and measure which opening holds attention.
- Caption everything. A large share of viewing happens muted, and captions also improve retention and accessibility.
- Track completion rate, not views. Views measure the thumbnail; completion measures the video.
Compare results by shot archetype, not just by campaign. Over time you learn that, for your audience, a slow push-in on a product outperforms a spinning hero shot. That knowledge is more valuable than any prompt library, because it tells you what to generate.
FAQ
How long does it take to produce a thirty-second AI video?
With a shot list, prepared references, and a working tool, a realistic timeline is two to four hours for generation and selection, plus two to three hours for editing, sound, and grading. The first project takes longer because you are learning your tool's quirks.
Do I need to train a custom model for consistent characters?
Usually no. A small reference set plus consistent prompt templates and the same seed gets you most of the way. Consider training only when volume makes per-shot consistency work a genuine bottleneck and you have a clean, rights-cleared dataset.
Why does my subject change appearance between shots?
Because each generation is independent unless you anchor it. Use the same reference images, keep the same prompt template, avoid changing aspect ratio mid-project, and lock a seed value when the tool supports it.
Is text-to-video or image-to-video better for product marketing?
Image-to-video, almost always. Your product must remain accurate, and text descriptions alone rarely preserve logos, materials, and proportions.
How do I stop clips from looking "AI generated"?
Three fixes do most of the work: trim the soft first and last frames, grade all clips with one consistent look, and add layered sound. Applying a single transition style also helps enormously.
What is the most common beginner mistake?
Prompting a still image instead of a change over time. If your prompt does not describe what is different at the end of the clip, the model has no reason to move anything.
Can I use generated footage commercially?
It depends on the tool's terms and your jurisdiction. Read the license, keep records of your source assets, and avoid uploading references you do not have rights to. When in doubt, use assets you created yourself.
How many generations should I expect per usable shot?
Plan for five to fifteen. Experienced users get closer to three to five on simple shots, but anything with hands, text, or complex motion will need more attempts.
Should I generate at final resolution immediately?
No. Iterate at a lower setting to find the right motion and framing, then regenerate the approved version at full quality. It is faster and cheaper in every sense.
What is the fastest way to improve output quality?
Improve your inputs. Better references, a written shot list, and prompts that describe motion will outperform any change of tool.
Where to Start This Week
The practical path is unglamorous. Pick one real project with a clear purpose. Write a six-shot list. Prepare three clean reference images. Generate three-second clips, trim the edges, cut them together with one transition style, layer ambience and one music bed, then apply a single grade. Publish it somewhere you can measure completion rate.
Do that once and you will have a repeatable pipeline rather than a folder of experiments. From there, the improvements compound: better references, calmer prompts, tighter edits, and a growing sense of which shot types your audience actually finishes watching. That combination — clear intent, controlled inputs, and disciplined post-production — is what turns AI video generation from a novelty into a reliable production tool.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.