
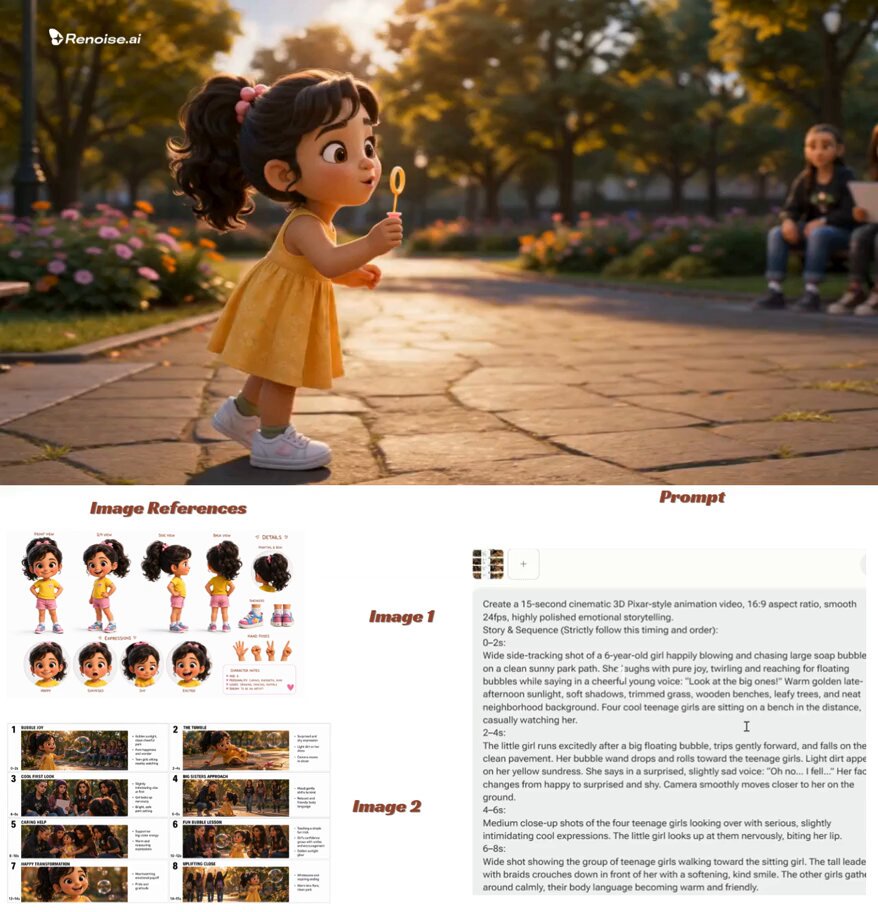
Character consistency is the hardest unsolved problem in AI video production. A model can render a breathtaking hero shot in seconds, then hand you a second shot where the same character has a different jawline, a slightly narrower face, and eyes that drifted two shades lighter. Audiences forgive soft focus and imperfect motion blur. They do not forgive a protagonist whose face changes shape between cuts.
Multi-shot image fusion is the technique that closes that gap. Instead of describing a character in words and hoping the model interprets those words the same way twice, you anchor generation to a small, curated set of reference images and let the pipeline carry identity across every scene. The words still matter — but they describe the scene, not the face.
This article walks through the underlying principles, the reference-set discipline that makes fusion work, keyframe control for believable motion, a complete production workflow, quality assurance scoring, common failure modes, and the decision criteria for choosing tools.
Why characters drift between shots
Diffusion-based video models do not store a character. They generate each frame by gradually denoising random noise, guided by text conditioning and, optionally, reference imagery. Identity is not a property the model holds; it is a tendency the model reproduces when the conditioning is strong enough.
Several forces push that tendency off course:
- Text conditioning is lossy. The phrase "a woman in her thirties with dark curly hair" maps to a broad region of the model's learned space, not a single point. Different random seeds land in different spots inside that region.
- Scene context leaks into appearance. Ask for the same character in a rain-soaked alley at night, and the model adjusts skin tone, contrast, and hair texture to fit the lighting. That is desirable realism, but it changes how the face reads.
- Motion priors override detail. When the model generates a turn, a run, or a fight sequence, it spends capacity on movement physics. Fine facial structure degrades first.
- Compression compounds. Every re-render, upscale, or format conversion shaves away small features. Over a ten-shot sequence, those losses stack.
The practical result: a text-only workflow rarely holds a character for more than two or three shots without visible drift. Image fusion exists to counteract exactly these four forces.
Separate identity from scene context
The core insight behind multi-shot image fusion is architectural, not cosmetic. You split the conditioning signal into two streams that never contaminate each other.
The identity stream
The identity stream carries what should not change: facial structure, hairline, eye color, skin tone, body proportions, signature wardrobe elements. It is expressed as images — a handful of clean, well-lit references — rather than adjectives. Images are far more information-dense than words, and crucially, they are stable. The same reference image produces the same feature embedding every time it is used.
The scene stream
The scene stream carries everything that should change: location, time of day, weather, camera angle, lens behavior, action, mood, and lighting direction. This is where text prompting belongs, and where you should be generous with detail. The richer the scene description, the less the model has to guess about the environment — and the less it will cannibalize the identity stream to fill gaps.
How fusion combines them
A fusion pipeline typically encodes each reference image into a feature representation, averages or weights those representations into a single identity anchor, then injects that anchor at specific layers of the generation network. Early layers handle structure and proportion; middle layers handle texture and color; later layers handle fine detail. Injecting too early produces stiff, pasted-on results. Injecting too late produces drift. Most mature pipelines blend across multiple stages and let you tune the balance.
Two guardrails matter. First, keep the number of references small — four to eight strong images beat twenty mediocre ones, because averaging weak signals blurs the identity into a generic face. Second, keep references internally consistent. If one reference has heavy makeup and another is bare-faced, the anchor lands between the two and matches neither.
Build a reference set that survives many shots
The reference set is the single highest-leverage asset in the entire workflow. Time spent here pays back across every downstream shot.
How many references are enough
For a character who appears in five to fifteen shots, aim for six to ten images:
- 2–3 frontal or near-frontal portraits at neutral expression
- 2 three-quarter views (left and right)
- 1–2 profile or extreme angle shots if the story requires them
- 1 full-body or waist-up frame to lock proportions and silhouette
- 1 emotional expression that reflects the character's dominant register
If the character only appears briefly, cut this to four: one frontal, one three-quarter, one full body, one expression.
Coverage beats quantity
A common mistake is supplying twelve beautifully lit studio portraits from the same angle. The model learns that angle perfectly and fails the moment the camera moves. What you want is angular and lighting variety around a single stable identity. Think of it as photogrammetry with a fraction of the images: enough viewpoints to infer the underlying face.
Lighting variety matters too, but within bounds. References shot in soft, even light generalize best. If every reference is dramatic chiaroscuro, the model bakes those shadows into the identity and reproduces them in a sunny meadow scene.
Clean before you feed
Before images enter the pipeline:
- Crop tightly to the subject; remove distracting background elements.
- Standardize resolution so no single reference dominates through pixel count.
- Remove watermarks, text overlays, and heavy filters.
- Check color balance. A yellow-cast reference will drag skin tone warm in every shot.
- Verify that the face is not blurred, tilted at an extreme, or partially occluded.
A ten-minute cleanup pass prevents dozens of wasted generations.
Keyframe control: the backbone of stable motion
Fusion locks who the character is. Keyframe control locks where the character goes. Together they make a shot sequence hold together.
Anchor the ends of a shot
Most modern video models accept a first frame, a last frame, or both. Anchor the first frame with a fused reference render — a still image of your character in the scene's opening pose. If the shot ends in a specific composition that the next shot continues from, anchor the last frame too. Interpolating between two identity-consistent anchors gives the model an enormous head start and dramatically reduces drift inside the shot.
Keep motion prompts about motion
When you write the motion prompt, spend your words on action, camera movement, and pacing — not on appearance. "Slow dolly-in as she turns her head to the left, wind moving her hair" is useful. "Beautiful dark-haired woman, curly hair, green eyes, 30s" repeats information the identity stream already supplies and creates competing conditioning that can pull the face.
Handle cuts, costume changes, and time jumps
Long sequences break consistency in predictable places:
- Hard cuts to a new location. Re-anchor with a fresh first frame built from the same fused identity, then let the scene prompt change.
- Costume changes. Update the wardrobe inside the reference set or, if the tool supports it, in a dedicated wardrobe block. Do not bury clothing changes in general scene text; the model will treat it as noise and may alter the face instead.
- Time jumps. Aging a character is a deliberate identity change. Create a second reference set and a second identity anchor rather than asking one anchor to stretch across twenty years.
- Crowd and interaction shots. When two or more fused characters share a frame, occlusion and blended features become likely. Generate the interaction, then repair the faces with a targeted pass.
A practical end-to-end workflow
Here is a repeatable sequence that keeps a multi-shot scene coherent.
1. Write the character bible. One page: age, build, hair, wardrobe, two or three defining features, and one line about how they carry themselves. This document governs every reference you select.
2. Assemble and clean the reference set. Follow the coverage rules above. Save the final set in a folder you never overwrite.
3. Render a neutral master portrait. Generate a clean frontal still at high resolution. This becomes your canonical identity check — every later shot is compared against it.
4. Build the shot list. For each shot, note location, action, camera move, duration, and whether it shares a frame with another character.
5. Generate opening keyframes. Produce a still for each shot using the fused identity plus that shot's scene prompt. Approve all stills before generating any video. Fixing a still costs seconds; fixing a video costs minutes.
6. Generate video in short increments. Two to four seconds per pass. Short passes keep the model close to the anchor and make re-rolls cheap.
7. Review at sequence level, not shot level. Play the shots back-to-back at normal speed. Drift that is invisible in isolation is obvious in sequence.
8. Repair, then assemble. Fix problem shots with targeted re-rolls, then edit. Do not color grade before consistency review — heavy grading masks the very differences you are hunting.
Quality assurance for multi-shot consistency
Ad hoc review misses slow drift. A lightweight scoring system catches it.
The five-point identity check
For each shot, compare against the neutral master portrait and score 1–5 on:
- Facial structure (jaw, cheekbones, brow)
- Eye shape and color
- Hairline and hair texture
- Skin tone and undertone
- Body proportion and silhouette
Any shot scoring 3 or below on structure or eyes gets regenerated. Texture and tone scores of 3 are usually salvageable in post.
Track drift direction
Log not just whether a shot drifted, but how. Consistent drift toward "younger" suggests a reference imbalance. Consistent drift toward "warmer skin" suggests a lighting mismatch in your anchors. Pattern-aware fixes are far faster than random re-rolls.
Decide: re-roll or re-anchor
A useful rule: if one shot is off, re-roll it. If three consecutive shots are off in the same way, stop rolling and rebuild the anchor. Repeated failures are almost always a conditioning problem, not a luck problem.
Common mistakes and how to fix them
| Symptom | Likely cause | Fix |
|---|---|---|
| Face changes every shot | Text-only conditioning, no fusion | Add a 6-image reference set and anchor keyframes |
| Face looks pasted on | Identity injected too strongly or too early | Lower fusion weight, shift injection later |
| Character ages between cuts | Reference set skews young or glamorous | Swap in neutral, age-appropriate references |
| Hair changes texture | Conflicting references | Remove outliers, standardize lighting |
| Features fade in motion shots | Model capacity spent on movement | Shorten passes, strengthen anchors, repair faces after |
| Two characters blend | Shared frame with both anchors | Generate separately, composite, or repair faces |
The pattern behind most of these: the identity signal is either too weak, too strong, or internally contradictory. Diagnose which of the three you have before changing anything else.
Choosing tools and building the pipeline
Not every generator needs to do everything. Evaluate on these criteria:
- Reference count and weighting. Can you supply multiple images and control their relative influence?
- Keyframe support. First frame, last frame, or both? Does interpolation respect identity?
- Consistency across separate generations. Does the same identity anchor produce the same character a week later, or does it drift with model updates?
- Iteration cost. How expensive is a two-second re-roll? High iteration cost forces you to accept bad shots.
- Export control. Resolution, frame rate, and codec options matter once you move into an editor.
A practical stack pairs one fusion-capable generator for identity shots, a general-purpose model for B-roll and establishing shots where no face is visible, and a dedicated face-repair pass for interaction scenes. Trying to force a single model to do all three usually costs more time than the split workflow.
FAQ
How many reference images do I really need?
Six is the practical sweet spot for a recurring character. Fewer than four leaves the identity under-constrained; more than ten rarely improves results and often blurs the anchor toward a generic face.
Can I reuse one reference set across multiple projects?
Yes, if the character recurs. Build a reusable identity library organized by project, with the neutral master portrait stored alongside the source references. It saves substantial setup time on sequels, series, and episodic formats.
Why does my character look right in stills but wrong in motion?
Stills give the model unlimited capacity for detail. Motion shots compete for that capacity. Shorten your generation passes, keep the camera move modest, and repair faces in a dedicated pass after the video is generated.
Do I need keyframe control if I have good references?
References control who; keyframes control where and how. References alone still allow pose and framing to wander across a long shot. For anything longer than three seconds, or any shot that must match an adjacent shot, keyframes are worth the extra step.
How do I handle a character who must age across the story?
Treat each era as a separate identity. Build one reference set per age range and switch anchors at the transition point. Trying to interpolate aging with prompt wording alone produces inconsistent, uncanny results.
What is the fastest way to fix one bad shot?
Rebuild the opening keyframe from the fused identity, re-anchor, and generate a short two-second pass. This is almost always faster than re-rolling with the same flawed anchor.
The bottom line
Consistent characters in AI video are not a prompting trick. They are the output of a system: a clean, well-covered reference set; a strict separation between identity and scene conditioning; keyframe anchors at the boundaries of every shot; short generation passes; and a sequence-level review that catches slow drift before it reaches the edit.
Build those habits once and they scale. A series, a product narrative, or a multi-episode story all depend on the same foundation — an audience that recognizes the same face in every frame.
