
Create
AI Avatar Photo and Video Generators: A Practical Workflow Guide
Oct 15, 2026
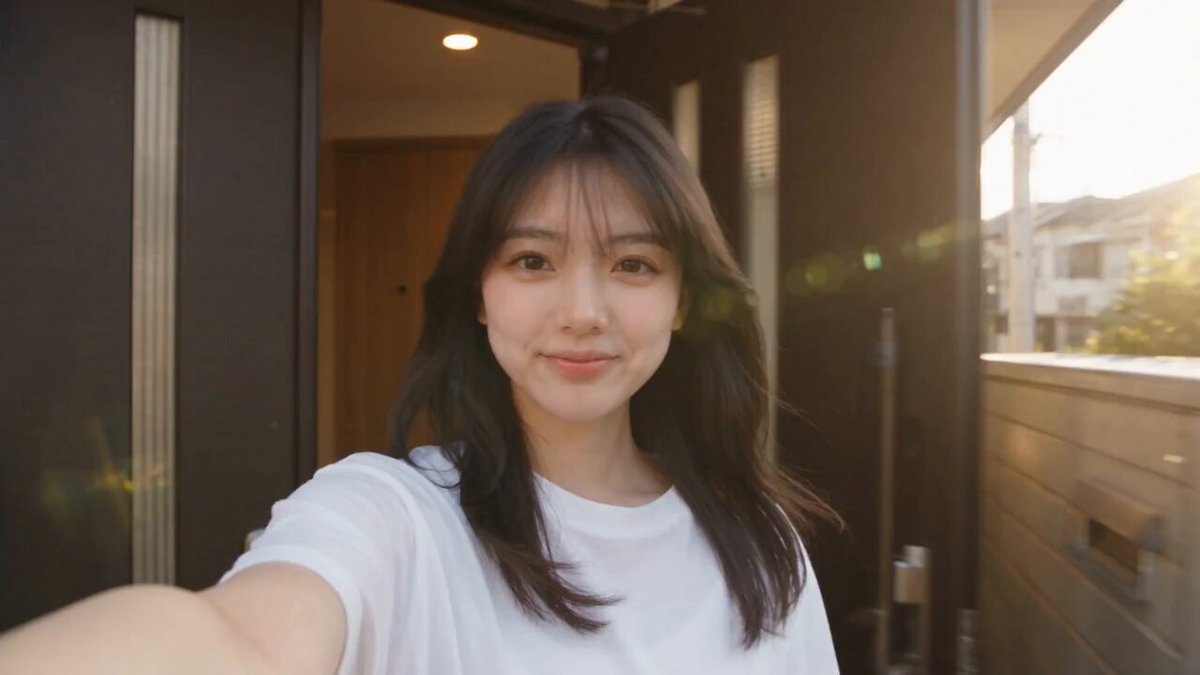
Why AI Avatars Became a Practical Production Tool
Digital avatars are not a new idea. Forum profile pictures, game characters, and early virtual presenters have existed for decades. What changed is the cost of entry. A few years ago, producing a convincing synthetic presenter required a motion-capture stage, a character artist, a lighting team, and a render farm. Today, a laptop and a handful of reference photos can produce a talking-head video that holds up on a phone screen.
That shift matters because most video content is not cinema. It is training modules, product walkthroughs, social clips, support answers, and internal announcements. These formats are repetitive, they need frequent updates, and they rarely justify a full production crew. Avatars solve a specific problem: they let a creator keep a recognizable on-screen presence without scheduling a shoot every time a script changes.
The trade-off is real. Synthetic presenters can look uncanny, drift in identity between shots, or flatten the emotional texture that makes a real person watchable. The rest of this guide focuses on how the underlying technology works, which workflow fits which job, and where the failure points usually hide.
How Avatar Generation Actually Works
Most modern avatar systems are pipelines, not single models. A photo or video goes in, an identity representation is extracted, a script is converted into speech and mouth shapes, and a renderer composites the result. Understanding the stages helps you diagnose problems when the output looks wrong.
Generative adversarial networks in plain terms
A generative adversarial network pairs two networks against each other. One network produces candidate images, the other judges whether those images look real. The producer improves by trying to fool the judge. For avatars, this approach was historically strong at producing sharp, plausible faces and at style transfer, where a portrait is repainted into an illustration, a painterly look, or a cartoon identity.
The weakness is stability. Adversarial training can collapse into a narrow set of outputs, which is why some avatar generators produce faces that all look related. It can also struggle with fine identity details like ear shape, hairline, or the exact spacing of eyes.
Diffusion models and identity preservation
Diffusion models work differently. They learn to reverse a process of adding noise, gradually turning random static into an image. In practice this produces higher diversity and better texture detail, and it handles prompts and reference images more gracefully.
For avatars, the important trick is identity conditioning. Instead of asking the model to invent a face, you feed it a face embedding derived from one or more reference photos, then let the model generate new poses, expressions, and lighting while keeping the embedding stable. Quality depends heavily on reference quality: even lighting, a neutral expression, no sunglasses, and several angles beat a single glamorous portrait every time.
Animation layers: lip sync, head pose, and micro-expression
Once you have a still avatar, someone has to make it talk. Speech-to-mouth systems map phonemes to visemes, the visible mouth shapes that correspond to sounds. Good systems also animate the jaw, cheeks, and subtle head motion. Poor systems animate only the mouth region, which produces the classic floating-mouth artifact where the rest of the face stays frozen.
Head pose and blinking are the second layer. A presenter who never blinks or never tilts their head reads as artificial within seconds. The third layer is micro-expression: eyebrows lifting on a stressed syllable, a slight squint on a question. These details are what separate a demo from something you would actually publish.
Four Avatar Workflows and When to Use Each
Not every avatar job is the same. Choosing the wrong workflow is the most common reason a project stalls.
Text-to-avatar
You write a script, choose or generate a face, and the system produces a speaking presenter. This is the fastest path and the best fit for explainers, FAQ content, and multilingual versions of the same message. The limitation is emotional range. Text-to-avatar is excellent at conveying information and weak at conveying conviction.
Photo-to-avatar
You supply photographs of a real person, and the system builds a digital double. This is the standard approach for personal branding, because the audience already recognizes the face. Requirements are stricter: multiple angles, consistent lighting, no heavy filters, and permission from the person depicted. A digital double of a real person raises consent and disclosure questions you should settle before you render anything.
Stylized and themed avatars
Style transfer maps a portrait into an illustration, an anime character, a 3D render, or a branded mascot. This is the right choice when you want a consistent visual universe rather than realism. It is also forgiving: stylized avatars hide the small anatomical errors that make photoreal output look unsettling.
Performance-driven avatars
Here a webcam or phone camera captures your performance, and the system transfers your facial motion onto an avatar. The result is far more expressive than text-driven animation, at the cost of a recording session. This is the best option for narrative content, comedy, and anything where timing matters.
Building a Consistent Avatar Across an Entire Video
Identity drift is the most common complaint about synthetic presenters. Frame one looks like your subject, frame nine hundred looks like a cousin. Consistency comes from a few disciplines.
Lock the identity reference. Generate the base face once, export it, and reuse that exact asset for every scene. Regenerating the face for each shot introduces variation you cannot control.
Keep the camera language stable. A model trained on frontal portraits will behave unpredictably at a three-quarter profile with dramatic side light. If you need multiple angles, test each angle in isolation before you commit to a script.
Standardize the render settings. Resolution, frame rate, and aspect ratio should be identical across clips. Upscaling some clips and not others creates a visible quality jump at the cut.
Use a shot list, not a script dump. Break your script into segments of 10 to 25 seconds. Generate each segment separately, review it, and only then assemble. Long unbroken generations are hard to repair and expensive to redo.
Match wardrobe and background. If the avatar changes clothing between segments, audiences tolerate it only if the scene also changes. A sudden shirt swap in the same room reads as an error.
A Repeatable Step-by-Step Production Workflow
This sequence works for both personal and commercial projects and scales from a single clip to a weekly series.
-
Write for the ear. Read the script aloud. Short sentences, active verbs, and no clauses that require a diagram. Avatar animation amplifies flat writing.
-
Pick the format before the tool. Decide whether you need realism, style, or performance capture. This decision eliminates most of the tool landscape immediately.
-
Prepare references. Five to ten images, frontal and three-quarter, neutral expression, even light, high resolution, no obstructions. Crop out other people.
-
Render a ten-second test. Say one sentence. Check lip sync on plosives, check blinking, check that the identity is stable. Fix problems here rather than after a full render.
-
Record or synthesize the audio. If you are cloning a voice, get explicit consent and keep the source recording clean. Background noise contaminates the clone.
-
Generate segment by segment. Keep a naming convention that maps files to script lines.
-
Assemble in an editor. Add captions, cut on motion, and insert B-roll to cover any segment where the animation looks weak.
-
Add sound design. Room tone, a subtle music bed, and small transitions do more for perceived realism than another pass of visual refinement.
-
Review on a phone. Most of your audience will watch at small size. Errors that look minor on a monitor can be invisible there, and vice versa.
-
Archive the project. Store references, prompts, audio, and settings together so the next episode matches this one.
Tool Selection Criteria
Features lists are noisy. These criteria separate tools that survive a real production schedule from those that only demo well.
| Criterion | What to check | Why it matters |
|---|---|---|
| Identity stability | Same face across 20+ short segments | Prevents reshoots and manual patching |
| Lip sync accuracy | Plosives, sibilants, and fast speech | The first thing viewers notice when it fails |
| Head and eye motion | Blinking, micro-tilts, gaze direction | Separates lifelike from mannequin |
| Aspect ratios | Vertical, square, and widescreen output | Social and presentation formats differ |
| Language coverage | Pronunciation quality in your target languages | Multilingual delivery is often the whole point |
| Export control | Resolution, frame rate, codec, alpha channel | Determines how the clip fits your edit |
| Compliance options | Consent records, watermarking, disclosure | Required for real-person doubles |
| Iteration speed | Time from script edit to new render | Decides whether you can update weekly |
A practical test: take one paragraph of your real script, run it through three candidate tools, and compare the outputs side by side with the sound off. Mouth shapes alone reveal a surprising amount.
Scene, Lighting, and Environment Integration
An avatar that looks convincing in isolation can fall apart in a composition. Integration is where amateur projects become obvious.
Start with lighting direction. If your background is lit from the left, the avatar's face must be lit from the left. Most tools let you choose a lighting preset or upload a reference; a mismatch reads as a cutout.
Match the color temperature. A warm window background with a cool blue face is instantly wrong. Sample the background in your editor and adjust the avatar's grade to match.
Respect the lens. A wide background shot with heavy depth of field implies a fast lens. If your avatar is rendered perfectly sharp across the whole frame, it will look pasted on. Adding a small amount of blur to the avatar or the background fixes most of this.
Add contact shadows. Even a subtle shadow under the chin or on a desk edge grounds the subject in the space. Many editors have a simple drop-shadow or light-wrap effect that is enough.
Finally, consider screen-position continuity. If the avatar sits on the left in one scene and jumps to the right in the next with the same background, the cut feels broken. Keep presenters on one side of the frame within a scene.
Common Mistakes That Ruin Avatar Footage
Over-scripting. Long, complex sentences give the animator more opportunities to misplace emphasis. Cut the script by 20 percent before you generate.
Chasing maximum realism. Photoreal avatars have the thinnest margin for error. A slightly stylized look is often more convincing, more consistent, and more clearly disclosed.
Ignoring consent and disclosure. If the avatar resembles a real person, you need documented permission and, in many contexts, an on-screen or in-description disclosure. This is a legal and reputational issue, not a stylistic one.
Single-angle references. One photo forces the model to hallucinate everything it cannot see. Feed it variety.
Skipping the audio pass. Viewers forgive imperfect visuals far more readily than bad audio. A cloned voice with room echo undermines an otherwise flawless render.
No B-roll plan. Talking heads get tiring. Plan cutaways, screen recordings, or text cards so the avatar does not carry every second of the runtime.
Rendering the final version first. Always test at low resolution and short duration. The expensive render should be the last step, not the diagnosis step.
Applications by Use Case
Personal branding and social video
A consistent avatar lets a solo creator publish daily without a daily shoot. The strongest results come from keeping the same face, the same intro framing, and the same caption style across episodes. Repetition builds recognition faster than novelty.
Learning and development
Training content changes constantly: new policies, new software versions, new compliance rules. An avatar-driven pipeline lets a small team update a module by editing a script and re-rendering two minutes of footage, rather than reassembling a full production.
Marketing and product explainers
Product tours benefit from a presenter who can point at interface elements and narrate without a studio. Combine an avatar with screen recordings and motion graphics, and the avatar carries the connective tissue rather than the whole video.
Localization and multilingual delivery
This is where avatars outperform almost everything else. One script, many languages, one recognizable presenter across all of them. The main quality variable is pronunciation: always have a native speaker review the generated audio before publishing, because a fluent-sounding sentence with one wrong stress pattern can undercut credibility.
Internal communications and accessibility
Recorded updates with captions and a consistent presenter help distributed teams. Avatars also make it practical to produce audio-described or sign-language-adjacent companion versions without doubling production load.
FAQ
Are AI avatars detectable?
Inconsistently. Static portraits are often convincing; long video with complex motion still shows artifacts around the mouth, teeth, and hairline. Assume your audience may suspect synthetic content and disclose accordingly.
Can I use my own face?
Yes, and you should keep a consent record even for yourself, since platforms and clients increasingly ask for provenance documentation. For anyone else, get written permission and define the scope of use.
How long should an avatar clip be?
Keep individual generations between 10 and 25 seconds. Longer clips accumulate drift and are painful to fix when one moment fails.
Do I need a good camera to create a source avatar?
You need even lighting and sharp detail more than a high-end sensor. A modern phone in daylight with a plain background beats a studio portrait with harsh shadows.
Why does my avatar look like a floating head?
Usually because the tool animates only the mouth region. Switch to a system that drives head pose and blinking, or shorten the shot and cover the rest with B-roll.
How many reference photos are enough?
Five to ten varied, clean images is a good baseline. More helps only if the additional images add genuinely new angles or lighting conditions.
Can avatars replace live presenters entirely?
For structured, information-dense content, often yes. For persuasive, emotional, or high-trust moments, a real person still outperforms. Most successful channels mix both.
Where This Is Heading
Avatar generation is converging on three improvements: better identity consistency across long sequences, finer control over performance direction, and clearer provenance signals built into the files themselves. The practical effect for creators is that the gap between a script and a finished, watchable video keeps narrowing.
The teams that get the most out of these tools will not be the ones with the largest model budget. They will be the ones with a disciplined workflow: clean references, short segments, a review pass on audio, honest disclosure, and a willingness to cut an avatar shot when a screen recording would simply communicate better. Treat the avatar as one instrument in the edit rather than the whole performance, and it will earn its place in your production line.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.