
Avatar Video vs Generative AI Video: A Practical Workflow Guide
Oct 14, 2026
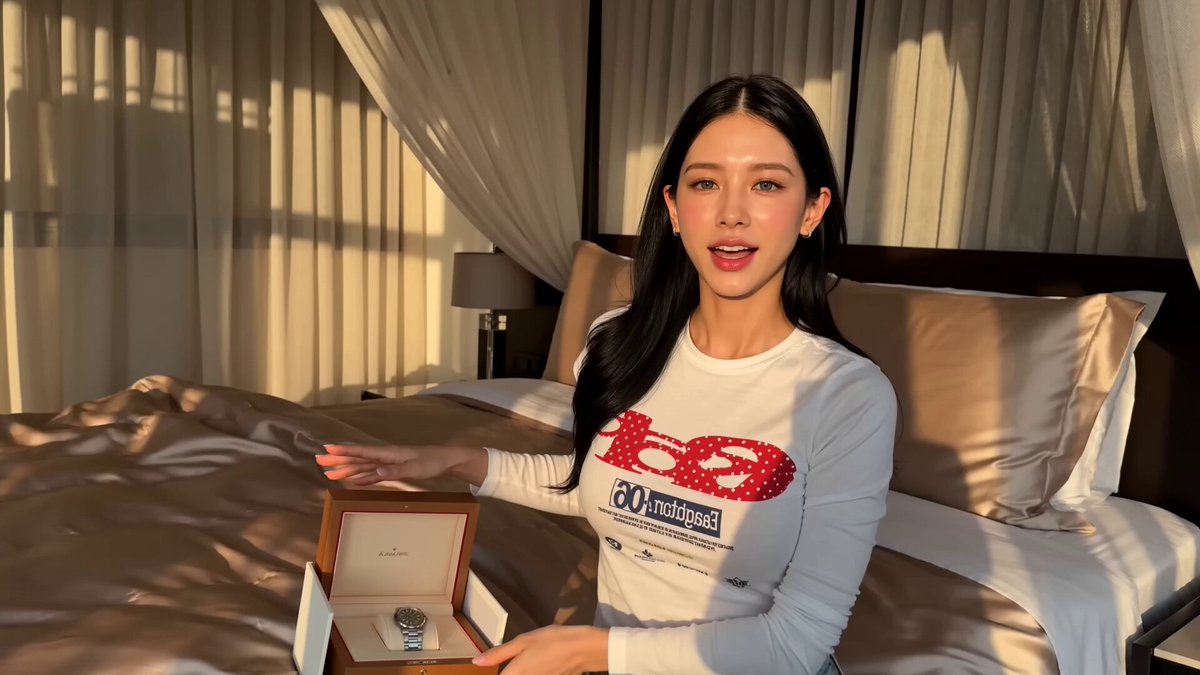
Most teams evaluating AI video tools ask the wrong first question: which platform is best? The more useful question is which pipeline fits the job in front of you. Avatar-led platforms and generative multi-model pipelines produce very different footage, demand different review habits, and break in different ways. Choosing between them is a workflow decision, not a loyalty decision.
This guide walks through both approaches, explains where each one wins, and lays out a repeatable end-to-end process you can apply to onboarding modules, product explainers, training series, or short social clips.
Avatar-led and generative pipelines solve different problems
Avatar-led video starts from a human presenter. You upload a script, pick or clone a presenter, choose a template, and the platform renders a talking-head performance with synced lip movement, gestures, and captions. The output is predictable. Slight variations in tone are possible through pacing and emphasis, but the visual grammar stays fixed: presenter, background, lower-third, cut.
That predictability is the entire point. When you need forty localized versions of a compliance module, or a product walkthrough that must be updated every quarter without reshooting, an avatar presenter removes a huge amount of production overhead. No lighting setup, no talent scheduling, no studio booking. Script in, video out.
Generative pipelines work differently. Instead of a single fixed presenter model, you prompt a text-to-video or image-to-video model for each shot. Camera moves, environments, lighting, and art direction are all controllable through language and reference images. The trade-off is variance: the same prompt can produce noticeably different results across runs, and consistency across a sequence requires deliberate anchoring.
The practical consequence is that avatar video is strongest for information delivery where the presenter carries the message, while generative video is strongest for concept work, b-roll, stylized sequences, and anything that would be impossible or expensive to film.
How each production model actually works
Avatar-first pipelines
An avatar workflow has four moving parts: the script, the presenter, the template, and the voice. Presenters can be stock characters or custom clones built from a short recording session. Templates control framing, background, and on-screen text behavior. Voice can be synthetic or recorded, and most editors let you adjust pronunciation for brand names and technical terms.
Because each part is a controlled input, iteration is cheap and deterministic. Changing one sentence re-renders one scene. Reviewers see a familiar format, so feedback tends to focus on wording rather than visuals, which shortens approval cycles considerably.
Generative multi-model pipelines
The generative approach treats each shot as an independent generation task. You may use one model for photoreal landscapes, another for stylized character motion, another for product inserts, and a separate tool for voiceover and music. Skilled operators develop a feel for which model handles which prompt pattern best, then stitch results together in a standard editor.
This model rewards planning. A shot list, reference frames, and a locked color direction are not optional extras, they are what make the output look like one film instead of five unrelated clips.
Hybrid pipelines
Most mature teams end up hybrid. An avatar presenter delivers the explanation while generative b-roll fills the gaps between talking points. Screen recordings and generative transitions carry the middle section. The presenter guarantees comprehensibility; the generative shots carry atmosphere and visual rhythm.
A decision framework for choosing a pipeline
Work through these criteria before you open any tool.
- Message shape. If the value is in spoken explanation, avatar-first wins. If the value is in showing something that cannot be filmed, generative wins.
- Volume and repetition. High-volume, template-friendly content favors avatar workflows. One-off hero pieces favor generative craft.
- Update frequency. If the content changes monthly, an avatar system with editable scenes saves more time than any rendering improvement.
- Localization. Avatar platforms usually handle multi-language voice and captions in one pass. Generative pipelines require re-versioning shots that contain text or culturally specific visuals.
- Risk tolerance. Regulated industries prefer deterministic output. Marketing experiments tolerate variance.
- Team skill. Generative pipelines need prompt craft, color sense, and editorial judgment. Avatar tools need good scriptwriting and template discipline.
A simple rule: if a stakeholder could ask "make this exactly the same but change one sentence," you want an avatar-first pipeline. If they ask "make this feel like nothing we have made before," you want generative.
The end-to-end workflow, step by step
Define the deliverable and the review path first
Before generating a single frame, write down the final spec: aspect ratios, runtime target, caption style, where the video will be hosted, and who signs off. Ambiguity here is what causes expensive re-renders later. Identify one decision-maker and one reviewer with technical accuracy responsibility. Two approvers is workable; five is paralysis.
Write for the format, not for the page
Spoken scripts read badly. Shorten sentences, cut subordinate clauses, and read the draft aloud at performance pace. Aim for roughly 140 to 160 spoken words per minute. A three-minute explainer is roughly 450 words, and that is less content than most drafts contain.
For avatar segments, mark emphasis and pause points. For generative segments, write the shot list in parallel: what the viewer sees, how long it holds, and what it must communicate. Every generative shot should earn its runtime.
Build a shot list and an asset pack
A shot list turns creative intent into a checklist. Columns worth keeping: shot number, description, model or template, reference image, duration, and status. The asset pack collects logos, fonts, brand colors, product screenshots, and any footage that will sit alongside generated material.
This is also where you decide the visual anchor. Pick a reference frame or a style description and treat it as the contract for the whole sequence: color temperature, lens feel, grain, lighting direction. Without an anchor, each generation drifts and the edit looks assembled rather than directed.
Generate in passes, not in one take
Generate more variations than you need, but review in batches. First pass: silhouette and motion. Second pass: lighting and color. Third pass: fine detail and text. Rejecting weak material early saves more time than polishing it later.
Keep a written prompt log. When a shot works, note the model, the prompt, the seed if available, and any reference images. When a client asks for "that look again" six weeks later, the log is what makes it reproducible.
For avatar scenes, render a single test segment before committing the full script. Lip sync issues, awkward emphasis, and mispronounced brand terms are much cheaper to catch at thirty seconds than at four minutes.
Assemble, caption, and mix
Editing is where most AI video either comes together or falls apart. Cut on motion, not on sentence boundaries. Use the presenter segments as the spine and place generative shots where the narration needs breathing room. Keep transitions simple; hard cuts read as confidence, elaborate wipes read as compensation.
Captions should be burned in or uploaded as a separate track, matching brand typography. Music sits low, roughly 15 to 20 percent under dialogue, and duck automatically during speech. Add subtle sound design: room tone under avatar segments hides synthetic flatness, and light whooshes under generative transitions hide abrupt cuts.
Finally, export two masters: a high-bitrate version for hosting platforms and a compressed version for internal distribution and social.
Consistency and brand control across a series
Series work lives or dies on consistency. Define a small set of locked variables and never change them mid-series: presenter, wardrobe, background set, lower-third position, title font, color grade, and music bed. Change one variable per season, not per video.
For generative sequences, consistency comes from reference images and repeatable prompt structure. Describe the subject the same way every time, then vary only the action and camera. If a character needs to appear in multiple shots, generate a clean reference frame first and use it as input for every subsequent shot.
Keep a single source of truth for on-screen terminology. Names of products, features, and job titles should be spelled and pronounced identically across every asset, including captions. A pronunciation list pasted into the script file prevents the most common localization embarrassment.
Quality control before you publish
Run the same checklist every time, in the same order.
- Watch once with sound off to check that visuals alone communicate the point.
- Watch once with eyes closed to catch narration that only makes sense with the visuals.
- Check lip sync on the first and last three seconds of every avatar segment, where drift is most visible.
- Verify text legibility at phone size, especially captions and on-screen labels.
- Confirm brand colors and fonts against the current guideline document.
- Check claims, numbers, and legal language against the approved copy.
- Confirm captions match the spoken audio exactly, including contractions.
- Test playback on the actual hosting platform, not just in the editor.
Keep the checklist in the project folder so freelancers and new hires can run it without asking.
Planning usage, time, and cost
AI video budgets behave differently from traditional production budgets. Instead of paying for people and locations, you pay for generation volume and iteration count. That means the biggest cost driver is indecision.
Estimate three numbers before starting: total finished runtime, expected variations per shot, and revision rounds. A sixty-second explainer with twenty shots and three variations each is sixty generations before a single edit. Understanding that volume up front prevents mid-project surprises.
Time estimates should include review latency, not just render time. Rendering is often the shortest step. The long tail is feedback, re-recording, and re-exporting. Build that into the schedule explicitly.
When evaluating subscription tiers, look at the constraints that actually bind: maximum video length, number of presenters or custom voices, watermark policy, commercial usage rights, resolution, and whether unused allowance rolls over. The headline number matters less than whether it supports your realistic monthly output.
The tool landscape: what to evaluate
Avatar-focused platforms such as Synthesia and HeyGen are built around presenter-driven content, templates, and localization. Generative model ecosystems such as Runway, Luma, Kling, Pika, and Google's video models favor shot-level craft. Voice tools like ElevenLabs handle narration quality, while editors like Descript or CapCut handle assembly and caption work.
When comparing anything, evaluate five dimensions:
- Determinism. Can you reproduce a result weeks later?
- Control. How precisely can you direct framing, motion, and style?
- Consistency. How well does the tool hold a character or look across many shots?
- Rights and usage. Are commercial rights clear, and is training data a concern for your legal team?
- Workflow fit. Does it export in formats your editor and hosting platform accept without friction?
Score each tool against your real brief rather than a demo. A tool that produces beautiful landscapes is useless if your content is ninety percent talking head.
Common mistakes that cost the most time
Writing a script at reading pace instead of speaking pace is the single most common error. It produces videos that feel rushed and require cutting after the render is already paid for.
Second is skipping the anchor frame, which turns a sequence into a patchwork of styles. Third is generating hero shots before the story is locked, so strong footage ends up on the cutting room floor. Fourth is treating captions as an afterthought, which breaks accessibility and mobile viewing. Fifth is approving visuals before the script is final, which guarantees at least one full re-render.
A quieter mistake is over-automation. Teams sometimes push every asset through a single generator because it is convenient, producing a monotonous rhythm. Varying tools within a defined visual anchor is not inconsistency, it is craft.
FAQ
Is avatar video still convincing to corporate audiences?
For instructional and informational content, yes. Viewers accept a synthetic presenter when the message is useful and the pacing is natural. The failure mode is trying to pass an avatar off as a filmed testimonial or an emotional brand story, where audiences notice the uncanny details immediately.
Can generative models produce a consistent recurring character?
With effort. Generate a clean reference frame, describe the character identically in every prompt, and vary only action and camera. Expect to discard more takes than with an avatar system, and budget review time accordingly.
How long should an AI-produced explainer be?
Most internal training performs best between two and four minutes, while marketing explainers often land between sixty and ninety seconds. Long enough to answer the obvious next question, short enough that the viewer does not need a reason to keep watching.
What should I do when the generated footage looks slightly off but usable?
Try one targeted fix at a time: adjust the prompt for motion only, then for lighting only, then swap the model. Random re-rolling wastes time. If three attempts fail, change the shot concept rather than fighting the model.
Do I still need an editor if the platform assembles the video?
For anything published externally, yes. Automated assembly is good at ordering scenes and adding captions, but it rarely gets pacing, sound balance, and brand typography right without a human pass.
How many people should be involved in approval?
Two is workable: one owner for message and one reviewer for accuracy. Add legal review only for claims-heavy content. Every additional approver removes a distinct creative decision and slows the cycle.
The teams that get the most from AI video treat it as a production system rather than a magic button. Pick the pipeline that matches the message, lock your visual variables, log your prompts, and run the same quality checklist every time. That discipline, not any single model, is what makes the output look professional.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.