
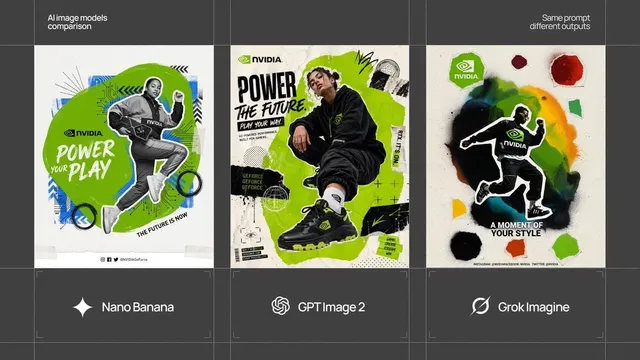
Photorealistic AI Image Generators Compared: A Practical Guide
Oct 14, 2026
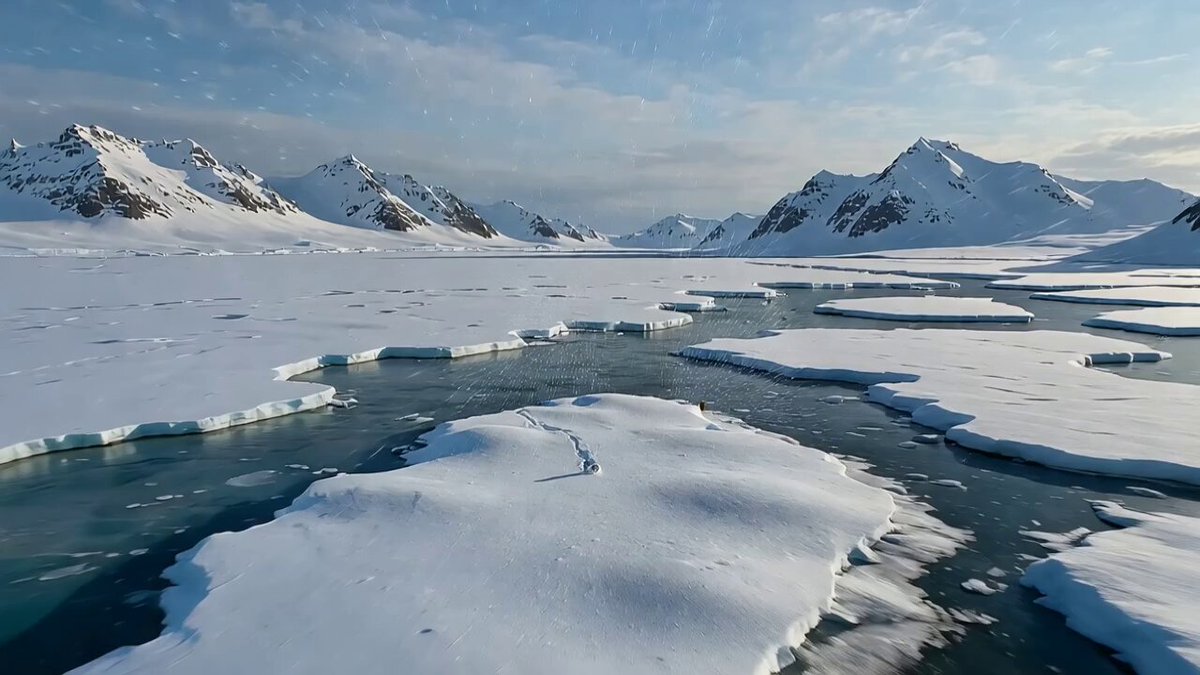
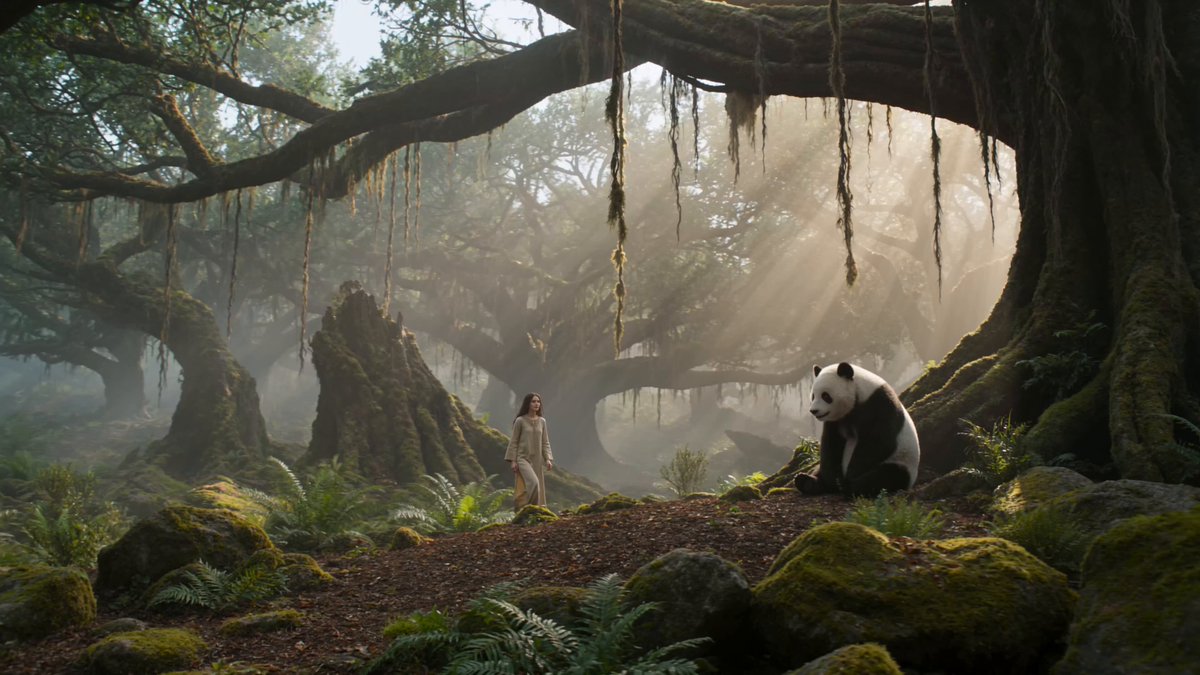
Why photorealism became the dividing line
A few years ago, an AI image that vaguely resembled a photograph was enough to impress an audience. That era is over. Viewers have now seen millions of generated images, and their tolerance for the uncanny has collapsed. A photorealistic result either survives a full-screen look on a decent monitor, or it fails — and the failure is usually obvious within a second. Waxy skin, melted jewellery, a shadow pointing the wrong way, a background that dissolves into mush the moment you zoom in.
The reason this matters is that the use cases changed. Photorealistic generation is no longer a novelty for social posts. It is now part of practical pipelines: advertising concepts, e-commerce product pages, storyboards that must convince a client, virtual try-on, editorial illustration that has to sit alongside real photography, and previsualisation for video shoots. In every one of those contexts, the image is not judged as art in isolation. It is judged against real photographs placed next to it.
The practical consequence is that "which generator is best" is the wrong question. The better question is: best for which shot, at which stage of the workflow, under which constraints? A model that produces stunning portraits may be mediocre at architecture. A model that nails a tabletop product shot may drift the moment you need the same character in a second image. What follows is a rubric for judging realism, a method for comparing models honestly, a prompting approach that actually moves the needle, and a workflow that carries a still frame all the way into motion.
What "photorealistic" actually means: a practical rubric
Physics and material behaviour
Realism starts with light transport. Look for subsurface scattering in skin — the subtle red glow at ears, nostrils and fingertips. Check that specular highlights are shaped like the light source that created them rather than a generic white blob. Contact shadows should anchor objects to surfaces; floating objects are the single most common giveaway in generated scenes. Metals need to reflect the environment that supposedly surrounds them, and fabric needs visible weave and believable weight at the folds.
Camera language and lens behaviour
Photographs carry the fingerprints of the lens. Depth of field should match the implied aperture and subject distance. Bokeh should have a consistent shape across the frame. Chromatic aberration should appear subtly at high-contrast edges, not everywhere. Sensor noise should be present in shadows at realistic levels. Motion blur should exist only where motion exists. When a generator produces an impossibly sharp foreground and an impossibly sharp background simultaneously, the eye reads it as artificial even if it cannot articulate why.
Prompt adherence and controllability
A photorealistic image that ignores your brief is worthless. Test whether the model respects subject count, wardrobe, pose, camera angle and composition. Then test the harder things: text on signage, logos, hands, and the negative space where you plan to place type. Controllability also means editability — can you change one element without regenerating the entire frame and losing the parts you liked?
Consistency across a set
The commercial test is never one image. It is ten images of the same person, product or location under different lighting. Identity drift is where most production pipelines break, and it is the criterion most comparisons ignore because it requires more than a single hero shot to detect.
The model families worth knowing
Stills-first diffusion systems
These are optimised for single frames. They tend to lead on fine texture, skin and material detail, and they usually offer the widest control tooling: reference images, pose guidance, depth and normal maps, and community fine-tunes for specific looks. If your final deliverable is a hero still, start your shortlist here.
Video-first cinematic systems
Systems built primarily for motion, such as Runway Gen-4 or OpenAI's Sora family, carry temporal priors. Their individual frames sometimes look slightly softer than those from a dedicated still model, but they understand camera movement, continuity and physical motion far better. If your deliverable is a clip, test these first and work backwards to stills.
Open-weight and regional options
Flux-derived families and open-weight releases, alongside strong regional offerings such as Kling and Hailuo, matter for three reasons: private or local deployment, fine-tuning on your own visual identity, and predictable behaviour at high volume. They also let you iterate without waiting in a queue, which changes how you explore a creative direction. For teams with strict data policies, a locally hosted model is often the only viable route.
Hybrid pipelines
In practice, the strongest results rarely come from one model. A common pattern is to generate composition and lighting with a fast model, refine the hero frame with a high-fidelity still model, then animate with a video-first system. Treat each model as a specialist station rather than a competitor.
How to compare models without fooling yourself
Build a fixed test set
Write ten prompts and do not change them during a comparison. A good set covers: a tight portrait in window light, a full-body shot in motion, a tabletop product with reflective packaging, an architectural exterior at golden hour, a plated food shot, a night street scene with mixed light sources, an animal close-up with fur, a group of three people with visible hands, a scene containing legible text, and an interior lit by a practical lamp. Run every prompt across every model at the same aspect ratio with documented settings. No cherry-picking, no re-rolls before you save the first result.
Score on weighted criteria
| Criterion | Weight | What you are actually checking |
|---|---|---|
| Physical realism | 30% | Light, shadow, materials, contact points |
| Prompt adherence | 25% | Count, wardrobe, pose, composition, text |
| Detail at 100% zoom | 20% | Eyes, teeth, hair edges, jewellery, type |
| Consistency across the set | 15% | Identity, wardrobe, lighting continuity |
| Workflow fit | 10% | Speed, editability, resolution ceiling |
Keep a spreadsheet with one row per prompt per model and write a one-line note describing the first visible flaw. Those flaw notes matter far more than the scores, because they tell you where each model breaks and what your repair process will need to handle.
Always judge at 100%
Thumbnails lie. Zoom into eyes, teeth, ears, hands, jewellery, hair edges and any text. Then view the frame full-screen on a phone, because that is where most client review happens. If an image holds up small but collapses when zoomed, it is a concept frame, not a deliverable.
Prompting for realism
Write like a photographer, not a poet
Structure prompts as subject, action, wardrobe, environment, lighting, camera, lens, grade. For example: "Portrait of a woman in her forties seated by a café window, natural daylight from camera left, 85mm lens at f/1.8, shallow depth of field, visible skin texture, muted film colour grade." Every clause constrains a physical variable instead of adding decoration.
Control lighting explicitly
Name direction, quality and colour temperature. "Soft key from the left, cool window light at 5600K, warm practical lamp behind at 2800K" produces consistently more believable results than "beautiful lighting". If you want a specific mood, describe the source that creates it rather than the feeling you want to feel.
Change one variable per iteration
When an image fails, adjust one clause and regenerate. Changing five things at once destroys your ability to learn what actually worked, and it makes reproducing a success almost impossible.
Use references wherever the platform supports them
Image prompts, pose references, depth maps and style references are the fastest route to control. Uploading a real photograph of a garment, a location or a face angle usually beats any amount of written description.
Avoid the plastic look
Words that push toward artificial perfection — flawless, hyper-detailed, perfect skin, ultra-sharp — frequently produce wax. Ask instead for visible pores, fine skin texture, slight asymmetry, retained blemishes. Realism lives in imperfection, and the imperfection has to be requested.
From still to motion: consistency is the hard part
Keyframes and multi-image references
The reliable way to animate a still is to control the ends. Supply a first frame and, where supported, a last frame. Multi-image references let you feed several angles of the same character so identity holds as the camera moves. Lock wardrobe, hairstyle and lighting direction in the reference set before you generate a single frame of motion.
Fighting flicker, drift and morphing
Keep clips short. Prefer slow camera moves and small gestures over fast action. Avoid hands near faces and dense overlapping crowds in a first attempt. If a face drifts, reduce motion amplitude and increase reference influence. If texture shimmers, the resolution ladder is usually wrong — generate at a higher base resolution before animating, because upscaling after the fact amplifies temporal noise rather than removing it.
Scene continuity across shots
For a sequence, generate a reference sheet first: one image per location, plus a character sheet with three angles. Reuse those references for every shot instead of letting each generation improvise a new version of the same room. This single habit prevents the most expensive rework in AI video production.
A workflow that holds up under deadlines
1. Brief and shot list
Write down the deliverable, aspect ratios, resolution and the two or three elements that must never drift. If a character's jacket colour matters, say so before generation, not after.
2. Generate wide, select narrow
Produce a broad first pass at low resolution to find composition. Select two or three candidates, then re-render the winners at higher fidelity using the same prompt and seed where the platform allows it.
3. Repair and upscale
Fix small errors — hands, text, stray objects — with inpainting rather than full regeneration. Then upscale. Finally, add a little grain and lens character, because perfect sharpness reads as synthetic.
4. Animate and assemble
Convert hero frames into short clips, cut them against music or narration, and keep motion consistent with the lighting established in the still. A shot that changes light direction halfway through reads as a mistake even to viewers who cannot name the problem.
5. Quality control on two screens
Review on a calibrated monitor and on a phone. Note artefacts in a shared list with the frame number so fixes can be batched rather than handled one at a time.
Mistakes that wreck realism
- Over-prompting with contradictory style words that cancel each other out.
- Ignoring hands and text until the final round, when they are most expensive to fix.
- Chasing maximum sharpness and landing on a hyper-real, plastic aesthetic.
- Mismatched depth of field between foreground and background.
- Regenerating from scratch for a tiny fix instead of inpainting the problem area.
- No version control — prompts, seeds, references and model versions should be saved with every selected frame.
- Using a recognisable real person's likeness without rights or consent.
- Judging on thumbnails and discovering artefacts only when the asset is printed or placed on a large screen.
- Assuming a single model will handle portraits, products, architecture and motion equally well.
Choosing a model for your deliverable
Start from the output, not the model
If the output is a print advertisement, prioritise resolution ceiling and material fidelity. If it is a social clip, prioritise temporal consistency and camera control. If it is a catalogue of two hundred product variants, prioritise throughput, editability and repeatability over peak beauty on a single frame.
Balance time, spend and control
Every realistic pipeline has three budgets: time, money and control. Low-resolution previews are cheap and ideal for exploration. High-fidelity renders are slow and should be reserved for frames that survived selection. Tiered workflows — preview, select, refine, upscale, animate — consistently beat trying to nail the final image in a single pass, because they give you decision points where you can stop spending.
Decide where privacy sits
For regulated industries, locally hosted open-weight models trade convenience for data control. For velocity, hosted video-first systems win. Most mature teams end up mixing two or three tools rather than pledging loyalty to one, and they document which tool owns which stage so the handoffs stay predictable.
Watch the resolution ladder
Generate slightly larger than you need, then downscale. Starting small and upscaling tends to bake artefacts into skin and fabric that no amount of sharpening can undo. If a frame will be animated, resolve the detail question before motion, not after.
FAQ
Are photorealistic generators good enough for commercial work?
For concepting, social, editorial and many e-commerce contexts, yes — with human retouching. For large-format print where a real photograph already exists, photography often still wins on cost and certainty.
How do I stop plastic skin?
Remove flawless and perfect from your prompts, add texture and asymmetry words, reduce sharpening in post, and add a small amount of grain.
Why do hands still fail?
Hands have many degrees of freedom, are frequently occluded, and appear inconsistently in reference material. Frame them larger, use inpainting, or change the composition so they matter less.
Do I need a local GPU?
Only if privacy, sustained volume or custom fine-tuning matter to you. Hosted tools cover the majority of everyday needs.
How many variations should I generate?
Enough to see a pattern — typically four to eight at preview resolution — before committing to a high-fidelity render.
Can one look carry across a whole video?
Yes, if you build reference sheets first and control both the first and last frame of each clip. Without references, expect drift by the third shot.
What single habit improves realism fastest?
Judging every candidate at 100% zoom before you fall in love with it at thumbnail size.
A short plan for this week
Pick two models: one stills-first, one video-first. Run the ten-prompt test set across both. Score at 100% zoom, note the first flaw in every image, and build a reference sheet for one character and one location. Then take your single best still and animate it into a three-second clip. By the end of that exercise you will know exactly which tool belongs at which stage of your workflow — and you will stop arguing about which generator is best in the abstract, because you will have evidence for the only question that matters: best for this shot, in this pipeline, under these constraints.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.