
Benchmarking Photorealistic AI Image Quality: Flux vs Runway
Oct 13, 2026
Why photorealism became the benchmark that actually matters
For a few years, the interesting question about generative media was whether a model could produce anything recognizable at all. That question is settled. Every serious tool now renders a plausible face, a plausible street, a plausible product. The interesting question has moved downstream: does the generated frame survive contact with a real production pipeline? A colorist's scopes, a client's calibrated monitor, a slow push-in on a face, a product hero shot that has to sit next to an actual photograph of the actual object.
That shift is why comparisons between model families such as Flux and Runway keep resurfacing. They are not really arguments about which tool is "better." They are arguments about which failure modes you can tolerate for a given shot. A model that produces gorgeous stills with slightly waxy skin may be perfect for a stylized social campaign and useless for a beauty commercial. A model that nails skin but drifts on background geometry may be ideal for a talking-head video and wrong for an architectural walkthrough.
This guide is about building your own evidence. Rather than repeating marketing claims, it lays out a repeatable way to benchmark photorealistic output, explains what to look at when you do, and gives decision criteria you can apply to your own projects. The specific strengths of any model will change with the next release; the evaluation method should not.
What each model family is actually optimized for
It helps to understand that Flux and Runway were not built to solve the same problem, even though their outputs increasingly overlap.
Flux is a diffusion-based image generation family built around a transformer backbone with a rectified-flow style training objective. In practice this design tends to reward prompt fidelity, strong text rendering, and high structural coherence in a single still frame. It handles complex multi-subject prompts with spatial relationships well, and it responds predictably to guidance and step changes, which makes it pleasant to tune.
Runway's lineage is rooted in video. Its models were pushed toward temporal stability, camera behavior, and motion plausibility long before they were pushed toward maximum micro-detail in a single frame. That inheritance shows: the frames are usually clean and consistent rather than maximally textured, and the tools around them assume you are producing sequences, not hero stills.
That difference is the single most useful thing to keep in mind. Image-first models tend to win blind still-image comparisons; video-first models tend to win when you scrub through a timeline. If your benchmark ignores this, you will draw the wrong conclusion.
Designing a fair benchmark instead of trusting vibes
Most informal comparisons fail because the test set is a handful of prompts the author already knows how to make look good. That measures familiarity, not quality. A usable benchmark needs three things: a fixed prompt set, blind scoring, and a separation between the model and the workflow wrapped around it.
Build a fixed prompt set across five difficulty tiers
Include roughly 25 to 40 prompts, distributed across tiers that stress different capabilities:
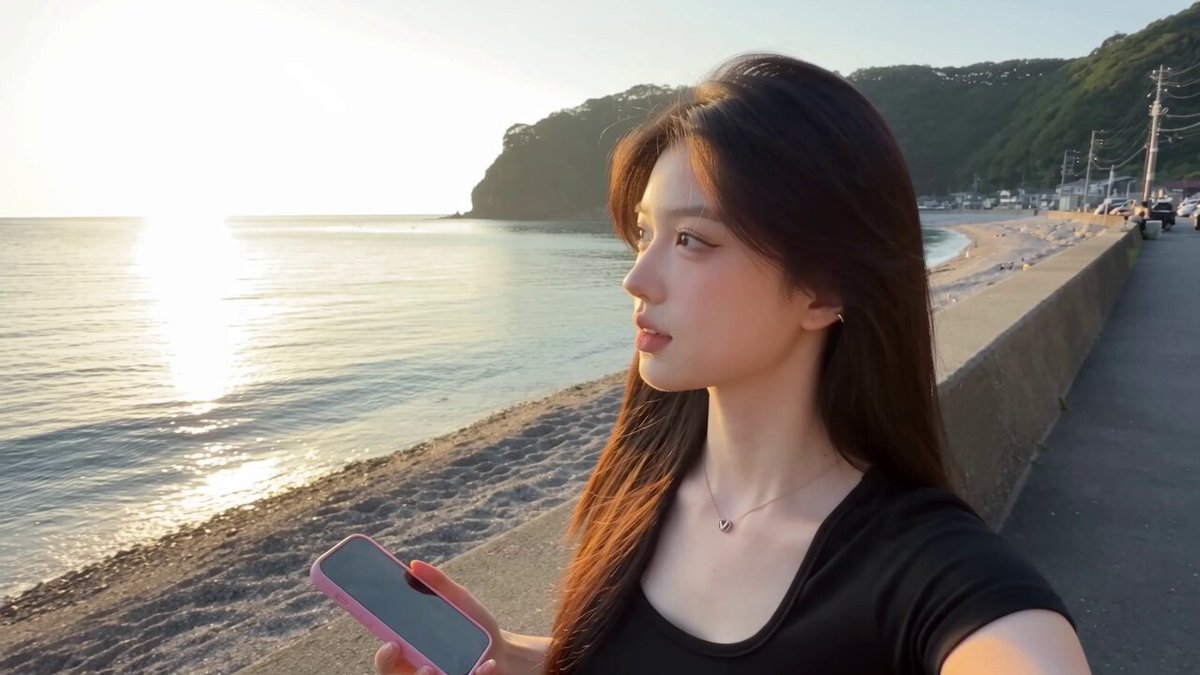
- Portrait realism: skin texture, pores, asymmetric facial features, catchlights, individual hair strands against a backlit rim.
- Materials: brushed metal, wet asphalt, matte ceramic, translucent glass, woven fabric, condensation on a cold surface.
- Complex light: mixed color temperature, hard sun plus soft bounce, practical lights in a dark interior, strong specular highlights.
- Spatial and text: signage with legible words, hands holding objects, reflections that must match the scene, reflections in curved surfaces.
- Motion (for video models): walking, head turns, hair movement, water, fabric, and any shot involving occlusion.
Keep the prompt text identical across models. Rewriting prompts to suit each model's quirks is legitimate for production work but invalid for benchmarking, because you no longer know whether the improvement came from the model or from your prompt engineering.
Score blind, and score the same frame twice
Generate at least four variations per prompt per model, label files with random identifiers, and strip metadata. Score each image without knowing the origin. Then re-score a random subset a day later. If your two scores disagree by more than a point on a five-point scale, your rubric is too vague to be useful.
Separate the model from the workflow
A model's raw output and a platform's output are different objects. Upscaling, face restoration, default negative prompts, and automatic color grading all sit between the model and your eyeballs. When you compare, note which stage you are judging. A still that looks soft may simply have skipped an upscale step that the competing tool applied silently.
Detail, texture, and micro-structure
The first thing people notice, and the last thing that actually predicts usefulness.
Zoom to 200 percent on skin. Look for three failure patterns. The first is smoothing: the model produces tone but no pore structure, so faces read as plastic under any sharpening. The second is false detail: a convincing-looking texture field that does not correspond to anatomy, such as pores that flow in a uniform direction or hair that merges into the jawline. The third is noise masquerading as detail, where high-frequency grain creates an illusion of sharpness that dissolves the moment you denoise.
In practice, image-first diffusion models tend to reproduce micro-texture more convincingly in isolation, while video-first models trade some of that texture for temporal consistency. Neither is automatically better. If your deliverable is a still, texture wins. If your deliverable is a five-second shot that will be viewed at 24 frames per second, nobody will ever see the pore structure, and unstable texture across frames will look far worse than a slightly smoother surface.
A useful test: downscale the image to 40 percent and view it at normal size. Texture that survives downscaling is doing real work. Texture that vanishes was decoration.
Light, materials, and physical plausibility
Photorealism is mostly a lighting problem. A frame with accurate geometry and bad light looks generated; a frame with approximate geometry and excellent light often passes.
Evaluate three things. First, contact shadows: does an object resting on a surface produce a shadow that tightens as it approaches the contact point? Models that fail here produce objects that appear to float. Second, specular behavior: highlights should follow the surface's curvature. A common artifact is a highlight that reads as a sticker pasted onto a flat plane rather than a reflection sliding across a curved surface. Third, indirect bounce: the shadow side of an object should pick up color from nearby surfaces. A red wall next to a white shirt should tint the shadow slightly.
Materials follow from the same logic. Look at how each model handles the difference between matte and glossy versions of the same object. Strong models preserve the underlying form while changing only the reflectance; weak models alter the shape or blur the silhouette when the material changes.
A quick practical check: prompt the same scene twice, once with a mirror finish and once with a matte finish, and compare the silhouettes. If the outline changes significantly, the model is not reasoning about materials so much as regenerating a new image that happens to match the adjective.
Color science and post-production readiness
This is where benchmarks usually stop and real production usually starts.
Ask whether the output is a finished image or a starting point. Look for five signals. Clipping: are highlights blown in a way that destroys recoverable information? Shadow detail: is the dark end crushed to pure black? Neutrality: do gray cards and white surfaces stay neutral, or drift magenta or green? Skin tone consistency: does the same character retain a stable complexion across angles and lighting conditions? Bandwidth: does the file survive a moderate grade without banding in gradients such as skies?
If you plan to grade the output, test it. Take a generated frame, apply a modest contrast curve and a slight saturation lift, and see how it degrades. Frames that fall apart under a one-stop equivalent adjustment are difficult to integrate with real footage.
For video work there is an additional question: how does the model handle the transition between very warm and very cool lighting within one shot? Models that shift the entire frame's white balance when a warm practical enters the scene will fight you in the edit, because the shot no longer cuts against the preceding scene.
Motion and temporal coherence in video pipelines
If you are producing sequences, this section matters more than all the others combined.
Watch for texture boil, where fine detail shimmers frame to frame as if repainted each frame. This is the single most common giveaway of generated video. Next, examine identity drift: over eight seconds, does a face remain the same person? Ears, nose width, and jawline are the tell. Then check object permanence: does a prop left at the edge of frame stay where it was when the camera returns?
At the edges of frame, look for warping, especially around hands, hair, and thin structures such as railings. And finally, evaluate motion arc plausibility: does the movement decelerate naturally, or does it stop on a frame as though the animation loop ended?
A concrete method: scrub through the clip frame by frame at a consistent point of interest, such as an eye or a button, and mark its position on each frame. If the position jumps in a way that does not match a smooth trajectory, you have found instability that will be visible even at playback speed.
Image-first models run as video often show strong first frames and progressively degrade. Video-first models often show a slightly softer first frame but hold together better at second six. Judge both at the same timestamp, not on the poster frame.
Prompt adherence versus aesthetic bias
Every model has taste. The question is whether its taste serves your brief.
To measure adherence, build prompts with countable constraints: three objects, one dominant color, a specific camera height, a named lighting condition, text that must appear verbatim. Then score how many constraints survived. Models with strong adherence will satisfy nearly all of them; models with strong aesthetic bias will satisfy the mood and quietly discard the constraints, producing something beautiful and wrong.
Neither behavior is universally better. For mood boards and concept exploration, an aesthetic bias is a feature, because it fills gaps you did not specify. For client work with approval rounds and a shot list, adherence matters more, because every deviation becomes a note.
A useful habit is to keep a running log of what each model silently ignores. In my experience the recurring casualties are camera angle, object count, and negative instructions. If a prompt says "no reflections," most models will happily add a reflective surface, because negation is weak in the underlying conditioning.
Workflow control and production reliability
Photorealism at the single-image level is table stakes. Reliability across a hundred images is what determines whether a tool belongs in your pipeline.
Character consistency is the first test. Generate the same person in five different settings with a reference image and compare faces. Then try a different expression and a different lighting direction. Small models collapse here; strong ones keep a stable identity while allowing the pose and lighting to change.
Seed behavior is the second. Does a fixed seed produce a stable variation space, or does the output jump? Reproducibility matters whenever a client wants a small change to an approved image.
Batch throughput and iteration cost is the third. The real cost of a model is not the per-image step; it is how many attempts you need before one is usable, multiplied by how long each attempt takes. A tool with slightly lower peak quality but a 60 percent first-pass hit rate beats one with stunning output and a 10 percent hit rate on a deadline.
Export and interoperability is the fourth. Can you get a clean file into your editor with intact metadata? Can you upscale without introducing halos? Can you composite a generated element over live footage without a visible edge? Test these on a real edit, not in isolation.
Decision criteria, common mistakes, and FAQ
Matching the tool to the job
- Cinematic stills and key art: favor maximum micro-detail, strong prompt adherence, and predictable seeds. Image-first diffusion models usually lead here.
- Short-form social video with motion: favor temporal stability and clean motion arcs over texture. Video-first models usually lead here.
- Product and packshot work: favor material accuracy, neutral color, and legible text. Test both, then check whether the label survives an upscale.
- Character-driven narrative: favor reference-based identity locking above all else. Texture is negotiable; a face that changes is not.
- Hybrid pipelines: generate key frames in an image-first model, then animate. This is often the highest-quality route, at the cost of an extra step and some motion fidelity.
The mistakes that invalidate most comparisons
- Optimizing prompts for one model. Rewrite all prompts or none.
- Judging at the wrong viewing size. Score at delivery resolution, not at 400 percent zoom.
- Confusing the platform with the model. Silent upscaling and grading distort results.
- Testing one image per prompt. Variance between generations is large; use at least four.
- Ignoring time-to-approved-asset. Aesthetic quality without iteration cost is half a metric.
- Trusting a single reviewer. Realism judgments are subjective; two scorers catch more bias than one.
FAQ
Which is more photorealistic, Flux or Runway? There is no universal answer. Image-first models such as Flux tend to lead in single-frame micro-detail and prompt fidelity; video-first models such as Runway tend to lead in temporal coherence and motion plausibility. The right question is which of those two properties your deliverable depends on.
How many prompts do I need for a valid benchmark? Twenty-five is a reasonable minimum, spread across portrait, material, lighting, spatial, and motion categories. Below that, you are mostly measuring luck.
Can I trust one review to pick a tool? No. Model behavior changes with version updates, and reviewer familiarity with prompts creates strong bias. Run your own small test on your own subject matter.
Do I need both? Many teams use an image-first model for framing and key art, then a video-first model for motion. That workflow often beats either tool used alone.
How often should I re-benchmark? Whenever a major model version ships or whenever your deliverables change format. A benchmark you ran for stills will not tell you what you need to know about a vertical video campaign.
What is the fastest shortcut? Take three frames from a recent real project, regenerate them with each candidate, and compare at final export resolution with a colleague who does not know which is which. That ten-minute test reliably predicts more than a week of reading spec sheets.

Alexander
More Blogs
Read MoreMontaggio video rapido: transizioni e software per l'AI
Guida pratica al montaggio video rapido con AI: transizioni fluide, software, workflow, coerenza visiva, errori da evitare e FAQ operative.
Building an AI Video Production Workflow From Concept to Cut
A practical guide to planning, generating, editing, and finishing AI-assisted videos with consistent characters, clear shot lists, and reliable review loops.
A Repeatable Post-Production Workflow for Polished AI Video
Build a repeatable AI video post-production pipeline: organize assets, cut story-first, design transitions, refine audio, and review versions calmly.