
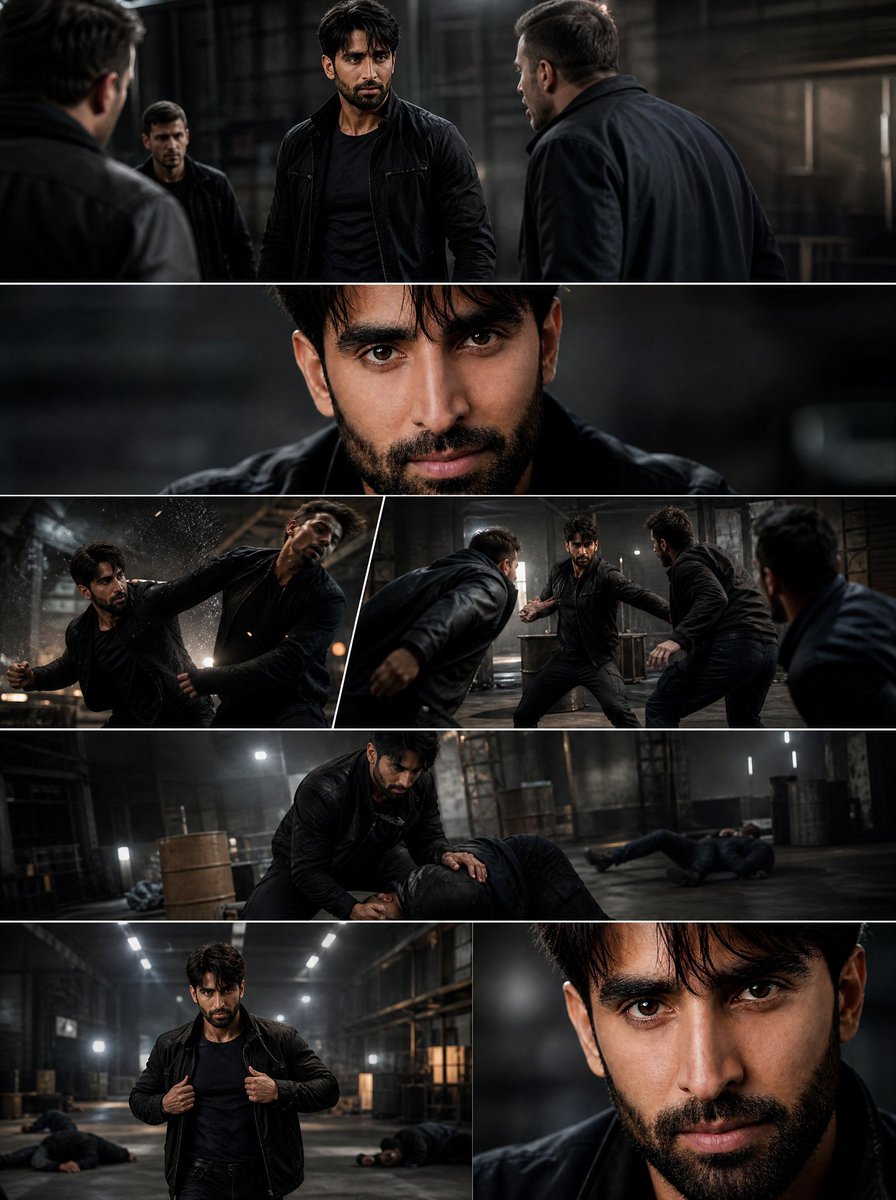
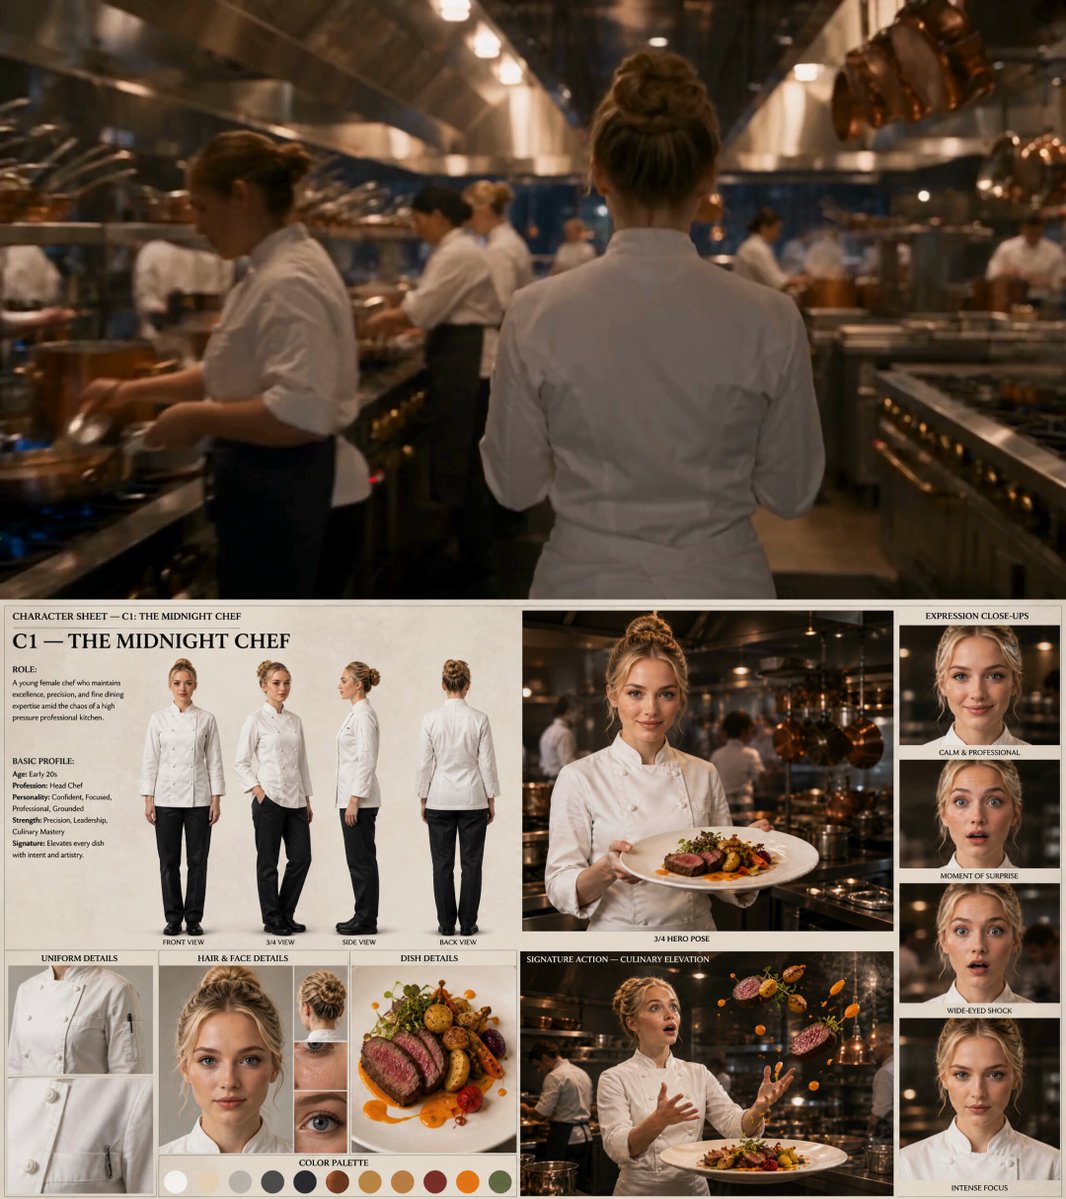
Why the text-and-image-to-video shift actually matters
For years, generative video was a novelty. You typed a sentence, waited, and received a few seconds of dreamlike motion that looked impressive in a demo and unusable in a real edit. That gap has closed. Modern pipelines can take a written prompt, a still photograph, or a combination of both and return clips with believable camera movement, stable subjects, and lighting that holds together across a timeline.
The important change is not the visual quality alone. It is the workflow. A single creator can now move from concept to a finished thirty-second piece without a camera crew, a location shoot, or a render farm. Small teams can prototype five visual directions in the time it used to take to storyboard one.
That speed creates its own problem. When generation is cheap, the bottleneck moves to decisions: what to generate, in what order, with what references, and how to judge whether a clip is good enough to keep. Most disappointing AI video projects fail at that stage, not at the model level.
This guide walks through a repeatable production workflow for text-to-video and image-to-video work. It covers when to start from words versus pictures, how to prompt for motion instead of appearance, how to keep characters and locations consistent, how to choose between tools, and how to run quality control before you publish. The goal is not to chase whichever model released most recently. It is to build a process you can run again next month with different tools and the same results.
Choosing your starting point: text-first, image-first, or hybrid
Every project begins with one decision that shapes everything downstream. Do you describe the shot in words, provide a reference image, or do both?
When a text prompt is enough
Text-first generation works best when the subject is generic or when you care more about mood and motion than about a specific face. Establishing shots, abstract transitions, B-roll of weather or traffic, product-agnostic backgrounds, and title-sequence imagery all fall into this category.
Text-first also wins when you need volume. If you want twelve variations of a forest at dawn to pick the best one, writing twelve prompts is faster than sourcing twelve images. The tradeoff is control: the model interprets your words, and interpretation drifts between generations.
When a reference image does the heavy lifting
Image-first generation is the right choice whenever identity matters. A recurring character, a branded product, a specific location, an outfit, or a logo must come from a visual reference, not a description. Words like "a woman in a red coat" produce a different woman every time; a reference image produces the same one.
Image-first is also your best defense against style drift. If your project has an established look — a muted documentary palette, a retro film grain, a flat illustration style — feeding a still that already carries that look anchors every clip to it.
Hybrid pipelines usually win
In practice, the strongest results come from combining both. Use an image to lock identity, composition, and palette, then use text to direct what happens inside the frame: the action, the camera move, the pace, and the duration.
A useful rule of thumb: images control who and what, text controls how and when. When a shot goes wrong, check whether you were asking words to do a job that only a reference image could do.
Build the story spine before you open any model
Generating clips before you know what the piece is about is the single most expensive habit in AI video. You end up with a folder of attractive fragments and no structure.
Start with a beat sheet. Write the piece in five to eight beats — a sentence each. For a thirty-second product story that might be: quiet morning, problem introduced, product enters, close-up detail, moment of relief, wide shot of the result, logo. For a sixty-second explainer, expand to ten or twelve beats.
Then convert beats into a shot list with four columns: shot number, visual description, motion description, and audio intent. Motion description is the column people skip and later regret. "Wide shot of the kitchen" is not a shot; "slow push-in on the kitchen counter, steam rising, morning light from the left" is.
Finally, decide which shots must be generated and which can be practical. Stock footage, screen recordings, simple typography cards, and static images with a slow zoom all cost far less time than a generated clip, and audiences rarely notice the difference in a supporting role. Reserve generation for the shots that carry the story.
A finished shot list is also your estimation tool. If a beat needs six clips and each clip takes several attempts, you can budget accordingly instead of discovering the scope at the end.
Prompting for motion, not just appearance
Most weak AI video prompts describe a photograph. Strong prompts describe a moment in time.
The six-slot prompt structure
A reliable prompt covers six slots: subject, action, camera, lighting, style, and duration or pace. Here is a text-only example:
"A silver-haired baker in a flour-dusted apron lifts a loaf from a stone oven, slow dolly right at eye level, warm tungsten light from the oven mouth, shallow depth of field, 35mm documentary look, calm pace, four seconds."
Compare that to "a baker making bread." The second prompt gives the model nothing to do with the camera and nothing to do with time, so it defaults to a drifting, floaty motion that reads as synthetic.
Direct the camera explicitly
Camera language is the highest-leverage vocabulary you can learn. Useful terms include push-in, pull-back, dolly left, tracking shot, crane up, handheld drift, whip pan, orbit, and locked-off static. Naming a camera move does two things: it creates intentional motion, and it suppresses the model's habit of adding unmotivated movement.
If a shot must stay still — a talking-head insert, a product beauty shot — say "locked-off camera, no movement" and expect to regenerate once or twice anyway.
Control pacing with duration
Ask for short durations when you need precise cutting. A three-second clip is easier to control than an eight-second clip because there is less time for the model to invent new content. Build long sequences from short, deliberate shots rather than trying to generate a single long take.
Keep a personal prompt library. When a prompt produces something excellent, save the full text alongside a still from the result. Reusing proven phrasing beats reinventing it, and over a few months your library becomes the most valuable asset in the project.
Keeping characters, locations, and style consistent
Inconsistency is the classic complaint about generative video, and it has three separate causes: identity drift, palette drift, and geometry drift. Each has a different fix.
Identity drift
Identity drift means your character's face, hair, or build changes between shots. The fix is a reference set rather than a single image. Collect three to five stills of the same person from different angles and lighting conditions, then attach the appropriate one to each shot based on the angle in the frame. A profile shot needs a profile reference; a front-facing shot needs a front reference.
The second technique is to avoid unnecessary variation. If your character appears in five shots, do not put them in five different outfits unless the story requires it. Fewer variables means less drift.
Palette drift
Palette drift happens when one shot is warm and golden and the next is cold and blue for no narrative reason. Fix it globally by defining a look — three or four reference frames that represent the intended grade — and applying a consistent color treatment in post. Unified grading can rescue clips that were generated with slightly different white balance.
Geometry drift
Geometry drift affects locations and objects: a room that changes shape, a product whose proportions shift. The fix is to generate wide establishing shots first, then derive tighter shots from that same reference frame. Working from wide to tight keeps spatial relationships intact, whereas generating close-ups first and widens later almost always produces a mismatch.
One more practical habit: name your files with shot number, take number, and a short descriptor. Consistency problems are easier to diagnose when you can find the previous take in seconds.
A repeatable six-stage production workflow
Here is a pipeline that works for solo creators and small teams alike. It assumes nothing about which model you use.
Stage one: brief. Write one paragraph describing the audience, the message, and the target length. Everything else gets judged against this.
Stage two: look development. Generate or gather five to eight stills that define the visual direction. Approve the look before generating a single second of video. This is the cheapest place to change your mind.
Stage three: shot generation. Work through the shot list in order, generating two to four takes per shot. Do not perfect shot one before moving on; generate the whole sequence at a rough level first so you can judge rhythm.
Stage four: assembly. Cut the rough sequence with placeholder audio. Watch it once without pausing and note where attention drops. Replace or shorten those shots.
Stage five: audio and polish. Add music, voice-over, and sound effects. Sound design does more for perceived realism than any generation setting — footsteps, room tone, and cloth movement make synthetic footage feel grounded.
Stage six: delivery. Export the correct aspect ratios for each destination, add captions, and archive the project file with its prompts and references.
Stages two through four are iterative by design. Expect to loop back to generation after assembly; that loop is the process working, not the process failing.
How to choose tools without chasing hype
Tool selection should follow your constraints, not release announcements. Four criteria cover most decisions.
Control versus convenience. Some tools give you fine control over camera, motion strength, and reference weighting but require more setup. Others deliver a good result from a short prompt with almost no configuration. Use convenient tools for exploration and controllable tools for final shots.
Reference handling. If your project depends on character consistency, test how each candidate tool handles multiple input images before you commit. Generate the same three-shot sequence in each and compare.
Clip length and resolution. Check the maximum usable duration and output resolution against your delivery spec. A six-second limit forces a different editing style than a twenty-second limit.
Cost predictability. Understand how each tool meters usage — per generation, per second of output, or a subscription ceiling — and pick a model that matches your iteration style. Heavy iterators should favor flat-rate plans; light users usually prefer pay-per-use.
A practical stack often looks like this: one image generator for look development and reference frames, one or two video models for motion, a compositing or editing app for assembly and grading, and a separate audio tool for voice and music. Mixing vendors is normal; the workflow, not the brand, is what holds the project together.
Common mistakes and how to fix them
The melty hands and morphing faces problem. Shorten the clip, reduce on-screen motion, and simplify the action. Fast, complex movement gives the model more room to fail.
Everything looks like a slow drift. Add explicit camera language and ask for a shorter duration. Vague prompts default to drift.
The shot is beautiful but off-message. This is a briefing failure, not a generation failure. Return to the beat sheet and re-read what the shot was supposed to accomplish.
Every clip feels like a different film. Apply a single grade across the timeline and unify grain and sharpness. Small technical mismatches read as separate productions.
The piece drags. Cut ten percent of the runtime. Generated footage often looks better than it functions, and trimming is usually the fix.
Text and logos are unreadable. Do not ask a video model to render typography. Generate a clean plate and add text in post.
You are generating infinitely without deciding. Set a take limit before you start — four per shot — and treat the limit as final. Decision fatigue costs more time than a mediocre take.
Quality control before you publish
Run the same checklist every time, on the smallest screen you own and then on the largest.
Watch the piece muted. If the story does not read without sound, the visuals are not carrying their weight.
Watch at two times speed. Continuity errors, flicker, and repeated motion become obvious at speed.
Check the first three seconds separately. If the opening does not create a reason to keep watching, nothing after it matters.
Verify technical delivery: correct aspect ratio per platform, captions burned in or uploaded, audio peaks controlled, and consistent frame rate throughout. Mixed frame rates are one of the most common causes of footage that looks subtly wrong without anyone being able to say why.
Finally, keep an archive note. Record the prompts, references, and settings for every shot you kept. Your next project starts from that document instead of from zero.
FAQ
Is image-to-video always better than text-to-video?
No. Image-first gives you more control over identity and style, but it also locks you into a composition. For abstract or establishing shots, text-first is faster and often more creative.
How many takes should I expect per usable shot?
Two to four is typical for a controllable tool with a good reference. If you are averaging more than six, your prompt or reference is probably underspecified.
Do I need to learn prompt engineering formally?
You need a consistent structure more than a vocabulary. The six-slot approach — subject, action, camera, lighting, style, duration — covers most situations, and a saved prompt library does the rest.
What is the fastest way to improve consistency?
Reduce variables. Fewer outfits, fewer locations, fewer lighting changes, and consistent reference sets. Every new variable is a new opportunity for drift.
Should I generate audio with the video model?
Treat generated audio as a scratch track. Replace or reinforce it with dedicated sound design. Layered ambience and effects are what make footage feel real.
How do I handle a client who wants changes after approval?
Keep the project file, prompts, and reference images archived. Regenerating a single shot is quick when you have the original inputs; it is painful when you have to reverse-engineer them.
Can this workflow scale to longer pieces?
Yes, but not by generating longer clips. Scale by generating more short, deliberate shots and assembling them. Structure comes from editing, not from generation length.
What should a beginner do first?
Pick one thirty-second concept, write a six-beat sheet, and complete all six production stages end to end. Finishing a small piece teaches more than experimenting with ten tools.
