
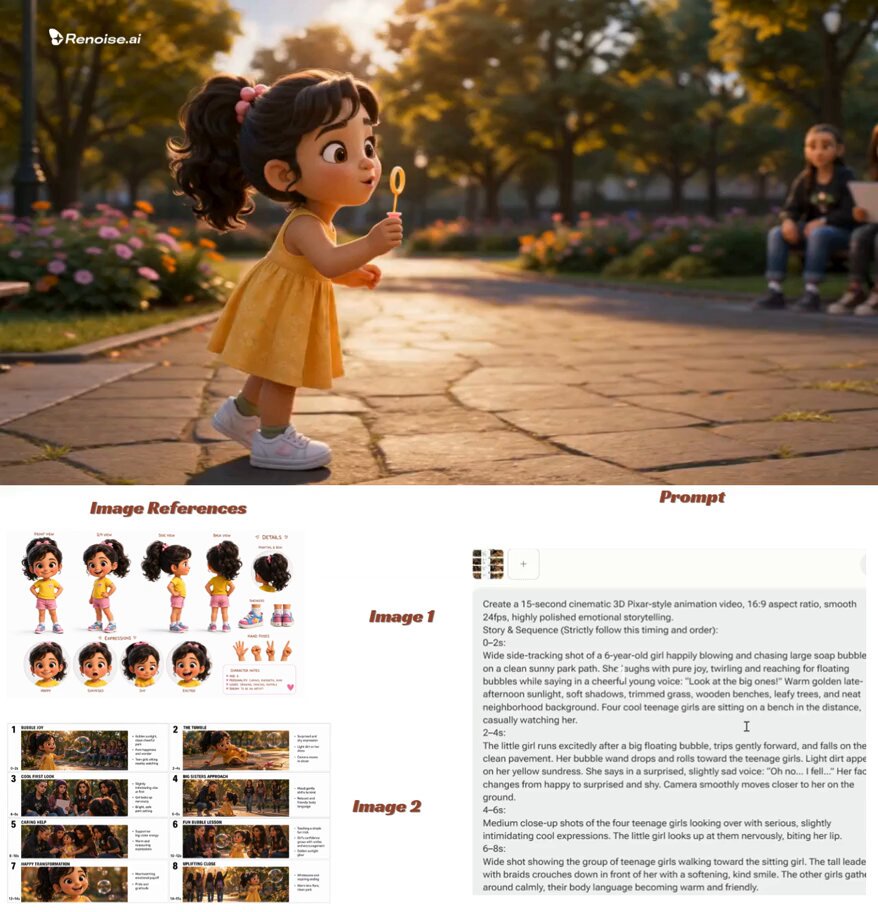
Text to Animation AI: Build Animated Stories Step by Step
Oct 15, 2026
Why Text-to-Animation Changed How Stories Get Made
A decade ago, turning a short story into an animated film meant a team: a storyboard artist, a background painter, a character animator, a compositor, a sound designer. Today a single writer with a laptop can produce a 60-second animated short over a weekend. That shift is not about one magic button. It is about a new production pipeline where language models interpret intent and video models render it frame by frame.
The important change is the skill you need. Drawing ability matters less than directing ability. If you can describe a shot clearly, define a visual style, keep a character recognizable, and cut on rhythm, you can produce animation that holds a viewer's attention. The model handles pixel-level labor; you handle meaning.
That said, text-to-animation tools are not story generators. They are rendering engines with an extremely high ceiling and an extremely literal mind. Anything ambiguous in your prompt becomes a stylistic gamble. Anything you forget to specify becomes the model's default taste, which is often glossy, over-lit, and slightly generic. The craft is in controlling those defaults.
This guide walks through a practical workflow: script writing for shots, style bibles, keyframe generation, image-to-video animation, character continuity, sound design, and publishing. It also covers the failure modes you will hit in your first week and how to work around them.
What Text-to-Animation Actually Does — and What It Cannot
Three Layers Working Together
Most modern systems stack three components. The first is a language layer that parses your prompt or script into entities, actions, and camera intentions. The second is a visual synthesis layer — usually a diffusion or transformer-based video model — that generates pixels conditioned on that interpretation. The third is a temporal control layer that decides how motion evolves between frames: how a cloak folds, how a head turns, how a camera dollies.
When output looks wrong, the failure usually lives in one specific layer. A confusing prompt is a language-layer problem. A melted face is a visual-synthesis problem. Jittery motion or a rubbery walk is a temporal-control problem. Diagnosing which layer failed tells you what to change instead of rewriting everything blindly.
The Honest Limits
Long continuous takes, precise acting, legible on-screen text, complex hand choreography, and physical interactions between multiple characters are still the weak spots. Models generally do well with: a single subject, clear motion, a strong environment, and a camera move that is either static or simple.
Duration is another constraint. Many tools generate a few seconds per pass, so a 90-second animation is assembled from 20 to 40 individual shots. That is not a bug — it is closer to how traditional animation works anyway. Shot-by-shot thinking is a useful discipline.
Finally, physics is approximate. A character may drift, a door may bend, a glass may pass through a table. Accept imperfection, hide the worst of it with editing, and design shots that avoid the problem in the first place.
Choosing the Right Tool for Your Story
Decision Criteria That Actually Matter
Ask seven questions before committing to a tool.
- What is the maximum shot length, and can I extend it without visible texture drift?
- Does it accept an image as the first frame? Image-to-video gives far more control than pure text prompts.
- Can it reference a character across separate generations using a reference image, a saved model, or an identity-preserving technique?
- What camera and motion controls exist — zoom, pan, dolly, motion brush, trajectory lines?
- What are the output resolution and frame rate, and can I upscale and interpolate cleanly?
- What does the commercial license allow, and where does the tool stand on training-data disputes?
- How fast is iteration? A tool that produces a usable shot in 90 seconds beats one that produces a beautiful shot in 20 minutes when you need 30 shots.
Tool Families, Not Brand Loyalty
There are four broad families, and most serious projects use at least two.
Text-to-video models such as Sora, Veo, Kling, Runway, Luma Dream Machine, and Pika excel at generating motion from a written description. They are strongest for establishing shots, atmosphere, and stylized transitions.
Image-to-video pipelines take a still you already approve and animate it. This is the backbone of a controlled workflow, because a still image is cheap to fix and a video is expensive to fix.
Stylized 2D pipelines built around Stable Diffusion, AnimateDiff, ControlNet, and ComfyUI graphs give the most aesthetic control, especially for flat illustration, watercolor, or comic looks. They demand more technical patience.
Traditional hybrid tools — After Effects, Moho, Blender with Grease Pencil, Toon Boom — remain the best way to handle lip-sync precision, recurring characters, and reusable rigs. A practical approach is to generate backgrounds and atmospheric shots with AI, then animate your hero character with a rig that you control shot to shot.
A Step-by-Step Workflow: From Script to Finished Animation
Step 1: Write a Shot-Ready Script
Write your story in plain prose first, then break it into numbered shots. Each shot entry should contain five elements: subject, action, environment, camera, and mood. A line like 'Mira runs through the market, panicked' becomes: 'Mira, a young courier in a red raincoat, sprints between vegetable stalls, handheld camera tracking from her left, wet cobblestones, overcast morning, tense.'
The second version is renderable. The first is a wish.
Step 2: Build a Style Bible
Before generating anything, decide on palette, lighting logic, lens character, grain, line weight, and aspect ratio. Write it down as a reusable block of prompt text you paste into every generation. This single habit does more for visual coherence than any post-processing trick.
Include a character sheet: front view, side view, three-quarter view, plus a short description of wardrobe and silhouette. Consistency starts with documentation.
Step 3: Generate Stills Before Motion
Generate still keyframes for every shot and approve them first. Iterate on composition, lighting, and character look while changes are cheap. Once a still is right, you have a reliable first frame that anchors the animation.
Step 4: Animate From the Stills
Feed each approved still into an image-to-video tool with a motion prompt and camera instruction. Keep motion prompts short and physical: 'slow push in,' 'she turns her head to the left,' 'cloth ripples in wind.' Avoid stacking three actions into one pass; split them into separate generations and cut between them.
Step 5: Assemble in the Edit
Bring all clips into an editor, trim to rhythm, add transitions only where they serve the story. Fix speed, stabilize wobble, and color-match shots. Roughly 60 to 70 percent of perceived quality comes from this stage, not from the model.
Prompt Patterns That Hold Up Under Pressure
The Five-Part Prompt Formula
Use a consistent order: subject, action, environment, camera, style. Example: 'A lanky fox in a knitted scarf, walking slowly through deep snow, pine forest at dusk, wide static shot, muted pastel palette, soft grain, hand-painted look.'
Vary one element at a time. If you change subject, camera, and style simultaneously, you cannot tell what caused the improvement.
Motion Vocabulary That Models Understand
Models respond better to concrete physical verbs than to emotional adjectives. Instead of 'sadly,' try 'shoulders drop, gaze lowers, slow blink.' Instead of 'energetic,' try 'quick steps, arms swinging, camera tracking backward.'
Negative Constraints and Safety Rails
Maintain a standing list of exclusions: extra limbs, text overlays, watermarks, sudden zooms, flickering, long held close-ups on faces, crowded backgrounds. Reuse the same list every time so results stay comparable across shots.
Character Consistency Across Dozens of Shots
This is the hardest problem in AI animation, and it has practical solutions.
First, anchor identity with reference images rather than words. A single strong portrait plus a full-body reference will outperform paragraphs of description.
Second, fix your seed where the tool allows it, and change only the elements that must change.
Third, simplify design. Characters with distinctive silhouettes — a hat, a scarf, a specific coat color — survive generation variance far better than a generic figure in neutral clothing.
Fourth, control framing. Faces survive mid-shots and wide shots much better than extreme close-ups during motion. Reserve close-ups for shots with minimal movement, or animate them from a static still with subtle parallax.
Fifth, consider training a small custom style model on your own approved frames. It takes effort upfront and pays back across a series.
Sixth, accept managed imperfection. Slight variation between shots reads as hand-drawn expressiveness to most viewers, as long as wardrobe, palette, and proportion stay stable.
Sound, Voice, and Pacing
Animation without sound feels like a technical demo. Sound is what makes it a story.
Start with a scratch voice track. Record lines yourself, or generate them with a text-to-speech tool, and cut your visuals to that timing. Animating to a locked audio track is dramatically easier than fitting audio to finished visuals.
Use ambience to establish place: rain, market chatter, wind through grass. One well-chosen layer of background sound does more than ten sound effects.
Keep music minimal and low in the mix under dialogue. If you are publishing to social platforms, assume viewers may hear the first two seconds through a phone speaker — put a clear sonic hook there.
Pacing matters more in animation than in live action because every frame is deliberately constructed. Animation 'on twos' — holding each drawing for two frames — gives a deliberate, handcrafted feel. Interpolating AI output to a smooth 60 frames per second often makes it look cheaper, not better. Test both and trust your eye.
Common Mistakes and How to Fix Them
Asking for a whole story in one prompt. Break it into shots. Always.
Ignoring the first frame. Most motion problems are actually composition problems. Fix the still.
Overloading motion prompts. Two actions per pass maximum.
Mixing art styles across shots. Lock a style block and paste it verbatim, even when it feels repetitive.
Skipping stabilization. Slight warping is normal; a stabilize pass and subtle crop hides most of it.
Generating at the wrong aspect ratio. Decide delivery format first — vertical for short-form, widescreen for a series — because cropping later destroys framing.
Neglecting sound. Silent AI animation is judged harshly. Add ambience, music, and voice before showing anyone.
Chasing perfect photoreal faces. Stylized, illustrative looks are more forgiving and often more memorable.
Not archiving prompts. Save every prompt, seed, and reference image alongside each clip. You will need to regenerate.
Publishing, Repurposing, and Building a Series
Before export, standardize deliverables: a widescreen master, a vertical cut, and a square variant if you need one. Burn in captions for social versions, and keep a clean master without them.
Structure your animation so it can be serialized. A recurring location, a fixed cast, and a repeatable cold-open format let you produce episode two in a fraction of the time of episode one. Series also compound audience attention in a way standalone shorts rarely do.
Write a one-sentence hook for your title and thumbnail. Viewers decide in under two seconds whether the animation looks intentional. A strong keyframe from your own approved stills usually outperforms anything generated specifically for a thumbnail.
Finally, keep a production log. Track which prompts produced usable shots, which tools failed at which task, and how long each stage took. After three projects, that log becomes the most valuable document you own.
FAQ
Do I need drawing skills to make animated stories with AI?
No, but visual literacy helps enormously. Understanding composition, lighting, and silhouette will improve your prompts more than technical tinkering.
How long does a one-minute animation take?
For a solo creator with an established pipeline: roughly eight to twenty hours, depending on how many shots need regeneration. The first project always takes longer.
Can I keep the same character across many shots?
Yes, with reference images, fixed seeds, simplified design, and careful framing. Expect some variation; hide the worst of it through editing rather than fighting the model.
Is pure text-to-video or image-to-video better for storytelling?
Image-to-video, almost always. Approving a still is cheap; fixing a bad clip is not.
What about lip-sync?
Dedicated lip-sync tools can handle short dialogue shots well. For anything longer, animate mouths in a traditional tool over an AI-generated background, or frame the character away from camera during long speeches.
How do I avoid a generic look?
Choose a specific, non-default aesthetic: limited palette, unusual lens, distinctive grain, or a hand-drawn line style. Specificity in the style block beats complexity in the story prompt.
Should I disclose that AI generated my animation?
Many platforms require it, and audiences generally respond better to transparency than to discovery. Disclose, then let the work speak.

Alexander
More Blogs
Read MoreVidu Q4 Alternatives: 4K AI Video Models Compared (2026)
Vidu Q4 alternatives compared: Kling 4.0, Seedance 2.5, Wan 3.0, and Runway Gen-4 — 4K support, input modes, durations, audio, and what each costs in credits on Domer.
Top 4K AI Image Generators in 2026: 5 Models Compared on Real Costs
The top 4K AI image generators on Domer compared: Flux 3 Klein, Nano Banana 2.1, GPT Image 2.5, GPT Image 2, and Nano Banana Pro — 4K credit costs, reference limits, and speed.
Nano Banana 2.1 vs GPT Image 2.5: Which Image Model Should You Use? (2026)
Nano Banana 2.1 vs GPT Image 2.5 Flare compared: credit costs per resolution, aspect ratios, reference images, text rendering, and which tasks fit each model.