
Generating video from a written prompt is no longer a party trick. It is a production method. The difference between a clip that looks impressive for five seconds and a sequence that holds attention for a full minute comes down to workflow discipline: how you plan shots, which model you route each shot to, how you describe motion, and how you assemble the results.
This guide walks through an advanced text-to-video pipeline from brief to export. It focuses on decisions you make before pressing generate, because that is where most quality is won or lost.
Why text-to-video changed the production math
Traditional video production spends most of its budget on logistics. Location, crew, talent, weather, and reshoots all cost time. Text-to-video collapses the exploration phase. You can draft ten visual interpretations of a scene in the time it previously took to storyboard one.
The practical consequence is that previsualization becomes cheap. Directors can test camera moves, lighting moods, and pacing before committing to a shoot day. Marketing teams can produce variant edits for different audiences without booking a studio. Solo creators can build sequences that once required a small team.
But cheap generation creates a new bottleneck: selection. When you can produce forty candidate clips, the hard skill is judging which eight belong in the timeline. Advanced workflows are therefore built around constraints, not volume. You define the shot, the look, the duration, and the motion before generating anything, then treat the model as a rendering engine rather than a creative director.
There is also a craft shift. Prompt writing rewards precision about physical space and camera behavior. Vague poetic language produces vague results. Specific language about lenses, movement, and lighting produces controllable results.
How an advanced text-to-video pipeline works
It helps to know roughly what happens between your prompt and the returned file, because every stage suggests a lever you can pull.
Prompt understanding and latent encoding
Your text is converted into an internal numerical representation. The system does not read your sentence the way a person does; it maps tokens to visual concepts it has learned from training data. That is why familiar phrasing works better than invented phrasing. Describing a subject, an action, a setting, and a camera behavior in plain terms lands more reliably than abstract metaphor.
Temporal coherence: the hard part
A still image only has to be plausible once. A video must stay plausible across dozens or hundreds of frames. The model has to keep objects, textures, and identities stable while motion evolves. This is where most failures appear: a jacket changes color mid-clip, a hand gains a finger, a face drifts between one shot and the next.
Rendering, upscaling, and finishing
The output of the first pass is rarely the final asset. Advanced pipelines add a second stage: upscaling to delivery resolution, interpolation to smooth framerates, and color treatment to match the rest of the edit. Treating these as separate, intentional steps gives you far more control than accepting the raw render.
Plan the edit before you write prompts
The single biggest upgrade you can make is to stop generating clips and start generating shots. A shot has a purpose in the sequence. A clip is just footage.
Beat sheets for short clips
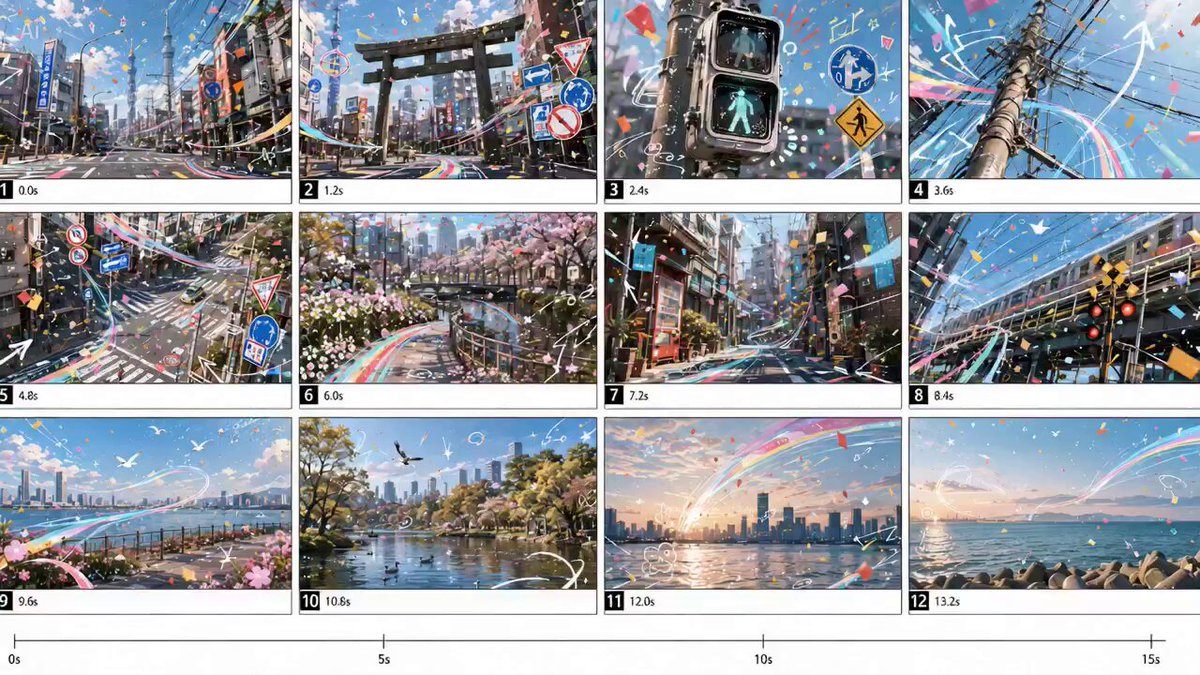
Most generated clips work best between three and eight seconds. That is short, so write your sequence as a beat sheet first. A thirty-second piece might be seven beats: establishing environment, subject introduction, action, complication, reaction, product or idea reveal, closing frame. Each beat becomes one or two shots.
The three-layer prompt formula
Use a consistent structure so you can debug one layer at a time.
Layer one is subject and action: who or what, doing what, in what setting. Layer two is camera: shot size, angle, lens feel, and movement. Layer three is treatment: lighting, palette, texture, and mood.
A workable example: a ceramicist shaping a bowl on a wheel, in a sunlit studio; medium close-up, 50mm equivalent, slow push in; warm morning light, soft shadows, muted earth tones, shallow depth of field.
Separating these layers means when a result is wrong you know whether to fix the action, the camera, or the look.
Choosing a model per shot, not per project
Different engines are better at different jobs. Locking yourself to one generator for a whole project is a common mistake.
Decision criteria that actually matter
Ask five questions for each shot. Does it need photoreal humans, or would stylized rendering be safer? How complex is the motion, and does the action stay inside the frame? Is text or a logo visible, since lettering is the most fragile element? Does the shot need audio or lip sync? How many attempts can you afford before the shot becomes a time sink?
Photoreal human faces favor engines tuned for identity preservation. Stylized sequences, animation, and illustration favor engines with strong aesthetic priors. Product and macro shots reward models that handle reflective surfaces and fine texture.
Mixing models without breaking visual continuity
Mixing engines across a sequence works if you standardize the variables around them. Fix aspect ratio, resolution, framerate, and color treatment across all shots. Choose a single grade to apply at the end so differences in rendering style converge. Keep the same lens language and palette descriptors in every prompt. The audience forgives small texture differences; it notices jarring shifts in color and crop.
Advanced prompting: camera, light, and motion
Once subjects are stable, the remaining quality gains come from describing motion and optics precisely.
Camera language that models understand
Use standard vocabulary: wide establishing shot, medium shot, close-up, extreme close-up, over-the-shoulder, low angle, high angle, Dutch angle. For movement, use slow push in, pull back, tracking left, pan right, orbit, crane up, handheld follow, static locked-off frame. Adding a speed qualifier such as slow or subtle reduces exaggerated motion.
Lighting, lens, and color descriptors
Lighting does more for perceived quality than almost any other variable. Useful terms include soft diffused daylight, hard directional sun, rim light, practical neon, overcast, golden hour, blue hour, and single-source candlelight. Lens descriptors such as 24mm wide, 85mm portrait, macro, and shallow depth of field give the renderer cues about perspective and focus behavior.
Motion verbs and physics cues
Replace generic verbs with physical ones. Instead of a person walking, describe steps landing on wet pavement with subtle fabric movement. Instead of smoke, describe smoke curling upward and thinning as it rises. Physics cues such as weight, inertia, spray, and dust help motion read as real rather than as interpolation.
Finally, name what you do not want. Cropped heads, warped hands, text artifacts, and flicker are common failure modes. Stating them reduces how often you have to re-roll.
Holding characters and scenes together
Consistency is what separates an amateur sequence from a professional one.
Reference frames and image-to-video
The most reliable method is to establish a look with a still image, approve it, then drive motion from that still. Image-to-video keeps the approved design intact and lets the model focus on movement. Generate a character sheet first: front, three-quarter, and profile views in consistent lighting. Use the approved frame as the starting point for every shot featuring that character.
Continuity notes, wardrobe sheets, and seed discipline
Keep a short continuity document for each project. Record wardrobe, hair, props, environment details, palette, and time of day. When a render drifts, compare it against this document rather than against memory. Reusing seeds where the tool supports them helps stabilize repeated shots, and keeping the same descriptive phrasing across shots reinforces the same visual concept internally.
Do not rely on the model to remember. Carry the state yourself.
Audio, dialogue, and lip sync
Audio is often treated as an afterthought, and it shows. Decide early whether a shot needs a generated voice, natural ambience, or music only.
Dialogue on camera is the hardest case. Keep lines short, keep the face large enough to read the performance, and avoid overlapping speakers. If precision matters more than novelty, record voice separately and animate to it, or keep the character off-screen and let dialogue carry over action shots.
Ambience is where cheap sequences are exposed. A city street without traffic hum, or a forest without birds, feels hollow. Build a small ambience library and reuse it. Consistent room tone across cuts does more for perceived production value than a bigger music track.
Editing and assembly: making clips feel like a film
Generated clips are raw material. Assembly is where they become a sequence. Import everything at matched resolution and framerate, then cut for rhythm rather than for completeness. If a beat works in two seconds instead of five, cut to two.
Use transitions deliberately. Hard cuts suit energy; dissolves suit time passing. Avoid decorative transitions that call attention to the editing rather than the content.
Add motion in post when a generated shot feels static: a slow digital push, a subtle drift, or a shake on impact. Apply one grade across the timeline so color differences between engines disappear. Sound design should land on movement: footsteps on contact, cloth movement on a turn, a soft whoosh on a fast cut.
Finally, watch the sequence without sound. If the story reads visually, the edit is working. If it only makes sense with narration, the shots are too weak.
Quality control: the pass that saves a project
Before delivery, run a fixed checklist rather than eyeballing the result.
Check anatomy at normal speed and paused: hands, teeth, eyes, and ears are the usual failures. Check text and logos frame by frame, since lettering warps easily. Check continuity: wardrobe, props, hair, and light direction across cuts. Check motion for stutter, ghosting, or unnatural acceleration. Check audio for clipping, mismatched room tone, and abrupt level jumps. Check the ending holds on a deliberate frame rather than stopping mid-action.
Common mistakes that waste the most time: generating before writing a shot list, using one engine for everything, overloading prompts with too many competing actions, ignoring aspect ratio until the end, and accepting the first acceptable render instead of testing two variations of the same shot.
FAQ
How long should a single generated clip be?
Aim for three to eight seconds for shots with people or complex motion, and up to ten seconds for slow environmental shots. Longer clips increase the chance of drift, and you can always extend a shot by cutting to a second angle.
Do I need to be good at prompt writing to get results?
You need to be specific, not literary. Describe the subject, the action, the camera, and the light in plain terms. A structured prompt beats a poetic one almost every time.
What is the fastest way to fix an inconsistent character?
Approve a still image first, then drive every shot from that reference. Rebuild the character sheet if the drift started early, and keep consistent lighting descriptors in every prompt.
Should I generate audio in the same tool as the video?
Use it for ambience and quick drafts. For dialogue you care about, record separately and sync in the edit. You gain control over performance, timing, and clarity.
How many attempts should one shot get?
Set a limit before you start, usually three to five. If a shot is not working after that, the problem is usually the prompt structure or the model choice, not luck. Change one layer and test again.
Can I mix generated footage with real footage?
Yes, and it is one of the most effective approaches. Match resolution, framerate, and color, and cut generated shots into the sequence where a real camera would be impractical. A shared grade makes the two sources sit together convincingly.
What resolution should I work at?
Cut at the resolution you will deliver, and generate slightly above it when possible so you have room to reframe. Standardizing early prevents a rebuild later.
How do I keep a long sequence from feeling repetitive?
Vary shot size, not subject. Alternate wide establishing frames with close detail shots and reaction shots. Rhythm comes from changing scale and duration, not from changing content.
