
Why Characters Drift Between Scenes
Every generative video pipeline eventually hits the same wall. Shot one shows a woman with a sharp jawline, an auburn bob, and a chipped enamel pin on her jacket. Shot forty shows the same character with a rounder face, a longer braid, and no pin at all. The camera moved, the lighting shifted, and the model quietly invented a new person.
This is not a defect in any single model. It is the predictable result of how diffusion and video generation systems work. Each shot is an independent sampling process, and a text prompt is a lossy description of identity. Phrases like "auburn bob" describe a category, not a specific human being. When the sampler rolls the dice again for scene two, it lands somewhere else inside that category — sometimes close, sometimes not close at all.
Text prompts describe categories, not people
Language is built for generalization. When you write "a woman in her thirties with short red hair," you are handing the model a broad region of latent space and asking it to pick a point. It picks a different point on every render, especially when the pose, lens, or lighting changes between shots.
Why drift gets worse as the project grows
Drift compounds. A small facial variation in shot three becomes a different person by shot twelve, because later shots often use earlier outputs as visual references. Errors feed forward. By the time you notice, you are facing a reshoot of the entire second act.
What consistency actually costs in post
Manual fixes are expensive in time, not money. Rotoscoping a face, color-matching skin tones, or re-running a shot with a different seed can eat an afternoon. The real fix has to happen before generation, in the conditioning signal.
What Multi-Image Fusion Actually Does
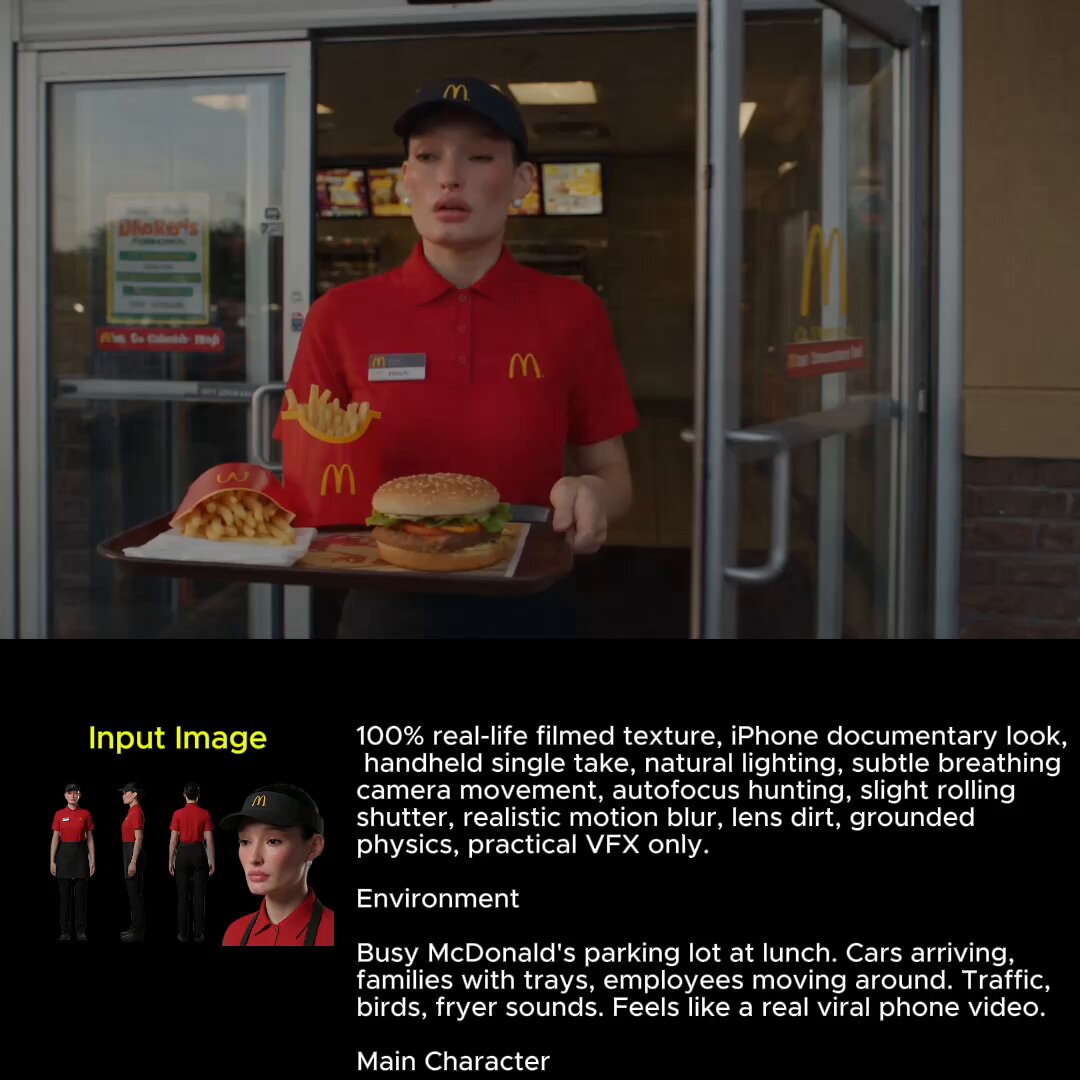
Multi-image fusion changes what the model conditions on. Instead of describing a face with words, you supply several photographs of that face. The pipeline converts those images into a compact identity representation and reuses that same representation for every subsequent generation. Same conditioning signal, same face — across angles, scenes, and even different underlying models.
The process has three layers worth understanding, because each one has a tuning knob you will eventually need.
Identity embeddings versus semantic tokens
Most fusion stacks extract two things from your references. The first is a geometric identity embedding — the proportions and distances that make a face recognizable. The second is a set of semantic tokens covering hair color, wardrobe, silhouette, and overall vibe. The first locks who the character is. The second locks how they currently look. Confusing the two is the most common source of frustration: if you change wardrobe in scene four, you want the semantic layer to move while the identity layer stays fixed.
Conditioning strength and the over-fitting cliff
Fusion strength usually runs on a scale from about 0.4 to 1.0. Low values produce a generic face that barely resembles your references. High values reproduce the reference photo almost literally, including its background, its lens distortion, and its exact head angle. The useful band is narrow — often 0.65 to 0.85 — and it shifts depending on how many references you supply and how varied they are.
Image first, then motion
The most reliable pattern is to resolve identity in still images before you generate a single frame of motion. Generate keyframes for each shot, approve them, then animate. Video models add temporal attention on top of spatial attention, and temporal attention tends to smear or drift identity if the first frame is already ambiguous.
Building a Character Reference Kit
The quality of your reference set sets the ceiling for everything downstream. Garbage references produce a character who looks plausible in one shot and unrecognizable in the next.
The shot list that works
Aim for six to ten images per character. More is not automatically better; twenty near-duplicate selfies teach the model less than eight varied ones.
- Straight-on headshot, neutral expression, even lighting
- Three-quarter view, slight smile
- Full profile, mouth closed
- Full-body standing shot, arms relaxed at the sides
- Two or three expression variants (laughing, angry, worried)
- Wardrobe and prop reference frames, shot separately if needed
Technical specifications that matter
Use files between 1024 and 2048 pixels on the long edge. Avoid heavy compression, beauty filters, motion blur, and dramatic color grading. Neutral or plain backgrounds reduce bleed into generated scenes. Keep lighting consistent across the set so the model learns a face rather than a lighting condition.
What to leave out
Sunglasses, masks, extreme low angles, group photos, and images where the face occupies less than a tenth of the frame all weaken the identity signal. If your character wears glasses, include one frame with them and four without.
| Reference slot | What it locks | Why it matters |
|---|---|---|
| Frontal headshot | Facial geometry | Primary identity anchor |
| Three-quarter view | Cheekbone and jaw volume | Prevents flattening in angled shots |
| Profile | Nose and skull shape | Critical for side-on coverage |
| Full body | Height and build | Keeps scale consistent across scenes |
| Expression variants | Muscle patterns | Reduces uncanny stillness |
Writing Prompts That Hold Identity Together
Once fusion is handling identity, your prompt should stop trying to describe the face. Redundant face descriptions fight the identity embedding and pull the render back toward a generic average.
A prompt structure you can reuse
Build every shot prompt from the same skeleton:
- Identity anchor — a short phrase, kept byte-for-byte identical across all shots, such as "character A" plus one distinctive token.
- Action and emotion — what the character is doing and feeling right now.
- Environment — location, weather, time of day, background depth.
- Camera — lens length, height, movement, framing.
- Lighting — key direction, contrast ratio, color temperature.
- Style — film stock, grade, texture, grain.
- Negative block — artifacts, extra limbs, warped hands, text overlays.
Change blocks two through six freely. Never change block one.
Prompts that fight the fusion engine
"A twenty-eight-year-old woman with high cheekbones, almond eyes, a slim nose, and a small mole on her left cheek" is a trap. It gives the model a competing description that may override your embedding. Use one or two anchor words instead, and let the references do the heavy lifting.
When to use negative prompts strategically
Negatives are useful for artifacts, not identity. Listing "different person" rarely helps. Listing "blurry, plastic skin, extra fingers, watermark, distorted background" does. Keep negatives stable across the whole project so any change in output can be attributed to the variables you actually intended to change.
A Repeatable Scene-by-Scene Workflow
Consistency comes from process discipline more than from any single setting. Here is a sequence that scales from a three-shot test to a thirty-shot episode.
Step 1: Lock the character bible
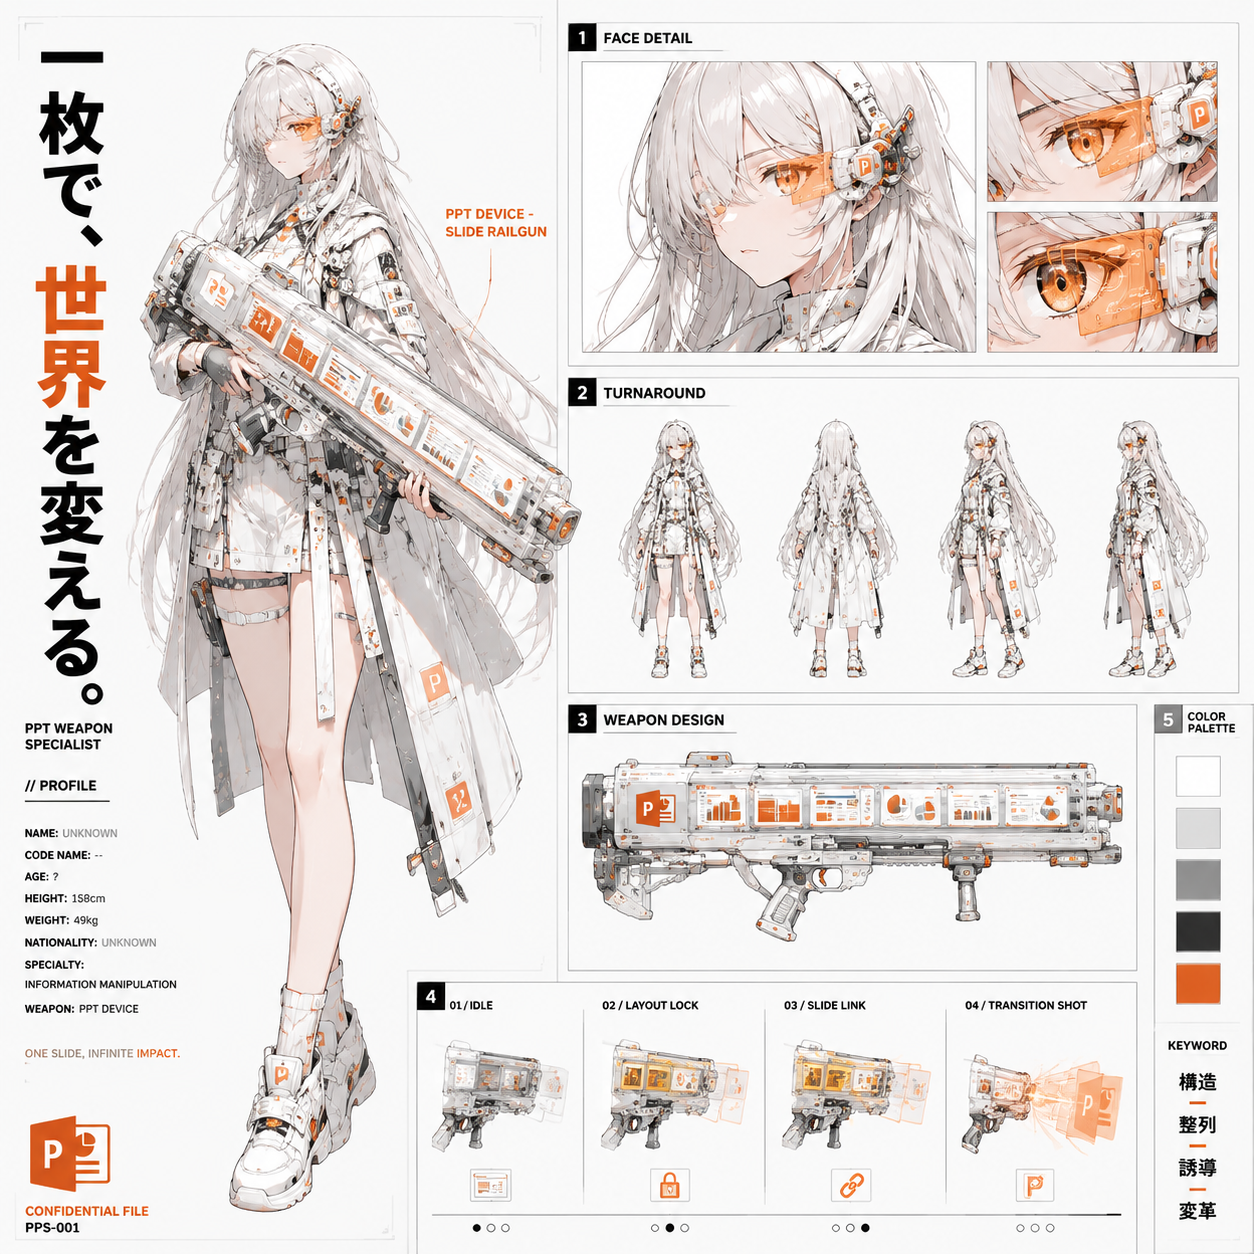
Write a one-page document per character. Include height, build, age range, default wardrobe, two alternate outfits, hair behavior in wind and rain, and a short list of signature props. This is the reference you check against when reviewing renders.
Step 2: Build and validate the reference kit
Generate a test grid of twelve images from your fusion setup before touching the story. Same prompt, same identity anchor, twelve different seeds. If three or more look like a different person, fix the references before going further.
Step 3: Generate keyframes shot by shot
Produce a single approved still for every shot in the sequence. Approve them in batches against the character bible. If a keyframe is ambiguous, regenerate it now — it is far cheaper than fixing it after animation.
Step 4: Freeze seeds and settings
Record the seed, fusion strength, sampler, and step count alongside each approved keyframe. When a later shot drifts, you can reproduce the good state instead of guessing.
Step 5: Animate with restrained motion
Image-to-video with moderate motion strength preserves identity better than text-to-video. Push the camera, not the face. Rapid head turns and extreme expressions are where temporal drift appears first.
Step 6: Repair, do not rebuild
When a shot drifts, fix the first frame and re-animate the clip rather than regenerating the whole thing from text. Most drift is inherited from an ambiguous opening frame.
Handling Emotion, Lighting, Wardrobe, and Age
Real scenes are not flat. Characters cry, step into shadow, change jackets, and appear in flashbacks. Each of these changes identity conditioning in a different way.
Emotion without identity loss
Express changes should be driven by prompt and reference, not by fusion strength. Push the emotion words harder before you touch the identity slider. If an angry expression flattens the face, add one or two expression references to the kit rather than raising fusion strength, which tends to make every shot look like the reference photo.
Lighting that does not repaint the face
Low-key lighting is where identity embeddings strain. Keep a rim or fill source in the prompt so facial planes stay readable. Three-point lighting language — key, fill, rim — is more reliable than vague mood words.
Wardrobe swaps and continuity props
Change wardrobe in the semantic layer, not the identity layer. Update the prompt's clothing block, keep the identity anchor identical, and always keep at least one signature prop constant. A scarf, a watch, or a specific jacket shape gives the viewer continuity cues that survive small facial shifts.
Aging and flashback shots
Age changes should be a separate character preset rather than a slider tweak mid-project. Build a young and an old reference kit from the start, then cross-fade between them in the edit. Trying to age a character on the fly produces uncanny results and unpredictable drift.
Choosing Models and Tools: Decision Criteria
Different projects need different trade-offs. Rather than testing everything, match the tool to the constraint that matters most.
| Constraint | What to prioritize |
|---|---|
| Long dialogue scenes | Temporal stability and lip-sync quality |
| Cinematic wide shots | Prompt adherence and lens control |
| Fast iteration | Render speed and predictable seeds |
| Multi-character shots | Per-subject fusion weights and masking |
| Stylized animation | Style reference support alongside identity |
Multi-character scenes
Two-character shots are the hardest case. Use per-subject conditioning with spatial guidance — masks, depth maps, or pose references. If the tool does not support per-subject fusion, shoot the characters in separate passes and composite.
Local versus hosted pipelines
Local setups give you reproducibility and full control over seeds and checkpoints. Hosted pipelines give you throughput and easier scaling. Many teams run both: local for keyframe iteration, hosted for final renders.
Common Mistakes and How to Fix Them
Overloading the prompt with facial detail
Symptom: characters look generic despite strong references. Fix: strip all anatomical description from the prompt and leave a single anchor phrase.
Using too few or too similar references
Symptom: identity holds at one angle only. Fix: add a profile and a three-quarter view; replace near-duplicates with genuine variation.
Cranking fusion strength to maximum
Symptom: every shot looks composited from the reference photo, with frozen expressions and mismatched backgrounds. Fix: lower strength and let the prompt carry the scene.
Ignoring aspect ratio and crop
Symptom: the face stretches in vertical formats. Fix: generate keyframes at the final aspect ratio instead of cropping later.
Reusing a seed across different shots
Symptom: composition repeats and backgrounds bleed together. Fix: hold the identity conditioning constant and vary the seed per shot.
Skipping the approval gate
Symptom: hours of animation on a flawed first frame. Fix: approve every keyframe against the character bible before it enters the animation queue.
A Shot-Level QA Checklist
Run this before any clip leaves the review stage.
- Face shape matches the character bible at this angle
- Hair length, parting, and color are correct
- Wardrobe and signature props are present and consistent
- Skin tone reads correctly under the scene's lighting
- Hands are readable and count correctly
- Background has no warped geometry near the subject
- Motion does not smear or morph the face mid-clip
- Color grade matches adjacent shots in the sequence
- Aspect ratio and framing are identical to neighbouring shots
When a clip fails, log which check failed and link it to the keyframe that produced it. Over a few projects, patterns emerge: most drift traces back to two or three recurring reference gaps.
FAQ
How many reference images do I actually need?
Six to ten varied images per character is the practical sweet spot. Eight well-chosen references outperform twenty near-identical ones, because variety teaches the model how the face behaves under different angles and lighting.
Can I keep a character consistent across different video models?
Yes, within limits. Identity embeddings transfer reasonably well between models when the reference kit is strong, but you should re-validate with a twelve-image test grid on each new model. Expect to re-tune conditioning strength, since the useful band differs between architectures.
Why does my character change when they turn their head?
Almost always a missing profile or three-quarter reference. The model has never seen that character from the side, so it improvises. Add a clean profile shot and a full-body frame, then regenerate the affected keyframes.
Should I generate the whole sequence from text or animate stills?
Animate approved stills. Image-to-video gives you an explicit identity gate at frame one, which dramatically reduces temporal drift. Text-to-video is faster for exploration, but it is the wrong tool for continuity.
What do I do when a two-character shot fails repeatedly?
Separate the characters. Generate each in the same environment with matching lighting and camera language, then composite using masks or depth. Per-subject conditioning is improving quickly, but compositing is still the most predictable route.
How do I handle a character who wears a mask or helmet?
Build two reference kits: one with the face visible, one with the covering. Lock the covering kit's identity to the silicone props, size, and weathering details. Consistency then comes from the prop rather than the face, which is much easier to hold across shots.
Is consistency slower than accepting drift?
The upfront work is slower. The project overall is much faster. A validated reference kit and an approval gate generally save more time than they cost, because they eliminate the reshoot cycles that wreck a production schedule.
Where to Start
Pick one character from a current project. Build an eight-image reference kit, write a single anchor phrase, generate a twelve-image test grid, and review it against a one-page character bible. If fewer than three of the twelve images look like a stranger, your setup is ready. Then move to keyframes, approve them shot by shot, and animate only what has passed. That loop — references, anchor, grid, approval, animation, repair — is the whole discipline. Everything else is tuning.
