
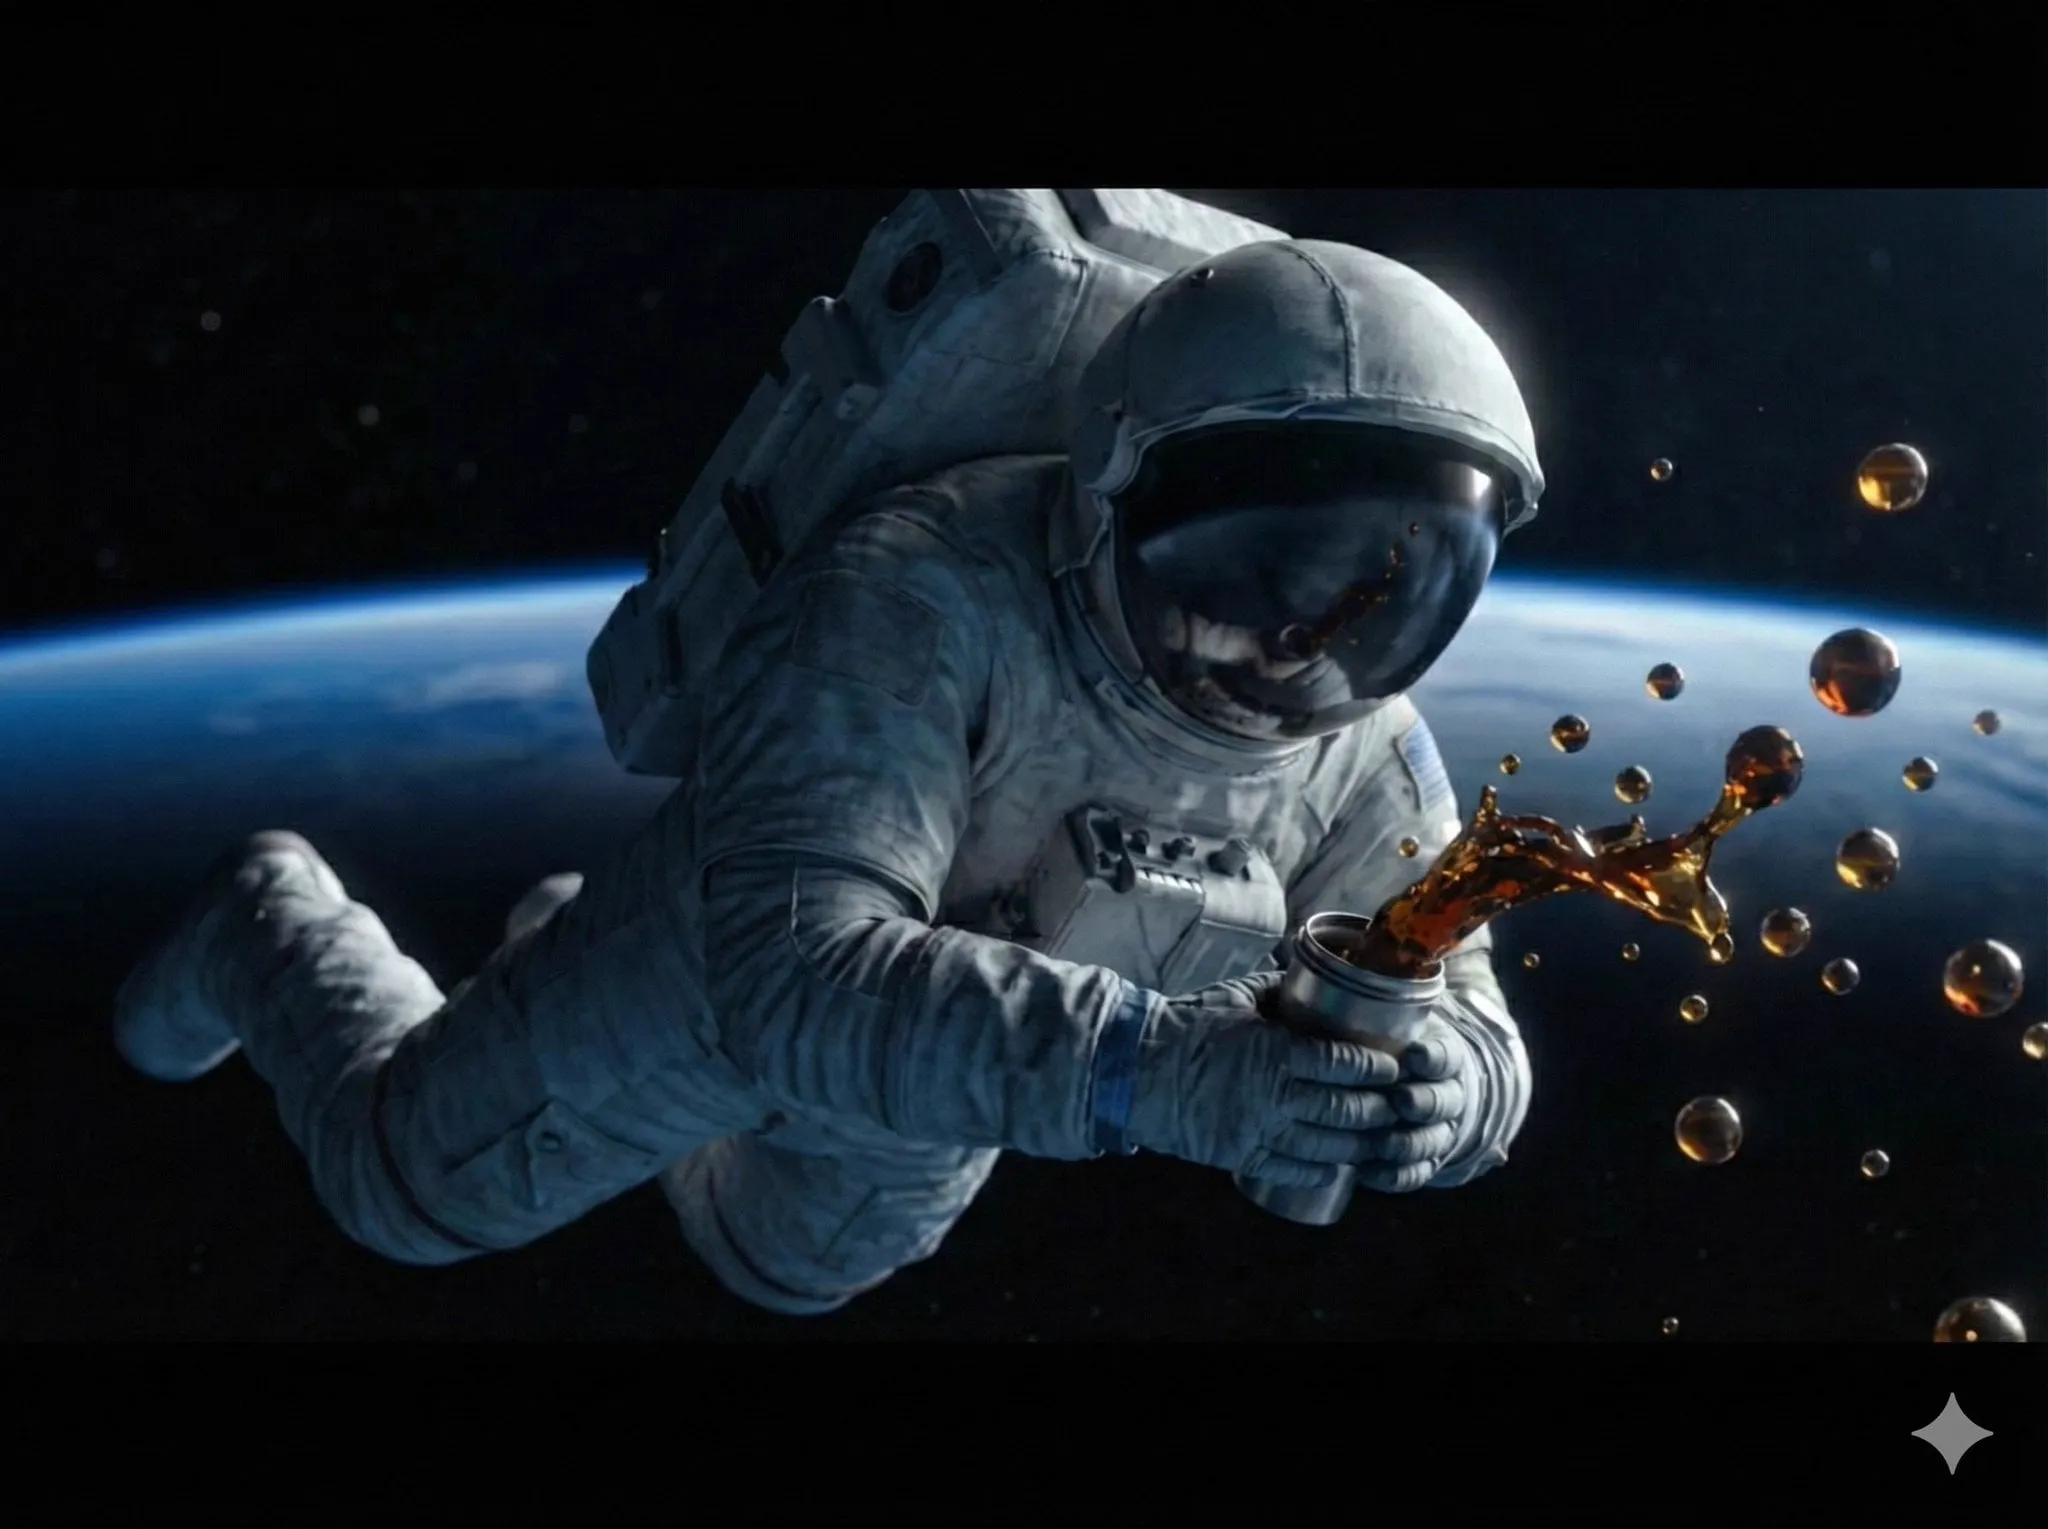
Ten years ago, a cinematic shot required a camera body, a lens kit, a lighting package, a location, a crew of at least four people, and a day of schedule. Today the same shot can start as a sentence typed into a text box, a reference image pulled from a mood board, and a five-second clip that gets cut into a timeline before lunch. The barrier has not disappeared — it has moved. It is no longer gear or budget. It is planning, visual vocabulary, and taste.
That shift is what makes AI cinematography worth learning as a craft rather than a novelty. Tools that generate images and motion are everywhere now, and they all respond to the same fundamentals: what the shot is, where the camera sits, how the light falls, and what the audience should feel. If you understand those four things, you can produce footage that survives a 60-inch screen instead of looking like a slot machine jackpot. This guide walks through a full practical workflow, the vocabulary that actually changes results, the mistakes that waste the most time, and how to decide which tools deserve a place in your pipeline.
What AI cinematography actually means
The phrase gets used loosely, so it helps to be precise. AI cinematography is not a single button that turns a paragraph into a finished film. It is a pipeline of decisions, and each stage has its own failure modes.
A typical pipeline has six stages:
- Shot intent — you decide what the shot must communicate dramatically.
- Image generation — you create a still frame that could plausibly be a frame from the finished film.
- Motion generation — you animate that frame, or generate video directly from text.
- Continuity management — you keep characters, wardrobe, locations, and lighting consistent across shots.
- Assembly — you cut shots together with rhythm, sound, and music.
- Finishing — you grade, add grain or texture, and clean up artifacts.
Most beginners jump straight from step one to step three, ask for a ten-second clip of complex action, and then blame the model when it looks wrong. Professionals treat the still frame as the real deliverable and the motion as a small addition on top of it. That single change in mindset improves output quality more than any prompt trick.
There are three broad ways to work, and each one has a different control-to-speed ratio.
- Text-to-video is the fastest and least controllable. Good for abstract B-roll, establishing shots, and experimentation.
- Image-to-video is the workhorse. You control composition and look in a still image, then add restrained camera movement and subject motion.
- Hybrid shooting is the most underrated. You film a real plate on a phone — a hallway, a hand, a street corner — then restyle or extend it with AI. Real footage carries real physics, and physics is exactly what generators still struggle with.
If you are new, start with image-to-video on short clips. It teaches you composition first, which is the part that transfers to every other tool you will ever use.
The shot language you can actually prompt
Generators do not read intentions; they read descriptions. The word "cinematic" is almost meaningless on its own because it has been used so often that it describes everything and nothing. What works instead is concrete cinematographic vocabulary, the same vocabulary a director of photography would use on a call sheet.
Here is how the main categories translate into prompt language:
| Category | What it controls | Example phrasing |
|---|---|---|
| Shot size | How much of the subject fills the frame | wide establishing shot, medium close-up, extreme close-up on the eyes |
| Camera angle | Power and perspective | low angle looking up, high angle looking down, eye level, Dutch tilt |
| Camera movement | Energy and intent | slow dolly in, handheld follow, crane rise, slow orbit around the subject |
| Lens and depth | Compression and focus | 35mm lens, 85mm portrait compression, shallow depth of field, deep focus |
| Lighting | Mood and dimensionality | soft window key with a dim rim light, hard noon sun, practical neon at night |
| Color | Emotional temperature | cool desaturated teal shadows, warm amber highlights, high-contrast monochrome |
| Texture | The feeling of film | subtle 35mm grain, slight halation around highlights, anamorphic flare |
| Time of day | Atmosphere | blue hour, overcast morning, golden hour backlight, deep night |
Why specificity beats adjectives
Compare two prompts for the same shot. The first says: "a woman walking through a city, cinematic, 4K, masterpiece, highly detailed." The second says: "medium tracking shot from behind, a woman in a grey wool coat walking through a rain-slicked alley at night, 40mm lens, shallow focus on her shoulders, neon sign reflections on wet asphalt, cool teal shadows with warm rim light, subtle grain."
The second prompt gives the model decisions to make: framing, distance, lens, focus, palette, texture. The first gives it a lottery ticket. When results disappoint, the fix is almost never "more detail" — it is "more specific decisions."
A practical habit: write your prompt in the order a camera department would talk about a shot. Subject and action first, then framing and camera, then light, then lens and texture. Keep it under about 60 words. Long prompts dilute themselves; models weight the beginning most heavily.
A step-by-step workflow from script beat to finished shot
This is the sequence that consistently produces usable footage. It assumes you have a short piece to make — a 30-second ad, a music video section, a YouTube intro, a product teaser.
Step 1: Break the script into beats, then beats into shots
Write the piece as five to eight beats. Each beat is one idea: "she notices the letter," "he runs," "the city at dawn." Then assign one or two shots per beat. A 30-second piece usually needs eight to fourteen shots, most of them two to four seconds long.
If you cannot describe a shot in one sentence, it is not a shot yet — it is a scene, and it needs to be broken down further.
Step 2: Build a reference board before you generate anything
Collect eight to twelve images that share a look: color palette, contrast, lens character, lighting direction. These do not have to be AI-generated. Film stills, photography, paintings, and architectural references all work. The board is not decoration — it is your consistency anchor. When a generated frame feels off, you compare it against the board instead of guessing.
Step 3: Write image prompts from a fixed template
Use the same template for every shot so you only vary the elements that should change:
[shot size] of [subject + action], [location], [time of day],
[lighting setup], [lens and depth of field], [color palette],
[texture or film stock feel], [aspect ratio]
Keeping the tail of the prompt constant — lens, palette, texture, aspect ratio — is the cheapest consistency trick available. Half of the "look" of a film is repeated constraints, not repeated subjects.
Step 4: Generate wide, then refine one variable at a time
Generate four to eight variations of each shot. Pick the one that reads best at thumbnail size, because that is how audiences will actually see it in a feed. Then refine. Critically: change one element per iteration. If you rewrite framing, lighting, and wardrobe at the same time, you cannot tell which change helped.
Step 5: Animate with restraint
Animate the still you selected. Motion prompts should describe one movement and one small action: "slow dolly in, she turns her head slightly toward camera." Ask for too much and the model invents anatomy, dissolves faces, or warps the background.
Keep generated clips short — three to six seconds. Long clips almost always drift. You will get a better result from three short clips cut together than from one long clip that slowly falls apart.
Step 6: Enforce continuity with a written bible
Create a single document that lists, for every recurring element:
- Character description block: age range, hair, wardrobe, distinguishing features, exactly as you prompt them.
- Location block: architecture, materials, signage, time of day, weather.
- Lighting rule: which side the key comes from, what the palette does in day versus night.
- Lens rule: focal length and depth-of-field behavior for interiors versus exteriors.
Copy-paste from this document instead of retyping. Small wording drift creates large visual drift.
Step 7: Assemble before you polish
Cut the shots to a scratch track — a temp music bed or a voiceover demo. Most cuts should land on a beat or on a movement. Two to four seconds per shot is a good default for social; faster feels frantic, slower feels like a slideshow.
Do not start fixing small artifacts until the edit works with placeholder visuals. Rhythm problems cannot be graded away.
Step 8: Run a quality-control checklist
Before exporting, check every clip for:
- Hands, teeth, and ears — the classic failure zones.
- Text and signage, which often renders as gibberish.
- Reflection and shadow direction consistency between adjacent shots.
- Physics: liquid, cloth, hair, smoke, and anything falling.
- Flicker or pulsing between frames on longer clips.
- Face stability at the start and end of each clip, where drift is worst.
Cut around problems rather than fighting them. A one-second trim solves more than an hour of regeneration.
Continuity: the problem that decides perceived quality
If you ask experienced creators what separates amateur AI video from professional work, most will say continuity. Audiences forgive an imperfect hand. They do not forgive a character whose jacket changes color between cuts.
Three techniques carry most of the weight:
Character sheets. Generate a single reference image per character in neutral light, then use that image as the starting point for every shot that character appears in. When a tool supports image prompting, this is the most reliable anchor available.
Locked prompt blocks. Keep wardrobe, hair, and facial-description sentences identical across shots. Do not paraphrase. "Grey wool coat over a black turtleneck" stays exactly that in every prompt.
Environment rules. Decide what never changes about a location — the wall color, the window position, the street width — and repeat it. If a scene happens at night, keep the night lighting logic consistent even when the camera moves indoors.
A fourth technique is more editorial than technical: hide the seams. Shoot a cutaway, insert a reaction, or use a match cut when two shots almost match but not quite. Editing exists partly to solve problems that generation creates.
Common mistakes and how to fix them
Overloading the prompt. Fix: cap the prompt, delete synonyms, and keep the first fifteen words about subject and framing.
Asking for complex action in one clip. Fix: split the action into two shots with a cut between them.
Ignoring sound. Fix: add room tone, foley, and a music bed. Sound carries more perceived production value than resolution. A slightly soft image with good sound reads as professional; a sharp image with silence reads as a test render.
Chasing the perfect single frame. Fix: generate more variations faster and cut better. The edit is where quality is decided.
Using real people's likenesses. Fix: use synthetic or fully consented faces. Likeness is a legal and reputational risk that no shortcut justifies.
Believing the model wrote your story. Fix: write the beat sheet yourself. Generators are excellent at rendering and terrible at dramatic intent.
Treating one tool as the whole pipeline. Fix: accept that you need a still generator, a motion tool, an editor, and a sound source. The combination is the craft.
Choosing tools: decision criteria that matter
Tool lists go stale quickly, so it is more useful to know how to evaluate whatever is in front of you. Test every candidate against the same short benchmark: one medium shot of a person walking through a doorway, one product close-up, one landscape establishing shot. Same prompt, same aspect ratio, same effort budget.
Then compare on these axes:
- Motion realism. Does cloth, hair, and liquid behave plausibly, or does it smear?
- Camera control. Can you specify movement type and speed, or do you only get "cinematic pan"?
- Consistency features. Does it accept a reference image or character anchor?
- Clip length before drift. Where does quality fall off — four seconds, eight, twelve?
- Licensing and commercial rights. What does the terms of service permit for client work?
- Aspect ratios. Vertical for social, widescreen for film, square for ads.
- Speed and queue behavior. How long is a generation at your typical settings?
- Cost model. Subscription versus per-generation pricing determines how freely you can experiment. If you cannot afford forty failed attempts, you will not find the good frame.
- API or batch access. Essential if you plan to produce at volume or automate variations.
A useful rule: pick one still-image tool and one motion tool and learn them deeply for a month. Tool-hopping is the most common reason creators plateau.
Three scenarios where this workflow pays off fastest
A 20-second product ad. Beat sheet: problem, product reveal, macro detail, real-world use, logo. Nine shots. Generate macros and lifestyle frames as stills, animate with slow push-ins, cut to a music bed with accents on the logo reveal. Total production time: an afternoon.
A music video section. Prioritize texture and rhythm over narrative. Build five looks — neon night, harsh daylight, underwater, mirrored corridor, slow motion crowd — and alternate them on the beat. Continuity matters less here; color and cutting tempo carry the piece.
Documentary-style B-roll. This is where hybrid shooting wins. Film a real street, workshop, or kitchen, then use AI to extend the location, restyle the grade, or generate matching inserts of details you could not capture. Real plates with generated inserts look more credible than fully generated sequences.
Rights, likeness, and disclosure
Three rules keep you out of trouble. First, do not generate recognizable real people, trademarked characters, or protected logos without permission. Second, read the license for the specific tool you use — several permit personal use but restrict commercial distribution, and terms change. Third, disclose synthetic footage when a reasonable viewer could be misled, especially in news, advertising claims, and testimonials.
Also keep your source materials organized: reference images, generated stills, prompts, and export versions. If a client asks how a shot was made, a clean project folder is the answer.
Frequently asked questions
Do I need editing experience to make this work?
You need basic cutting skills, which take a weekend to learn. The edit is where AI footage is either saved or wasted.
How long should each generated clip be?
Three to six seconds for most narrative work. Longer clips tend to drift in faces, hands, and background detail.
Why does my footage look like AI even when the composition is good?
Usually because of three things: no sound design, uniform sharpness with no lens character, and cuts that do not respect rhythm. Add grain, vary depth of field, and cut on beats.
Can I mix generated footage with real camera footage?
Yes, and it is one of the strongest approaches. Match palette, contrast, and grain in the grade, and keep generated shots short so viewers do not have time to study them.
What is the fastest way to improve consistency?
Write a character and location bible, copy-paste from it instead of retyping, and always start from a reference still when the tool supports it.
Do I still need a shot list?
More than ever. Without one, you generate endlessly without assembling anything.
What resolution should I export?
Match your delivery platform. Upscaling after the fact is fine for social, but for anything shown large, generate at the highest native resolution your tools support.
Building a pipeline you can reuse
The most valuable output of your first AI video project is not the video. It is the system: a shot-list template, a prompt template with your locked tail of lens and texture, a character and location bible, and a quality-control checklist. Everything after that gets faster, and speed is what lets you experiment, which is what produces good frames.
Start small. Pick one beat, one shot, one look. Nail it, then build outward. The craft has not changed — you are still deciding where the camera stands and what the light does. You have simply removed everything between you and that decision.
