
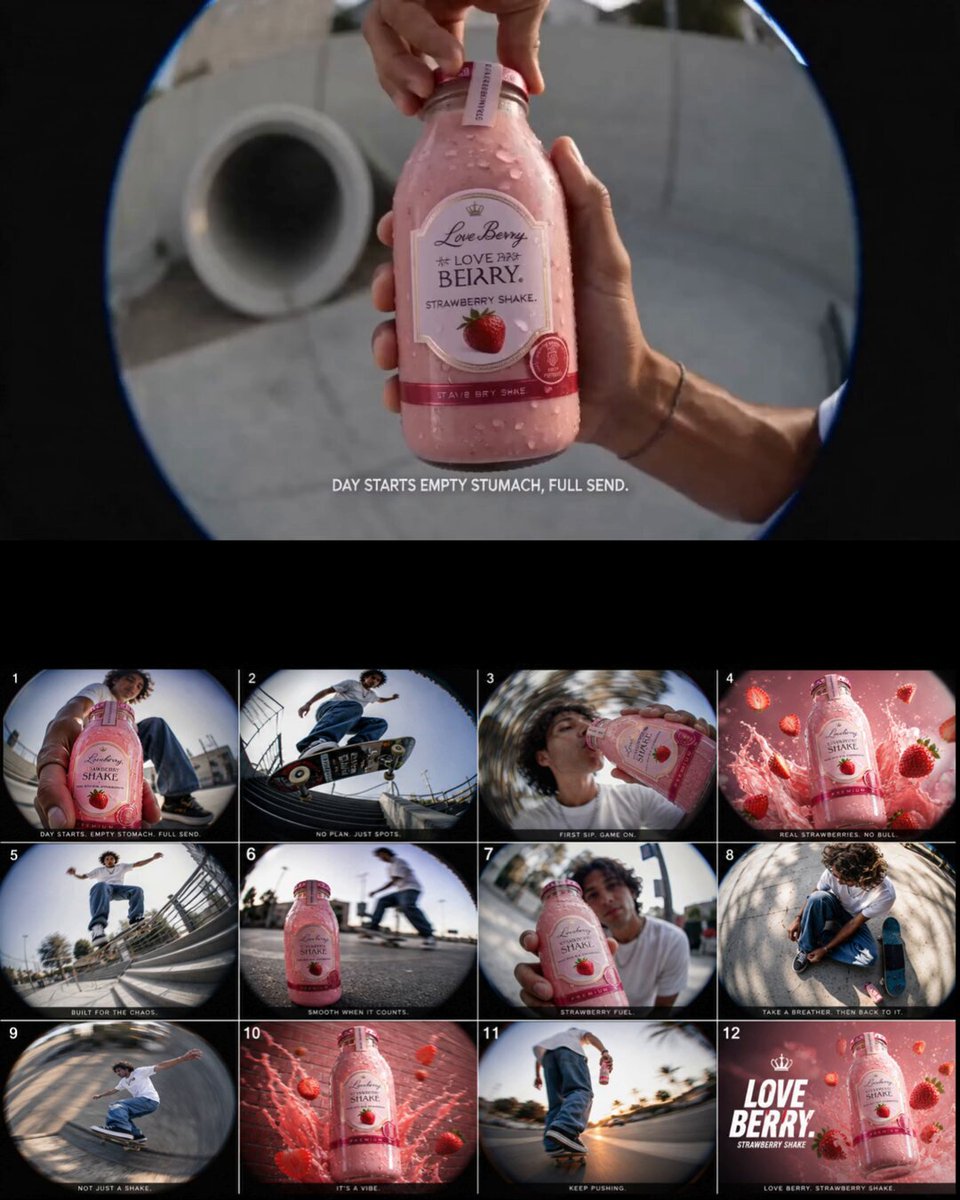
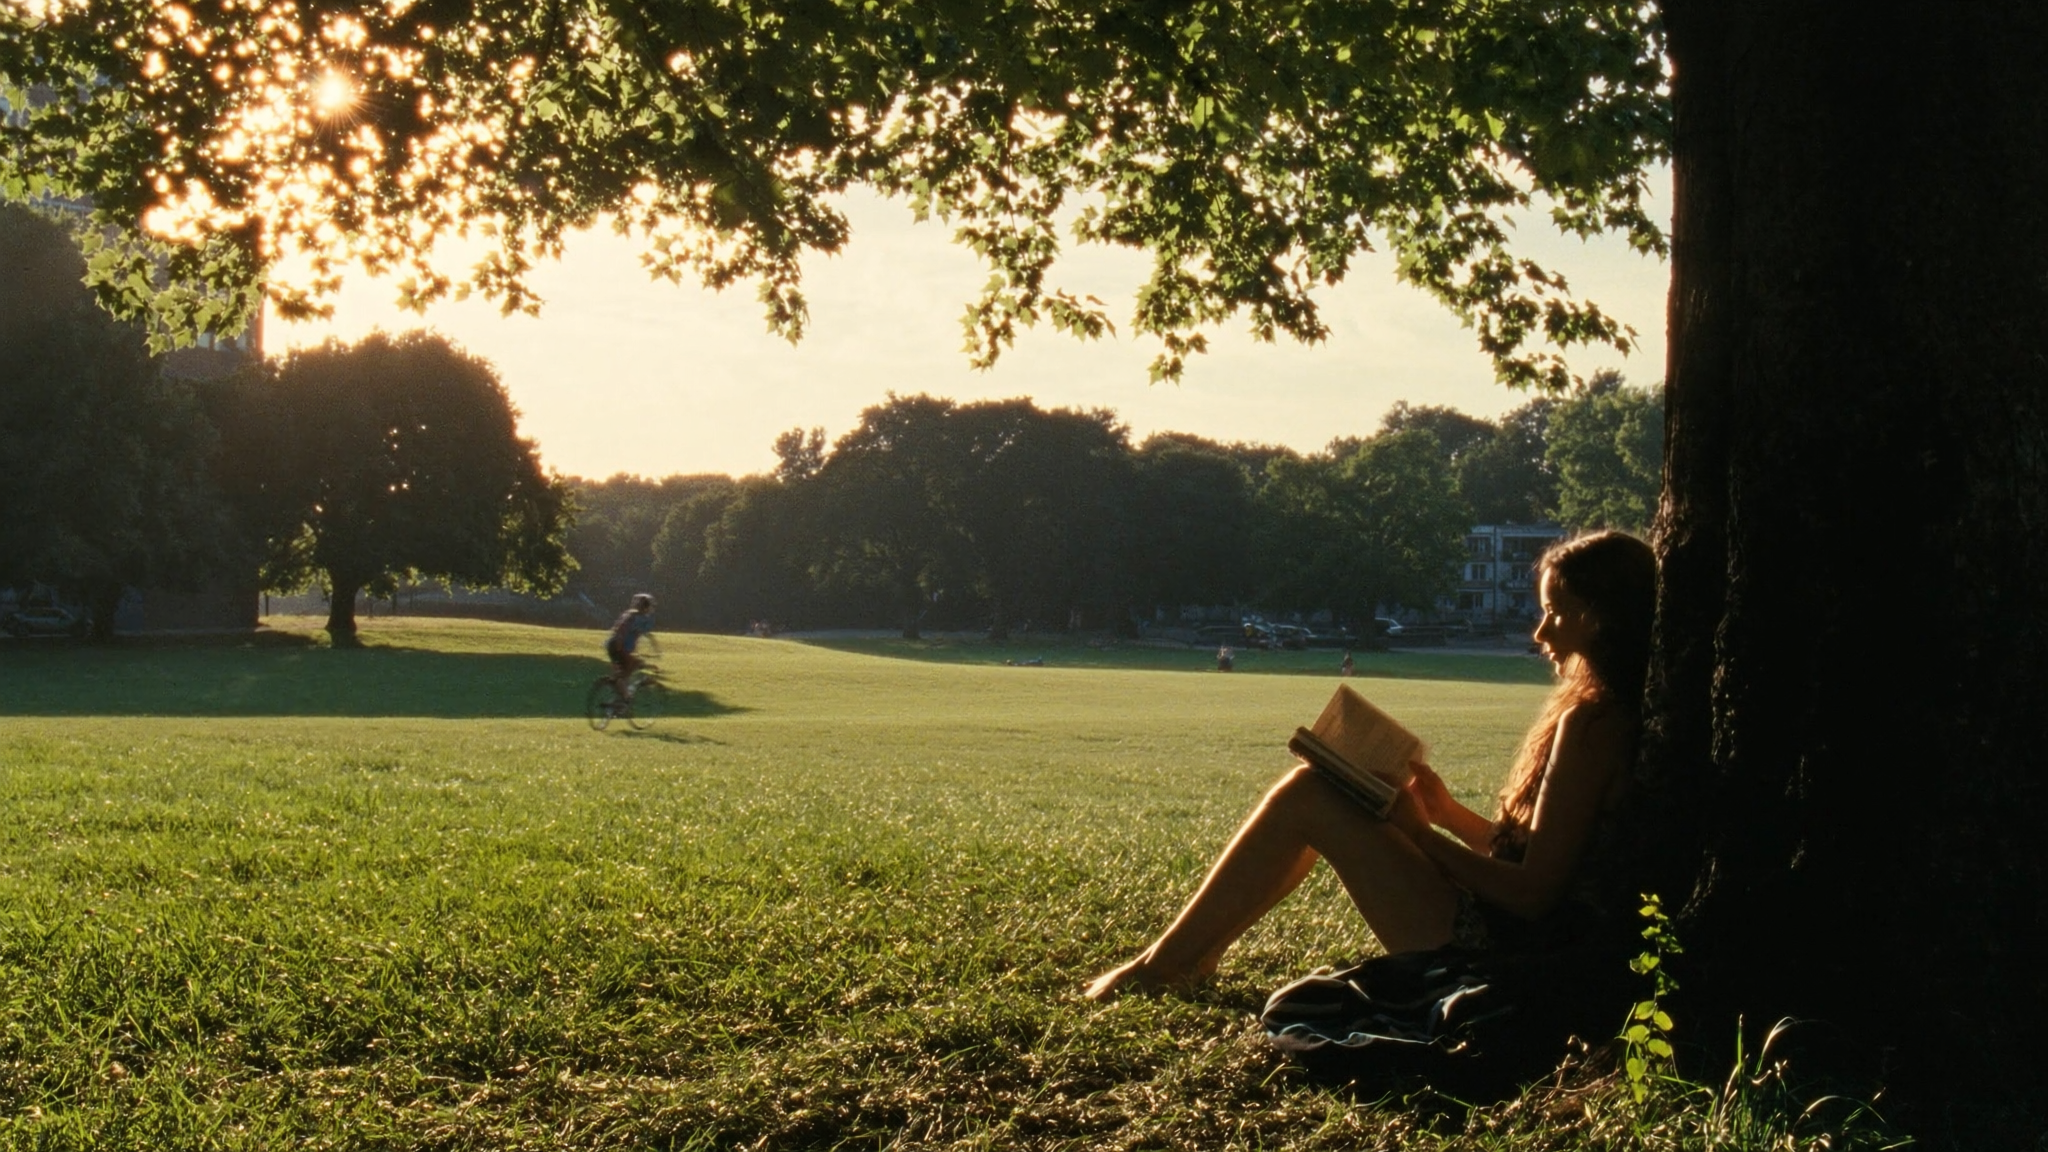
A single photograph used to be the end of the line. You could retouch it, crop it, print it, or post it — but the image stayed still. Image-to-video generation changes that assumption. You hand a model one frame, describe how the world should move inside it, and receive a short clip that looks like it was filmed by someone standing in the same place.
The practical value is obvious for anyone who produces visuals at volume: marketers, illustrators, e-commerce teams, indie filmmakers, and social creators. A product shot becomes a slow orbit. A portrait gains a blink and a subtle head turn. A concept art piece becomes a five-second mood clip you can cut into a pitch deck.
This guide is a working manual rather than a leaderboard. Tool rankings age quickly; workflow knowledge does not. Below you will find how the technology actually behaves, how to choose between the options available, how to write motion prompts that survive contact with reality, and the mistakes that waste the most time.
Why Stills Are Suddenly a Video Format
For years, the bottleneck in video production was capture. You needed a camera, a subject, lighting, a location, and time. Generative models removed the capture requirement for a specific class of shots: anything that can be inferred from a single strong frame.
That class is larger than people expect. Establishing shots, product hero moments, title backgrounds, social loops, animated illustrations, and previz beats all work well when you already have a good image. The image carries composition, color, subject identity, and style. The model only has to add motion and temporal consistency.
This is why image-to-video tends to be more controllable than pure text-to-video. You are not asking a model to invent a scene from a sentence. You are asking it to continue something you already approved. That shifts creative authority back toward the person with the reference, which is exactly where most production teams want it.
How Image-to-Video Actually Works
Diffusion, transformers, and temporal coherence
Most current systems combine a diffusion-style image backbone with a temporal component that predicts how pixels move between frames. Early approaches animated latent noise per frame and then tried to smooth the result, which produced shimmer and identity drift. Modern architectures treat the clip as a volume of data — width, height, and time — so the model can reason about motion across the whole sequence at once.
Transformer blocks help here because attention can connect a patch of the first frame to the corresponding patch several frames later. That is what keeps a face recognizable, a logo readable, and a horizon straight while the camera moves. When people describe a tool as "consistent," they are usually describing how well that attention mechanism holds identity over time.
The practical consequence: motion quality and identity quality are separate problems. A clip can have beautiful camera movement and a morphing face, or a locked-off stable subject with lifeless motion.
What the model really needs from you
The model only knows what the still tells it. If the image is soft, low-contrast, or ambiguous about depth, the animation will guess — and guesses show up as warping. A sharp, well-lit frame with clear foreground and background separation gives the model an obvious hierarchy of what should move and what should stay anchored.
Resolution matters less than clarity. A clean 1024-pixel frame with defined edges usually outperforms a noisy 4K frame. Aspect ratio matters more than resolution: match the ratio to your delivery format before generating, because cropping after the fact can cut off the motion you paid to create.
Image-to-Video vs Text-to-Video: Which One to Choose
Text-to-video is the right tool when the scene does not exist yet. You want a specific idea, you have no reference, and you are comfortable iterating on language until something interesting appears. It is fast for exploration and weak for brand control.
Image-to-video is the right tool when the look is already decided. You have a photograph, a render, an illustration, or a frame from an existing edit, and you need it to move without changing its identity. It is slower per idea but far more predictable.
The strongest workflows combine both. Generate a still with an image model, refine it in an editor until the composition is exactly right, then animate it. That three-stage pipeline — generate, refine, animate — gives you precise control at the stage where control is cheapest, and it avoids the common trap of trying to fix composition through motion prompts.
Building a Repeatable Image-to-Video Workflow
Step 1: Prepare the still
Fix composition first. Crop to final aspect ratio. Remove distracting background elements, sharpen edges, and check that the subject is not touching the frame border — models often stretch or smear content at the edges.
If you plan to animate a face, make sure the eyes are visible and the head is not at an extreme angle. Three-quarter views animate more convincingly than full profiles or heavy foreshortening.
Step 2: Write motion, not description
Your prompt should not restate what is visible. The image already contains that information. Describe only what changes: "slow push in, hair moving gently, background bokeh drifting, no camera shake."
Name the camera behaviour explicitly, because models default to whatever their training data favours. If you do not specify, you may get an unwanted zoom, a drift, or a handheld wobble you never asked for.
Step 3: Set duration, motion strength, and camera
Short clips are more reliable than long ones. Five seconds of clean motion almost always beats ten seconds that dissolve into artifacts in the second half. Generate short, then extend the winners if the tool supports continuation.
Motion strength is the single most misunderstood control. High strength produces dramatic movement and higher failure rates. Most professional-looking results sit in the low-to-medium range, where the subject moves subtly and the frame stays intact.
Step 4: Review at full speed, then frame by frame
Watch the clip once at normal speed and judge it as a viewer. Then scrub through it frame by frame and look for the tells: flickering textures, edges that breathe, hands that change shape, text that reflows.
Keep a short list of what went wrong and adjust one variable at a time. Changing prompt, motion strength, and seed simultaneously teaches you nothing.
Step 5: Extend, stitch, and finish in the edit
Treat generated clips as footage, not as finished scenes. Normal editing tools fix most problems: cut before the artifacts appear, speed-ramp to hide weak sections, add grain to unify shots from different tools, and stabilize in post if the camera drifts.
Stitching several short clips from the same source image is often more effective than requesting one long generation. You keep the strongest seconds and discard the rest.
Choosing a Tool: Decision Criteria That Matter
The market is crowded and the marketing is loud. Ignore the demos and evaluate against the criteria that affect your production week.
Motion realism and camera control
Can you request a specific camera move — dolly, pan, orbit, crane — and get approximately that? Some tools respect camera language; others ignore it. Test with a fixed prompt across three tools and compare.
Identity and style consistency
Generate three clips from the same portrait. Does the person stay the same person? Does the illustration style hold, or does it drift toward photorealism? This is the single best predictor of whether a tool is usable for series work.
Resolution, duration, and export control
Check the maximum duration per generation, the native output resolution, and whether you get a clean file without watermarks on your plan. Also check whether the tool returns a deterministic seed you can reuse.
Commercial rights and reproducibility
Confirm the licence terms for commercial use before you build a campaign around a tool. Reproducibility matters too: if you cannot recreate a result months later, you cannot shoot pickups or match a new clip to an old one.
Cost structure and iteration budget
Most platforms meter usage through subscription tiers, generation limits, or per-second render pricing. The important number is not the headline price — it is the cost of a usable five-second clip, including the failed attempts. A cheap tool with a 20 percent success rate is often more expensive than a premium tool with a 70 percent success rate.
Also weigh queue times. If each generation takes ten minutes, your iteration loop becomes the bottleneck, not your budget.
Prompting Motion: Patterns That Work
A reliable motion prompt has four parts: subject behaviour, camera behaviour, environmental behaviour, and negative constraints.
An example for a portrait: "Subject blinks slowly and turns head slightly to the left, camera locked off with a very slow push in, soft window light shifting on the cheek, no facial distortion, no camera shake, no background warping."
An example for a product: "Liquid inside the bottle ripples gently, camera orbits ten degrees to the right at constant speed, specular highlights travel across the label, no text distortion, no logo deformation."
An example for a landscape: "Clouds drift left to right, grass sways in a light breeze, camera holds static with a subtle parallax, no flicker in the sky gradient."
Three rules make these work. Keep it under roughly forty words. Use one primary motion and at most one secondary motion. Always state what must not change — text, faces, logos, and straight lines are the first things models break.
Common Mistakes and How to Fix Them
Describing the image instead of the motion. "A woman in a red coat standing in a snowy street" gives the model nothing to animate. Replace it with motion verbs.
Overloading the prompt. Five simultaneous movements produce a mess. Pick the one movement the shot exists for.
Asking for long clips immediately. Generate short, verify, then extend. Long single generations are where artifacts concentrate.
Ignoring aspect ratio. Animating in one ratio and delivering in another forces a crop that can remove your motion. Decide the format first.
Animating weak source images. If the still is blurry or cluttered, no prompt will rescue it. Fix the image or generate a better one.
Treating output as final. Generated clips are raw material. Color, grain, sound, and pacing are added in the edit, and that is where the polish comes from.
Never saving settings. Keep a small log of prompt, motion strength, seed, and tool for every usable clip. When a client asks for "more like that one," the log is the answer.
Where This Fits in Real Production
Marketing and social
Static ad variants can be animated into short loops for feed and stories without reshooting. The cost per variant drops sharply, which makes broader A/B testing practical. Keep clips under six seconds and lead with motion in the first second.
E-commerce and product
A single studio photograph can become an orbit, a light sweep, or a subtle liquid movement. This replaces some turntable shoots, though not all — complex mechanical motion still needs real footage.
Storyboarding and previz
Directors can animate concept art to communicate a camera move before the shoot day. Even imperfect clips settle arguments about framing faster than a paragraph of description.
Illustration and motion design
Illustrators can bring flat artwork to life with restrained parallax and texture motion, keeping the drawn style intact instead of converting it into 3D.
FAQ
How long does a generated clip typically need to be?
Most usable output lands between three and six seconds. Longer sequences are usually built by stitching several short generations, which also gives you more control over the final cut.
Can I animate text or logos without distortion?
Sometimes, but never by default. Keep text areas static in the prompt, use low motion strength, and verify frame by frame. For critical branding, composite the logo in post instead of generating it.
Do I need a powerful computer?
Usually not. Most tools run in the cloud through a browser. Local options exist but demand a strong GPU and reward technical patience.
Why does my face keep changing between clips?
Identity drift comes from weak temporal attention and vague prompts. Use a clear, well-lit source image, keep motion small, reuse the same seed when possible, and avoid prompts that describe the person rather than the movement.
Is image-to-video good enough for client work?
Yes for backgrounds, product shots, mood pieces, and social variants. It is riskier for close-up dialogue and complex choreography, where real footage still wins on reliability.
How many attempts should I expect per usable clip?
Budget three to five generations per finished shot as a realistic baseline, and more for ambitious camera moves. Plan your iteration time accordingly rather than assuming the first result will be final.
Final Checklist Before You Export
Confirm the aspect ratio matches delivery. Watch the clip at full speed for viewer impression, then scrub for artifacts. Check faces, hands, text, and straight edges specifically. Verify that the motion serves the shot rather than merely existing. Add grain, sound, and color in the edit so the clip sits with surrounding footage. Save your prompt, seed, and settings for reuse.
Image-to-video is not a magic button, but it is a genuine production shortcut for anyone who already works with strong stills. Treat it as a camera you can point at an existing image — and the results get predictable fast.
