
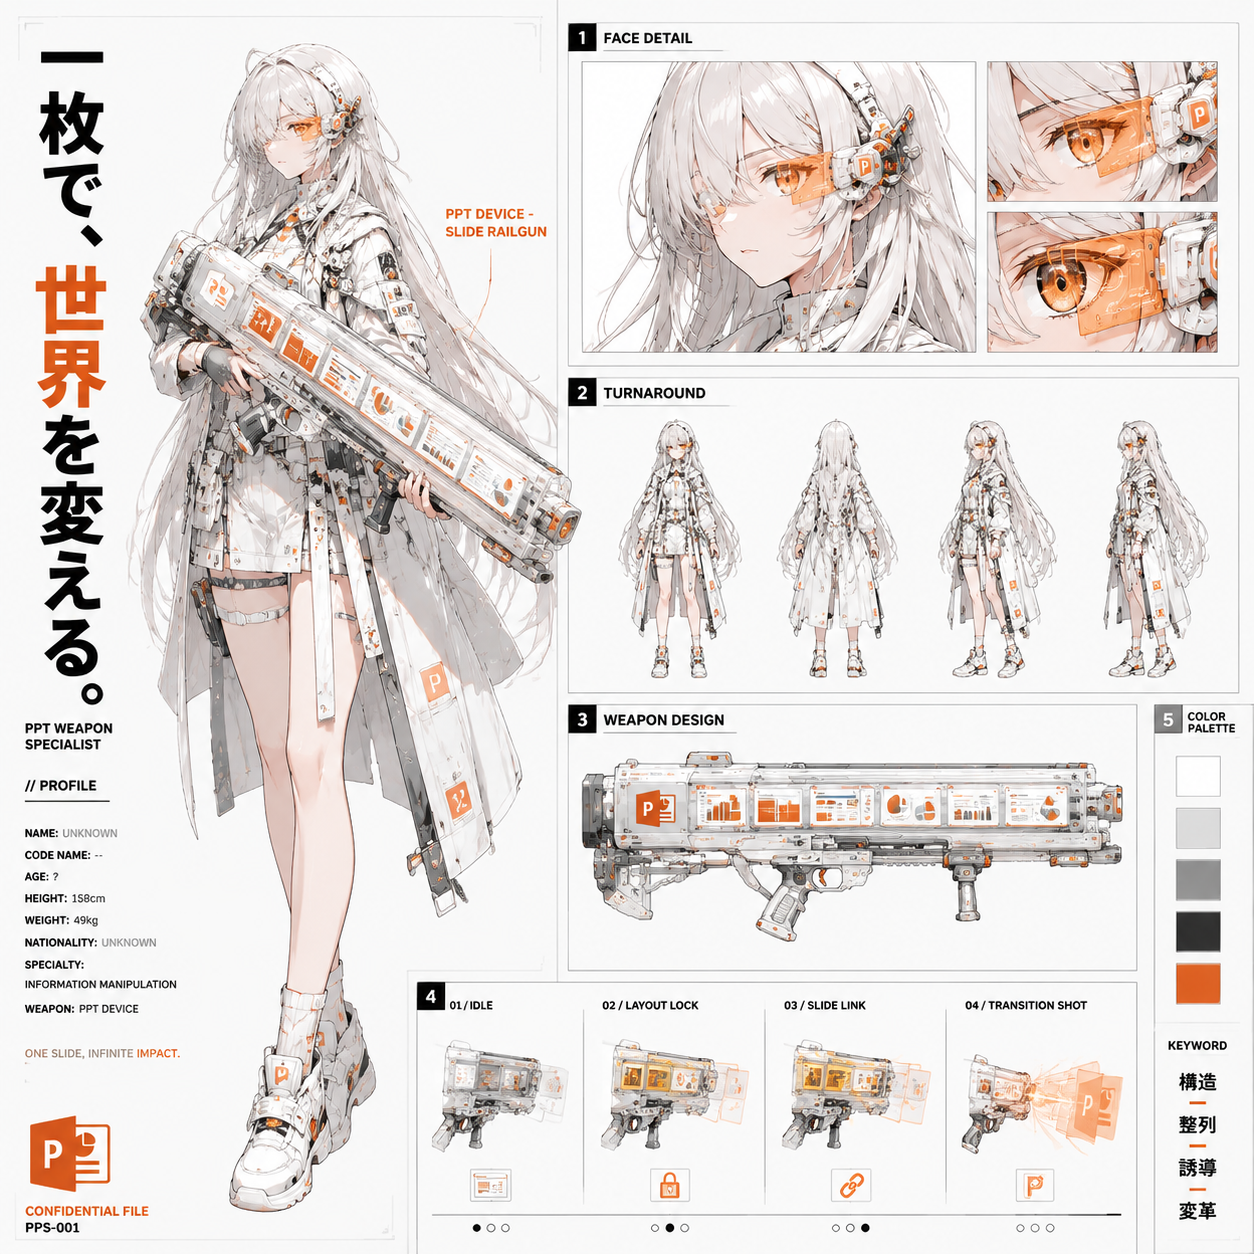
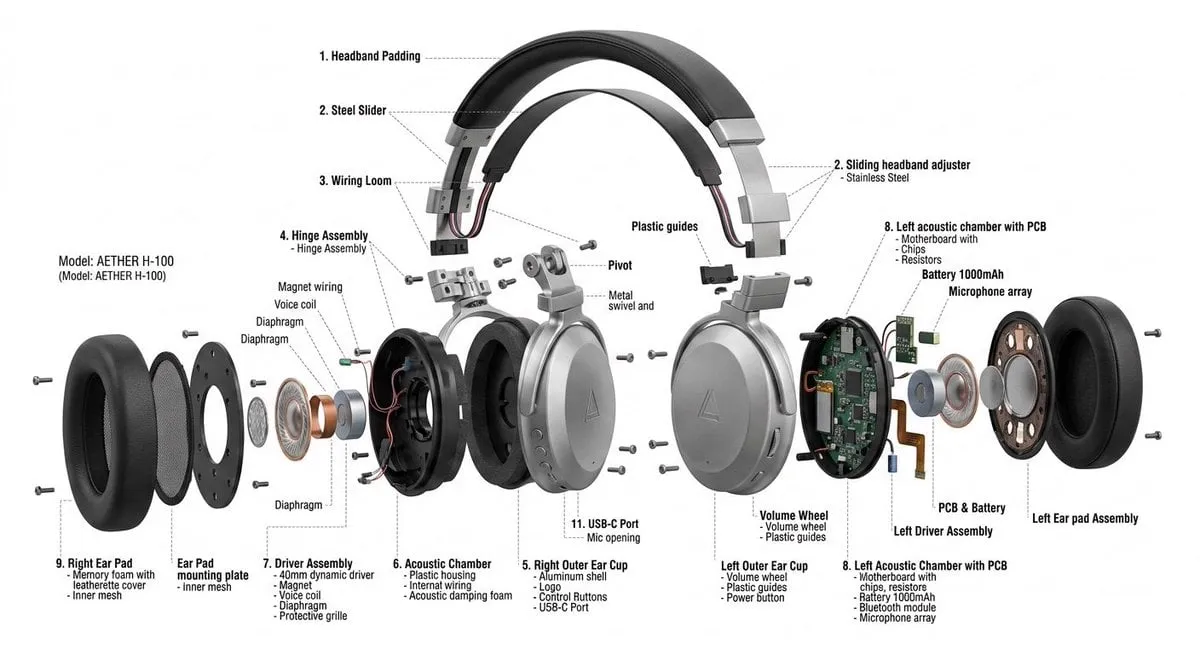
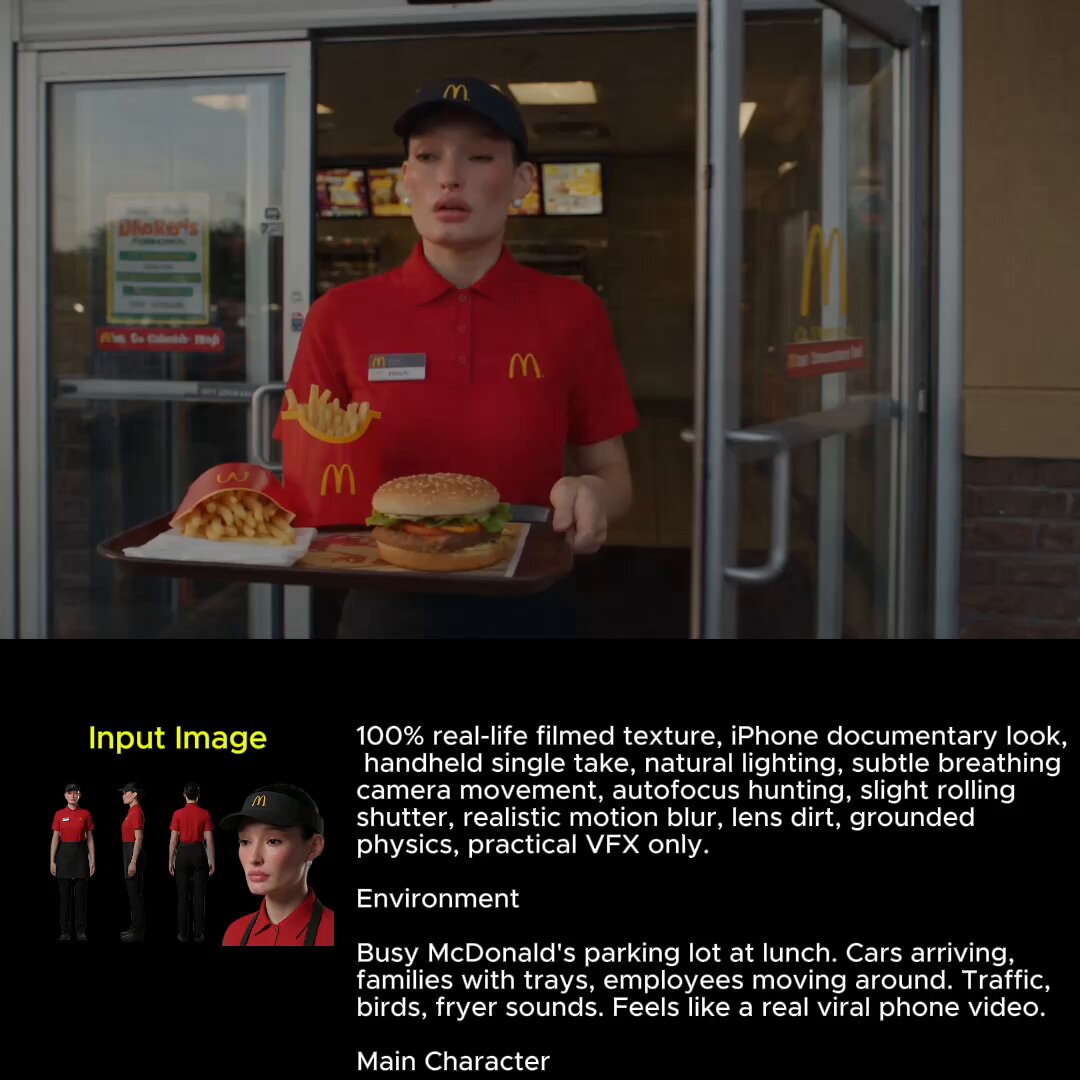
Still images are the most controllable asset in any production pipeline. You can art-direct a frame precisely, light it, compose it, retouch it, and know exactly what it will look like before anyone books a studio. Image-to-video generation takes that finished frame and extends it into time. Rather than describing a scene in words and hoping the model interprets you correctly, you hand it a visual anchor and ask a much narrower question: what happens next?
That shift matters more than it sounds. Text-to-video asks a model to invent composition, subject, lighting, and motion all at once. Image-to-video asks it to invent motion only. Fewer variables means fewer ways to fail, tighter iteration loops, and results that actually match the storyboard you already approved.
The practical consequence is that photographers, illustrators, and designers can move into motion work without rebuilding their visual language from scratch. A portrait that already works becomes a living portrait. A product still becomes a rotating hero shot. A concept painting becomes the establishing shot of a short film. The craft you already have stays relevant; only the delivery format changes.
This guide covers how these systems work under the hood, how to prepare source images that animate cleanly, how to write motion prompts that behave predictably, and how to build a repeatable workflow around short takes, review cycles, and finishing steps.
How image-to-video models actually work
Most modern systems start from a pretrained image or video generator and condition it on your still. Underneath the interface, three things have to agree: identity, geometry, and time. When they disagree, you get artifacts that no amount of prompt tweaking will fix.
The source frame acts as a strong prior
A good source image removes most of the guesswork. The model no longer has to invent a face, a color palette, or a lighting setup, because all of it is already resolved in pixels. This is why the same prompt produces wildly different results in text-to-video but fairly consistent results in image-to-video. The still is doing the heavy lifting of art direction; the prompt is only choreographing.
The trade-off is fidelity to your frame. If the model misreads your image, treating a reflection as a doorway or a shadow as an object, it will animate that mistake confidently and consistently. Clean, unambiguous source material is worth more than any prompt trick you will find.
Temporal coherence is the hard part
Generating a single beautiful frame is a solved problem. Generating thirty of them that look like the same moment is not. Temporal coherence covers flicker in flat areas, texture crawling on fabric, hair that boils instead of flows, and edges that shimmer. Models handle slow, small movements far better than fast, large ones, which is why a two-second push-in almost always looks better than a two-second whip pan.
The practical rule: the more the model has to invent between frames, the more likely something breaks. Keep motion modest, keep the camera deliberate, and keep clips short.
What the text prompt really controls
The prompt is a director's note, not a script. It should describe camera behavior, subject action, speed, and atmosphere, which are exactly the things that are not visible in a still. Phrases like slow dolly in, she turns her head to the left, steam rising, handheld micro-shake, or warm afternoon light shifting give the model something concrete to schedule across frames.
Re-describing the image wastes prompt space. A woman in a red coat standing on a bridge tells the model nothing it cannot already see. She turns toward the camera as the wind lifts her collar tells it everything about what should change.
Preparing a source image that animates well
Resolution, aspect ratio, and edges
Feed the model enough pixels to work with, but not so many that generation slows to a crawl or starts throwing artifacts. A crisp image that is already close to your target aspect ratio will beat a huge one that has to be cropped and rescaled. Keep faces sharp, avoid heavy compression noise, and make sure nothing important sits right at the frame edge where motion will push it out or drag empty background in.
Depth cues and subject separation
Motion reads best when the model understands what is in front and what is behind. Clear foreground and background separation, visible shadows, and consistent perspective give it that map. Flat, evenly lit images with no depth cues tend to produce motion that looks like a sliding sticker rather than a camera move through space.
If you are compositing, fake the depth explicitly. Put the subject on its own layer, add a soft blur to the background plate, and let the model parallax between them.
Mattes, layers, and composites
For product shots, logos, and any frame where a specific element must stay pixel-accurate, split the image. Generate the moving background separately, then composite the untouched product cutout over it. You get real motion without a single warped edge on the thing that has to be perfect. This hybrid approach, generative background plus deterministic foreground, is the most reliable pattern in commercial work.
Writing motion prompts that behave predictably
Separate camera from subject
Write two clauses, not one sentence. Camera: slow dolly in, slight tilt up. Subject: she blinks and turns her head to the right. Mixing them into a single run-on description makes it harder to diagnose which instruction caused a bad result, and harder to swap one instruction out during iteration.
Keep each take to one beat
A clip should do one thing. Push in. Turn. Rise. Walk. When a prompt stacks four actions into four seconds, the model rushes and squeezes, and everything looks sped up. If your story needs a sequence, generate the beats as separate takes and cut them together. You get better motion and far more editorial control.
Use negative guidance sparingly
Long lists of things to avoid often backfire, because the model still has to process the concepts. Keep exclusions short and structural: no camera shake, no text overlays, no morphing. If a shot keeps failing, fix the source image instead of stacking more negatives on top of the problem.
Match speed language to clip length
Words like slow, gentle, and gradual are not decoration. They materially change how much movement the model schedules per frame. For dialogue-adjacent shots, stay on the slow end. For action beats, you usually still want slower motion than you think, then speed it up in the edit where you control the curve.
A repeatable production workflow
Step 1: lock the shot design before generating
Storyboard the shot in stills first. Approve the composition, the lighting, and the background. Every hour spent fixing a frame in the still phase saves several hours of re-rolling generations later.
Step 2: generate short takes in batches
Work in two-to-four-second clips. Short takes are cheaper to produce, easier to review, and far more likely to stay coherent. Generate several variations per shot with small prompt differences, one with a dolly, one with a static camera, one with a slower head turn, then compare them side by side rather than trying to perfect a single output.
Step 3: keep the best frame, discard the rest
The most useful habit in this workflow is frame harvesting. If a take goes wrong halfway through, the first second may still be perfect. Export that frame, use it as the source image for the next generation, and continue from a state you actually like. This turns failures into material.
Step 4: extend, interpolate, and stabilize
Once you have good takes, extend them by chaining. Take the last frame of clip A, generate clip B from it with a continuing prompt, and repeat. Interpolate frame rate for slow motion, and apply light stabilization to handheld looks. Be conservative here, because heavy stabilization fights the motion you paid for and produces warping.
Step 5: upscale, grade, and finish
Generate at a workable resolution, then upscale for delivery. Grade all clips together so they share a single color identity, and add sound early. Ambient audio and a music bed hide small motion imperfections better than any filter, and they make an audience read the shot as intentional rather than experimental.
Keeping characters and style consistent across shots
Consistency is a sourcing problem more than a prompting problem. Start from the same character reference, keep the seed or reference image stable across shots when your tool allows it, and lock the prompt template so the wording for wardrobe, lighting, and lens stays identical. Change one variable at a time and log what you changed.
For recurring characters, build a small reference kit: a neutral front-facing portrait, a three-quarter profile, and a full-body frame, all lit the same way. Use the closest reference for each shot rather than forcing one image to cover every angle. Keep a style block, a short paragraph describing grain, contrast, color bias, and lens character, and paste it into every prompt so the whole sequence reads as one production.
Troubleshooting: common artifacts and how to fix them
Face warping: reduce motion magnitude, shorten the clip, and start from a sharper, higher-contrast source. If the face is small in the frame, crop the source tighter before generating.
Texture crawling: usually caused by fine repetitive detail such as fabric weave, foliage, or brick. A slight blur on the background plate, or a modest reduction in generation detail, generally settles it.
Object morphing: typically a depth misread. Add a matte, simplify the background, or generate the element separately and composite it back in.
Stuttery motion: check that frame rate matches your delivery, then interpolate. Also verify you are not asking for motion that is too fast for the clip length.
Color drift: lock exposure and white balance in the source image, avoid mixed color temperatures inside one frame, and grade after generation rather than trying to prompt your way to a consistent look.
Background sliding: the classic tell of a parallax misunderstanding. Composite in layers, or reframe the shot so the camera move is mostly rotational instead of lateral.
Choosing the right tool for the shot type
Different tools suit different jobs. Quick social clips favor fast, forgiving generators with generous aspect ratio options. Product and brand work favors tools whose image conditioning respects fine detail and that support layer-based compositing. Narrative work favors anything that lets you extend clips, control camera language, and hold character consistency across many shots.
Ask three questions before committing to a stack: does it accept my source image at the resolution I need, does it let me extend a clip from its last frame, and can I reproduce a result from the same inputs? Reproducibility is the quiet requirement that separates a toy from a pipeline. If you cannot get roughly the same output twice, you cannot build a schedule around it.
Where image-to-video earns its keep
E-commerce and product: turn catalog stills into short motion spots without a reshoot.
Real estate and interiors: animate architectural renders into walkthrough teasers.
Publishing and editorial: bring illustrations and archival photography to life for social cutdowns.
Music and performance: give album art, tour posters, and press photos motion that matches a track's mood.
Education and explainers: animate diagrams, cross-sections, and historical images so concepts move instead of sitting still.
Indie film and previsualization: test camera moves and pacing on a still before committing to a shoot day.
The common thread is that the still is already an asset you own, so the marginal cost of motion is small compared to shooting something new from scratch.
Frequently asked questions
How long should an image-to-video clip be? Two to four seconds for the initial generation, then extend by chaining if the shot needs length. Long single generations are where coherence breaks down fastest.
Do I need a powerful GPU? Not necessarily. Local generation offers more control and privacy; hosted tools trade that for convenience and speed. Many hybrid workflows prepare and retouch images locally, then generate remotely.
Can I animate a photo of a real person? Technically yes, but get written permission and be transparent about the manipulation. Synthetic media of identifiable people carries legal and ethical weight that no tool setting resolves.
Why does my result look like a sticker sliding across the frame? The model has no depth cues. Add foreground and background separation, a shadow, and a defined vanishing point, then reduce motion magnitude.
Should I generate at the final resolution? No. Generate at a resolution the model handles comfortably, then upscale. Pushing for maximum resolution in the generation step usually costs coherence.
How many takes should I generate per shot? Five to ten small variations beats one long attempt. Treat it like photography: shoot a roll, then pick the frame.
What is the fastest way to improve output quality? Better source images. Sharper, better lit, with clear depth. Prompting is the second-order variable.
Can I mix generated motion with real footage? Yes, and it is often the best approach. Use generated clips as inserts, transitions, or backgrounds, and keep live action for anything where performance or dialogue delivery matters.
