
Generative image and video tools have moved past the novelty stage. What used to be a demo you showed colleagues at lunch is now a production step in real campaigns, explainer videos, social cutdowns, and previsualization pipelines. The problem is no longer whether AI can make something striking. The problem is choosing among a crowded field of engines, each with its own strengths, quirks, limits, and prompt dialects — and then fitting them into a workflow that actually ships finished work.
This guide takes a different approach from a simple ranked list. Instead of declaring one winner, it explains how the major categories of tools differ, what each is genuinely good at, and how to sequence them into a repeatable production process. You will find decision criteria, prompt patterns, a comparison grid, common failure modes, and a practical first-week plan you can adapt to your own projects.
How Modern Image and Video Generation Actually Works
Before comparing tools, it helps to understand what you are actually comparing. Almost every system in this space is built on a variation of the same idea: a model learns the statistical structure of images or frames, then generates new content by starting from noise and progressively refining it toward something that matches your prompt.
The practical consequences of that architecture matter more than the theory.
Text-to-image models work in a compressed representation of an image rather than raw pixels. That is why they are fast, why they respond to style language, and why they sometimes produce artifacts in fine details like hands, small text, or complex backgrounds. Most image engines also support image-to-image, inpainting, and reference conditioning, which lets you steer an output instead of gambling on a fresh roll.
Video models add a temporal dimension. They must keep objects coherent across dozens or hundreds of frames, which is a much harder problem. Different tools solve it differently: some generate a short clip in one pass, others animate a still image, and others let you specify a first and last frame so the model fills the motion between them. The result is that video quality is not a single number. A tool can produce gorgeous frames and still fail at motion, or create smooth camera movement while drifting on character identity.
Hybrid pipelines are increasingly common. You generate a keyframe in an image model for maximum control, then animate it in a video model. You upscale, interpolate, and stabilize in post. Understanding this division of labor is the single biggest unlock for consistent results, because it lets you use each engine where it is strongest instead of asking one tool to do everything.
The Creative Landscape: Tool Categories, Not Just Brand Names
New models launch constantly, so memorizing rankings is a losing game. Learning the categories is more durable.
Cinematic-quality video engines
This group targets filmmakers, agencies, and anyone who needs shots that can sit in a finished edit. Strengths include realistic lighting, believable physics, expressive camera moves, and longer coherent clips. Typical limitations are higher cost per second of output, slower generation, and less tolerance for chaotic or abstract prompts. Runway, Kling, Luma's Ray family, and Google's Veo models all compete in this space, and each has a slightly different personality: some favor natural motion, others favor stylized art direction, others favor strict prompt adherence.
Fast social-first generators
These tools optimize for iteration speed and vertical formats. They are excellent for TikTok-style hooks, quick concept tests, and high-volume content calendars where you need twenty variations before lunch. You trade some fine control and realism for velocity. Pika and a range of mobile-first apps sit here, and many desktop suites now include a "fast" mode for drafting alongside a "quality" mode for final renders.
Open-weight and self-hosted options
If privacy, cost predictability, or deep customization matter, open models are compelling. You can run Stable Diffusion derivatives or open video models on your own hardware, fine-tune them on a branded dataset, and avoid per-generation fees entirely. The tradeoff is real: setup time, GPU requirements, maintenance, and a steeper learning curve. For teams producing thousands of assets a month, that math often works. For a solo creator making two videos a week, it rarely does.
Specialist image engines
Midjourney remains a benchmark for aesthetic quality out of the box. Flux models often lead in prompt adherence and text rendering. Stable Diffusion offers unmatched control through ControlNet-style conditioning, LoRA fine-tunes, and inpainting workflows. Adobe's Firefly integrates directly with editing tools and emphasizes commercially safer training data. Choosing here is less about "best" and more about which constraint you cannot compromise on: look, control, licensing, or integration.
Building a Repeatable Workflow From Idea to Finished Frame
The tools matter far less than the sequence. Here is a workflow that scales from a single social clip to a multi-shot brand film.
Step 1 — Define the deliverable and its constraints
Write down the aspect ratio, duration, resolution, platform, and deadline before you open any generator. A 9:16 clip for a feed is a different project from a 16:9 hero film. Decide early whether you need photoreal humans, stylized illustration, product accuracy, or abstract motion, because that single question eliminates half the tool options immediately.
Step 2 — Script and build a shot list
Treat it like traditional production. A 30-second video might be six shots of five seconds each. For each shot, note the subject, action, camera framing, lighting mood, and transition intent. This shot list becomes your generation checklist and prevents the classic spiral of generating attractive clips that do not cut together.
Step 3 — Lock your visual language
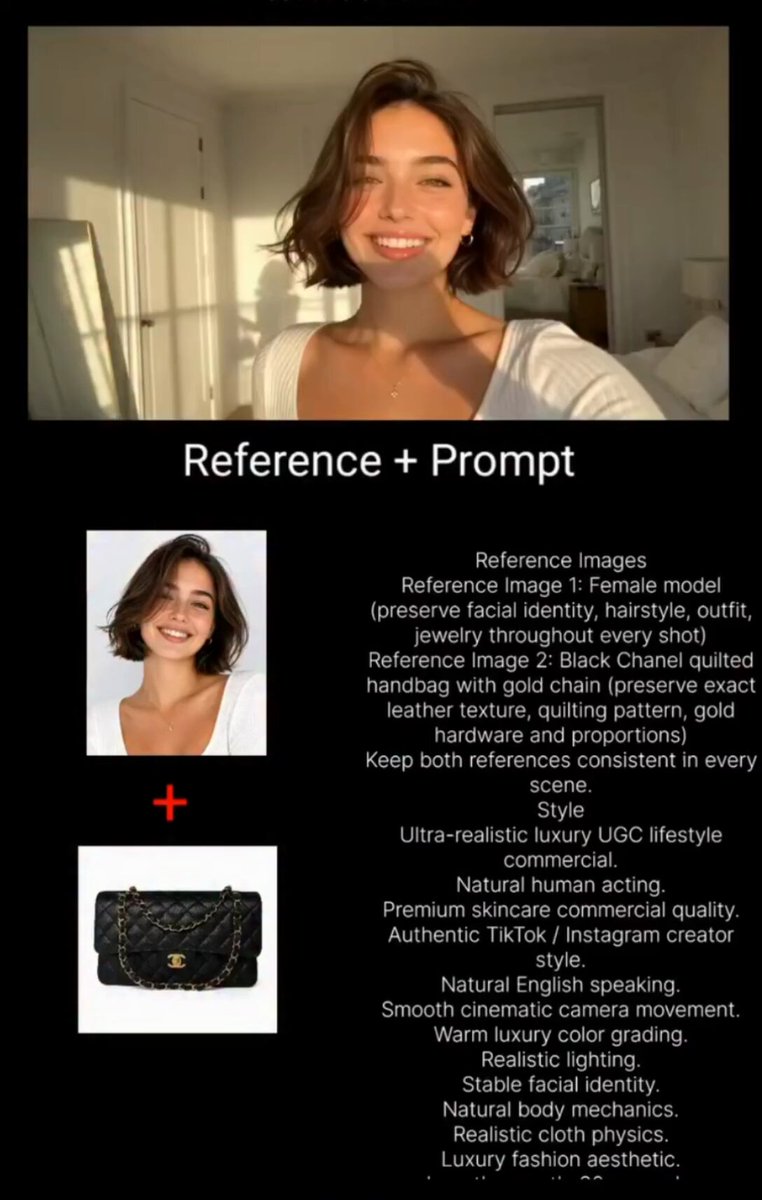
Generate three to five reference stills that define palette, lighting, lens character, and composition. Approve them before producing motion. If your project involves a recurring character, product, or location, this is the moment to establish a reference set you will reuse in every subsequent prompt. Consistency problems are almost always solved at the still-image stage, not in the video stage.
Step 4 — Generate keyframes, then animate
For any shot that matters, create the first frame as a high-quality still. Then use image-to-video to bring it to life, describing only the motion: "slow dolly in, hair lifting in breeze, subtle head turn toward camera." This approach gives you dramatically more control than describing an entire scene in text and hoping the model interprets it the way you imagined.
Step 5 — Assemble, sound-design, and polish
Cut the clips in your editor, add music and sound effects, correct color, and stabilize any shots with drift. Sound is not optional. A simple ambient layer plus one well-placed impact can make a mediocre clip feel intentional. Export, review on a phone screen, and only then publish.
Prompting for Images vs Video: What Actually Changes
Prompting is often taught as a magic formula. In practice it is closer to directing. The good news is that the underlying skills transfer between tools.
Prompts that survive motion
Text prompts that work beautifully for a still often fail as video instructions, because they describe a static tableau. For video, describe what changes over time. Verbs and adverbs do more work than adjectives: "steam rising," "fabric rippling," "crowd walking past the camera." If nothing in your prompt implies movement, the model may produce a near-still clip with unsettling micro-jitter.
Camera language is a control surface
Terms borrowed from filmmaking — dolly in, tracking shot, crane up, handheld, locked-off tripod — are usually respected by cinematic models. Overloading a prompt with three camera moves at once produces mush. Pick one primary move per shot, exactly as a director would.
Structural prompt patterns
A reliable structure for both images and video looks like this: subject and action, environment, lighting, lens and camera, style or film reference, and technical qualifiers. Keep it specific but not exhaustive. When results feel generic, the fix is usually to add a concrete detail rather than another adjective. "Weathered leather jacket with brass zipper" beats "highly detailed clothing."
Iterate one variable at a time
When a generation disappoints, change a single element and re-run. If you rewrite the entire prompt, you lose the ability to learn what caused the improvement. Keep a running notes file of prompt fragments that consistently work for your brand.
Comparing Tools Without Getting Lost: Decision Criteria
Rather than asking which tool is best, ask which tool is best for this shot, this deadline, and this licensing situation. Six criteria cover most decisions.
Output quality versus consistency
Quality is how good a single clip looks. Consistency is how reliably the tenth clip matches the first. For one-off social posts, quality wins. For series, brand films, or anything with a recurring character, consistency is worth far more, and you should prioritize tools with strong reference-image and character-conditioning support.
Speed and iteration cost
How long does a five-second clip take, and what does a failed attempt cost you? A model that produces excellent results on the third try can be cheaper in practice than a cheaper model that needs twelve attempts. Track your own hit rate rather than trusting benchmark tables, because hit rate depends heavily on your subject matter and prompting style.
Control features
Look for the controls that match your bottleneck: first and last frame specification, motion brushes or region-based motion, camera path controls, image references, style references, inpainting, and upscaling. A tool with fewer controls but excellent prompt adherence may beat a control-rich tool that ignores half your instructions.
Length and resolution limits
Most engines cap clips at a few seconds. Know the ceiling before you design a shot that requires eight continuous seconds of complex action. Where limits are tight, plan to stitch shorter clips at natural cut points, or use frame interpolation to extend motion smoothly.
Rights, licensing, and commercial use
The fine print matters enormously if you are producing for clients. Check whether outputs can be used commercially, whether you own or license the result, how the provider handles training data provenance, and whether your plan tier changes those terms. If your client requires indemnification or human-made-only assets, verify before you build a campaign around a tool.
Privacy and data handling
Uploading unreleased product photography or unreleased footage to a third-party service is a real risk. If confidentiality is a requirement, self-hosted open models or enterprise agreements with explicit data-retention terms are the safer route.
A Practical Comparison Grid by Use Case
The table below maps common needs to the type of tool that usually fits best. Specific products are listed as examples, not as an endorsement of a fixed ranking — the landscape shifts quickly.
| Use case | What matters most | Typical tool type | Example engines |
|---|---|---|---|
| Cinematic brand film | Realism, camera control, coherence | High-end video engine | Runway, Kling, Luma Ray, Veo |
| Fast social variations | Speed, vertical formats, volume | Social-first generator | Pika, mobile AI video apps |
| Character-driven series | Identity consistency across shots | Image reference + image-to-video chain | Flux with references, Midjourney, Stable Diffusion workflows |
| Stylized illustration or anime | Aesthetic control, style fidelity | Image model plus animation | Midjourney, Flux, anime-tuned checkpoints |
| Product visualization | Accuracy, text rendering, editability | Image model with inpainting | Flux, Firefly, Stable Diffusion |
| Confidential or high-volume work | Privacy, cost predictability, fine-tuning | Self-hosted open models | Stable Diffusion family, open video models |
| Previz for live action | Fast shot exploration, rough motion | Any fast video model | Fast modes across major suites |
A useful exercise is to run the same three-shot test through two or three candidate tools before committing. Score each on quality, consistency, speed, and how much post-processing you needed. Your personal scorecard will be more accurate than any published leaderboard.
Common Mistakes and How to Avoid Them
The same handful of errors accounts for most disappointing AI video projects.
Chasing tools instead of finishing work. Every new model release tempts you to restart. Set a rule: finish the current project with the tool you have, then evaluate new options at the next project boundary.
Writing a novel in the prompt. Long prompts dilute emphasis. Shorter, denser prompts with one clear subject and one clear action outperform sprawling descriptions.
Ignoring the first frame. A weak first frame guarantees a weak clip. Fix the still before spending time on motion.
Skipping the shot list. Without a plan, you accumulate disconnected footage and blame the tools for your edit not working.
Neglecting sound. Viewers forgive imperfect visuals far more readily than silence or mismatched audio.
Forgetting aspect ratio and safe areas. Generate in the target ratio, and keep important subject matter away from where platform UI will cover it.
Overlooking rights. Producing an entire campaign before checking licensing terms is an expensive lesson.
Expecting identical characters for free. Perfect consistency requires references, seeds, or fine-tuned models. Budget effort for it rather than hoping.
Managing Cost and Scale Sensibly
Generative production has two cost curves: the per-generation spend and your own time. Both are easy to underestimate.
Start by measuring your real hit rate. If one in five generations is usable, your effective cost per usable clip is five times the sticker price. Improving prompt craft, using keyframe-first workflows, and testing in lower quality before final renders can cut that ratio significantly.
Next, separate drafting from finishing. Draft on fast, inexpensive settings and only run final renders on approved shots. This one habit often reduces spend more than switching providers.
Finally, consider where a hybrid approach wins. Generating a still image and animating it is frequently cheaper and more controllable than generating video from text, because you can iterate on the free part of the pipeline and pay only once at the motion stage. For long-running series, a modest investment in a fine-tuned or self-hosted model can pay for itself if your volume is high enough.
A First-Week Plan You Can Actually Follow
If you are starting from zero, resist the urge to test ten tools at once. Instead:
- Pick one image model and one video model. Learn them properly for seven days.
- Reproduce three reference videos you admire as closely as you can. Copying teaches composition and motion better than open-ended experimentation.
- Build a personal prompt library organized by shot type: establishing shot, close-up, product hero, transition.
- Memorize one reliable shot formula — keyframe, then animate, then polish — and run it ten times.
- Publish something small. A fifteen-second clip that ships teaches more than a month of unfinished tests.
After that week, you will have firsthand data on your own bottlenecks, and evaluating new tools becomes a quick, confident decision rather than an overwhelming comparison exercise.
Frequently Asked Questions
Can AI video tools replace a traditional production crew?
For certain formats — social content, explainers, mood pieces, previz — they can replace or shrink a crew dramatically. For narrative work with precise performances, dialogue, and complex blocking, they are best treated as an additional production stage rather than a replacement.
How do I keep a character consistent across multiple shots?
Create a locked reference image, reuse it in every shot as an image prompt or character reference, keep the same seed where supported, and change only the action description. Avoid regenerating the character's face from scratch in each new prompt.
What clip length should I aim for?
Target three to five seconds per generated clip and cut between shots. Short clips are easier to control, cheaper to iterate on, and force better editorial rhythm.
Do I need a powerful computer?
If you use cloud tools, no. If you want to run open models locally for privacy or volume reasons, a modern GPU with adequate video memory is the baseline, plus patience for setup.
How do I handle text inside images?
Some image models render text far better than others. Generate the scene without lettering, then add typography in your design tool. It is faster and far more accurate.
What is the fastest way to improve output quality?
Improve the first frame. Better stills, better clips. This single change outperforms switching models in most cases.
Should I use one tool or several?
Most serious workflows use two or three: an image engine for keyframes, a video engine for motion, and a post tool for finishing. Specialization beats loyalty.
How do I evaluate a new model quickly?
Run the same three-prompt test you use for every model — one portrait, one action shot, one product or environment shot — and compare hit rate, consistency, and time to usable output. Keep the results in a file so you can compare across months.
Where to Go From Here
The generative media landscape will keep changing, and any tool you master today may be superseded next season. What carries over is the workflow: define the deliverable, plan the shots, lock the visual language, generate keyframes, animate deliberately, finish with sound and color, and review your own hit rate honestly.
Start with one image model and one video model. Build the smallest possible pipeline that produces a complete, publishable clip. Then improve one stage at a time — prompt craft, consistency, motion control, or post-production polish. Teams that treat these tools as a production discipline rather than a slot machine consistently get better results, spend less, and ship more. The tools are powerful; the process is what makes them useful.
