
Why Photo-to-Video Changed the Production Chain
Most AI video conversations still begin with a blank text prompt: describe a scene, wait, get something vaguely cinematic. Photo-to-video flips that order. You start with an image that already has the composition, lighting, wardrobe, product detail, and casting you want, and the model's only job is to add time. Motion, camera drift, a blink, a shifting shadow, a hand reaching for a cup.
That inversion matters because most production problems are not imagination problems. They are continuity problems. A brand shoot already produced the perfect hero frame. A real estate client already has a wide angle with the right dusk lighting. An actor's headshot already matches the character brief. Regenerating that from text means losing what was already approved, then trying to describe it back into existence.
Photo-to-video also shortens the feedback loop. Reviewers can approve a still in minutes, before any compute-heavy rendering happens. If the still is wrong, no amount of motion design will rescue the clip. Fixing the frame first is cheap. Fixing it after generation costs iterations, patience, and review cycles.
The practical result: teams now treat the still as the storyboard, the lighting reference, and the continuity anchor at the same time. The video model becomes an animator rather than a director of photography. That shift changes how you plan, how you review, and what skills matter on a small content team.
What Photorealistic Actually Means in AI Video
"Photorealistic" is not one property. It is a stack of properties that fail independently, and knowing which layer is breaking tells you exactly what to fix.
The four fidelity layers
Structural fidelity covers geometry and anatomy: perspective lines, straight edges, fingers, teeth, eyes, the joints of a chair. If structure drifts, viewers feel wrongness instantly even if they cannot name it.
Temporal fidelity covers stability across time: no warping between frames, no heavy "melting" of texture, no surface that keeps re-rendering itself. This is where most generated clips fail.
Material fidelity covers how surfaces respond to light: skin subsurface, fabric weave, brushed metal, glass refraction, wet pavement, condensation on a bottle.
Photographic fidelity covers the camera's fingerprints: motion blur, sensor noise, depth of field, highlight roll-off, subtle lens breathing. Ironically, the flaws of real cameras are what make a clip read as footage rather than rendering.
Where most clips fail
A single frame can look flawless and the clip still feels artificial. The usual culprits are texture crawl (fine detail like hair or foliage boiling frame to frame), identity drift (a face slowly becoming a different person), limb rubber (elbows and wrists bending in ways no skeleton allows), and background regeneration (a wall's texture rearranging itself because the model re-imagines it each frame).
One counterintuitive rule: judge clips at playback speed first. At 24 frames per second with motion blur, small errors vanish. Only after a clip passes the playback test should you step through frames to hunt for defects. Reviewing frame-by-frame from the start mostly produces false rejections and endless regeneration.
Decision Criteria: Choosing the Right Approach
The tool matters less than the method. Before opening any platform, decide which of these three approaches fits the job.
Single-image animation
One photo, one continuous shot, four to eight seconds. Best for social loops, product reveals, portraits that need a living quality, and establishing shots. It is the cheapest method in time and the most predictable.
Anchored multi-shot sequences
Several stills that share a character, wardrobe, and lighting, animated separately and cut together. This is how you build a 30-second narrative without a video model that can hold a scene for half a minute. Each shot is short, so each shot is controllable.
When text-to-video is genuinely better
If no approved still exists, if the scene needs complex physics (water, fire, crowds, vehicles in motion), or if you need a camera move that no photo can imply, generate from text. Then extract the best frame, approve it, and return to photo-to-video for the rest of the sequence. Hybrid pipelines beat purist ones.
Platform categories worth comparing: fast, lightweight generators for social loops; larger foundation models such as Runway, Kling, Sora, Luma, and Pika for harder motion and longer shots; open-weight models such as Wan when you need local control; and specialist tools for face animation and lip sync. Add an upscaler and an interpolation tool as separate steps. No single platform wins every category, and the best teams chain two or three.
Preparing Source Images: The Pre-Flight Checklist
Garbage in, wobble out. Image prep takes ten minutes and saves hours.
Resolution, aspect ratio, and cropping
Start at 1920 pixels on the short edge, ideally higher. Set the crop to your target ratio before generating: 16:9 for landscape delivery, 9:16 for vertical, 1:1 or 4:5 for feeds. Cropping after generation is a re-render, not an edit.
Lighting and depth separation
Clear lighting direction and visible separation between subject and background give the model depth cues to work with. Flat, front-lit images with no shadows produce flat, floaty motion.
What to remove before animating
Strip compression noise and oversharpening, which the model amplifies into crawl. Avoid or mask dense text, fine logos, mesh patterns, chain-link fences, and striped fabrics, all of which are warp magnets. Hands holding small objects, mirrored reflections, and crowds are high-risk regions.
Portraits and skin detail
Eyes should be sharp and correctly focused; a baked-in motion blur or focus miss will follow the clip. Keep skin texture natural rather than plastic-smooth, since some grain gives the model something to animate. Teeth are a known failure zone: slightly soften extreme sharpening there, and avoid open-mouth expressions that will later need lip sync.
Prompting Motion Without Breaking Realism
The five-part motion prompt
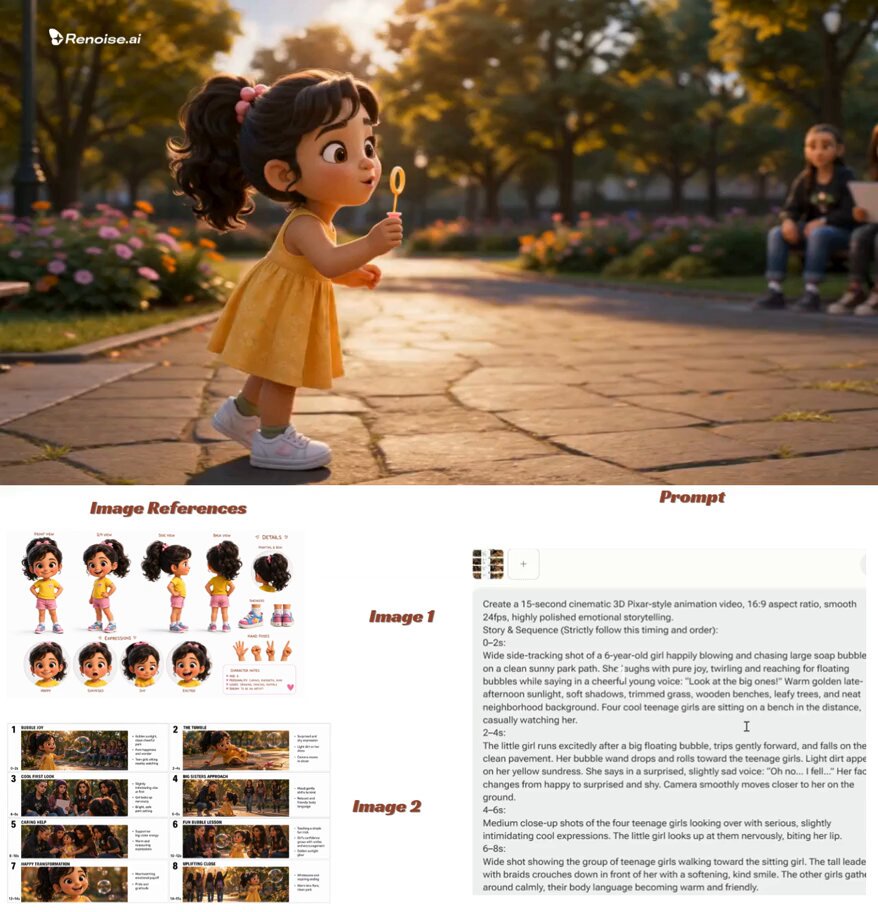
Write every motion prompt in five parts: subject action, camera behavior, environment and atmosphere, pace, and continuity constraints. For example: "A woman in a linen shirt slowly turns her head toward the window. The camera pushes in roughly ten centimeters. Dust motes drift in warm afternoon light, shallow depth of field. Pace is slow and calm. Keep the background furniture, wardrobe, and framing unchanged."
Camera language versus subject action
Pick one dominant move. A slow push, a gentle pan, or a subtle handheld drift, not all three. Slow motion reads as realistic; fast motion hides temporal errors less well than people assume and exposes them more.
Negative constraints
State what must not happen: no camera shake, no zoom, no face morphing, no hand warping, no text distortion, no lighting change. Negative constraints are especially effective for logos and product labels.
Motion strength, duration, and speed
Four to eight seconds per shot is the sweet spot. Beyond that, drift compounds. If you need a longer beat, generate two clips and join them, using the last frame of the first as the first frame of the second.
A Repeatable Step-by-Step Workflow
- Lock the deliverable: duration, aspect ratio, frame rate, platform, and whether vertical and horizontal versions are both required.
- Approve the still. Get sign-off on the frame before spending any generation time.
- Build a shot list from the stills, noting which frames share a character or location.
- Write motion prompts using the five-part frame.
- Generate three to four drafts at lower resolution or draft quality.
- Review at playback speed, then step through frames only on the finalists.
- Fix problems in place with masking, inpainting, or a fresh seed rather than rewriting the entire prompt.
- Extend or join shots by matching the final frame to the next clip's opening frame.
- Layer audio: voiceover, ambience, foley accents, music.
- Post-process: upscale, interpolate sparingly, add grain, color match, deliver.
Keep a naming convention as you go, for instance scene01_shot03_v4_ok.mp4. When a client asks for the version they liked three revisions ago, you will be grateful.
Keeping Identity Consistent Across Shots
Reference conditioning and character locks
Most modern models accept a reference image or character embedding. Feed the same reference for every shot with that character, and keep the reference image clean and well lit. Mixing references mid-sequence is the fastest way to produce siblings who are not related.
Wardrobe, lighting, and lens anchors
Consistency is not only faces. Note collar type, cuff style, hair parting, light direction, time of day, and the implied focal length. If shot one is a 50mm look with warm side light, shot two cannot be a 24mm wide with cool overhead light unless the story explains it.
Handling multiple characters
Two or more people in frame multiplies failure modes, especially hand contact and eye lines. Generate them in separate shots when possible, or keep their physical interaction minimal.
Continuity checks
After each shot, compare it side by side with the previous one at the same frame size. Check hair, collar, background objects, and any props. Small drift across five shots reads as an entirely different location.
Sound, Pacing, and Editability
Dialogue and lip sync
If a character speaks, plan for it before generation: front-facing framing, stable head position, mouth visible. Generate the visual first, then dub or drive lip sync from the audio, and keep lines short. Long monologues expose sync drift. For product and lifestyle work, narration over B-roll is almost always more reliable than on-camera speech.
Ambience and foley
Generated clips are silent, and silence reads as fake. Add a room tone, footsteps, cloth movement, a distant city hum. These layers do more for perceived realism than a fourth regeneration attempt.
Cutting to rhythm
Short generated shots are ideal for rhythmic editing. Keep two seconds of handles on each clip so cuts land on the beat, and alternate motion direction between consecutive shots so the sequence does not feel like one drifting camera.
Post-Production, Quality Control, and Common Mistakes
Upscaling and interpolation
Upscale after you lock the cut, not before. Aggressive frame interpolation to 60fps often creates soap-opera motion and warping around fast edges; use it only when the delivery requires it, and preview the result at full speed.
Grain, halation, and color match
Adding fine film grain, a touch of halation on highlights, and a consistent color grade unifies clips from different generations. Grade all shots together, not individually.
Quality control pass
Play the full sequence once without pausing. Note every moment your eye catches. Then fix only those moments. Chasing invisible defects at 400% zoom wastes the schedule you saved with photo-to-video.
Ten common mistakes
- Animating a low-resolution or heavily compressed JPEG.
- Overloading the prompt with three camera moves and four actions.
- Skipping still approval and discovering the problem after rendering.
- Ignoring aspect ratio until the final export.
- Reviewing frame-by-frame before watching at speed.
- Using every generated clip because it took effort to make.
- Leaving text and logos unmasked in high-motion areas.
- Forgetting an audio plan.
- Letting each shot have its own lighting mood.
- Removing all motion blur, which makes footage look synthetic.
FAQ and Final Checklist
How long should a photo-to-video clip be?
Four to eight seconds for a single generation. Build longer sequences by joining shots, not by pushing one generation past its stable range.
Why does my clip look melty or wobbly?
Usually fine detail in the source, motion that is too fast, or a high-motion area with text or pattern. Mask the problem region, slow the motion, and regenerate.
Can I animate a product photo with a label?
Yes, with care. Keep the label low in the frame or camera movement minimal, and add explicit negative constraints against text distortion. Straight-on shots hold typography far better than angled ones.
How do I stop faces from changing between shots?
Use one clean reference per character for every shot, keep lighting consistent, and avoid fast head turns that force the model to invent profile detail it does not have.
Do I need to be a prompt engineer?
No. You need a repeatable checklist. The five-part motion prompt and the still-approval step cover most of the value.
Should I always upscale and interpolate?
No. Upscale when the delivery format demands it, interpolate only when the platform or client requires a higher frame rate.
Final checklist before you publish
- Source still approved and archived at full resolution.
- Aspect ratios verified for every delivery channel.
- All shots watched end to end at normal speed.
- Character, wardrobe, and lighting consistent across the sequence.
- Audio bed present: voice, ambience, music, and level-matched.
- Grain and grade applied to the whole timeline, not per clip.
- File naming, versioning, and project files saved for future revisions.
Photo-to-video rewards preparation more than raw model choice. Approve the still, describe the motion in five parts, keep the shot short, and unify everything in post. Do that consistently and the output stops looking like a demo and starts looking like footage.
