
Why character consistency became the real bottleneck in AI video
A single generated clip can look astonishing. Skin, fabric, lens flare, the way light bends around a shoulder — modern video models handle all of it. The problem starts when you need a second shot of the same person. Suddenly the jaw is wider, the eyes sit slightly farther apart, the jacket has a different collar, and the hairline has migrated. Nothing looks broken in isolation, but played back to back the illusion collapses. The audience does not need to articulate what is wrong; they simply stop believing the character exists.
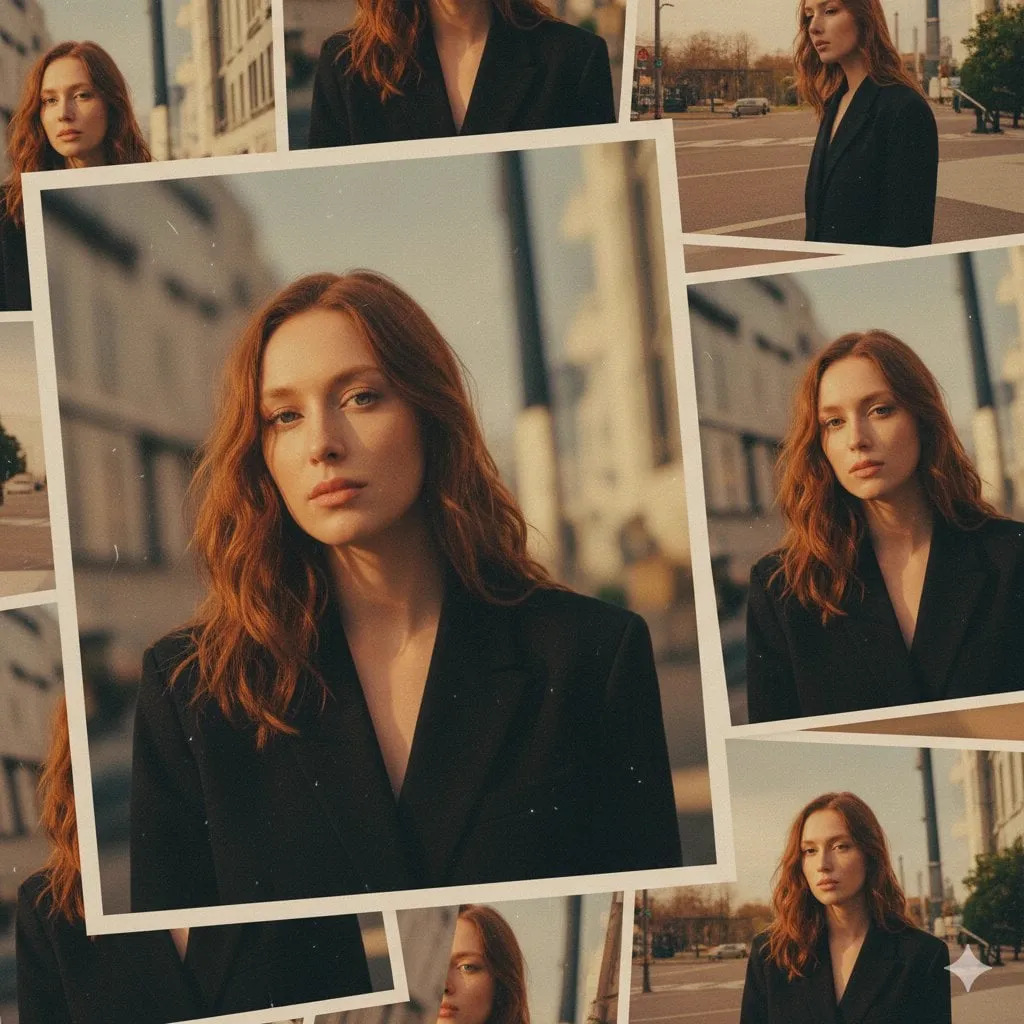
This is why multi-image fusion has moved from a niche trick to the standard way of producing narrative AI video. Instead of asking a model to invent a person from a sentence, you feed it several stills of an established face and body, then ask it to move that specific person through a new scene. The reference images carry identity. The prompt carries action, mood, and camera intention.
There are three kinds of drift you will fight repeatedly:
- Identity drift — facial geometry, age, skin tone, and hair shift between shots.
- Wardrobe and prop drift — the coat changes cut, a necklace disappears, a scar moves to the other cheek.
- Photographic drift — color temperature, contrast, grain, and lens character change so much that two shots look like they came from different productions.
A good workflow addresses all three separately. Most beginners try to fix everything inside the text prompt and wonder why the face keeps sliding. The prompt is the weakest tool for identity. Images are the strongest.
How multi-image referencing actually works under the hood
It helps to know what the model is doing with your stills, because that knowledge tells you which lever to pull when results disappoint.
Reference conditioning
Some video models accept one or more images alongside the text prompt. The image is encoded into features that guide the generation, similar to how a pose or depth map guides a diffusion pass. With a single reference you get a strong hint of identity; with several angles, the model can triangulate the face from multiple viewpoints, which sharply reduces the "almost right" problem.
Identity adapters and embeddings
Adapters and embeddings are lightweight identity representations trained from a small set of images. They are fast to apply and easy to reuse across many generations. Their weakness is fidelity: they capture a general likeness rather than an exact face. For stylized or animated characters this is often enough. For a realistic human appearing in close-up, an adapter alone will usually produce a cousin, not the person.
Full character fine-tuning
Training a dedicated model on 15 to 40 well-curated images of one character gives the highest identity fidelity. The trade-off is setup time and the need for careful image selection. Bad training data — inconsistent lighting, varied angles shot with different lenses, heavy filters — produces a model that is confidently wrong. Spend the extra hour curating images; it saves a hundred regenerations later.
Post-generation repair
Sometimes the cleanest solution is a repair pass. Generate the motion and composition you want, then apply a face restoration or identity transfer step to the frames. This is powerful when a shot is otherwise perfect. It is also risky: repair passes can flatten natural skin texture, fight against strong shadows, or produce a subtle "pasted on" look in profile shots. Use it surgically, not as a blanket fix.
In practice, most reliable pipelines combine two or three of these: a character model or adapter for baseline identity, multi-image references per shot for angle accuracy, and a light repair pass only where a frame fails quality control.
Build a reference kit the model can actually use
Your reference set is the single highest-leverage asset in the whole process. Treat it like a casting folder, not a camera roll.
The shot list
Aim for these nine to twelve images:
- Straight-on neutral face, relaxed expression, even light.
- Three-quarter left and three-quarter right.
- Full profile left and right.
- Close-up of the eyes and brow.
- Full body, neutral standing pose.
- Two expression extremes — a genuine smile and a tense or worried look.
- Two or three wardrobe variants, clearly labeled.
- Any signature props: glasses, earrings, a scar, a jacket.
- One or two images in different lighting temperatures, so the model learns identity is separable from color.
Rules that prevent wasted generations
- Keep the face unobstructed. Hair over the eyes or a hand on the chin ruins the geometry signal.
- Avoid dramatic shadows. Hard side light teaches the model that half the face is missing.
- Match lens feel. Mixing a wide-angle selfie with a telephoto portrait creates contradictory facial proportions and the model averages them into a stranger.
- Use plain backgrounds. Busy backgrounds leak into generated scenes.
- Keep resolution high but not enormous. Extremely compressed images lose micro-detail; absurdly large files slow the pipeline without improving identity.
- Crop consistently. The character should occupy a similar portion of the frame across the set.
If you are working with a person who has a distinctive feature — a crooked smile, thick eyebrows, a gap in the teeth — make sure at least three references show it clearly. Models love to normalize faces toward an average. Distinctive features are exactly what gets smoothed away.
Prompt patterns that survive multi-scene production
With references attached, your prompt should do less identity work and more directing. Over-describing the face actively harms results, because descriptive words compete with the reference signal.
A structure that works well across most generators:
Identity: [character name], consistent with reference images
Wardrobe: charcoal wool coat, cream turtleneck, no jewelry
Action: walking through a market, glancing left, one hand in pocket
Scene: narrow stone alley, wet pavement, early morning
Camera: medium shot, 50mm look, slow dolly right, eye-level
Light: cool overcast ambient with a warm practical from the left
Motion: subtle, natural, no exaggerated gestures
Exclude: text overlays, extra limbs, face distortion
Four habits separate clean outputs from messy ones:
- Name the character once. Repeating "the same woman with green eyes and a sharp chin" in every prompt invites the model to reinterpret her each time.
- Keep wardrobe language short and binary. "Charcoal wool coat" beats "a stylish dark coat, maybe with a scarf."
- Describe motion in verbs, not adjectives. "She turns, then stills" gives the model a timeline. "Dynamic and cinematic" gives it nothing.
- Limit each shot to one primary action. Two actions in a five-second clip produce mush in the middle.
Camera, lighting, and continuity discipline
Consistency is not only about the face. Two shots of the same person under wildly different photographic treatment still read as a discontinuity, especially in a cut.
Lock your lens language
Decide the visual grammar before generating anything: is this handheld documentary or locked-off cinematic? Pick two focal-length feels and stay inside them. Jumping between a wide 24mm look and a compressed 85mm look on the same character will subtly change the face shape in every shot, and no reference kit can fully compensate.
Carry color across scenes
Export a reference still from your best shot and use it as your grade target. When assembling, apply the same color transform to every clip and then adjust exposure per shot. Grading every clip from scratch is how a coherent sequence turns into a patchwork.
Respect the axis
If a character walks left to right in the establishing shot, keep them moving left to right until a deliberate reversal. AI generation makes this easy to violate because each clip is generated independently, with no awareness of the previous shot. Track directions in your notes.
Maintain a continuity sheet
A simple table beats memory. Columns: scene, wardrobe, hair state, injuries or dirt, props, time of day, light direction, lens. Fill it in before generating and check it after. In a ten-scene sequence, this is the difference between a professional result and an expensive accident.
A repeatable workflow, from beat sheet to final cut
Here is the sequence that consistently produces usable footage.
Step 1: Write the beat sheet, not the script
List what changes in each shot: location, action, emotional beat. Ten to fifteen beats is plenty for a two-minute piece. This tells you how many distinct set-ups you need and reveals continuity risks early.
Step 2: Generate a character sheet
Use a text-to-image model to create the character in a clean, neutral setting. Iterate until the face is genuinely right. Do not accept "close enough" here — this face is the source of truth for everything downstream.
Step 3: Expand to a reference kit
Generate or photograph the nine to twelve angles from your shot list. If you generated the character, use image-to-image variation to keep identity while changing angle. If you are working with a real person, shoot the set in one session with consistent lighting.
Step 4: Lock keyframes per scene
Generate a still for the opening frame of each shot. This is your composition anchor: framing, wardrobe, background, lighting. Approve all keyframes before touching video. Fixing a still takes seconds; fixing a five-second clip with the wrong wardrobe takes a full regeneration.
Step 5: Animate from the keyframe
Use image-to-video with the keyframe as the first frame and the character references attached as identity guidance. Keep motion descriptions modest. Short, contained movements hold identity far better than large ones.
Step 6: Inspect at 200 percent
Pause on the first frame, the middle frame, and the last frame of every clip. Zoom into the face. Check ear shape, eye spacing, teeth, hairline, and jaw. Check that the wardrobe reads identically to the previous shot. Reject early; a flawed clip that "almost works" costs you more in editing than a clean regeneration costs in time.
Step 7: Repair rather than restart when it is close
If a clip is 90 percent right but the face slips in the final second, try a targeted fix: regenerate only the tail, or apply a light identity pass to the offending frames. Reserve full restarts for genuine structural failures.
Step 8: Assemble and unify
Edit with deliberate cut points, then apply your shared grade. Add sound — footsteps, room tone, a music bed. Audio does more for perceived continuity than most people expect; a consistent ambience makes slightly imperfect visual matches read as intentional.
Choosing your stack without wasting weeks
Tool choice matters less than workflow discipline, but the wrong tool for your genre will cost you. Evaluate candidates against these criteria:
- Reference input count. Can it accept multiple images per generation, or only one? Multi-image support is the whole game for character work.
- Maximum coherent clip length. Longer single takes reduce the number of identity handoffs you have to manage.
- Control features. Keyframe start and end, camera motion controls, and inpainting dramatically reduce reshoots.
- Identity fidelity at close-up range. Test with a tight shot, not a wide. Wides hide everything.
- Style range. Some models excel at realism and struggle with stylized animation; others are the reverse.
- Repair and upscale paths. A model that plays well with external restoration and upscaling tools gives you a safety net.
- Export and integration. Frame rates, codecs, and alpha support matter if you are compositing.
Run a one-hour test before committing: same reference kit, same prompt, three scenes across two candidate tools. Judge on identity stability, not on which clip looks prettiest in isolation.
The mistakes that waste the most time
Over-prompting the face. The single most common error. If references are attached, stop describing cheekbones.
Mixing reference styles. Photos shot with different lenses and light produce an averaged, unfamiliar face.
Chasing motion instead of identity. Big, sweeping camera moves are impressive in a demo and disastrous for continuity. Earn stability first, then add movement.
Skipping the keyframe approval step. Reviewing stills is cheap; reviewing video is expensive.
Ignoring background continuity. The character is consistent but the alley changes from brick to stone between cuts. Audiences notice.
Regenerating everything. Learn which failures are patchable and which are structural.
No continuity sheet. Memory does not scale past three shots.
Neglecting audio. Silent cuts feel more disjointed than they are.
Turning consistency into a reusable system
Once a character works, treat it as an asset rather than a one-off. Build a folder with the reference kit, the approved keyframes, the winning prompt template, the grade reference still, and a versioned continuity sheet. Name versions so you can roll back: character-a_refkit_v3, scene-04_keyframe_v2.
For series work, keep a living character bible: physical description, wardrobe sets per season, speech patterns, and the exact prompt blocks that produced approved shots. When a new collaborator joins, the bible plus the reference kit lets them generate a consistent shot on day one instead of week three. Teams that skip this step end up with two or three variants of the same character, and no clean way to reconcile them.
FAQ
How many reference images do I actually need?
Five is a minimum for a simple stylized character; eight to twelve is the sweet spot for realistic humans. Beyond roughly twenty, returns flatten unless you are fine-tuning a dedicated model.
Can I keep a character consistent with text prompts alone?
Rarely for more than one shot. Text descriptions normalize toward an average face. References, adapters, or a trained model are what hold identity across scenes.
Why does my character change when the camera angle changes?
Because the model has never seen that side of the face. Add profile and three-quarter references. This is the most common cause of identity collapse and the easiest to fix.
Should I train a custom model or use an adapter?
If the character appears in close-ups across many scenes, train. If they appear in wides, in motion, or in a stylized style, an adapter plus strong references is usually sufficient and much faster.
How do I handle wardrobe changes without losing identity?
Keep the reference kit focused on the face and body, and control clothing purely through prompt text and keyframes. Mixing wardrobe variants into the identity references teaches the model that the coat is part of the person.
What clip length should I aim for?
Generate the shortest clip that covers the beat, typically three to five seconds. Short clips drift less and cut together better than long ones.
Do I need to color grade AI footage?
Yes, if you want it to look like a single production. Generate or choose one grade reference and apply it consistently, then adjust exposure per shot. Ungraded AI clips rarely match each other out of the box.
How do I know when a clip is good enough?
Watch it three ways: alone, at normal speed; paused at the first, middle, and last frame at high zoom; and in sequence with the shots before and after it. A clip that passes all three is done.
Where this is heading
Multi-image fusion is not a temporary workaround. It reflects a shift in how AI video is made: away from one-shot novelty and toward production systems with bibles, references, continuity tracking, and quality control. The teams producing the most convincing character-driven work are not using dramatically better tools — they are using ordinary tools with unusual discipline.
Start small. Pick one character, build a proper reference kit, generate five scenes, and track continuity in a spreadsheet. The first pass will be rough. The second will be noticeably better, and by the third you will have a reusable pipeline that turns an idea into a coherent sequence instead of a collection of beautiful, disconnected clips.
