
Character consistency is the quiet bottleneck of AI video. A model renders a flawless face in shot one, then hands you a distant cousin of that face in shot four. When the output is a one-off clip, that drift is annoying. When it is episode three of a series, a forty-second ad, or a course module with a recurring presenter, it breaks the illusion entirely.
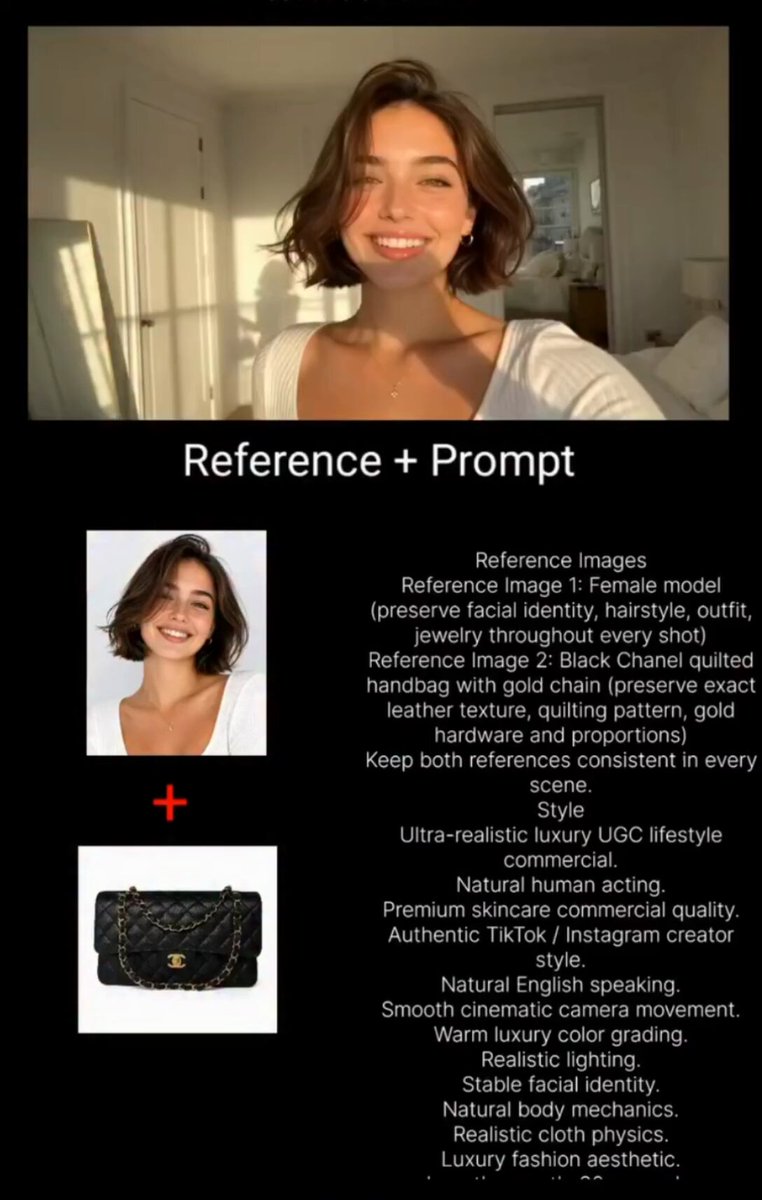
Multi-image fusion is the practical answer most teams land on. Instead of feeding the model a single portrait and hoping, you build a small reference set of the same identity — different angles, expressions, and lighting conditions — and let the model fuse them into a stable representation it can reapply shot after shot. This guide covers how that works in practice, how to prepare references, how to prompt around them, and how to audit the result without watching every frame.
What Multi-Image Fusion Changes About AI Video
Most early text-to-video and image-to-video pipelines treat the reference as a hint rather than a specification. One still image carries one angle, one lighting condition, one expression. The model has to guess what the character looks like from the side, how the face behaves mid-sentence, how the hair falls when the head turns. It guesses differently in every generation, and the seams show.
Multi-image fusion reverses that relationship. You supply a handful of images of the same character, and the conditioning stage extracts a shared identity representation instead of copying pixels from one frame. Downstream generation still creates new pixels, but it is anchored to a representation that survived multiple viewpoints.
What fusion genuinely improves
- Identity stability across cuts. The face survives a scene change, a wardrobe change, and a jump in focal length.
- Better off-axis results. Three-quarter and profile angles stop looking like a different actor.
- Expression flexibility. You can ask for a laugh, a scowl, or a whisper without the bone structure sliding around.
- Tolerance for camera motion. Dolly-ins and handheld moves degrade more gracefully when the anchor is strong.
What fusion does not fix
- Costume and prop continuity. That is a separate conditioning problem, usually solved with wardrobe references and tighter shot descriptions.
- Brand-exact logos and legible text. Treat these as post-production layers.
- Physics and hands. Fusion has nothing to say about finger count.
- Style drift between models. If you switch engines mid-project, expect to re-anchor.
The mental model that helps most: fusion makes the character recognizable, while prompting and editing make the sequence coherent. You still need both.
Why Characters Drift: The Root Causes
Before optimizing anything, it helps to know which failure you are actually looking at. Most drift traces back to one of six causes.
1. Thin reference signal. A single frontal portrait gives the model almost no information about jawline depth, ear shape, or hair volume. It fills the gap with averages pulled from its training data, and those averages shift between generations.
2. Contradictory references. Mix a soft-lit studio headshot with a harsh-flash candid and the fusion step averages incompatible shading. The face becomes slightly generic because the model is trying to satisfy both.
3. Prompt conflict. Describing the character in detail in every prompt — age, cheekbones, eye shape — creates competition between your words and your images. The model sometimes follows the text and quietly drops the anchor.
4. Long uninterrupted shots. A twelve-second continuous take gives latent drift time to accumulate. A character can change subtly from second two to second ten without any single frame looking wrong.
5. Camera motion and scale change. Wide shots give the identity representation very few pixels to work with. When you cut from a close-up to a wide and back, the model may rebuild the face at the wider scale rather than scaling down what it had.
6. Pipeline mixing. Model switching mid-scene, aggressive upscaling, face restoration passes, and heavy compression all alter the face after generation. Restoration tools in particular tend to "beautify" toward a generic ideal.
Knowing which cause you are facing determines the fix. Rebuilding the reference set will not help if the real problem is a face-restoration pass at the end of your chain.
Assembling a Reference Set That Survives Every Shot
The reference set is the single highest-leverage asset in the whole workflow. Treat it like a casting packet, not a photo dump.
How many images?
Three is the practical floor. Five to eight is the sweet spot for a recurring character. Beyond ten, returns flatten quickly and contradictory images become more likely to sneak in.
Angle coverage
Aim for a spread that answers the questions the model will face later:
- one clean frontal, eyes open, neutral expression
- one three-quarter left and one three-quarter right
- one near-profile
- one slight low angle (helps for heroic or upward-looking shots)
- one full-body or waist-up frame if the character moves through space
Lighting and color discipline
Keep the set within one lighting family. If your video is soft daylight, do not include a moody rim-lit portrait just because it looks good. Consistent white balance matters too — a warm image and a cool image of the same face produce a washed-out anchor.
Expression range
Two or three expressions are useful: neutral, a relaxed smile, and something more animated. Avoid extreme expressions in the reference set itself; a full shout or a dramatic squint distorts facial geometry and pulls the anchor with it.
What to exclude
- images where hair, hands, or accessories cover the face
- motion-blurred frames
- heavy filters, beauty smoothing, or stylized color grades
- different hairstyles or facial hair unless the story requires the variation
- anything generated with a different model that has a visibly different render style
Preprocessing checklist
Resize references to similar dimensions, crop to comparable framing, and check that no image is noticeably sharper or softer than the rest. Sharpness mismatch is a common and underrated source of anchor instability, because the model learns detail levels along with identity.
A Practical Multi-Image Fusion Workflow, Step by Step
Here is the sequence that holds up across ad work, explainer content, and episodic series.
Step 1 — Write the identity brief. One paragraph: age range, build, hair, wardrobe base, distinguishing features, and the emotional register the character should read as. This brief exists to stop you from re-describing the character in every prompt later.
Step 2 — Build and normalize the reference set. Follow the section above. Clean the set before you ever open a generator.
Step 3 — Create the fusion anchor. Load the references into your tool's character or reference feature and generate a single test image. Do not start with video. Confirm the anchor produces a face you would cast.
Step 4 — Calibrate with one controlled shot. Generate a short, simple clip: static or nearly static camera, neutral background, the character speaking or turning slightly. This is your baseline. Save the exact settings.
Running the calibration properly
Change one variable at a time. First vary the camera angle, then the lighting, then the motion. If the anchor breaks during calibration, it will break harder in a complex scene. Fixing it here costs minutes; fixing it after a full scene costs an afternoon.
Step 5 — Lock parameters. Record seed, reference set version, aspect ratio, motion strength, and any identity-weight settings. This is your reproducibility contract.
Step 6 — Generate in shot-sized chunks. Four to six seconds per generation is the reliable range for most current models. Longer chunks invite drift and force you to throw away more work when one frame misbehaves.
Step 7 — Review in batches. Pull contact sheets rather than scrubbing timelines. More on that below.
Step 8 — Version and archive. Name reference sets with dates and version numbers. When a campaign returns in six months, you want the exact set that worked, not a folder called refs_final_v2_new.
Prompting for Identity: Short Anchors Beat Long Descriptions
When a strong reference set is doing the work, your prompt should describe the scene, not the person.
The anchor phrase
Pick a short, stable descriptor — something like the woman from the reference or a character name — and reuse it verbatim in every prompt. Consistency in naming gives the model a consistent token to bind to.
Describe what changes
Instead of restating eye color, describe action, environment, lens, and light:
Character turns from the window, mid-sentence, soft window light from camera left, shallow depth of field, 50mm feel, slow push in
That prompt tells the model what is new. The reference tells it who is standing there.
Motion and camera language
Keep motion instructions modest during identity-critical shots. A slow push, a gentle pan, or a slight handheld float preserves the face. Rapid whip pans and fast dolly moves force the model to reconstruct identity repeatedly at different scales, which is exactly where drift lives.
Negative phrasing that helps
Useful avoidances include style words that pull toward generic renders — overly glossy skin, heavy HDR, extreme sharpening. If your tool supports negative prompts, list them once and keep them static across the project.
The over-prompting trap
Long character descriptions feel productive but usually hurt. Ten clauses about cheekbones and jaw structure compete with the image conditioning. If you must include detail, keep it to one distinguishing feature and let the references carry the rest.
How the Major Tools Handle Character References
Different engines expose the same idea through different interfaces, and knowing the shape of each helps you plan.
- Reference-image features. Several mainstream video models let you attach one or more reference images directly to a generation. These are the most straightforward path to fusion-style consistency and usually accept multiple images.
- Character-consistency flags in image generators. Image tools often include a character reference parameter that carries an identity from a source image into new compositions. Useful for building shot plates before animating them.
- Adapter-based pipelines. Node-based environments support identity adapters, pose guides, and structural controls that let you separate who the character is from what the body is doing. This is the most controllable route and the most technical.
- Fine-tuned identity models. Training a small identity model on twenty to forty images of one character yields the strongest long-term consistency, at the cost of setup time and compute. Worth it for a character appearing across dozens of shots.
- Restoration and upscaling passes. Treat these as identity-risky. Test them on a single clip before applying them to a whole sequence, and prefer passes that preserve facial detail over those that smooth it.
A pragmatic stack for many teams: generate plates in an image tool with a character reference, animate in a video model with reference images attached, and keep upscaling light.
Quality Control: Auditing Consistency Without Watching Every Frame
Watching every frame is impossible at scale. Sampling is not.
The contact sheet method
Extract one frame every twelve to twenty-four frames, tile them into a grid, and view the grid at a glance. Identity breaks jump out immediately in grid form because your eye compares faces side by side. This catches ninety percent of problems in a fraction of the time.
Pairs and triples
For identity-critical sequences, build a comparison sheet: reference image on the left, three sampled frames on the right. This is the fastest way to spot gradual drift, which is otherwise invisible when you watch a clip in real time.
Automated signals worth tracking
- Face embedding similarity. If your pipeline supports it, measure similarity between sampled frames and the reference set. A gradual downward slope across a scene is a drift alarm.
- Temporal flicker. Compare consecutive frames for sudden changes in facial geometry. Flicker usually precedes a visible identity break.
- Color and exposure histograms. Sudden shifts in skin tone often accompany identity changes, especially after a cut.
- Silhouette and proportion checks. Height-to-head ratio drift shows up in full-body shots before faces reveal problems.
A five-minute review checklist
- Does the first frame of every shot match the reference?
- Does the last frame of every shot match the first?
- Do faces hold through the widest shot in the scene?
- Did any post-processing pass alter skin texture or facial geometry?
- Do transitions between shots preserve hair length, eye color, and jawline?
If all five pass, the sequence is usually safe to assemble.
A Worked Example: One Character, Nine Shots
A sixty-second brand film with a single recurring presenter. The reference set: one frontal portrait, two three-quarter views, one near-profile, one waist-up frame in the target wardrobe. Five images total.
| Shot | Framing | Identity risk | Approach |
|---|---|---|---|
| 1 | Close-up, static | Low | Full reference set, calm prompt |
| 2 | Medium, slow push | Medium | Same seed, same anchor |
| 3 | Wide, walk-through | High | Shorter chunk, no fast motion |
| 4 | Over-shoulder | High | Reference plus angle-specific note |
| 5 | Close-up, cutaway | Low | Reuse shot 1 settings |
| 6 | Profile, window light | High | Profile reference highlighted |
| 7 | Two-shot with object | Medium | Keep face large in frame |
| 8 | Insert, hands only | None | No character conditioning needed |
| 9 | Closing close-up | Low | Match shot 1 exactly |
The high-risk shots are the same in every project: wide framings, profile angles, and anything with fast motion. Front-load your best references there and keep those shots short.
Common Mistakes, Fixes, and Choosing the Right Approach
| Mistake | Symptom | Fix |
|---|---|---|
| Reusing one reference everywhere | Face drifts on turns | Expand to a five-image set |
| Mixing lighting in references | Slightly generic face | Rebuild set in one lighting family |
| Over-describing the character | Identity weakens over time | Cut character description from prompts |
| Twelve-second generations | Late-scene drift | Split into four-to-six-second chunks |
| Heavy face restoration | Plastic, smoothed identity | Reduce or remove the pass |
| Switching models mid-scene | Visible style jump | Re-anchor, or finish the scene in one tool |
| No version control on references | Cannot reproduce a good result | Version and date every reference set |
Choosing the right level of effort
- One-off clip, character seen once: a single good reference is enough.
- Recurring character in one video: multi-image fusion with five to eight references.
- Character across a series or campaign: fusion plus a small fine-tuned identity model.
- Legal or brand-critical likeness: plan for a real performer, licensed material, and a consistent post pipeline rather than relying on generation alone.
Cost, timeline, and how many times the character appears should drive the decision. Fusion is cheap insurance; fine-tuning is expensive certainty.
FAQ
How many reference images do I actually need?
Three to five covers most projects. Go to eight when the character appears in wide shots or needs a wide emotional range. Beyond ten, contradictions in the set start to outweigh the extra information.
Can I mix images from different sources?
You can, but you should not mix render styles or lighting families. A photograph and a heavily stylized illustration of the same person will pull the anchor in two directions.
Why does consistency break only in wide shots?
Wide framings give the model very few pixels for the face. Keep wide shots short, avoid fast motion in them, and consider generating a medium framing and widening in edit instead.
Does a fixed seed guarantee consistency?
No. A seed supports reproducibility of a given configuration, but identity comes primarily from the reference set and conditioning. Change the prompt substantially and the result will shift even with the same seed.
Should I describe the character in the prompt as well?
Briefly, if at all. One distinguishing token is fine. Long descriptions compete with the reference images and tend to flatten the identity.
How do I handle a character who changes costume mid-story?
Keep the face references identical and add wardrobe references separately. Changing the reference set to match the costume usually costs you the face.
What about consistency between the thumbnail and the video?
Generate the thumbnail from the same anchor and the same reference set, then compare them side by side at small size. Small-size comparison is the fastest way to spot a mismatch that viewers will notice in a feed.
Is fusion enough for a full series?
For a handful of episodes, yes, if you version references carefully. For a long-running series, plan on a fine-tuned identity model plus a documented identity bible so any editor can reproduce the look.
Character consistency is not a single feature you switch on. It is a workflow: a disciplined reference set, a calibrated anchor, prompts that stay out of the way, short generations, and a review process that catches drift before it reaches the timeline. Multi-image fusion gives you the strongest anchor available without training a model from scratch — and the teams that treat reference preparation as real production work are the ones whose characters look the same in shot nine as they did in shot one.
