
Why AI video editing is now a production system, not a gimmick
For most of the last decade, "editing" meant one thing: working with footage that already existed. You shot, you imported, you trimmed, you graded, and you exported. Generative video changed the first half of that sentence. Today a creator can open a browser tab, describe a scene, and get usable motion footage in minutes. That shift moves the creative bottleneck from capture to decision-making — and decision-making is where most creators still lose time.
The real change is not that models can produce a clip. It is that a single creator can now run a pipeline that used to require a small crew. A talking-head segment, an establishing shot of a fictional city, a stylized product rotation, an animated diagram, and a b-roll montage can all come out of the same afternoon — provided you have a system. Without a system, you get a folder of disconnected clips, inconsistent characters, mismatched color, and an edit that feels like a demo reel instead of a story.
This guide is written for that middle ground: creators who already know how to cut a timeline but want a repeatable, professional way to fold generative tools into their workflow. It covers how to think about the layers of an AI stack, how to pick the right model for a specific shot rather than the most hyped one, how to protect consistency across shots, how to handle sound and captions, and how to run quality control before anything goes live.
The three layers of an AI video stack
Most creators treat AI video as a single tool. In practice, it is three distinct layers doing different jobs, and confusing them is the fastest way to waste an evening. Map your work to the layers and you will immediately see where automation helps and where human judgment is still doing the heavy lifting.
Generation layer: creating footage that did not exist
This layer covers text-to-video, image-to-video, and video-to-video. It is where you produce base motion: a character walking through rain, a drone push over a coastline, an abstract transition, a character delivering a line with lip sync. The inputs you can control vary enormously — some models accept only a text prompt, while others accept a reference image, a depth map, a pose skeleton, or an explicit camera path.
Assembly layer: turning clips into a sequence
Assembly is where generative output meets traditional editing logic. Tools in this layer handle automatic silence removal, scene detection, rough-cut generation from a transcript, multi-cam syncing, and beat-matched cutting. This is also where timeline editors that accept AI-generated assets sit. The assembly layer decides rhythm. A mediocre clip placed with perfect timing often beats a beautiful clip placed badly.
Enhancement layer: repair, upscale, and polish
Enhancement takes what generation produced and makes it broadcast-tolerable: upscaling to a delivery resolution, denoising the shimmer that low-step generation leaves behind, stabilizing imperfect motion, relighting a scene, repairing or isolating dialogue, generating room tone, and matching color across shots. Skipping this layer is the single most common reason AI-heavy edits look amateur.
How to choose the right model for each shot
Model choice should follow the shot, not the other way around. Before you open anything, write down four properties of the shot you need: how long it must be, how much motion it contains, whether realism or stylization matters more, and which control signal you can realistically provide.
Those four answers narrow the field quickly. A two-second abstract transition needs speed and iteration, not photorealism. A ten-second continuous camera move needs a model that holds temporal coherence. A character close-up that speaks needs lip sync and facial stability. A product shot needs clean edges, readable branding, and consistent lighting.
| Shot type | Priority | What to look for |
|---|---|---|
| Establishing / landscape | Stability over detail | Long-duration support, slow camera control, consistent horizon |
| Character dialogue | Face and lip fidelity | Image reference input, identity preservation, audio-driven sync |
| Action and movement | Temporal coherence | Motion handling, fewer warping artifacts, higher frame consistency |
| Product and packshot | Edge accuracy and text | High resolution, controllable background, minimal texture drift |
| Abstract transitions | Speed and style | Fast iteration, stylization presets, short clip lengths |
| Animation and illustration | Style adherence | Style reference, line consistency, 2D-friendly output |
Three practical criteria matter more than benchmark charts. First, iteration cost in time: how quickly can you generate, look, and adjust? A slightly weaker model that answers in seconds will beat a stronger one that makes you wait, because you will actually refine your prompt. Second, control fidelity: does the model respect the reference image, mask, or camera path you give it, or does it drift? Third, licensing terms for commercial use — check them once, write them down, and stop re-litigating the question on every project.
A repeatable seven-step workflow
A workflow only counts if you can run it on a Tuesday when you are tired. Here is one that scales from a thirty-second short to a five-minute explainer.
Step 1: Write the brief as a shot list, not a script
Scripts describe dialogue. Shot lists describe images. Convert your idea into a table with columns for shot number, duration, subject, action, camera, and mood. This takes twenty minutes and saves hours, because every generation prompt can now be derived mechanically from a row instead of invented from scratch.
Step 2: Lock the visual rules
Decide the things that must stay constant: aspect ratio, frame rate, color treatment, lens feel, and the character or product appearance. Write them as a short style block of text you will paste into every prompt. Consistency is a documentation problem before it is a model problem.
Step 3: Generate in ascending order of risk
Do not start with the hardest shot. Generate the simple, safe shots first — establishing frames, texture inserts, transitions. They build momentum and confirm your style block works. Then move to the difficult shots: dialogue, complex motion, hands, animals, text on screen. By the time you reach them, your prompt vocabulary is already tuned.
Step 4: Generate more takes than you need
Professionals generate three to five variations per shot and select ruthlessly. The instinct to accept the first decent output is the main reason AI edits feel flat. Keep a subfolder for near-misses; they often become cutaways later.
Step 5: Assemble on a real timeline
Bring selects into a normal editing timeline. Cut to a scratch music bed or a reference track. Place your strongest shot at the opening and the second strongest at the end — that is the structure viewers remember. Delete anything that only exists because it was hard to generate.
Step 6: Enhance after the picture lock
Once the cut stops changing, run enhancement passes: upscale, denoise, stabilize, and color match. Doing this before picture lock wastes processing time on shots you will delete.
Step 7: Deliver in the shapes the platforms want
Export a master, then derive vertical, square, and horizontal versions from the same timeline. Keep the captions editable as a separate file so you can restyle them without re-rendering everything.
Prompting for shots that survive generation
Prompts written like poetry produce unpredictable results. Prompts written like a camera report produce repeatable ones. A useful structure is: subject and wardrobe, action in present tense, environment, lighting direction, lens and framing, camera movement, and style reference.
Consider the difference. "A lonely warrior in a ruined city, cinematic" gives a model almost nothing to anchor to. "Medium shot, woman in worn leather jacket walking left to right through a rain-soaked alley, neon signs overhead, wet asphalt reflections, handheld camera drifting with her, shallow depth of field, cool blue key light with warm sign accents" gives it a subject, a direction, a lens, a movement, and a palette. The second prompt is not longer for the sake of length; every phrase removes a decision the model would otherwise make randomly.
Three habits improve output quality more than any parameter tweak. First, describe one action per shot — models handle a single continuous motion far better than a sequence of events. Second, state what should not move as often as what should; stability language reduces warping. Third, keep a personal prompt library organized by shot type so you never rebuild a working prompt from memory.
Negative phrasing and what it actually does
Negative prompts are not magic, but they are useful for recurring artifacts: extra fingers, floating limbs, morphing faces, text that turns into gibberish, and unwanted lens flares. Keep a short, stable list of negatives that you append to everything rather than a long one you edit every time.
Reference images beat adjectives
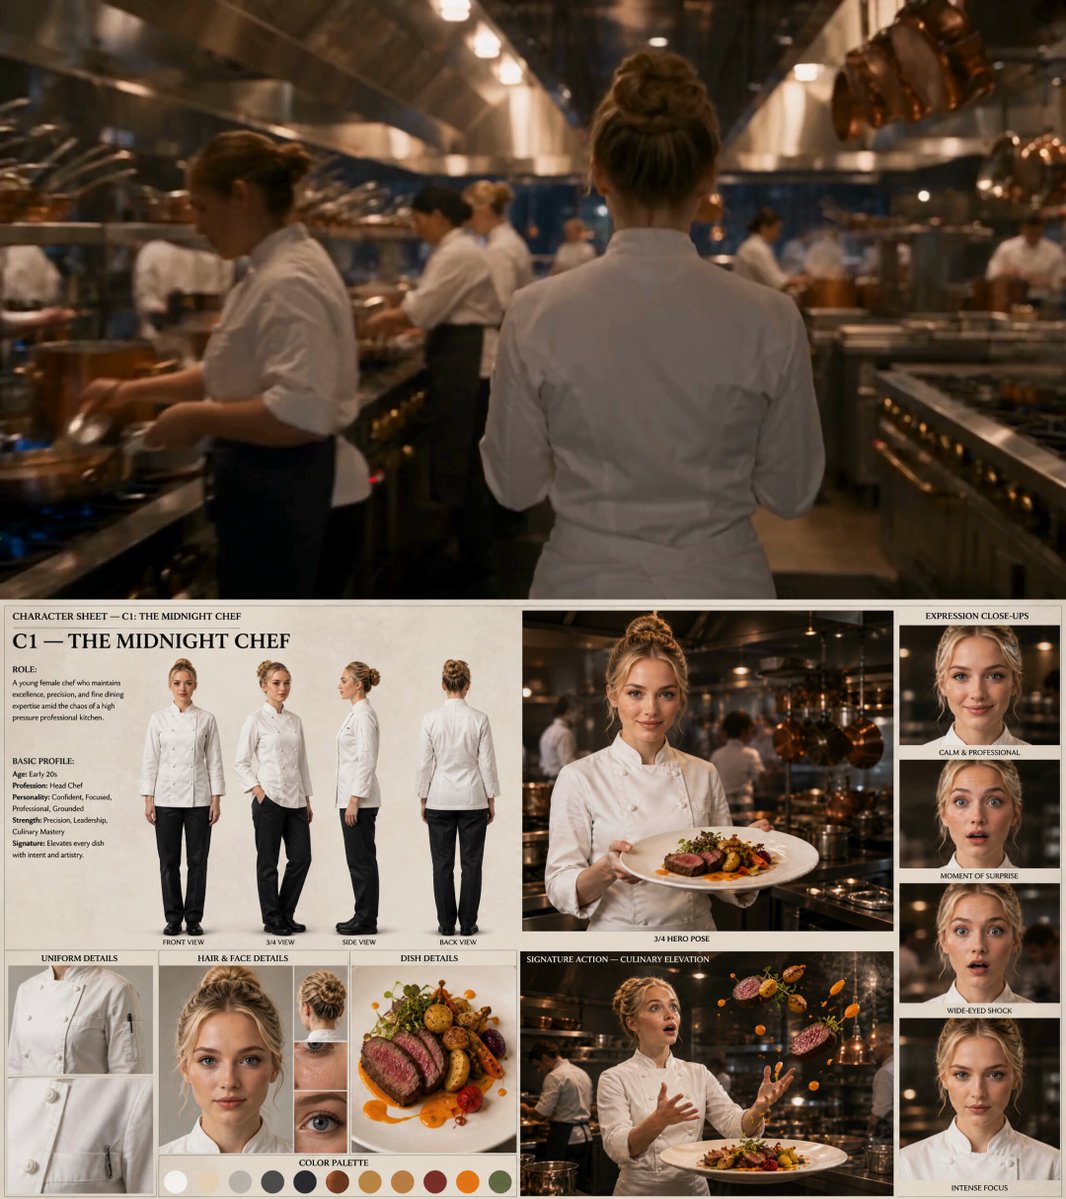
If a model accepts an image reference, use it. A single reference frame communicates wardrobe, palette, framing, and lighting more precisely than three sentences of description. Build a small reference board per project: one character sheet, one location plate, one lighting reference, one color palette.
Keeping characters and styles consistent across shots
Consistency is the hardest part of AI video work and the part viewers notice immediately. A character whose jacket changes color between shots breaks the illusion faster than any rendering artifact.
Treat consistency as a constraint system. Lock these variables and change only one at a time while testing: character identity, wardrobe, hair, environment, time of day, color grade, and camera language. When a shot drifts, you can now identify which variable caused it instead of regenerating everything.
Practical techniques that reliably help:
- Build a character reference frame and use it as image input for every shot that character appears in.
- Reuse the same seed or identity setting where the model supports it.
- Describe wardrobe identically, word for word, in every prompt. Do not paraphrase.
- Generate all shots of a location in one session so lighting matches.
- Apply a single color grade across the final timeline; a unified grade hides small inconsistencies in generation.
- Keep a continuity sheet with columns for character, wardrobe, location, and time of day, and check it before each generation batch.
Sound, captions, and localization
Audiences forgive imperfect visuals far more readily than bad audio. Treat sound as a first-class layer, not an afterthought.
Start with dialogue. If a shot needs a spoken line, generate or record clean speech first and drive the visual from it where the model supports audio-driven animation; this is far more reliable than generating video and trying to match a performance afterward. Next, build the sound bed: room tone, ambience, and a light foley pass. Room tone is the invisible glue that makes cuts feel intentional. Finally, add music and duck it under dialogue rather than mixing by ear on laptop speakers.
Captions should be generated from a transcript, edited by a human, then styled. Automatic captions are a starting point, not a deliverable — names, technical terms, and numbers are exactly where they fail. Keep captions in a separate file so you can translate and restyle them without touching the master export.
If you localize, dub before you burn in subtitles. Subtitle timing shifts when a dub changes line length, and rebuilding burned-in captions means a full re-render. Exported caption files keep that door open.
Common mistakes and how to avoid them
Most failed AI-assisted edits share the same handful of causes.
- Chasing novelty over story. A visually spectacular shot that does not advance the idea is dead weight. Cut it.
- Mixing models randomly. Every model has a signature look. Use one primary model for the bulk of a project and reserve others for specific shot types.
- Skipping the enhancement pass. Raw generation has artifacts that read as amateur on a large screen.
- Over-long clips. Generative models drift the longer they run. Generate short and cut precisely instead of asking for a twenty-second continuous take.
- Ignoring pacing. AI footage tends to be smooth and slow. Cut on action and use shorter shots to create energy.
- Forgetting aspect ratio early. Compose and generate with the final frame in mind; cropping a wide shot to vertical destroys composition.
- No naming convention. File chaos costs more time than rendering. Use project, scene, and take numbers from day one.
- Publishing without a sound check. Watch the export once on phone speakers and once on headphones before uploading.
A quality control checklist before you publish
Run the same checklist every time. It takes six minutes and prevents most re-uploads.
- Watch the full export at normal speed without stopping. Note anything that pulls your eye.
- Check the first three seconds — is there a reason to keep watching?
- Confirm no text, signage, or logo has turned into nonsense characters during generation.
- Verify faces and hands in every shot; look specifically for morphing during movement.
- Listen at low volume for audio dropouts, clipped peaks, and abrupt music edits.
- Confirm captions are accurate, timed, and inside safe margins for the target platform.
- Check color and brightness on a second screen if available.
- Make sure the export resolution, frame rate, and codec match the destination.
FAQ
Do I need a powerful computer to work this way?
Not necessarily. Much of the heavy generation and enhancement work happens remotely, so a modest laptop plus a stable connection can carry a full pipeline. Local hardware matters most for timeline editing at high resolutions and for long encoding jobs.
How many models do I actually need?
Fewer than you think. Most creators get better results with three or four tools they understand deeply than with a dozen they use occasionally: one primary generator, one backup for a specific weakness, one editor, and one enhancement or upscaling tool.
How do I stop my output from looking like everyone else's?
Style comes from constraints, not from prompts. Pick an unusual palette, a consistent lens choice, a recurring framing device, and a strong sound identity. Models converge on the average; your rules are what pull the work away from it.
Is it worth generating b-roll instead of filming it?
For anything hard to film — distant locations, historical settings, fantasy elements, dangerous stunts — yes. For simple shots you can capture in ten minutes at home, filming is usually faster and more controllable.
How long should a generated clip be?
Short. Two to six seconds is the sweet spot for most tools, because coherence degrades with length. Build longer sequences by cutting multiple short clips together.
What is the most common reason an AI edit gets rejected?
Audio and pacing, not visuals. Viewers abandon smooth, slow, quiet videos quickly regardless of how good the images look.
Building a system you can run again next week
The difference between a one-off experiment and a working practice is documentation. After every project, spend ten minutes writing down what your style block was, which shots your primary model handled well, which ones needed a fallback, and where you lost the most time. Within three projects you will have a personal playbook that is more valuable than any list of tools.
Keep the pipeline boring and the ideas ambitious. Choose models by shot type, generate more takes than you need, assemble on a real timeline, enhance only after picture lock, and treat sound with the same seriousness as image. Do that consistently and AI video editing stops being a novelty in your workflow and becomes the reason you can ship more work, at a higher standard, without a crew.
