
Why AI video editing changes the production pipeline
For decades, editing meant shaping footage that already existed. You shot more than you needed, then found a story in the timeline. AI video editing inverts that order. The story comes first, the footage is generated to fit the cut, and the timeline becomes a place where you assemble intent rather than trim leftovers.
That shift has practical consequences. A small team can now produce a polished 60-second spot without a camera, a location, or a cast. It also creates new failure modes: shots that look plausible on their own but incoherent next to each other, motion that drifts mid-clip, faces that change between cuts, and audio that fights the picture.
The productive way to think about AI video editing is as a pipeline with two halves. The first half is generation: turning a written or visual idea into raw clips. The second half is classical post-production: selection, assembly, repair, sound, grade, delivery. Teams that treat both halves with equal seriousness get the best results. Teams that struggle usually skip the second half and hope the model did the editing for them.
Another key difference is iteration cost. Reshooting a scene traditionally means schedules, permits, and travel. Regenerating a shot takes minutes. That changes creative risk: you can test three endings, four lighting moods, or two casting directions before committing. The craft moves from getting the perfect take on set to building a system that reliably produces usable takes.
Mapping the workflow: seven stages from idea to export
A repeatable structure beats inspiration. The following seven-stage pipeline works for anything from a 15-second social cut to a five-minute brand film.
Stage 1 — Brief and beat sheet
Write the story in beats before you write prompts. A beat sheet lists what changes from moment to moment: the problem, the turn, the proof, the payoff. Keep it to six to ten beats for short-form work. Every beat should be describable in one sentence, and each sentence should translate into one or two shots.
Stage 2 — Look development and style frames
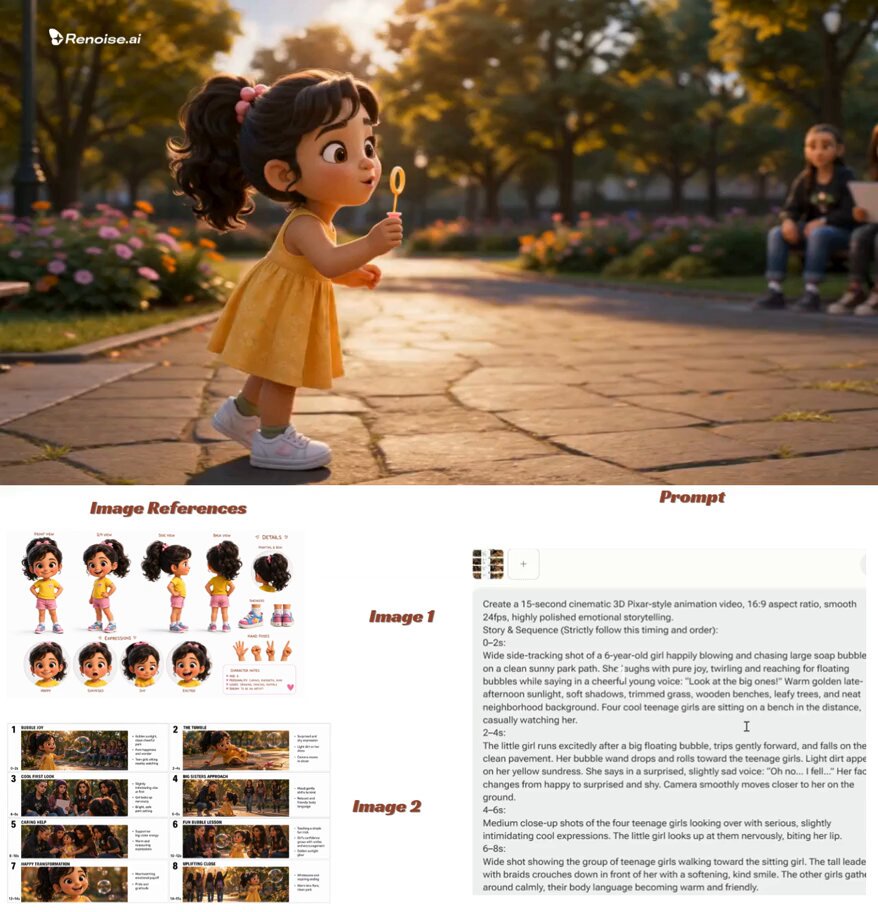
Before generating motion, generate stills. Static images are fast, cheap to iterate, and reveal composition problems immediately. Produce five to eight style frames that establish palette, lens character, lighting direction, and texture. These frames become references for every later shot, and they double as approval artifacts for clients.
Stage 3 — Shot list and generation plan
Convert beats into a shot list with columns for shot number, duration, framing, subject action, camera movement, and the specific tool you intend to use. Naming the tool in advance prevents the common trap of trying every model on every shot.
Stage 4 — Generate and tag
Generate in batches per shot, not per project. Produce four to eight variations, then name files with a strict convention such as s03_take04_panleft. Tagging is not bureaucracy; it is what lets you find the one usable take out of forty when you are assembling at speed.
Stage 5 — Assembly and rhythm
Cut with placeholders first. Use style frames as stills on the timeline, set the music, and establish timing. Only then replace placeholders with generated clips. Editing to a locked rhythm makes mismatched motion obvious and forces you to regenerate the shots that actually matter.
Stage 6 — Repair passes
This is where AI earns its keep in post. Typical repairs include upscaling, frame interpolation for slow motion, object or logo removal, background replacement, relighting, and extending a shot that ends two seconds too early. Do repairs shot by shot, then re-review the whole sequence, because a repair can change color and grain in ways that break continuity.
Stage 7 — Sound, grade, and delivery
Sound design glues generated footage together more effectively than any visual trick. Lock dialogue or voiceover, add ambience and foley, place music, then do a final color pass that unifies exposure and saturation across all shots. Export masters in the required aspect ratios rather than cropping after the fact.
Choosing the right generation model for each shot
Model choice is a decision problem, not a loyalty test. Different shot types reward different capabilities, and the best workflow uses two or three tools rather than one.
Decision criteria that matter
- Shot type. Talking heads, product macros, landscapes, and stylized animation require different strengths. A model excellent at cinematic landscapes may produce weak lip sync.
- Motion complexity. Simple camera pushes and slow reveals are forgiving. Running figures, crowded scenes, and hand interactions are where artifacts appear.
- Duration. Many models produce short clips natively. Long continuous action usually means generating overlapping segments and stitching them.
- Realism versus stylization. Photoreal work demands accurate skin, hair, and reflections. Stylized work tolerates abstraction and often looks better with lighter models.
- Reference fidelity. If a shot must match an approved frame or a specific person, image-to-video with strong reference adherence beats text-only generation.
- Iteration speed. A model that returns results in thirty seconds changes how boldly you experiment. Slower models are better reserved for hero shots.
A practical model map
| Shot need | Best-fit capability |
|---|---|
| Establishing landscape | Text-to-video with camera-motion controls |
| Character close-up | Image-to-video with identity reference |
| Dialogue delivery | Talking-head and lip-sync tooling |
| Product detail | Image-to-video with macro prompt and high-resolution export |
| Transition or abstract bed | Short text-to-video clips with heavy grading |
| Repair work | Upscaling, inpainting, and frame interpolation tools |
The safest approach is to keep a small, tested set. Two reliable generalists plus one specialist for faces plus one repair tool covers most production needs.
Prompting and shot design that survives the edit
Prompts written for stills rarely work for motion. Video prompts need a different grammar because the model must decide how things change over time.
A prompt skeleton that holds up
Structure prompts in this order: subject, action, camera, lens, lighting, palette, texture, motion quality, and avoid-list. For example: a ceramics artist shaping a bowl, hands turning slowly, medium close-up, 50mm lens, soft window light from the left, warm terracotta palette, matte texture, steady handheld micro-movement, no text, no extra fingers.
The avoid-list matters more than beginners expect. Most visible failures — warped hands, floating objects, text artifacts, crowd melt — are reduced by naming them explicitly.
Keep generated shots short
Three to five seconds is the sweet spot for most models. Longer clips accumulate drift: faces soften, backgrounds morph, lighting shifts. Generate short, cut often, and let sound and rhythm create the sense of continuity. Audiences read fast cutting as energy, not as a mistake.
Design for the cut you will actually make
Think about entry and exit frames. If a shot begins with the subject off-center and ends centered, you can cut into it at the halfway point and get two usable moments. Overlap action between adjacent shots so you have trimming room, the same way editors shoot overlapping coverage on set.
Keeping characters, style, and motion consistent
Consistency is the difference between a demo reel and a deliverable.
Character consistency
Build a character sheet: three to five reference stills from different angles, consistent wardrobe, and consistent lighting. Feed the same reference set into every shot featuring that character. Where a tool supports it, lock a seed value and keep the reference image dimensions identical across generations. When a face drifts, regenerate rather than repair; compositing a new face onto drifting motion usually looks worse than starting over.
Style consistency
Style lives in three places: reference frames, prompt vocabulary, and the final grade. Lock all three. Write a short style note — for instance, overcast daylight, muted teal shadows, shallow depth of field, subtle 35mm grain — and paste the same phrasing into every prompt. Then apply one color treatment across the sequence so small discrepancies between tools disappear.
Motion consistency
Camera language should be as deliberate as dialogue. Decide whether the sequence uses locked-off shots, slow pushes, or handheld movement, and hold that decision per scene. Mixing three camera personalities in one 30-second sequence reads as chaos. Reusable motion templates — a matching dolly-in, a matching orbit — make separate generated clips feel like they came from one shoot.
Sound, pacing, and the invisible edit
Audio is the most underrated tool in AI video editing. It masks seams, sets pace, and carries emotion when visuals are still imperfect.
Build sound in layers
Start with voice. If the video has narration, lock it first and cut picture to the voice, not the other way around. Then add ambience to establish place, foley to make actions feel physical, and music last so it supports rather than leads. A door that opens with no sound feels synthetic no matter how good the render is.
Cut on audio landmarks
Place cuts on breaths, beats, and consonant hits. This single habit makes generated footage feel intentional. When a shot must change but the motion does not support a hard cut, use a two-frame dissolve or a whip-pan sound effect to cover the transition.
The two-second rule
If any shot holds longer than about two seconds without new information, motion, or sound, tighten it. AI-generated clips are usually strongest at their midpoint and weakest at their ends, so trimming entry and exit frames improves perceived quality without regenerating anything.
Toolchain decisions: single suite versus best-of-breed
Every team eventually faces the same choice: one platform that does everything, or a stack of specialized tools.
When a single suite wins
Choose an all-in-one environment when your team is small, when you need fast handoffs, when your output is primarily short-form social video, and when consistency between shots matters more than peak quality on any single shot. Shared libraries, unified export settings, and one place to review versions save hours.
When a specialized stack wins
Choose best-of-breed when you have a dedicated editor, when a client requires a specific look, when face performance is central, or when you need heavy repair work. The tradeoff is file management: you will spend real time moving assets between tools, keeping naming conventions, and re-checking color after each round trip.
A workable middle path
Use one primary generation environment for eighty percent of shots, then bring in one specialist tool for faces and one for repair. Document the handoff rules so anyone on the team can follow them without asking.
Common mistakes and how to fix them
- Generating before writing. Fix: never open a generation tool before the beat sheet is finished.
- One long clip instead of many short ones. Fix: cap clips at five seconds and cut more.
- Ignoring reference images. Fix: create a character sheet and a style frame set first.
- Chasing perfection on shot one. Fix: build a rough full-sequence pass before polishing anything.
- Mixing camera personalities. Fix: define camera language per scene and enforce it.
- Leaving audio until the end. Fix: lock voice and music early, then cut picture to it.
- Skipping the final grade. Fix: apply one unifying treatment across all shots, even a light one.
- No naming convention. Fix: enforce file naming on day one; retroactive cleanup is painful.
- Delivering one aspect ratio. Fix: plan vertical, square, and horizontal crops during shot design, not after export.
- Trusting the first render. Fix: review every clip at full size on a real timeline before approving it.
Workflow example: a 60-second brand story
Here is how the pipeline looks end to end for a one-minute piece.
Day one. Write eight beats, produce six style frames, and get sign-off on the look. Draft the voiceover script and time it to roughly 130 spoken words.
Day two. Build a 22-shot list, generate four takes per shot with a generalist model, and use image-to-video for the six shots containing the main character. Tag everything consistently as it lands.
Day three. Assemble stills on the timeline against the rough voiceover. Lock timing. Replace placeholders with the best generated takes and immediately note which shots need repair.
Day four. Run repairs: upscale the two hero shots, remove a stray object from the opening, interpolate a slow-motion insert, and extend the closing shot by two seconds. Add ambience, foley, and music, then do the final grade.
Day five. Export masters in three aspect ratios, spot-check audio loudness, and deliver with a version of the film that has no voiceover for markets that will dub it later.
Two things make this schedule realistic: shots are generated in parallel batches, and no single shot is allowed to consume more than a few iterations before being redesigned.
FAQ
How long should an AI-generated clip be?
Three to five seconds for most purposes. Longer clips accumulate visual drift, and short clips give you far more freedom in the edit.
Do I still need a video editor if I use AI tools?
Yes, and the role becomes more important, not less. Selection, rhythm, sound, and continuity are judgment calls that generation tools do not make for you.
How do I stop faces from changing between shots?
Use a consistent reference set for each character, keep generation settings stable, and favor image-to-video over text-only prompts whenever a specific person appears on screen.
What is the fastest way to improve output quality?
Improve your audio. Clean voice, ambience, and foley raise perceived production value more than another round of regeneration.
Should I generate in the final aspect ratio?
Yes. Generating natively for the target format preserves composition. Cropping afterward routinely cuts off faces and product details.
How many takes should I generate per shot?
Four to eight for standard shots, ten or more for hero shots where the opening frame must land perfectly. Beyond that, redesign the shot instead of generating more.
Can I mix output from different tools in one video?
Yes, provided you unify grading, grain, and aspect ratio in post. Consistency of treatment hides differences in origin.
What is the biggest mistake beginners make?
Treating generation as the whole job. The generation step is roughly half the work; assembly, sound, and finishing are the other half, and they are what make the result watchable.
